Compare commits
1536 Commits
v2.1.1
...
ppdiffuser
| Author | SHA1 | Date | |
|---|---|---|---|

|
2c92c543f2 | ||
|
|
a85212ed00 | ||
|
|
6f71c7cf5e | ||
|
|
767d3552e3 | ||
|
|
feb9d8296b | ||
|
|
00ae25bf35 | ||
|
|
e97f670440 | ||
|
|
6289d9c0d3 | ||
|
|
7b4cf36b90 | ||
|
|
a50fbbcc30 | ||
|
|
9e2a0a8a9f | ||
|
|
f74de55082 | ||
|
|
e785bb1163 | ||
|
|
ce31a77f90 | ||
|
|
58a5a9dcfd | ||
|
|
6387410b5a | ||
|
|
1a53c35887 | ||
|
|
fd6ef4058e | ||
|
|
1f2b2c5d58 | ||
|
|
7b6454908a | ||
|
|
02b4383b7e | ||
|
|
6471ce331a | ||
|
|
61acf19460 | ||
|
|
c38902e3a8 | ||
|
|
1fc23a8888 | ||
|
|
afeb623588 | ||
|
|
ff546f6d9a | ||
|
|
81bb7d1433 | ||
|
|
6eb6937b69 | ||
|
|
228c58a494 | ||
|
|
e94af7978a | ||
|
|
83a9c3893a | ||
|
|
bdd659d266 | ||
|
|
b52c2ea5d2 | ||
|
|
2483d4fb85 | ||
|
|
7bc85cdfb2 | ||
|
|
513a8328d9 | ||
|
|
3e2ddd182c | ||
|
|
b90ed42dff | ||
|
|
b705fa481d | ||
|
|
cf478ba6ee | ||
|
|
9eda9a46c4 | ||
|
|
1f88c41d14 | ||
|
|
7f650ac0ca | ||
|
|
b6c3589ea6 | ||
|
|
c2e1dc4852 | ||
|
|
1c5e127866 | ||
|
|
c8bc4405fc | ||
|
|
05e7432ef7 | ||
|
|
d390dc95e8 | ||
|
|
b262611f37 | ||
|
|
78c8615791 | ||
|
|
16aa2ba5b1 | ||
|
|
21345f8d2e | ||
|
|
c9c5c15a66 | ||
|
|
d57e350f9e | ||
|
|
295d68e940 | ||
|
|
947007f552 | ||
|
|
14c934c1a1 | ||
|
|
e98231f911 | ||
|
|
d1506f8a38 | ||
|
|
94864bc48e | ||
|
|
b0f7650ecf | ||
|
|
cd5a2e35a6 | ||
|
|
91d5c527dd | ||
|
|
fca7ca25da | ||
|
|
b0ba2e1e79 | ||
|
|
553ba12211 | ||
|
|
122824885c | ||
|
|
211e8204dd | ||
|
|
47f7c36e1e | ||
|
|
7eac0586bc | ||
|
|
a0f5a8ebcd | ||
|
|
636e3430fc | ||
|
|
d52d8e5ea1 | ||
|
|
97fe71d000 | ||
|
|
1bad94989f | ||
|
|
04a742106e | ||
|
|
1076b890de | ||
|
|
219b6abd15 | ||
|
|
fb0cb9b35b | ||
|
|
293c8308af | ||
|
|
e14487780b | ||
|
|
39b49c928f | ||
|
|
38fcccbd86 | ||
|
|
31dc47aed5 | ||
|
|
8f3e4e51e3 | ||
|
|
7476962a6c | ||
|
|
b1ac71b2f5 | ||
|
|
1ac55f0325 | ||
|
|
0497ce7984 | ||
|
|
0a402ca287 | ||
|
|
a12481fc30 | ||
|
|
3e7d4d8140 | ||
|
|
ce67b4fc41 | ||
|
|
839b2d09bb | ||
|
|
db915e756a | ||
|
|
217a25cf01 | ||
|
|
c00d28fcd8 | ||
|
|
90c6f1da59 | ||
|
|
f43cfd0d79 | ||
|
|
caa37ce8d8 | ||
|
|
988204dfbf | ||
|
|
a6b46912d2 | ||
|
|
a3e92bbb04 | ||
|
|
426b75778f | ||
|
|
6011ed8573 | ||
|
|
b1e373c6db | ||
|
|
e83abbb47f | ||
|
|
361d826fbd | ||
|
|
63b3c312ec | ||
|
|
c65dbb42f8 | ||
|
|
4c4f961b89 | ||
|
|
db1f9919c3 | ||
|
|
7fbd726ccf | ||
|
|
50cd2197f1 | ||
|
|
e544a04f8a | ||
|
|
ddb59bfb56 | ||
|
|
ee696c397d | ||
|
|
0b4985dda2 | ||
|
|
907144f8ee | ||
|
|
aa1bef4890 | ||
|
|
01be7792c8 | ||
|
|
70b6e5043a | ||
|
|
031e2bf8f6 | ||
|
|
eee364e7f8 | ||
|
|
289d8214b1 | ||
|
|
a8f08c8ed5 | ||
|
|
9182f34818 | ||
|
|
1e81d90f1f | ||
|
|
3f9ea47d15 | ||
|
|
b6a718bc87 | ||
|
|
0cb7fe99f7 | ||
|
|
3109311e58 | ||
|
|
507084013c | ||
|
|
c987531a2a | ||
|
|
6b54c4e523 | ||
|
|
9c6300d6a5 | ||
|
|
fcb477de4f | ||
|
|
c5c06ce0bb | ||
|
|
c92632bfe0 | ||
|
|
4f70f7297b | ||
|
|
2dfdfa04a2 | ||
|
|
c297ab07b1 | ||
|
|
fdc9a1b1f2 | ||
|
|
116790b58f | ||
|
|
e08cd026d6 | ||
|
|
afcfb6712d | ||
|
|
3db00167e8 | ||
|
|
e5189e973b | ||
|
|
d6f460e54a | ||
|
|
6a0be69064 | ||
|
|
0eb379261a | ||
|
|
d6f1c61fb6 | ||
|
|
985a9a41c0 | ||
|
|
bc23b8b0c2 | ||
|
|
2cfeadf114 | ||
|
|
3abb3589a8 | ||
|
|
be4b6c2a0e | ||
|
|
3b6b183503 | ||
|
|
131750a5bc | ||
|
|
fe2543d981 | ||
|
|
18e2e1188b | ||
|
|
759ec97e70 | ||
|
|
829f445169 | ||
|
|
521fd43191 | ||
|
|
abf217e9f3 | ||
|
|
252a9c0133 | ||
|
|
adf6fcad61 | ||
|
|
0e159ad0c5 | ||
|
|
07e5c553e6 | ||
|
|
b4b1bdc3ed | ||
|
|
0711a60584 | ||
|
|
fb69d1500f | ||
|
|
3d83e742fd | ||
|
|
24fb15e4ef | ||
|
|
90491a00a5 | ||
|
|
62f55d0e25 | ||
|
|
85d7ac6afe | ||
|
|
07994a19cf | ||
|
|
b525401826 | ||
|
|
ad6fe2403f | ||
|
|
2f57f9b036 | ||
|
|
675bfa14a4 | ||
|
|
c64ed99efd | ||
|
|
68d7946293 | ||
|
|
8dc205c918 | ||
|
|
7708822b76 | ||
|
|
17ca23a15e | ||
|
|
a4065c9917 | ||
|
|
e9d24e5e4e | ||
|
|
2080001221 | ||
|
|
aae81be26d | ||
|
|
31a8dc5c24 | ||
|
|
df9e6473ec | ||
|
|
d5587376de | ||
|
|
929e019712 | ||
|
|
8a3a1aa8ae | ||
|
|
77b65d3999 | ||
|
|
611b7c543d | ||
|
|
0befe965af | ||
|
|
938edda04f | ||
|
|
f6e0068a45 | ||
|
|
b8e12c5a33 | ||
|
|
e893a6304e | ||
|
|
2baa92a84a | ||
|
|
a4749e1f50 | ||
|
|
9a25764763 | ||
|
|
1e919ba45d | ||
|
|
338fe2afec | ||
|
|
eb05f409b1 | ||
|
|
7fdfbf2b2b | ||
|
|
7ce1b5cf35 | ||
|
|
20ab09baa0 | ||
|
|
0bdb7b5141 | ||
|
|
46f395ae1d | ||
|
|
0f464e8303 | ||
|
|
fb4eec74d0 | ||
|
|
8ca5cd8256 | ||
|
|
b1ad85171e | ||
|
|
37a68609f0 | ||
|
|
8fc38d6201 | ||
|
|
87613d4c25 | ||
|
|
135e9fa753 | ||
|
|
28f0b9195b | ||
|
|
e1f700a0a2 | ||
|
|
815ddfb72b | ||
|
|
8f5f965fa8 | ||
|
|
64c695aec1 | ||
|
|
2173cf358b | ||
|
|
363269affb | ||
|
|
4ce8fd9a9b | ||
|
|
3e66b0cd02 | ||
|
|
94dd90ae88 | ||
|
|
6b59ba2ef2 | ||
|
|
8b827f410e | ||
|
|
f4e1b67d62 | ||
|
|
2f84f9791e | ||
|
|
93d9c67ec4 | ||
|
|
51fa58f11c | ||
|
|
b50fa0dd22 | ||
|
|
f32a6cab0d | ||
|
|
0ea3cc4b5e | ||
|
|
332da6ba34 | ||
|
|
f0c64b8666 | ||
|
|
848268d284 | ||
|
|
fbd155d602 | ||
|
|
635eb8cabd | ||
|
|
3dfadff339 | ||
|
|
f05794c4b0 | ||
|
|
23979e704b | ||
|
|
6fa2df53d2 | ||
|
|
88435c2701 | ||
|
|
a837aeead6 | ||
|
|
9570637275 | ||
|
|
63ad917675 | ||
|
|
447c0146f5 | ||
|
|
cbc07032f9 | ||
|
|
9f858e6bf5 | ||
|
|
824982dade | ||
|
|
ead43829e3 | ||
|
|
98f6df61ae | ||
|
|
9ab5a91df6 | ||
|
|
12c605af45 | ||
|
|
bd8fa1a972 | ||
|
|
9b51a64069 | ||
|
|
60a475e157 | ||
|
|
a6ab9c896b | ||
|
|
0ed8de72bc | ||
|
|
c6abe76ab9 | ||
|
|
c7287ce9dc | ||
|
|
4f10afa914 | ||
|
|
b7437055f0 | ||
|
|
19e03c4e71 | ||
|
|
b88fc4ea5b | ||
|
|
58e5e7e4bb | ||
|
|
9d9b00bb75 | ||
|
|
ceded4b4dd | ||
|
|
da23449878 | ||
|
|
b72aa7e5bf | ||
|
|
9729a475ee | ||
|
|
2c82f0327c | ||
|
|
caaa102f64 | ||
|
|
aafd5a9178 | ||
|
|
319c56e6d4 | ||
|
|
ea28142590 | ||
|
|
54df619236 | ||
|
|
6f953a928f | ||
|
|
ab2bd216c1 | ||
|
|
47a2ea50d4 | ||
|
|
920e1e8fe0 | ||
|
|
5401f01af8 | ||
|
|
a51c757af1 | ||
|
|
e49344f5ec | ||
|
|
8fde089f40 | ||
|
|
d789b4f154 | ||
|
|
53bdc2d456 | ||
|
|
7614879da2 | ||
|
|
b82cbe8045 | ||
|
|
d759e87383 | ||
|
|
d56c71470e | ||
|
|
2ed52ed88b | ||
|
|
13a13aff17 | ||
|
|
e08964bb58 | ||
|
|
3a90faa916 | ||
|
|
a087e0c21f | ||
|
|
5bfa11c5e1 | ||
|
|
a8886f898c | ||
|
|
09d8ad519b | ||
|
|
2083256f16 | ||
|
|
cece39407d | ||
|
|
536f3c34c1 | ||
|
|
724da5570c | ||
|
|
e8f8eca101 | ||
|
|
c19efe5f34 | ||
|
|
1abe10bb74 | ||
|
|
66b33fd330 | ||
|
|
f89d26ec5f | ||
|
|
e549b57367 | ||
|
|
58e785a7e7 | ||
|
|
0861160e57 | ||
|
|
26daca4cf1 | ||
|
|
2887ae8071 | ||
|
|
f5636731f4 | ||
|
|
a24c852c63 | ||
|
|
674ac4eba4 | ||
|
|
debad267f1 | ||
|
|
3b89d63f35 | ||
|
|
200af6de8d | ||
|
|
08b51e7ab6 | ||
|
|
b40a3c05d8 | ||
|
|
d4b41227bb | ||
|
|
893987dd7f | ||
|
|
0f133c04ac | ||
|
|
98eab225f3 | ||
|
|
522becff95 | ||
|
|
d3ace6c5e3 | ||
|
|
d6f58c836f | ||
|
|
b1629c0cdf | ||
|
|
75c29031c2 | ||
|
|
7b50b5450a | ||
|
|
949c848522 | ||
|
|
a032b304af | ||
|
|
2c294008b9 | ||
|
|
084416868f | ||
|
|
52a18de38f | ||
|
|
4ec0b62f77 | ||
|
|
70bc0b06c1 | ||
|
|
7852629d28 | ||
|
|
08636b3a1e | ||
|
|
f1634e5b16 | ||
|
|
813e5c901b | ||
|
|
22bd3aaa53 | ||
|
|
bfc8700136 | ||
|
|
2be8555763 | ||
|
|
ec893dd053 | ||
|
|
203b6a80d4 | ||
|
|
a1e6a4644c | ||
|
|
07cb2cdc94 | ||
|
|
a2de0bf9ce | ||
|
|
4bbf1b08ff | ||
|
|
ff437f6c19 | ||
|
|
e1f575bb0e | ||
|
|
61b76c5f68 | ||
|
|
869dd96117 | ||
|
|
451ccacec8 | ||
|
|
5c4b1f937c | ||
|
|
8b692d0b60 | ||
|
|
a549c894fc | ||
|
|
493dc101eb | ||
|
|
e05adbf229 | ||
|
|
b10aa7a84b | ||
|
|
9954750b8c | ||
|
|
a15da5fcf6 | ||
|
|
84a6f28899 | ||
|
|
10225001b2 | ||
|
|
56a8957945 | ||
|
|
42ec8e31b4 | ||
|
|
bf0d3ab433 | ||
|
|
a85059fed3 | ||
|
|
f61e7cac75 | ||
|
|
baa47b644d | ||
|
|
8980d64f5f | ||
|
|
115d69d4c2 | ||
|
|
6952b91cff | ||
|
|
4c54f6d3e2 | ||
|
|
3f0d6ce515 | ||
|
|
377ecb22c0 | ||
|
|
6b3f40ced9 | ||
|
|
7ce81e1b6a | ||
|
|
2a4a2fb69f | ||
|
|
54eda93fdd | ||
|
|
8dc6c98c32 | ||
|
|
c097614233 | ||
|
|
bb1729b267 | ||
|
|
085ac53cad | ||
|
|
145333e7b4 | ||
|
|
70e6a31d13 | ||
|
|
101a02c283 | ||
|
|
00a3551f7b | ||
|
|
40423017cd | ||
|
|
52531dde9e | ||
|
|
63b556eb78 | ||
|
|
516f54942b | ||
|
|
14d2c93df5 | ||
|
|
3e863a3e2c | ||
|
|
36ccdcd2d6 | ||
|
|
a7bebbf1f9 | ||
|
|
d97d952cc4 | ||
|
|
79e71a51e3 | ||
|
|
1c812c88d8 | ||
|
|
e98716f8a7 | ||
|
|
7795eeb874 | ||
|
|
1e68ed1dc5 | ||
|
|
54929a2db9 | ||
|
|
4c3518c38c | ||
|
|
30757bea4d | ||
|
|
7d0c831749 | ||
|
|
72344b205b | ||
|
|
42693bf57e | ||
|
|
e69926326c | ||
|
|
c195224a8f | ||
|
|
6b4b62d4c6 | ||
|
|
37888772f0 | ||
|
|
86a373e35c | ||
|
|
445ad52979 | ||
|
|
1c498bc8a5 | ||
|
|
123c4c7816 | ||
|
|
7932dd2924 | ||
|
|
84e8026113 | ||
|
|
8292c719ff | ||
|
|
912e0274a1 | ||
|
|
95c5e00137 | ||
|
|
77a1111cf2 | ||
|
|
112830ba2a | ||
|
|
842954c200 | ||
|
|
721190efcd | ||
|
|
92ca5dc5b9 | ||
|
|
a149af9a5a | ||
|
|
3787da1f15 | ||
|
|
8609c92cb1 | ||
|
|
174ce23ac6 | ||
|
|
0722c85fed | ||
|
|
8ab6d87c9f | ||
|
|
5848a9c482 | ||
|
|
e568e07329 | ||
|
|
4d18e4d648 | ||
|
|
c677a526ec | ||
|
|
8e2f1dced5 | ||
|
|
5f2115e4c5 | ||
|
|
7f3c63af22 | ||
|
|
583a058c62 | ||
|
|
e645d83474 | ||
|
|
9d11665e7b | ||
|
|
fe9d03c49f | ||
|
|
0c93356e7e | ||
|
|
0a618c70f9 | ||
|
|
7745db00b4 | ||
|
|
48d52c5423 | ||
|
|
6e1372fda7 | ||
|
|
0fd17f81bd | ||
|
|
51a8c85867 | ||
|
|
b3087c4b4c | ||
|
|
b4c9dc9686 | ||
|
|
f1f3eb7b5c | ||
|
|
46de583283 | ||
|
|
063eb2c9f0 | ||
|
|
50f666a5c9 | ||
|
|
9a7394b5ca | ||
|
|
3910c52631 | ||
|
|
98c4f399a2 | ||
|
|
54444bbb6d | ||
|
|
80e64b1774 | ||
|
|
e822ee47a8 | ||
|
|
45f23301fd | ||
|
|
bd4e266ac7 | ||
|
|
60e354aa72 | ||
|
|
c339b03d90 | ||
|
|
2ced97a583 | ||
|
|
2e34b1669f | ||
|
|
548d59aeb6 | ||
|
|
cf055c8239 | ||
|
|
5813bfd60e | ||
|
|
cfd5466861 | ||
|
|
b5d0d22b38 | ||
|
|
8a5443b311 | ||
|
|
00f05b8456 | ||
|
|
ae17eed919 | ||
|
|
167464c778 | ||
|
|
e95bd9384c | ||
|
|
38f806d025 | ||
|
|
de777fd789 | ||
|
|
f9231425af | ||
|
|
a0c9e1d84f | ||
|
|
960fe9e0c3 | ||
|
|
a88cd55765 | ||
|
|
17b76a4a64 | ||
|
|
96b6999ca7 | ||
|
|
989155cd19 | ||
|
|
068a8d9777 | ||
|
|
8cbf0f44f6 | ||
|
|
7eba09149d | ||
|
|
c5f14a66d2 | ||
|
|
803b41ed4b | ||
|
|
85f76e50f1 | ||
|
|
2517583397 | ||
|
|
9000712ed0 | ||
|
|
0ca48c5553 | ||
|
|
93974f0d97 | ||
|
|
b192b848e5 | ||
|
|
f6a8a5a261 | ||
|
|
24edee6549 | ||
|
|
131bb80da2 | ||
|
|
aebb717023 | ||
|
|
13e500bf5f | ||
|
|
1f078ef9e4 | ||
|
|
94b74c03ec | ||
|
|
157ced55fb | ||
|
|
1d5e425a8c | ||
|
|
06368eca6d | ||
|
|
b0a60615c1 | ||
|
|
40734bb3af | ||
|
|
67d512b240 | ||
|
|
5e3a588de4 | ||
|
|
7fa724472c | ||
|
|
0650e01bbe | ||
|
|
683d14ed55 | ||
|
|
4718676968 | ||
|
|
4e31451d30 | ||
|
|
7dfacbdfb3 | ||
|
|
4d40a2ea80 | ||
|
|
737a300030 | ||
|
|
f5cb6b85fb | ||
|
|
77873b0fe9 | ||
|
|
95f963339c | ||
|
|
7ffd30e6ed | ||
|
|
9230a1eaa7 | ||
|
|
d7ae773f79 | ||
|
|
0fb361753f | ||
|
|
2710b7d454 | ||
|
|
c19372bca1 | ||
|
|
42311124dc | ||
|
|
a5760045d2 | ||
|
|
dbf57dd77a | ||
|
|
7e1a4332d5 | ||
|
|
ad36a14f73 | ||
|
|
40417bf8de | ||
|
|
08f0633296 | ||
|
|
38629479f5 | ||
|
|
eb43ab76b4 | ||
|
|
dab5e26f3e | ||
|
|
9fda199877 | ||
|
|
7838255d9a | ||
|
|
03dcbeff74 | ||
|
|
c92810b1ff | ||
|
|
497dedd63b | ||
|
|
14b476893c | ||
|
|
0315365dba | ||
|
|
8dd2e2a41d | ||
|
|
634c2e7759 | ||
|
|
fc0313b3e4 | ||
|
|
761c295d25 | ||
|
|
baf322f20a | ||
|
|
1710fb26c4 | ||
|
|
397319997b | ||
|
|
805ecf3a23 | ||
|
|
070322f6e1 | ||
|
|
156b6761e8 | ||
|
|
b3d93484e2 | ||
|
|
ae97b77778 | ||
|
|
7f5f43aa31 | ||
|
|
536ab141f5 | ||
|
|
662ec5aaa4 | ||
|
|
7833edf910 | ||
|
|
0ebb047b98 | ||
|
|
222fc3154a | ||
|
|
5901915881 | ||
|
|
417ccafef9 | ||
|
|
42bf0f78a6 | ||
|
|
2f366e4d50 | ||
|
|
7f7f7d09f9 | ||
|
|
f10575dea9 | ||
|
|
4a23b50ade | ||
|
|
bc84454065 | ||
|
|
07bafdc688 | ||
|
|
d95cfc314f | ||
|
|
be6a077d59 | ||
|
|
835aed06d8 | ||
|
|
e135626896 | ||
|
|
a93bdffb47 | ||
|
|
6ccc0be765 | ||
|
|
1f446ff575 | ||
|
|
d99b333543 | ||
|
|
b07a41787f | ||
|
|
4d384e513c | ||
|
|
baf0247996 | ||
|
|
5bc1b98624 | ||
|
|
5cd8fd5b29 | ||
|
|
016db3c15c | ||
|
|
7c06b02e31 | ||
|
|
837d06ad58 | ||
|
|
7b971c442b | ||
|
|
43c6c46ae2 | ||
|
|
d33892863e | ||
|
|
31deea6c98 | ||
|
|
79412aa3fc | ||
|
|
b8881b5519 | ||
|
|
dbda1f50a6 | ||
|
|
617fee64dc | ||
|
|
681d5e21b5 | ||
|
|
d1c683dbfd | ||
|
|
ce61f68323 | ||
|
|
94bb8db332 | ||
|
|
647dc69c74 | ||
|
|
ececddb03e | ||
|
|
b72d37f13d | ||
|
|
80d22aafd2 | ||
|
|
636e2e5efb | ||
|
|
0fae3067aa | ||
|
|
db33f19a01 | ||
|
|
e4de45f3e0 | ||
|
|
2027317693 | ||
|
|
b34c318a5c | ||
|
|
9af11bb465 | ||
|
|
9805556535 | ||
|
|
cec1caf485 | ||
|
|
1b904b7cb0 | ||
|
|
64ac2f404b | ||
|
|
3ec1d35f7f | ||
|
|
75edf33e3b | ||
|
|
0e76981a54 | ||
|
|
f6b3ccac92 | ||
|
|
5abaaecd93 | ||
|
|
41daa257de | ||
|
|
7d1d6fe3ac | ||
|
|
8fdf42d9db | ||
|
|
6ab0ee3872 | ||
|
|
2a6b6c6c18 | ||
|
|
0432c12691 | ||
|
|
dc1b8238fb | ||
|
|
d911bf2bf2 | ||
|
|
f428a8c046 | ||
|
|
0a94ab4360 | ||
|
|
56783d90b3 | ||
|
|
75735a8585 | ||
|
|
f982df890a | ||
|
|
c367f8f38e | ||
|
|
058a43aae4 | ||
|
|
9a80a9c303 | ||
|
|
99673ad382 | ||
|
|
25b41ea854 | ||
|
|
3082fc07f6 | ||
|
|
e1014ee6fa | ||
|
|
1a8c099139 | ||
|
|
38efa7947d | ||
|
|
e608d9056a | ||
|
|
d34b51d66e | ||
|
|
910da2e308 | ||
|
|
ba69fd7e9c | ||
|
|
d5bd2d9b5a | ||
|
|
3b3f09b979 | ||
|
|
8c86f33dd0 | ||
|
|
d0bbb9070d | ||
|
|
47b32efb86 | ||
|
|
4a6b26c14b | ||
|
|
54115c9e0f | ||
|
|
25acac7f64 | ||
|
|
7c3a7e4e3b | ||
|
|
f08ad860fe | ||
|
|
ea2925d2aa | ||
|
|
81bb1e7915 | ||
|
|
3e76bb1f69 | ||
|
|
1c3472a4af | ||
|
|
2e1b4d2d40 | ||
|
|
aebd26eb21 | ||
|
|
a1df427c5b | ||
|
|
461fc20d9c | ||
|
|
c21d13ea43 | ||
|
|
b19c8e449f | ||
|
|
a5f91d8c37 | ||
|
|
5d2cfd49ac | ||
|
|
76b56f3967 | ||
|
|
89e93cc7a1 | ||
|
|
790cd014dc | ||
|
|
8bea40f836 | ||
|
|
a3a8321747 | ||
|
|
2a994320e3 | ||
|
|
b02f6c615f | ||
|
|
2453f2fc5f | ||
|
|
3aa2c30f2c | ||
|
|
ac08a5b7fd | ||
|
|
b114842121 | ||
|
|
4d14ab7209 | ||
|
|
7d48acd907 | ||
|
|
6ac63220c7 | ||
|
|
ee5aa26331 | ||
|
|
5773fa2d45 | ||
|
|
1e18e09f8d | ||
|
|
3e55cb4656 | ||
|
|
ad73c59af8 | ||
|
|
6716b91220 | ||
|
|
f917e188ae | ||
|
|
f942c42085 | ||
|
|
da68bd43be | ||
|
|
e672bb4528 | ||
|
|
cd43cc6f3a | ||
|
|
1de6933c99 | ||
|
|
1f5bc06c99 | ||
|
|
e3aee9bd38 | ||
|
|
83f37a17c8 | ||
|
|
778049750f | ||
|
|
1fdf30828c | ||
|
|
1ed25f223f | ||
|
|
c2e5cc8dcf | ||
|
|
172389f87a | ||
|
|
1d433b1cce | ||
|
|
acf3832733 | ||
|
|
e0b74d18d1 | ||
|
|
75922448cd | ||
|
|
12f60e322b | ||
|
|
cd0b6988db | ||
|
|
a847d88bdf | ||
|
|
cc8134555b | ||
|
|
52c72730a5 | ||
|
|
bac1d83c31 | ||
|
|
86d9837c12 | ||
|
|
bf811e1c32 | ||
|
|
ec3c633c96 | ||
|
|
953d17837f | ||
|
|
11e4743aad | ||
|
|
a65de1d757 | ||
|
|
32f0aebe18 | ||
|
|
1115a70164 | ||
|
|
9dac2dc5fe | ||
|
|
928ef683a4 | ||
|
|
eb4a63027e | ||
|
|
78afe1d250 | ||
|
|
453aa70b4b | ||
|
|
e7bb926f3c | ||
|
|
db44190ab9 | ||
|
|
5a07b12784 | ||
|
|
7ba4523395 | ||
|
|
d9431a8026 | ||
|
|
7ca4114d95 | ||
|
|
3ff2bdf86c | ||
|
|
63fcabed34 | ||
|
|
2f836d3d99 | ||
|
|
ecb3abcab5 | ||
|
|
f1ebb09480 | ||
|
|
f90a9bfdde | ||
|
|
cc4932e2da | ||
|
|
2e1f4be8e8 | ||
|
|
52a83248de | ||
|
|
90191811dc | ||
|
|
853f7c1241 | ||
|
|
9686c3bfa6 | ||
|
|
02ebee1e48 | ||
|
|
9d8df779f8 | ||
|
|
e93523da24 | ||
|
|
61774d5441 | ||
|
|
6a36a51c53 | ||
|
|
5e2e27300d | ||
|
|
1d2f32b538 | ||
|
|
33a08ed31d | ||
|
|
9b1584e20c | ||
|
|
d23267adf1 | ||
|
|
5ee1c6c19e | ||
|
|
2128037d73 | ||
|
|
fbd0543df0 | ||
|
|
94538b3aa2 | ||
|
|
2b6ba44e51 | ||
|
|
27033792a4 | ||
|
|
e4e0baa047 | ||
|
|
f08343f586 | ||
|
|
912edcadd2 | ||
|
|
72d9d1ba1f | ||
|
|
5be65fbee8 | ||
|
|
841a864d84 | ||
|
|
9765848dbd | ||
|
|
8294fb409a | ||
|
|
44659369bf | ||
|
|
6d1a6f06f0 | ||
|
|
0dcf0052b2 | ||
|
|
e6dff46fc2 | ||
|
|
b60760d60e | ||
|
|
89abb49635 | ||
|
|
6d62762bef | ||
|
|
c600f74aa2 | ||
|
|
d92f2ec1f1 | ||
|
|
f2085e65d6 | ||
|
|
8fee6a8c78 | ||
|
|
1b1b3b6058 | ||
|
|
5528ec4027 | ||
|
|
6f378fd475 | ||
|
|
9028d565c1 | ||
|
|
e806146b77 | ||
|
|
329f6a9f6b | ||
|
|
3a34cce669 | ||
|
|
ce1cc31f64 | ||
|
|
03303630a1 | ||
|
|
d5420e226e | ||
|
|
d66c83283b | ||
|
|
f21829c4be | ||
|
|
ba57969dbc | ||
|
|
9f00755ff7 | ||
|
|
d58a221338 | ||
|
|
a389a72c56 | ||
|
|
69a8c79586 | ||
|
|
e158e13a33 | ||
|
|
a3ac5a95d9 | ||
|
|
1ab0e48862 | ||
|
|
8ee2eb9b2e | ||
|
|
380a1db54b | ||
|
|
ed68f994e8 | ||
|
|
d0a5ea9691 | ||
|
|
361d91cbcb | ||
|
|
6de32e519b | ||
|
|
103241b3eb | ||
|
|
63ab91783b | ||
|
|
d405b2d85a | ||
|
|
d9b2e10687 | ||
|
|
7dde5b138e | ||
|
|
2730d3ce31 | ||
|
|
d83be59378 | ||
|
|
32ef8f84ba | ||
|
|
8e29ffb648 | ||
|
|
5ec8d131f6 | ||
|
|
a6d0fdf2d3 | ||
|
|
ac27a26a5f | ||
|
|
5ebb0a7c9e | ||
|
|
f1c259dafc | ||
|
|
187ef1e10a | ||
|
|
3c5d7c577b | ||
|
|
2f8f701fb2 | ||
|
|
7d21d7b3bf | ||
|
|
ea837b83fe | ||
|
|
bef2d2bbf1 | ||
|
|
c481083c2a | ||
|
|
6ec5afb6d6 | ||
|
|
cfd275ea91 | ||
|
|
b15f5b290f | ||
|
|
5bd04733fb | ||
|
|
a29ffed77f | ||
|
|
24a0abb654 | ||
|
|
df18bd1f76 | ||
|
|
d2a4ca5cc3 | ||
|
|
1ed1693842 | ||
|
|
4014cb3c4f | ||
|
|
8a424df650 | ||
|
|
8bf21c1b35 | ||
|
|
f7aad8893c | ||
|
|
57a286188f | ||
|
|
140ce172a9 | ||
|
|
70137aada4 | ||
|
|
e18121c59e | ||
|
|
63bf2d5149 | ||
|
|
c7369d4b21 | ||
|
|
f47f430388 | ||
|
|
4cf13bd9ed | ||
|
|
24aff87513 | ||
|
|
3b1d096e22 | ||
|
|
a27afd0d45 | ||
|
|
f8f6294342 | ||
|
|
68ea6dd5c9 | ||
|
|
44663b9d0c | ||
|
|
60e03a0b4a | ||
|
|
e387e70e7a | ||
|
|
e91253d865 | ||
|
|
80d1136e0d | ||
|
|
39432a2ace | ||
|
|
8cb27ad829 | ||
|
|
f7b7d52e39 | ||
|
|
cdd68258a4 | ||
|
|
caa386f297 | ||
|
|
fa8fe0ef25 | ||
|
|
5765fbeb9d | ||
|
|
3a81aee3a9 | ||
|
|
793eee08ee | ||
|
|
a0eac8e6b1 | ||
|
|
61685f0e50 | ||
|
|
5d2904a108 | ||
|
|
862bf6e9ee | ||
|
|
3b019a6a42 | ||
|
|
078dd64f8f | ||
|
|
04cb1adfe2 | ||
|
|
346a1c070e | ||
|
|
676ad02714 | ||
|
|
9fd7364426 | ||
|
|
a2a8817254 | ||
|
|
916791aee4 | ||
|
|
6d61877140 | ||
|
|
eeb9a5a322 | ||
|
|
619b94c1e8 | ||
|
|
0e4b2cab34 | ||
|
|
3f46723c55 | ||
|
|
f7487a45f1 | ||
|
|
fcd3d1a3c6 | ||
|
|
3ee4b23553 | ||
|
|
55122d2b67 | ||
|
|
2fe82d8ba6 | ||
|
|
4ab25251b9 | ||
|
|
d02b797595 | ||
|
|
db7aecf3cd | ||
|
|
d4d530d998 | ||
|
|
45e1587ce3 | ||
|
|
6bd7d6e6ee | ||
|
|
61cb9bce2e | ||
|
|
7d47e0961e | ||
|
|
0b18f4c271 | ||
|
|
68e4827ff8 | ||
|
|
321f45c729 | ||
|
|
04a6ca3ea4 | ||
|
|
ae2ddbfea8 | ||
|
|
e2ffdd4dbc | ||
|
|
26a7b0417c | ||
|
|
fb2ed84560 | ||
|
|
51d335dd36 | ||
|
|
d6c1f91498 | ||
|
|
b8b87dd919 | ||
|
|
bafcfb1539 | ||
|
|
d47c3cf31e | ||
|
|
49eedeee32 | ||
|
|
0928e7e03f | ||
|
|
226ca51cea | ||
|
|
adb1ef41dc | ||
|
|
fc63c1116f | ||
|
|
70a55a3f14 | ||
|
|
d315620465 | ||
|
|
b42754e466 | ||
|
|
52e1ab4e17 | ||
|
|
c08984cf13 | ||
|
|
17ce404571 | ||
|
|
810be72609 | ||
|
|
d099228b42 | ||
|
|
8154b118bf | ||
|
|
fb68158e46 | ||
|
|
3461c2b123 | ||
|
|
662d29bf18 | ||
|
|
e9a8903431 | ||
|
|
d35bdecef3 | ||
|
|
ebcb565ba4 | ||
|
|
5d349ad14c | ||
|
|
44896d10ef | ||
|
|
90dd690e17 | ||
|
|
b2bb385418 | ||
|
|
e186b1fba5 | ||
|
|
8bcc7b8c39 | ||
|
|
4b1ffa4797 | ||
|
|
aca133e621 | ||
|
|
d1c68094ce | ||
|
|
08deaab0e3 | ||
|
|
fda3d82a3f | ||
|
|
da3614d935 | ||
|
|
ce7c1538dc | ||
|
|
bb0c8ccd3b | ||
|
|
ecc3788409 | ||
|
|
46a268dde0 | ||
|
|
9ba16d98c9 | ||
|
|
a50633db94 | ||
|
|
746da81c5c | ||
|
|
a4369aae52 | ||
|
|
20d1734c79 | ||
|
|
8ce1a71c2d | ||
|
|
1ae624dadc | ||
|
|
78f034f862 | ||
|
|
bb272f4e71 | ||
|
|
8d75ff2895 | ||
|
|
9b227f2c4b | ||
|
|
2749e3428a | ||
|
|
69bf4b4d22 | ||
|
|
d0f2c551da | ||
|
|
006c4d9837 | ||
|
|
af18ef2156 | ||
|
|
0a4f75decb | ||
|
|
2922af4eef | ||
|
|
40cf839105 | ||
|
|
c086026d76 | ||
|
|
d35eec378e | ||
|
|
905fc554ff | ||
|
|
cda988311d | ||
|
|
dac0ccff49 | ||
|
|
390acb902a | ||
|
|
69f098a365 | ||
|
|
c9ddd0cac3 | ||
|
|
b9a1011491 | ||
|
|
2afc6062f9 | ||
|
|
3608dc3651 | ||
|
|
4b8f092fcb | ||
|
|
f2e421e7ff | ||
|
|
c068cff507 | ||
|
|
378d139db5 | ||
|
|
ff34f94b6a | ||
|
|
a09dba168f | ||
|
|
5dd1ba6e1a | ||
|
|
f6236d4db1 | ||
|
|
845dfd8ad0 | ||
|
|
519f552730 | ||
|
|
a0eea3c0c4 | ||
|
|
4c3e73c16d | ||
|
|
7394ddf6c0 | ||
|
|
ca92e6324a | ||
|
|
45e14c2463 | ||
|
|
ca63ba8897 | ||
|
|
e99e41b905 | ||
|
|
af89ed9cca | ||
|
|
efde6145c9 | ||
|
|
7c19d5914b | ||
|
|
6cdd4259f8 | ||
|
|
70649b1bf8 | ||
|
|
3021098cac | ||
|
|
20bed38555 | ||
|
|
4769d92baf | ||
|
|
d815ceb133 | ||
|
|
4e2802b3e7 | ||
|
|
7eb0c7a431 | ||
|
|
f9fab9430c | ||
|
|
7a5b0028c8 | ||
|
|
73d5318048 | ||
|
|
f089a1816c | ||
|
|
99804a2426 | ||
|
|
01d2c2a9ea | ||
|
|
b2e98d8d2d | ||
|
|
44569cc868 | ||
|
|
61b51ea9e6 | ||
|
|
164f0f6db1 | ||
|
|
dc26828139 | ||
|
|
86489d8809 | ||
|
|
ac6fc3a643 | ||
|
|
1ff5954481 | ||
|
|
2e236dbe9c | ||
|
|
11881bc071 | ||
|
|
671f0f3898 | ||
|
|
4ba301bb54 | ||
|
|
67d93b1f06 | ||
|
|
6f0535a14d | ||
|
|
07c0085608 | ||
|
|
adb2478427 | ||
|
|
2000ea2ea8 | ||
|
|
7ff492bad9 | ||
|
|
2ace3f1974 | ||
|
|
82cccba33d | ||
|
|
02d762c0a5 | ||
|
|
437c926dfc | ||
|
|
6c0e1bb4c4 | ||
|
|
1bc96a0180 | ||
|
|
ee157d6f8b | ||
|
|
6641d3ca57 | ||
|
|
9fb0148a30 | ||
|
|
b1d5b530a6 | ||
|
|
561f114eb8 | ||
|
|
79126042d6 | ||
|
|
c541f4ba1f | ||
|
|
f2506c37c9 | ||
|
|
9aac8b6a0c | ||
|
|
2bb8bf5f31 | ||
|
|
b373d98080 | ||
|
|
316b14a55b | ||
|
|
30b4ca575d | ||
|
|
95885249ef | ||
|
|
9a124efe31 | ||
|
|
44a290e94d | ||
|
|
00af227211 | ||
|
|
4a9a3dbec9 | ||
|
|
fd52aff878 | ||
|
|
a1e7dfff9c | ||
|
|
a6e56e3b6b | ||
|
|
832e8a7f99 | ||
|
|
a132cc1561 | ||
|
|
a2960792a7 | ||
|
|
4f8c69641f | ||
|
|
77e5192d55 | ||
|
|
1f4a5075b1 | ||
|
|
249227fe58 | ||
|
|
623d65e377 | ||
|
|
d0d20678f2 | ||
|
|
241b9e04a0 | ||
|
|
1df66439dc | ||
|
|
07a25b286b | ||
|
|
b7f9949871 | ||
|
|
3351ab0405 | ||
|
|
46cbe60018 | ||
|
|
919f7ed29c | ||
|
|
0a2988970e | ||
|
|
b69d56f513 | ||
|
|
c4fc6eafa2 | ||
|
|
5463a3ea62 | ||
|
|
2682d3c9d2 | ||
|
|
bb7916bee3 | ||
|
|
11c568c4fd | ||
|
|
4829631d7d | ||
|
|
85a3a252bb | ||
|
|
aa82dc0666 | ||
|
|
5f3ab326f9 | ||
|
|
630e21ef00 | ||
|
|
4aa9bb8c07 | ||
|
|
93b2a0c2ce | ||
|
|
f2239e3b6f | ||
|
|
93cae49c0c | ||
|
|
edcd9a4750 | ||
|
|
02f0e210c1 | ||
|
|
1d930169e1 | ||
|
|
3b675575cb | ||
|
|
c11a1465e1 | ||
|
|
97da5e0dc6 | ||
|
|
203232a21c | ||
|
|
b66d14d9bf | ||
|
|
6864ac37ee | ||
|
|
55ac7fbdbd | ||
|
|
c50cf7207f | ||
|
|
b0fa3ce47b | ||
|
|
6d102f5b97 | ||
|
|
fe06274910 | ||
|
|
8b68c74755 | ||
|
|
b137a35db7 | ||
|
|
b570fd11fd | ||
|
|
b260c8fa50 | ||
|
|
5637b5f15c | ||
|
|
08a22758b1 | ||
|
|
01a0c1fca3 | ||
|
|
6ff5eabb8f | ||
|
|
8fecd6b648 | ||
|
|
eb5cf37cea | ||
|
|
83743ccb63 | ||
|
|
36a8f5056f | ||
|
|
43ce0713d8 | ||
|
|
d6d77ecf03 | ||
|
|
87f342c3df | ||
|
|
5bcc708b82 | ||
|
|
783ac715dc | ||
|
|
631aaed007 | ||
|
|
40f45e2d10 | ||
|
|
5126f82586 | ||
|
|
7c47b62d37 | ||
|
|
1a9a48ebe9 | ||
|
|
e93f899a02 | ||
|
|
bdd703b257 | ||
|
|
aa63b68971 | ||
|
|
c6d7c7c26b | ||
|
|
ff027096cf | ||
|
|
684e90745c | ||
|
|
e91dc7858c | ||
|
|
549d9a5310 | ||
|
|
1a5695a18b | ||
|
|
e728f037d9 | ||
|
|
afd326da4b | ||
|
|
1e2ee01dad | ||
|
|
5d69c9f2e5 | ||
|
|
cf7c855955 | ||
|
|
48dee51548 | ||
|
|
ac29416211 | ||
|
|
a9cf35e08a | ||
|
|
503940fdb1 | ||
|
|
653ca9635b | ||
|
|
3ee73ac8f7 | ||
|
|
9da1bb6284 | ||
|
|
43e798916c | ||
|
|
54bede7c2d | ||
|
|
b554cbef59 | ||
|
|
7ff22597e0 | ||
|
|
7a8e95d369 | ||
|
|
30ab2533de | ||
|
|
bf0b18d0ae | ||
|
|
d767381445 | ||
|
|
ebd6859ab7 | ||
|
|
ba3ea1cffa | ||
|
|
205e5001f1 | ||
|
|
4871622621 | ||
|
|
92d82a859b | ||
|
|
61bfdd54ee | ||
|
|
81398635cf | ||
|
|
7b8dd49ad4 | ||
|
|
1e14c2a92d | ||
|
|
0782e912c9 | ||
|
|
a99f82f947 | ||
|
|
f71b7d8f20 | ||
|
|
bc3a10885f | ||
|
|
dc933f3dde | ||
|
|
66ccc0e06a | ||
|
|
d4f0fa4e77 | ||
|
|
dbd26feb80 | ||
|
|
4c36ef9e41 | ||
|
|
4a9106570b | ||
|
|
8801dc0643 | ||
|
|
4a1b98b939 | ||
|
|
d5db194ea2 | ||
|
|
655df0b47a | ||
|
|
090e636db5 | ||
|
|
d329c802f6 | ||
|
|
f6fca874b1 | ||
|
|
15f0aa8f45 | ||
|
|
26fe221a06 | ||
|
|
b03753726e | ||
|
|
b1807db9bb | ||
|
|
3e0ff9af3f | ||
|
|
09b4d17d41 | ||
|
|
557f109ed4 | ||
|
|
9ac1714ea1 | ||
|
|
eddc21d558 | ||
|
|
cae02abed9 | ||
|
|
d5bdcfeeca | ||
|
|
93647290d2 | ||
|
|
8b713d28b3 | ||
|
|
ce8dc9da62 | ||
|
|
029ec79ad7 | ||
|
|
1559f3b5c4 | ||
|
|
059dd28696 | ||
|
|
cff9a2585b | ||
|
|
275e62a9f1 | ||
|
|
9adaf58920 | ||
|
|
3e9ee57bfe | ||
|
|
c577cb4636 | ||
|
|
7153318373 | ||
|
|
0fa78717c2 | ||
|
|
c728cabd3a | ||
|
|
c720cf6254 | ||
|
|
3e68984baa | ||
|
|
28734abddb | ||
|
|
8e94a979fc | ||
|
|
2197402037 | ||
|
|
1c10abadb7 | ||
|
|
32d01fa103 | ||
|
|
82b1cc421c | ||
|
|
2455ec2cd0 | ||
|
|
8993c321ad | ||
|
|
f20539d80b | ||
|
|
078758e192 | ||
|
|
075423cfee | ||
|
|
7b455cce47 | ||
|
|
22a497cb30 | ||
|
|
31b6fd99b2 | ||
|
|
48a226f953 | ||
|
|
ed11f1f5f5 | ||
|
|
eb22a182c3 | ||
|
|
83b96f4e84 | ||
|
|
eb1dd6d366 | ||
|
|
df48dea129 | ||
|
|
2986c930c7 | ||
|
|
27d87b6caf | ||
|
|
0334963bd4 | ||
|
|
22cee265ab | ||
|
|
a5f8a3ec9d | ||
|
|
cf51c8ae4c | ||
|
|
60608d3906 | ||
|
|
6213573384 | ||
|
|
2a620ba2f2 | ||
|
|
e321e092a0 | ||
|
|
b0c35d5e1f | ||
|
|
b3130851db | ||
|
|
82e4316df8 | ||
|
|
85f4cc0ec1 | ||
|
|
1e4975d426 | ||
|
|
4ac2811533 | ||
|
|
bdda90143b | ||
|
|
c1d5241d58 | ||
|
|
24ac65d7c6 | ||
|
|
737e4fa0e8 | ||
|
|
719485c674 | ||
|
|
33d960b23a | ||
|
|
e80b4c17a7 | ||
|
|
7fea9ffd97 | ||
|
|
be5299ef0e | ||
|
|
54f2f0694a | ||
|
|
b15382b9b7 | ||
|
|
5163ae67b2 | ||
|
|
2a4b8ee382 | ||
|
|
9e74b50c15 | ||
|
|
a7d8fc1212 | ||
|
|
1333d435e6 | ||
|
|
0317a5c403 | ||
|
|
72e242ff0b | ||
|
|
5bef34ae49 | ||
|
|
3d3bc82c85 | ||
|
|
809bb57eee | ||
|
|
b27c647f51 | ||
|
|
51793e8f15 | ||
|
|
e8c7474d04 | ||
|
|
4911fe49d5 | ||
|
|
128a7e5df8 | ||
|
|
e1842d749f | ||
|
|
a8242221b6 | ||
|
|
05e80c0e85 | ||
|
|
7c8dd35955 | ||
|
|
cc9dc322ef | ||
|
|
4b50fdb885 | ||
|
|
a42800c408 | ||
|
|
65334b5472 | ||
|
|
49f7f0d4da | ||
|
|
39cbfeda2a | ||
|
|
032677e95b | ||
|
|
6277abfedb | ||
|
|
dcabd4f999 | ||
|
|
4070783a5b | ||
|
|
ec7fb3da42 | ||
|
|
d82766be1d | ||
|
|
a16c4bce16 | ||
|
|
588e5de602 | ||
|
|
806ff6f998 | ||
|
|
191f6aba40 | ||
|
|
c848db5344 | ||
|
|
3043717f0b | ||
|
|
a1d27c3051 | ||
|
|
a93a047b02 | ||
|
|
843c69af49 | ||
|
|
3012065e8c | ||
|
|
4359f6b8d5 | ||
|
|
7fb53ae735 | ||
|
|
74f9fae19b | ||
|
|
a8b1956050 | ||
|
|
09f18731a2 | ||
|
|
f631d3edb9 | ||
|
|
8aa407e700 | ||
|
|
b089b21e66 | ||
|
|
d94b6283b4 | ||
|
|
55130a9c35 | ||
|
|
50f71b3f73 | ||
|
|
b3b05581e0 | ||
|
|
e44a5672da | ||
|
|
01c6bfafa4 | ||
|
|
9dc70b423f | ||
|
|
69faee4375 | ||
|
|
f56e4291a6 | ||
|
|
10fc6a6272 | ||
|
|
374d31b7da | ||
|
|
7336d52dc5 | ||
|
|
fa1fa7565b | ||
|
|
5f2862a347 | ||
|
|
1ecff72d07 | ||
|
|
868e7a234d | ||
|
|
cc58a2390f | ||
|
|
4e59ce0212 | ||
|
|
f580332a2e | ||
|
|
4d06421908 | ||
|
|
b4542fa638 | ||
|
|
7fab504d30 | ||
|
|
87fa30b62e | ||
|
|
eb5385bc96 | ||
|
|
e35f1ee58c | ||
|
|
72d6590eca | ||
|
|
292ac62568 | ||
|
|
c612049f92 | ||
|
|
583f7246e3 | ||
|
|
d1140bb15d | ||
|
|
449b939d96 | ||
|
|
ff1103e8c8 | ||
|
|
5a3e2c04cd | ||
|
|
26ad5ebc1a | ||
|
|
09a43edcbe | ||
|
|
7a438f43ba | ||
|
|
ad06f37c18 | ||
|
|
9d9bd67f29 | ||
|
|
0720afe814 | ||
|
|
3a24b612ae | ||
|
|
4b870be191 | ||
|
|
6cac0aced7 | ||
|
|
40f39fd065 | ||
|
|
6a3f295ac9 | ||
|
|
aec3119907 | ||
|
|
f079f91c48 | ||
|
|
21e61b5b07 | ||
|
|
e468e19e5e | ||
|
|
10ac335ccd | ||
|
|
072b9ff086 | ||
|
|
5af122b71c | ||
|
|
beed3da7db | ||
|
|
8268726456 | ||
|
|
d3fcc6181e | ||
|
|
41ab2653cb | ||
|
|
91c1a49c49 | ||
|
|
4d9f920521 | ||
|
|
aea393eb7a | ||
|
|
b37d218243 | ||
|
|
d19ad50ad4 | ||
|
|
18f3a7c356 | ||
|
|
0287e5475d | ||
|
|
e27ac6a046 | ||
|
|
570685fd43 | ||
|
|
0ba12057b1 | ||
|
|
f3010d9fc5 | ||
|
|
208e8803b0 | ||
|
|
d4075ff0ad | ||
|
|
aa3ae6264d | ||
|
|
97e51ffceb | ||
|
|
8ef9979639 | ||
|
|
eea2d98bd9 | ||
|
|
ae02c319a4 | ||
|
|
c43df37410 | ||
|
|
1dc67bcb98 | ||
|
|
6039c90292 | ||
|
|
235cc509f0 | ||
|
|
c3a467b053 | ||
|
|
9f79af12b2 | ||
|
|
17517fe0d8 | ||
|
|
c443ffa498 | ||
|
|
96cf4dc342 | ||
|
|
0bed1f1b35 | ||
|
|
bd3fae29e8 | ||
|
|
2fbd04f752 | ||
|
|
b1ba31be0d | ||
|
|
794b116b1d | ||
|
|
0e5185210c | ||
|
|
93e40c642e | ||
|
|
0a880fd849 | ||
|
|
d8b2ce8029 | ||
|
|
1bd462a96c | ||
|
|
48a2de375d | ||
|
|
f7933424f5 | ||
|
|
e03f8352eb | ||
|
|
cf38e199a9 | ||
|
|
dc5b6a817b | ||
|
|
4f4036f6a0 | ||
|
|
57ff4870fd | ||
|
|
863127ca0a | ||
|
|
673ecd4a40 | ||
|
|
edc57c1a7c | ||
|
|
8200fd8c96 | ||
|
|
e79822d7c2 | ||
|
|
8f0a0b6a47 | ||
|
|
8c7f4ec7e3 | ||
|
|
462f080fd3 | ||
|
|
d934e9ddee | ||
|
|
9f6634f57a | ||
|
|
d49b6b1af8 | ||
|
|
2afd760d0e | ||
|
|
eec798a941 | ||
|
|
27503e754a | ||
|
|
5d5e4dd4df | ||
|
|
666dcfc41d | ||
|
|
c54226bb78 | ||
|
|
f81c3b9066 | ||
|
|
588c997504 | ||
|
|
8681300253 | ||
|
|
ac9d6f9cc8 | ||
|
|
74b1bb8d25 | ||
|
|
ffc9190b9a | ||
|
|
f14bf99ef4 | ||
|
|
65d33d4310 | ||
|
|
fc880b0e7a | ||
|
|
ea62431c01 | ||
|
|
56f1a69a02 | ||
|
|
7c78894b8f | ||
|
|
fd415f0368 | ||
|
|
5b092c3bd5 | ||
|
|
827b18c4b5 | ||
|
|
26c1f07385 | ||
|
|
450e784992 | ||
|
|
54bef3dd03 | ||
|
|
168f05856d | ||
|
|
492b040666 | ||
|
|
471a8a0333 | ||
|
|
b07d60f16f | ||
|
|
0ea5fd43a1 | ||
|
|
64954f06cd | ||
|
|
2a08c1425f | ||
|
|
3f2756757b | ||
|
|
46374d8ab1 | ||
|
|
87a552fce1 | ||
|
|
946195be8a | ||
|
|
0c921010fb | ||
|
|
57b58520f4 | ||
|
|
064f1258cc | ||
|
|
500e5e90a5 | ||
|
|
e1148b9eea | ||
|
|
2d7e781dbe | ||
|
|
30eb43ce3e | ||
|
|
5aee8c73f3 | ||
|
|
3c83d18b9f | ||
|
|
af6e432ce8 | ||
|
|
8f9690c4f9 | ||
|
|
8d513aa2b3 | ||
|
|
307de58dc3 | ||
|
|
b9ee142d5f | ||
|
|
a30552ab40 | ||
|
|
799b33875f | ||
|
|
7e415cf3a1 | ||
|
|
755ccf02c2 | ||
|
|
8b8921899a | ||
|
|
c235c06c43 | ||
|
|
db707a1e73 | ||
|
|
80f62d3a4c | ||
|
|
1f3af8b515 | ||
|
|
26bc36e629 | ||
|
|
65c772c475 | ||
|
|
06bf0e49fc | ||
|
|
839bc1d9ec | ||
|
|
844f24ce67 | ||
|
|
a5ef06cde0 | ||
|
|
f207fde89f | ||
|
|
287e0beab9 | ||
|
|
6977ccf73f | ||
|
|
2e3ed68f90 | ||
|
|
e2c6c2d492 | ||
|
|
05cc10b1e5 | ||
|
|
94f2651890 | ||
|
|
d436ab797d | ||
|
|
a6094c40ea | ||
|
|
630792e44c | ||
|
|
9fecb86f6a | ||
|
|
ad941bb6f4 | ||
|
|
d0633e3550 | ||
|
|
82e46cf305 | ||
|
|
a77af2ef23 | ||
|
|
44fadbf9f5 | ||
|
|
9e198d0eb2 | ||
|
|
31c6e0802d | ||
|
|
a2d6f375f8 | ||
|
|
2b794ebf4a | ||
|
|
bf052acda1 | ||
|
|
9d7027f9ff | ||
|
|
5ececbbe95 | ||
|
|
92208643d0 | ||
|
|
d07e2376bd | ||
|
|
0a3faeea7a | ||
|
|
48e58f01ac | ||
|
|
20acd1614d | ||
|
|
27e0c3468c | ||
|
|
f59de0f1b3 | ||
|
|
6060d7a0c4 | ||
|
|
d65d1587a4 | ||
|
|
0f427aabdf | ||
|
|
385e55da1a | ||
|
|
61ec0b1414 | ||
|
|
6427591dd8 | ||
|
|
99e3b593f5 | ||
|
|
8833ee34f8 | ||
|
|
723becfafe | ||
|
|
8b13058a16 | ||
|
|
089f8aee59 | ||
|
|
0a338ccb53 | ||
|
|
4ace4ff7b1 | ||
|
|
418a8dabfe | ||
|
|
80ac7dce3e | ||
|
|
a4c1dce24c | ||
|
|
f4969098f6 | ||
|
|
f9f553702c | ||
|
|
c862e9c3a4 | ||
|
|
7d0d89d480 |
134
.copyright.hook
Normal file
134
.copyright.hook
Normal file
@@ -0,0 +1,134 @@
|
||||
# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
|
||||
import argparse
|
||||
import io
|
||||
import re
|
||||
import sys
|
||||
import os
|
||||
import datetime
|
||||
|
||||
COPYRIGHT = '''Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.'''
|
||||
|
||||
def _generate_copyright(comment_mark):
|
||||
copyright=COPYRIGHT.split(os.linesep)
|
||||
header = copyright[0].rstrip()
|
||||
|
||||
p = re.search('(\d{4})', header).group(0)
|
||||
now = datetime.datetime.now()
|
||||
|
||||
header = header.replace(p,str(now.year))
|
||||
|
||||
ans=[comment_mark + " " + header + os.linesep]
|
||||
for idx, line in enumerate(copyright[1:]):
|
||||
ans.append(comment_mark + " " + line.rstrip() + os.linesep)
|
||||
|
||||
return ans
|
||||
|
||||
def _get_comment_mark(path):
|
||||
lang_type=re.compile(r"\.(py|sh)$")
|
||||
if lang_type.search(path) is not None:
|
||||
return "#"
|
||||
|
||||
lang_type=re.compile(r"\.(h|c|hpp|cc|cpp|cu|go|cuh|proto)$")
|
||||
if lang_type.search(path) is not None:
|
||||
return "//"
|
||||
|
||||
return None
|
||||
|
||||
|
||||
RE_ENCODE = re.compile(r"^[ \t\v]*#.*?coding[:=]", re.IGNORECASE)
|
||||
RE_COPYRIGHT = re.compile(r".*Copyright( \(c\))* \d{4}", re.IGNORECASE)
|
||||
RE_SHEBANG = re.compile(r"^[ \t\v]*#[ \t]?\!")
|
||||
|
||||
def _check_copyright(path):
|
||||
head=[]
|
||||
try:
|
||||
with open(path) as f:
|
||||
head = [next(f) for x in range(4)]
|
||||
except StopIteration:
|
||||
pass
|
||||
|
||||
for idx, line in enumerate(head):
|
||||
if RE_COPYRIGHT.search(line) is not None:
|
||||
return True
|
||||
|
||||
return False
|
||||
|
||||
def generate_copyright(path, comment_mark):
|
||||
original_contents = io.open(path, encoding="utf-8").readlines()
|
||||
head = original_contents[0:4]
|
||||
|
||||
insert_line_no=0
|
||||
for i, line in enumerate(head):
|
||||
if RE_ENCODE.search(line) or RE_SHEBANG.search(line):
|
||||
insert_line_no=i+1
|
||||
|
||||
copyright = _generate_copyright(comment_mark)
|
||||
if insert_line_no == 0:
|
||||
new_contents = copyright
|
||||
if len(original_contents) > 0 and len(original_contents[0].strip()) != 0:
|
||||
new_contents.append(os.linesep)
|
||||
new_contents.extend(original_contents)
|
||||
else:
|
||||
new_contents=original_contents[0:insert_line_no]
|
||||
new_contents.append(os.linesep)
|
||||
new_contents.extend(copyright)
|
||||
if len(original_contents) > insert_line_no and len(original_contents[insert_line_no].strip()) != 0:
|
||||
new_contents.append(os.linesep)
|
||||
new_contents.extend(original_contents[insert_line_no:])
|
||||
new_contents="".join(new_contents)
|
||||
|
||||
with io.open(path, 'w') as output_file:
|
||||
output_file.write(new_contents)
|
||||
|
||||
|
||||
|
||||
def main(argv=None):
|
||||
parser = argparse.ArgumentParser(
|
||||
description='Checker for copyright declaration.')
|
||||
parser.add_argument('filenames', nargs='*', help='Filenames to check')
|
||||
args = parser.parse_args(argv)
|
||||
|
||||
retv = 0
|
||||
for path in args.filenames:
|
||||
comment_mark = _get_comment_mark(path)
|
||||
if comment_mark is None:
|
||||
print("warning:Unsupported file", path, file=sys.stderr)
|
||||
continue
|
||||
|
||||
if _check_copyright(path):
|
||||
continue
|
||||
|
||||
generate_copyright(path, comment_mark)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
exit(main())
|
||||
15
.github/ISSUE_TEMPLATE/----.md
vendored
15
.github/ISSUE_TEMPLATE/----.md
vendored
@@ -1,15 +0,0 @@
|
||||
---
|
||||
name: 问题反馈
|
||||
about: PaddleNLP问题反馈
|
||||
title: ''
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
欢迎您反馈PaddleNLP使用问题,非常感谢您对PaddleNLP的贡献!
|
||||
在留下您的问题时,辛苦您同步提供如下信息:
|
||||
- 版本、环境信息
|
||||
1)PaddleNLP和PaddlePaddle版本:请提供您的PaddleNLP和PaddlePaddle版本号,例如PaddleNLP 2.0.4,PaddlePaddle2.1.1
|
||||
2)系统环境:请您描述系统类型,例如Linux/Windows/MacOS/,python版本
|
||||
- 复现信息:如为报错,请给出复现环境、复现步骤
|
||||
23
.github/ISSUE_TEMPLATE/ask-question.yml
vendored
Normal file
23
.github/ISSUE_TEMPLATE/ask-question.yml
vendored
Normal file
@@ -0,0 +1,23 @@
|
||||
name: 🐛 Ask Question
|
||||
description: 请描述您使用PaddleNLP时遇到的问题
|
||||
title: "[Question]: "
|
||||
labels:
|
||||
- question
|
||||
body:
|
||||
- type: markdown
|
||||
attributes:
|
||||
value: >
|
||||
#### 你可以在这里提出一个使用/咨询问题,提问之前请确保:
|
||||
|
||||
- 1)已经百度/谷歌搜索过你的问题,但是没有找到解答;
|
||||
|
||||
- 2)已经在官网查询过[API文档](https://www.paddlepaddle.org.cn/documentation/docs/zh/api/index_cn.html)与[FAQ](https://www.paddlepaddle.org.cn/documentation/docs/zh/faq/index_cn.html),但是没有找到解答;
|
||||
|
||||
- 3)已经在[历史issue](https://github.com/PaddlePaddle/Paddle/issues)中搜索过,没有找到同类issue或issue未被解答。
|
||||
|
||||
- type: textarea
|
||||
id: question
|
||||
attributes:
|
||||
label: 请提出你的问题
|
||||
validations:
|
||||
required: true
|
||||
45
.github/ISSUE_TEMPLATE/bug-report.yml
vendored
Normal file
45
.github/ISSUE_TEMPLATE/bug-report.yml
vendored
Normal file
@@ -0,0 +1,45 @@
|
||||
name: 🐛 Bug Report
|
||||
description: PaddleNLP问题反馈
|
||||
title: "[Bug]: "
|
||||
labels: bug
|
||||
body:
|
||||
- type: textarea
|
||||
id: environment
|
||||
attributes:
|
||||
label: 软件环境
|
||||
description: |
|
||||
请使用以下命令给出您本地Paddle相关包信息
|
||||
```sh
|
||||
pip list | grep paddle
|
||||
|
||||
```
|
||||
value: |
|
||||
- paddlepaddle:
|
||||
- paddlepaddle-gpu:
|
||||
- paddlenlp:
|
||||
render: Markdown
|
||||
validations:
|
||||
required: true
|
||||
- type: checkboxes
|
||||
id: dumplicated-problem
|
||||
attributes:
|
||||
label: 重复问题
|
||||
description: 是否已在issues中搜索相关问题
|
||||
options:
|
||||
- label: I have searched the existing issues
|
||||
required: true
|
||||
- type: textarea
|
||||
id: descripton
|
||||
attributes:
|
||||
label: 错误描述
|
||||
description: 给出错误详细描述,以便能够更好的追踪相关问题
|
||||
render: Markdown
|
||||
validations:
|
||||
required: true
|
||||
- type: textarea
|
||||
id: mvp-code
|
||||
attributes:
|
||||
label: 稳定复现步骤 & 代码
|
||||
description: 请给出稳定复现该问题的步骤 & 代码,以便相关人员能够快速定位到具体问题。
|
||||
validations:
|
||||
required: true
|
||||
32
.github/ISSUE_TEMPLATE/docs-report.yml
vendored
Normal file
32
.github/ISSUE_TEMPLATE/docs-report.yml
vendored
Normal file
@@ -0,0 +1,32 @@
|
||||
name: 🐛 Docs Report
|
||||
description: PaddleNLP文档反馈
|
||||
title: "[Docs]: "
|
||||
labels:
|
||||
- documentation
|
||||
|
||||
body:
|
||||
- type: textarea
|
||||
id: environment
|
||||
attributes:
|
||||
label: 软件环境
|
||||
description: |
|
||||
请使用以下命令给出您本地Paddle相关包信息
|
||||
```sh
|
||||
pip list | grep paddle
|
||||
|
||||
```
|
||||
value: |
|
||||
- paddlepaddle:
|
||||
- paddlepaddle-gpu:
|
||||
- paddlenlp:
|
||||
render: Markdown
|
||||
validations:
|
||||
required: true
|
||||
- type: textarea
|
||||
id: description
|
||||
attributes:
|
||||
label: 详细描述
|
||||
description: 请详细描述您想要反馈的具体问题
|
||||
render: Markdown
|
||||
validations:
|
||||
required: true
|
||||
30
.github/ISSUE_TEMPLATE/feature-request.yml
vendored
Normal file
30
.github/ISSUE_TEMPLATE/feature-request.yml
vendored
Normal file
@@ -0,0 +1,30 @@
|
||||
name: "\U0001F680 Feature request"
|
||||
description: 请详细描述您所需功能
|
||||
labels: [ "feature" ]
|
||||
body:
|
||||
- type: textarea
|
||||
id: feature-request
|
||||
validations:
|
||||
required: true
|
||||
attributes:
|
||||
label: Feature request
|
||||
description: |
|
||||
对特性提案的清晰而简明的描述。如果论文和代码存在,请提供链接。
|
||||
|
||||
- type: textarea
|
||||
id: motivation
|
||||
validations:
|
||||
required: true
|
||||
attributes:
|
||||
label: Motivation
|
||||
description: |
|
||||
请概述这项建议的动机。您的特性要求与问题有关吗?
|
||||
|
||||
- type: textarea
|
||||
id: contribution
|
||||
validations:
|
||||
required: true
|
||||
attributes:
|
||||
label: Your contribution
|
||||
description: |
|
||||
Is there any way that you could help, e.g. by submitting a PR? Make sure to read the CONTRIBUTING.MD [readme](https://github.com/huggingface/transformers/blob/main/CONTRIBUTING.md)
|
||||
28
.github/ISSUE_TEMPLATE/new-model.yaml
vendored
Normal file
28
.github/ISSUE_TEMPLATE/new-model.yaml
vendored
Normal file
@@ -0,0 +1,28 @@
|
||||
name: "\U0001F31F 添加新模型"
|
||||
description: 请为新模型提交一份说明
|
||||
labels: [ "New model" ]
|
||||
|
||||
body:
|
||||
- type: textarea
|
||||
id: description-request
|
||||
validations:
|
||||
required: true
|
||||
attributes:
|
||||
label: 简要描述
|
||||
description: |
|
||||
请简要描述模型的类型、解决的问题等。
|
||||
|
||||
- type: checkboxes
|
||||
id: information-tasks
|
||||
attributes:
|
||||
label: 是否已开源
|
||||
options:
|
||||
- label: 已开源
|
||||
- label: 未开源
|
||||
|
||||
- type: textarea
|
||||
id: additional-info
|
||||
attributes:
|
||||
label: 模型详细信息
|
||||
description: |
|
||||
请给出新模型相关信息,如论文地址、现存代码地址等。
|
||||
23
.github/ISSUE_TEMPLATE/others.yml
vendored
Normal file
23
.github/ISSUE_TEMPLATE/others.yml
vendored
Normal file
@@ -0,0 +1,23 @@
|
||||
name: 🧩 其他 Others
|
||||
description: 提出其他问题。
|
||||
labels: [others]
|
||||
|
||||
body:
|
||||
- type: markdown
|
||||
attributes:
|
||||
value: >
|
||||
#### 你可以在这里提出任何前面几类模板不适用的问题,包括但不限于:优化性建议、框架使用体验反馈、版本兼容性问题、报错信息不清楚等。
|
||||
|
||||
- type: textarea
|
||||
id: others
|
||||
attributes:
|
||||
label: 问题描述
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: markdown
|
||||
attributes:
|
||||
value: >
|
||||
感谢你的贡献 🎉!
|
||||
|
||||
|
||||
60
.github/workflows/pypi.yml
vendored
Normal file
60
.github/workflows/pypi.yml
vendored
Normal file
@@ -0,0 +1,60 @@
|
||||
name: PyPI
|
||||
|
||||
on: [push, pull_request]
|
||||
|
||||
jobs:
|
||||
build:
|
||||
name: Build
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- uses: actions/setup-python@v1
|
||||
with:
|
||||
python-version: 3.8
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install -r requirements.txt
|
||||
pip install -r docs/requirements.txt
|
||||
pip install -r ppdiffusers/requirements.txt
|
||||
|
||||
ppdiffusers:
|
||||
name: Pack
|
||||
needs: build
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- uses: actions/setup-python@v1
|
||||
with:
|
||||
python-version: 3.8
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install setuptools wheel twine
|
||||
make install-ppdiffusers
|
||||
|
||||
- name: Should Deploy to Pypi Server
|
||||
id: should-deploy
|
||||
run: python scripts/should_deploy.py --name ppdiffusers >> $GITHUB_OUTPUT
|
||||
- name: Check Branch
|
||||
id: check-branch
|
||||
run: |
|
||||
if [[ ${{ github.ref }} =~ ^refs/heads/(develop)$ ]]; then
|
||||
echo "match=true" >> $GITHUB_OUTPUT
|
||||
fi # See: https://stackoverflow.com/a/58869470/1123955
|
||||
|
||||
- name: Is A Publish Branch
|
||||
if: steps.check-branch.outputs.match == 'true' && steps.should-deploy.outputs.should_deploy == 'true'
|
||||
env:
|
||||
TWINE_USERNAME: paddle-dev
|
||||
TWINE_PASSWORD: ${{ secrets.paddlenlp }}
|
||||
run: |
|
||||
make deploy-ppdiffusers
|
||||
|
||||
- name: Should Not Deploy To Pypi Server
|
||||
if: steps.should-deploy.outputs.should_deploy != 'true'
|
||||
run: echo 'should not deploy pypi server'
|
||||
|
||||
- name: Is Not A Publish Branch
|
||||
if: steps.check-branch.outputs.match != 'true'
|
||||
run: echo 'Not A Publish Branch'
|
||||
2
.gitignore
vendored
2
.gitignore
vendored
@@ -53,6 +53,7 @@ coverage.xml
|
||||
# Translations
|
||||
*.mo
|
||||
*.pot
|
||||
*.doctree
|
||||
|
||||
# Django stuff:
|
||||
*.log
|
||||
@@ -122,3 +123,4 @@ FETCH_HEAD
|
||||
|
||||
# vscode
|
||||
.vscode
|
||||
./ppdiffusers/ppdiffusers/version.py
|
||||
@@ -1,11 +1,11 @@
|
||||
repos:
|
||||
- repo: https://github.com/PaddlePaddle/mirrors-yapf.git
|
||||
sha: 0d79c0c469bab64f7229c9aca2b1186ef47f0e37
|
||||
- repo: https://github.com/google/yapf
|
||||
rev: v0.32.0
|
||||
hooks:
|
||||
- id: yapf
|
||||
files: \.py$
|
||||
- repo: https://github.com/pre-commit/pre-commit-hooks
|
||||
sha: a11d9314b22d8f8c7556443875b731ef05965464
|
||||
rev: v4.1.0
|
||||
hooks:
|
||||
- id: check-merge-conflict
|
||||
- id: check-symlinks
|
||||
@@ -16,7 +16,7 @@ repos:
|
||||
- id: trailing-whitespace
|
||||
files: \.md$
|
||||
- repo: https://github.com/Lucas-C/pre-commit-hooks
|
||||
sha: v1.0.1
|
||||
rev: v1.1.14
|
||||
hooks:
|
||||
- id: forbid-crlf
|
||||
files: \.md$
|
||||
@@ -28,9 +28,8 @@ repos:
|
||||
files: \.md$
|
||||
- repo: local
|
||||
hooks:
|
||||
- id: clang-format
|
||||
name: clang-format
|
||||
description: Format files with ClangFormat
|
||||
entry: bash .clang_format.hook -i
|
||||
- id: copyright_checker
|
||||
name: copyright_checker
|
||||
entry: python .copyright.hook
|
||||
language: system
|
||||
files: \.(c|cc|cxx|cpp|cu|h|hpp|hxx|cuh|proto)$
|
||||
files: \.(c|cc|cxx|cpp|cu|h|hpp|hxx|proto|xpu|kps|py|sh)$
|
||||
|
||||
@@ -19,7 +19,7 @@ sphinx:
|
||||
|
||||
# Optionally set the version of Python and requirements required to build your docs
|
||||
python:
|
||||
version: 3.7
|
||||
version: 3.8
|
||||
install:
|
||||
- requirements: docs/requirements.txt
|
||||
- requirements: requirements.txt
|
||||
|
||||
88
CODE_OF_CONDUCT.md
Normal file
88
CODE_OF_CONDUCT.md
Normal file
@@ -0,0 +1,88 @@
|
||||
|
||||
# 贡献者公约
|
||||
|
||||
## 我们的承诺
|
||||
|
||||
身为社区成员、贡献者和领袖,我们承诺使社区参与者不受骚扰,无论其年龄、体型、可见或不可见的缺陷、族裔、性征、性别认同和表达、经验水平、教育程度、社会与经济地位、国籍、相貌、种族、种姓、肤色、宗教信仰、性倾向或性取向如何。
|
||||
|
||||
我们承诺以有助于建立开放、友善、多样化、包容、健康社区的方式行事和互动。
|
||||
|
||||
## 我们的准则
|
||||
|
||||
有助于为我们的社区创造积极环境的行为例子包括但不限于:
|
||||
|
||||
* 表现出对他人的同情和善意
|
||||
* 尊重不同的主张、观点和感受
|
||||
* 提出和大方接受建设性意见
|
||||
* 承担责任并向受我们错误影响的人道歉
|
||||
* 注重社区共同诉求,而非个人得失
|
||||
|
||||
不当行为例子包括:
|
||||
|
||||
* 使用情色化的语言或图像,及性引诱或挑逗
|
||||
* 嘲弄、侮辱或诋毁性评论,以及人身或政治攻击
|
||||
* 公开或私下的骚扰行为
|
||||
* 未经他人明确许可,公布他人的私人信息,如物理或电子邮件地址
|
||||
* 其他有理由认定为违反职业操守的不当行为
|
||||
|
||||
## 责任和权力
|
||||
|
||||
社区领袖有责任解释和落实我们所认可的行为准则,并妥善公正地对他们认为不当、威胁、冒犯或有害的任何行为采取纠正措施。
|
||||
|
||||
社区领导有权力和责任删除、编辑或拒绝或拒绝与本行为准则不相符的评论(comment)、提交(commits)、代码、维基(wiki)编辑、议题(issues)或其他贡献,并在适当时机知采取措施的理由。
|
||||
|
||||
## 适用范围
|
||||
|
||||
本行为准则适用于所有社区场合,也适用于在公共场所代表社区时的个人。
|
||||
|
||||
代表社区的情形包括使用官方电子邮件地址、通过官方社交媒体帐户发帖或在线上或线下活动中担任指定代表。
|
||||
|
||||
## 监督
|
||||
|
||||
辱骂、骚扰或其他不可接受的行为可通过 paddlenlp@baidu.com 向负责监督的社区领袖报告。
|
||||
所有投诉都将得到及时和公平的审查和调查。
|
||||
|
||||
所有社区领袖都有义务尊重任何事件报告者的隐私和安全。
|
||||
|
||||
## 处理方针
|
||||
|
||||
社区领袖将遵循下列社区处理方针来明确他们所认定违反本行为准则的行为的处理方式:
|
||||
|
||||
### 1. 纠正
|
||||
|
||||
**社区影响**:使用不恰当的语言或其他在社区中被认定为不符合职业道德或不受欢迎的行为。
|
||||
|
||||
**处理意见**:由社区领袖发出非公开的书面警告,明确说明违规行为的性质,并解释举止如何不妥。或将要求公开道歉。
|
||||
|
||||
### 2. 警告
|
||||
|
||||
**社区影响**:单个或一系列违规行为。
|
||||
|
||||
**处理意见**:警告并对连续性行为进行处理。在指定时间内,不得与相关人员互动,包括主动与行为准则执行者互动。这包括避免在社区场所和外部渠道中的互动。违反这些条款可能会导致临时或永久封禁。
|
||||
|
||||
### 3. 临时封禁
|
||||
|
||||
**社区影响**: 严重违反社区准则,包括持续的不当行为。
|
||||
|
||||
**处理意见**: 在指定时间内,暂时禁止与社区进行任何形式的互动或公开交流。在此期间,不得与相关人员进行公开或私下互动,包括主动与行为准则执行者互动。违反这些条款可能会导致永久封禁。
|
||||
|
||||
### 4. 永久封禁
|
||||
|
||||
**社区影响**:行为模式表现出违反社区准则,包括持续的不当行为、骚扰个人或攻击或贬低某个类别的个体。
|
||||
|
||||
**处理意见**:永久禁止在社区内进行任何形式的公开互动。
|
||||
|
||||
## 参见
|
||||
|
||||
本行为准则改编自 [Contributor Covenant][homepage] 2.1 版, 参见 [https://www.contributor-covenant.org/version/2/1/code_of_conduct.html][v2.1]。
|
||||
|
||||
社区处理方针灵感来源于 [Mozilla's code of conduct enforcement ladder][Mozilla CoC]。
|
||||
|
||||
有关本行为准则的常见问题的答案,参见 [https://www.contributor-covenant.org/faq][FAQ]。
|
||||
其他语言翻译参见 [https://www.contributor-covenant.org/translations][translations]。
|
||||
|
||||
[homepage]: https://www.contributor-covenant.org
|
||||
[v2.1]: https://www.contributor-covenant.org/version/2/1/code_of_conduct.html
|
||||
[Mozilla CoC]: https://github.com/mozilla/diversity
|
||||
[FAQ]: https://www.contributor-covenant.org/faq
|
||||
[translations]: https://www.contributor-covenant.org/translations
|
||||
133
CODE_OF_CONDUCT_en.md
Normal file
133
CODE_OF_CONDUCT_en.md
Normal file
@@ -0,0 +1,133 @@
|
||||
|
||||
# Contributor Covenant Code of Conduct
|
||||
|
||||
## Our Pledge
|
||||
|
||||
We as members, contributors, and leaders pledge to make participation in our
|
||||
community a harassment-free experience for everyone, regardless of age, body
|
||||
size, visible or invisible disability, ethnicity, sex characteristics, gender
|
||||
identity and expression, level of experience, education, socio-economic status,
|
||||
nationality, personal appearance, race, caste, color, religion, or sexual
|
||||
identity and orientation.
|
||||
|
||||
We pledge to act and interact in ways that contribute to an open, welcoming,
|
||||
diverse, inclusive, and healthy community.
|
||||
|
||||
## Our Standards
|
||||
|
||||
Examples of behavior that contributes to a positive environment for our
|
||||
community include:
|
||||
|
||||
* Demonstrating empathy and kindness toward other people
|
||||
* Being respectful of differing opinions, viewpoints, and experiences
|
||||
* Giving and gracefully accepting constructive feedback
|
||||
* Accepting responsibility and apologizing to those affected by our mistakes,
|
||||
and learning from the experience
|
||||
* Focusing on what is best not just for us as individuals, but for the overall
|
||||
community
|
||||
|
||||
Examples of unacceptable behavior include:
|
||||
|
||||
* The use of sexualized language or imagery, and sexual attention or advances of
|
||||
any kind
|
||||
* Trolling, insulting or derogatory comments, and personal or political attacks
|
||||
* Public or private harassment
|
||||
* Publishing others' private information, such as a physical or email address,
|
||||
without their explicit permission
|
||||
* Other conduct which could reasonably be considered inappropriate in a
|
||||
professional setting
|
||||
|
||||
## Enforcement Responsibilities
|
||||
|
||||
Community leaders are responsible for clarifying and enforcing our standards of
|
||||
acceptable behavior and will take appropriate and fair corrective action in
|
||||
response to any behavior that they deem inappropriate, threatening, offensive,
|
||||
or harmful.
|
||||
|
||||
Community leaders have the right and responsibility to remove, edit, or reject
|
||||
comments, commits, code, wiki edits, issues, and other contributions that are
|
||||
not aligned to this Code of Conduct, and will communicate reasons for moderation
|
||||
decisions when appropriate.
|
||||
|
||||
## Scope
|
||||
|
||||
This Code of Conduct applies within all community spaces, and also applies when
|
||||
an individual is officially representing the community in public spaces.
|
||||
Examples of representing our community include using an official e-mail address,
|
||||
posting via an official social media account, or acting as an appointed
|
||||
representative at an online or offline event.
|
||||
|
||||
## Enforcement
|
||||
|
||||
Instances of abusive, harassing, or otherwise unacceptable behavior may be
|
||||
reported to the community leaders responsible for enforcement at
|
||||
paddlenlp@baidu.com.
|
||||
All complaints will be reviewed and investigated promptly and fairly.
|
||||
|
||||
All community leaders are obligated to respect the privacy and security of the
|
||||
reporter of any incident.
|
||||
|
||||
## Enforcement Guidelines
|
||||
|
||||
Community leaders will follow these Community Impact Guidelines in determining
|
||||
the consequences for any action they deem in violation of this Code of Conduct:
|
||||
|
||||
### 1. Correction
|
||||
|
||||
**Community Impact**: Use of inappropriate language or other behavior deemed
|
||||
unprofessional or unwelcome in the community.
|
||||
|
||||
**Consequence**: A private, written warning from community leaders, providing
|
||||
clarity around the nature of the violation and an explanation of why the
|
||||
behavior was inappropriate. A public apology may be requested.
|
||||
|
||||
### 2. Warning
|
||||
|
||||
**Community Impact**: A violation through a single incident or series of
|
||||
actions.
|
||||
|
||||
**Consequence**: A warning with consequences for continued behavior. No
|
||||
interaction with the people involved, including unsolicited interaction with
|
||||
those enforcing the Code of Conduct, for a specified period of time. This
|
||||
includes avoiding interactions in community spaces as well as external channels
|
||||
like social media. Violating these terms may lead to a temporary or permanent
|
||||
ban.
|
||||
|
||||
### 3. Temporary Ban
|
||||
|
||||
**Community Impact**: A serious violation of community standards, including
|
||||
sustained inappropriate behavior.
|
||||
|
||||
**Consequence**: A temporary ban from any sort of interaction or public
|
||||
communication with the community for a specified period of time. No public or
|
||||
private interaction with the people involved, including unsolicited interaction
|
||||
with those enforcing the Code of Conduct, is allowed during this period.
|
||||
Violating these terms may lead to a permanent ban.
|
||||
|
||||
### 4. Permanent Ban
|
||||
|
||||
**Community Impact**: Demonstrating a pattern of violation of community
|
||||
standards, including sustained inappropriate behavior, harassment of an
|
||||
individual, or aggression toward or disparagement of classes of individuals.
|
||||
|
||||
**Consequence**: A permanent ban from any sort of public interaction within the
|
||||
community.
|
||||
|
||||
## Attribution
|
||||
|
||||
This Code of Conduct is adapted from the [Contributor Covenant][homepage],
|
||||
version 2.1, available at
|
||||
[https://www.contributor-covenant.org/version/2/1/code_of_conduct.html][v2.1].
|
||||
|
||||
Community Impact Guidelines were inspired by
|
||||
[Mozilla's code of conduct enforcement ladder][Mozilla CoC].
|
||||
|
||||
For answers to common questions about this code of conduct, see the FAQ at
|
||||
[https://www.contributor-covenant.org/faq][FAQ]. Translations are available at
|
||||
[https://www.contributor-covenant.org/translations][translations].
|
||||
|
||||
[homepage]: https://www.contributor-covenant.org
|
||||
[v2.1]: https://www.contributor-covenant.org/version/2/1/code_of_conduct.html
|
||||
[Mozilla CoC]: https://github.com/mozilla/diversity
|
||||
[FAQ]: https://www.contributor-covenant.org/faq
|
||||
[translations]: https://www.contributor-covenant.org/translations
|
||||
10
Makefile
Normal file
10
Makefile
Normal file
@@ -0,0 +1,10 @@
|
||||
|
||||
|
||||
.PHONY: deploy-ppdiffusers
|
||||
deploy-ppdiffusers:
|
||||
cd ppdiffusers && make
|
||||
|
||||
.PHONY: install-ppdiffusers
|
||||
install-ppdiffusers:
|
||||
cd ppdiffusers && make install
|
||||
|
||||
318
README.md
318
README.md
@@ -1,318 +0,0 @@
|
||||
简体中文 | [English](./README_en.md)
|
||||
|
||||
<p align="center">
|
||||
<img src="./docs/imgs/paddlenlp.png" width="718" height ="100" />
|
||||
</p>
|
||||
|
||||
------------------------------------------------------------------------------------------
|
||||
[](https://pypi.org/project/paddlenlp/)
|
||||
[](https://pypi.org/project/paddlenlp/)
|
||||
[](https://pepy.tech/project/paddlenlp)
|
||||

|
||||

|
||||
|
||||
|
||||
## News <img src="./docs/imgs/news_icon.png" width="40"/>
|
||||
* [2021-10-12] PaddleNLP 2.1版本已发布!新增开箱即用的NLP任务能力、Prompt Tuning应用示例与生成任务的高性能推理!:tada:更多详细升级信息请查看[Release Note](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.1.0)。
|
||||
* [2021-08-22][《千言:面向事实一致性的生成评测比赛》](https://aistudio.baidu.com/aistudio/competition/detail/105)正式开赛啦🔥🔥🔥,欢迎大家踊跃报名!! [PaddleNLP比赛基线地址](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/examples/text_generation/unimo-text)。
|
||||
|
||||
|
||||
## 简介
|
||||
|
||||
PaddleNLP是飞桨自然语言处理开发库,具备**易用的文本领域API**,**多场景的应用示例**、和**高性能分布式训练**三大特点,旨在提升开发者在文本领域的开发效率,并提供丰富的NLP应用示例。
|
||||
|
||||
- **易用的文本领域API**
|
||||
- 提供丰富的产业级预置任务能力[Taskflow](./docs/model_zoo/taskflow.md)和全流程的文本领域API:支持丰富中文数据集加载的[Dataset API](https://paddlenlp.readthedocs.io/zh/latest/data_prepare/dataset_list.html);灵活高效地完成数据预处理的[Data API](https://paddlenlp.readthedocs.io/zh/latest/source/paddlenlp.data.html);提供60+预训练模型的[Transformer API](./docs/model_zoo/transformers.rst)等,可大幅提升NLP任务建模的效率。
|
||||
|
||||
- **多场景的应用示例**
|
||||
- 覆盖从学术到工业级的NLP[应用示例](#多场景的应用示例),涵盖NLP基础技术、NLP核心技术、NLP系统应用以及相关拓展应用。全面基于飞桨核心框架2.0全新API体系开发,为开发者提供飞桨文本领域的最佳实践。
|
||||
|
||||
- **高性能分布式训练**
|
||||
- 基于飞桨核心框架领先的自动混合精度优化策略,结合分布式Fleet API,支持4D混合并行策略,可高效地完成超大规模参数的模型训练。
|
||||
|
||||
## 安装
|
||||
|
||||
### 环境依赖
|
||||
|
||||
- python >= 3.6
|
||||
- paddlepaddle >= 2.1
|
||||
|
||||
### pip安装
|
||||
|
||||
```shell
|
||||
pip install --upgrade paddlenlp
|
||||
```
|
||||
|
||||
更多关于PaddlePaddle和PaddleNLP安装的详细教程请查看[Installation](./docs/get_started/installation.rst)。
|
||||
|
||||
## 易用的文本领域API
|
||||
|
||||
### Taskflow:开箱即用的工业级NLP能力
|
||||
|
||||
Taskflow旨在提供**开箱即用**的NLP预置任务能力,覆盖自然语言理解与生成两大场景,提供**工业级的效果**与**极致的预测性能**。
|
||||
|
||||
```python
|
||||
from paddlenlp import Taskflow
|
||||
|
||||
# 中文分词
|
||||
seg = Taskflow("word_segmentation")
|
||||
seg("第十四届全运会在西安举办")
|
||||
>>> ['第十四届', '全运会', '在', '西安', '举办']
|
||||
|
||||
# 词性标注
|
||||
tag = Taskflow("pos_tagging")
|
||||
tag("第十四届全运会在西安举办")
|
||||
>>> [('第十四届', 'm'), ('全运会', 'nz'), ('在', 'p'), ('西安', 'LOC'), ('举办', 'v')]
|
||||
|
||||
# 命名实体识别
|
||||
ner = Taskflow("ner")
|
||||
ner("《孤女》是2010年九州出版社出版的小说,作者是余兼羽")
|
||||
>>> [('《', 'w'), ('孤女', '作品类_实体'), ('》', 'w'), ('是', '肯定词'), ('2010年', '时间类'), ('九州出版社', '组织机构类'), ('出版', '场景事件'), ('的', '助词'), ('小说', '作品类_概念'), (',', 'w'), ('作者', '人物类_概念'), ('是', '肯定词'), ('余兼羽', '人物类_实体')]
|
||||
|
||||
# 句法分析
|
||||
ddp = Taskflow("dependency_parsing")
|
||||
ddp("百度是一家高科技公司")
|
||||
>>> [{'word': ['百度', '是', '一家', '高科技', '公司'], 'head': ['2', '0', '5', '5', '2'], 'deprel': ['SBV', 'HED', 'ATT', 'ATT', 'VOB']}]
|
||||
|
||||
# 情感分析
|
||||
senta = Taskflow("sentiment_analysis")
|
||||
senta("怀着十分激动的心情放映,可是看着看着发现,在放映完毕后,出现一集米老鼠的动画片")
|
||||
>>> [{'text': '怀着十分激动的心情放映,可是看着看着发现,在放映完毕后,出现一集米老鼠的动画片', 'label': 'negative', 'score': 0.6691398620605469}]
|
||||
```
|
||||
更多使用方法请参考[Taskflow文档](./docs/model_zoo/taskflow.md)
|
||||
|
||||
### Transformer API: 强大的预训练模型生态底座
|
||||
|
||||
覆盖**22**个网络结构和**90**余个预训练模型参数,既包括百度自研的预训练模型如ERNIE系列, PLATO, SKEP等,也涵盖业界主流的中文预训练模型如。欢迎开发者贡献更多预训练模型!🤗
|
||||
|
||||
```python
|
||||
from paddlenlp.transformers import *
|
||||
|
||||
ernie = ErnieModel.from_pretrained('ernie-1.0')
|
||||
ernie_gram = ErnieGramModel.from_pretrained('ernie-gram-zh')
|
||||
bert = BertModel.from_pretrained('bert-wwm-chinese')
|
||||
albert = AlbertModel.from_pretrained('albert-chinese-tiny')
|
||||
roberta = RobertaModel.from_pretrained('roberta-wwm-ext')
|
||||
electra = ElectraModel.from_pretrained('chinese-electra-small')
|
||||
gpt = GPTForPretraining.from_pretrained('gpt-cpm-large-cn')
|
||||
```
|
||||
|
||||
对预训练模型应用范式如语义表示、文本分类、句对匹配、序列标注、问答等,提供统一的API体验。
|
||||
|
||||
```python
|
||||
import paddle
|
||||
from paddlenlp.transformers import ErnieTokenizer, ErnieModel
|
||||
|
||||
tokenizer = ErnieTokenizer.from_pretrained('ernie-1.0')
|
||||
text = tokenizer('自然语言处理')
|
||||
|
||||
# 语义表示
|
||||
model = ErnieModel.from_pretrained('ernie-1.0')
|
||||
sequence_output, pooled_output = model(input_ids=paddle.to_tensor([text['input_ids']]))
|
||||
# 文本分类 & 句对匹配
|
||||
model = ErnieForSequenceClassification.from_pretrained('ernie-1.0')
|
||||
# 序列标注
|
||||
model = ErnieForTokenClassification.from_pretrained('ernie-1.0')
|
||||
# 问答
|
||||
model = ErnieForQuestionAnswering.from_pretrained('ernie-1.0')
|
||||
```
|
||||
|
||||
请参考[Transformer API文档](./docs/model_zoo/transformers.rst)查看目前支持的预训练模型结构、参数和详细用法。
|
||||
|
||||
### Dataset API: 丰富的中文数据集
|
||||
|
||||
Dataset API提供便捷、高效的数据集加载功能;内置[千言数据集](https://www.luge.ai/),提供丰富的面向自然语言理解与生成场景的中文数据集,为NLP研究人员提供一站式的科研体验。
|
||||
|
||||
```python
|
||||
from paddlenlp.datasets import load_dataset
|
||||
|
||||
train_ds, dev_ds, test_ds = load_dataset("chnsenticorp", splits=["train", "dev", "test"])
|
||||
|
||||
train_ds, dev_ds = load_dataset("lcqmc", splits=["train", "dev"])
|
||||
```
|
||||
|
||||
可参考[Dataset文档](https://paddlenlp.readthedocs.io/zh/latest/data_prepare/dataset_list.html) 查看更多数据集。
|
||||
|
||||
### Embedding API: 一键加载预训练词向量
|
||||
|
||||
```python
|
||||
from paddlenlp.embeddings import TokenEmbedding
|
||||
|
||||
wordemb = TokenEmbedding("w2v.baidu_encyclopedia.target.word-word.dim300")
|
||||
print(wordemb.cosine_sim("国王", "王后"))
|
||||
>>> 0.63395125
|
||||
wordemb.cosine_sim("艺术", "火车")
|
||||
>>> 0.14792643
|
||||
```
|
||||
|
||||
内置50+中文词向量,覆盖多种领域语料、如百科、新闻、微博等。更多使用方法请参考[Embedding文档](./docs/model_zoo/embeddings.md)。
|
||||
|
||||
### 更多API使用文档
|
||||
|
||||
- [Data API](./docs/data.md): 提供便捷高效的文本数据处理功能
|
||||
- [Metrics API](./docs/metrics.md): 提供NLP任务的评估指标,与飞桨高层API兼容。
|
||||
|
||||
更多的API示例与使用说明请查阅[PaddleNLP官方文档](https://paddlenlp.readthedocs.io/)
|
||||
|
||||
## 多场景的应用示例
|
||||
|
||||
PaddleNLP提供了多粒度、多场景的NLP应用示例,面向动态图模式和全新的API体系开发,更加简单易懂。
|
||||
涵盖了[NLP基础技术](#nlp-基础技术)、[NLP核心技术](#nlp-核心技术)、[NLP系统应用](#nlp-系统应用)以及文本相关的拓展应用如[模型压缩](./examples/model_compression/)、与知识库结合的[文本知识关联](./examples/text_to_knowledge)、与图结合的[文本图学习](./examples/text_graph/)等。
|
||||
|
||||
### NLP 基础技术
|
||||
|
||||
| 任务 | 简介 |
|
||||
| :------------ | ---- |
|
||||
| [词向量](./examples/word_embedding/) | 利用`TokenEmbedding API`展示如何快速计算词之间语义距离和词的特征提取。 |
|
||||
| [词法分析](./examples/lexical_analysis/) | 基于BiGRU-CRF模型实现了分词、词性标注和命名实体识的联合训练任务。 |
|
||||
| [语言模型](./examples/language_model/) | 提供了基于[RNNLM](./examples/language_model/rnnlm)和[Transformer-XL](./examples/language_model/transformer-xl)两种结构的语言模型,支持输入词序列计算其生成概率,可用于表示模型生成句子的流利程度。 |
|
||||
| [语义解析](./examples/text_to_sql):star: | 语义解析Text-to-SQL任务是让机器自动让自然语言问题转换数据库可操作的SQL查询语句,是实现基于数据库自动问答的核心模块。|
|
||||
|
||||
### NLP 核心技术
|
||||
|
||||
#### 文本分类 (Text Classification)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :----- | ------ |
|
||||
| [RNN/CNN/GRU/LSTM](./examples/text_classification/rnn) | 实现了经典的RNN, CNN, GRU, LSTM等经典文本分类结构。|
|
||||
| [BiLSTM-Attention](./examples/text_classification/rnn) | 基于BiLSTM网络结构引入注意力机制提升文本分类效果。 |
|
||||
| [BERT/ERNIE](./examples/text_classification/pretrained_models) | 提供基于预训练模型的文本分类任务实现,包含训练、预测和推理部署的全流程应用。 |
|
||||
|
||||
#### 文本匹配 (Text Matching)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :--------------- | ---------- |
|
||||
| [SimCSE](./examples/text_matching/simcse/):star2: | 基于论文[SimCSE: Simple Contrastive Learning of Sentence Embeddings](https://arxiv.org/abs/2104.08821)实现无监督语义匹配模型,无需标注数据仅利用无监督数据也能训练效果出众的语义匹配模型。|
|
||||
| [ERNIE-Gram w/ R-Drop](./examples/text_matching/question_matching/) | 提供基于ERNIE-Gram预训练模型结合R-Drop策略的问题匹配任在千言数据集上的基线代码。|
|
||||
| [SimNet](./examples/text_matching/simnet/) | 百度自研的语义匹配框架,使用BOW、CNN、GRNN等核心网络作为表示层,在百度内搜索、推荐等多个应用场景得到广泛易用。|
|
||||
| [ERNIE](./examples/text_matching/ernie_matching/) | 基于ERNIE使用LCQMC数据完成中文句对匹配任务,提供了Pointwise和Pairwise两种类型学习方式。 |
|
||||
| [Sentence-BERT](./examples/text_matching/sentence_transformers/) | 提供基于Siamese双塔结构的文本匹配模型[Sentence-BERT](https://arxiv.org/abs/1908.1008)实现,可用于获取文本的向量化表示。 |
|
||||
| [SimBERT](./examples/text_matching/simbert/) | 提供[SimBERT](https://github.com/ZhuiyiTechnology/simbert)模型实现,用于获取文本的向量化表示。|
|
||||
|
||||
#### 文本生成 (Text Generation)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :------------ | ---------- |
|
||||
| [Seq2Seq](./examples/text_generation/couplet) | 实现了经典的Seq2Seq with Attention的网络结构,并提供在自动对联的文本生成应用示例。 |
|
||||
| [VAE-Seq2Seq](./examples/text_generation/vae-seq2seq) | 在Seq2Seq框架基础上,加入VAE结构以实现更加多样化的文本生成。|
|
||||
| [ERNIE-GEN](./examples/text_generation/ernie-gen) | [ERNIE-GEN](https://arxiv.org/abs/2001.11314)是百度NLP提出的基于多流(multi-flow)机制生成完整语义片段的预训练模型,基于该模型实现了提供了智能写诗的应用示例。|
|
||||
|
||||
#### 文本纠错 (Text Correction)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :------------ | ---------- |
|
||||
| [ERNIE-CSC](./examples/text_correction/ernie-csc):star1: | [ERNIE-CSC](https://aclanthology.org/2021.findings-acl.198.pdf)是基于ERNIE预训练模型融合了拼音特征的端到端中文拼写纠错模型,在SIGHAN数据集上取得SOTA的效果。|
|
||||
|
||||
#### 语义索引 (Semantic Indexing)
|
||||
|
||||
提供一套完整的语义索引开发流程,并提供了In-Batch Negative和Hardest Negatives两种策略,开发者可基于该示例实现一个轻量级的语义索引系统,更多信息请查看[语义索引应用示例](./examples/semantic_indexing/)。
|
||||
|
||||
#### 信息抽取 (Information Extraction)
|
||||
|
||||
| 任务 | 简介 |
|
||||
| :--------------- | ---- |
|
||||
| [DuEE](./examples/information_extraction/DuEE/) | 基于[DuEE](https://link.springer.com/chapter/10.1007/978-3-030-60457-8_44)数据集,使用预训练模型的方式提供句子级和篇章级的事件抽取示例。 |
|
||||
| [DuIE](./examples/information_extraction/DuIE/) | 基于[DuIE](http://tcci.ccf.org.cn/conference/2019/papers/EV10.pdf)数据集,使用预训练模型的方式提供关系抽取示例。 |
|
||||
| [快递单信息抽取](./examples/information_extraction/waybill_ie/) | 提供BiLSTM+CRF和预训练模型两种方式完成真实的快递单信息抽取案例。 |
|
||||
|
||||
### NLP 系统应用
|
||||
|
||||
#### 情感分析 (Sentiment Analysis)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :--------- | ---------- |
|
||||
| [SKEP](./examples/sentiment_analysis/skep/):star2: | [SKEP](https://arxiv.org/abs/2005.05635)是百度提出的基于情感知识增强的预训练算法,利用无监督挖掘的海量情感知识构建预训练目标,让模型更好理解情感语义,可为各类情感分析任务提供统一且强大的情感语义表示。 |
|
||||
|
||||
#### 阅读理解 (Machine Reading Comprehension)
|
||||
|
||||
| 任务 | 简介 |
|
||||
| :------------------- | ---- |
|
||||
| [SQuAD](./examples/machine_reading_comprehension/SQuAD/) | 提供预训练模型在SQuAD 2.0数据集上微调的应用示例。 |
|
||||
| [DuReader-yesno](./examples/machine_reading_comprehension/DuReader-yesno/) | 提供预训练模型在**千言数据集DuReader-yesno**上微调的应用示例。 |
|
||||
| [DuReader-robust](./examples/machine_reading_comprehension/DuReader-robust/) | 提供预训练模型在**千言数据集DuReader-robust**上微调的应用示例。 |
|
||||
|
||||
#### 文本翻译 (Text Translation)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :--------------- | ------- |
|
||||
| [Seq2Seq-Attn](./examples/machine_translation/seq2seq) | 提供了[Effective Approaches to Attention-based Neural Machine Translation](https://arxiv.org/abs/1508.04025v5)基于注意力机制改进的Seq2Seq经典神经网络机器翻译模型实现。|
|
||||
| [Transformer](./examples/machine_translation/transformer) | 提供了基于[Attention Is All You Need](https://arxiv.org/abs/1706.03762)论文的Transformer机器翻译实现,包含了完整的训练到推理部署的全流程实现。|
|
||||
|
||||
#### 同传翻译 (Simultaneous Translation)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :---------- | ------- |
|
||||
| [STACL](./examples/simultaneous_translation/stacl) :star:| [STACL](https://www.aclweb.org/anthology/P19-1289/)是百度自研的基于Prefix-to-Prefix框架的同传翻译模型,结合Wait-k策略可以在保持较高的翻译质量的同时实现任意字级别的翻译延迟,并提供了轻量级同声传译系统搭建教程。|
|
||||
|
||||
#### 对话系统 (Dialogue System)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :---------------- | ------|
|
||||
| [PLATO-2](./examples/dialogue/plato-2) | [PLATO-2](https://arxiv.org/abs/2006.16779)是百度自研领先的基于课程学习两阶段方式训练的开放域对话预训练模型。|
|
||||
| [PLATO-mini](./examples/dialogue/unified_transformer):star2: | 基于6层UnifiedTransformer预训练结构,结合海量中文对话语料数据预训练的轻量级**中文**闲聊对话模型。|
|
||||
|
||||
### 拓展应用
|
||||
|
||||
#### 文本知识关联 (Text to Knowledge)
|
||||
|
||||
:star2:[**解语**](./examples/text_to_knowledge/)是由百度知识图谱部开发的文本知识关联框架,覆盖中文全词类的知识库和知识标注工具,能够帮助开发者面对更加多元的应用场景,方便地融合自有知识体系,显著提升中文文本解析和挖掘效果,还可以便捷地利用知识增强机器学习模型效果。
|
||||
|
||||
* [TermTree: 中文全词类的知识库](./examples/text_to_knowledge/termtree):star2:
|
||||
* [WordTag: 中文词类知识标注工具](./examples/text_to_knowledge/wordtag):star2:
|
||||
|
||||
#### 文本图学习 (Text Graph Learning)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :------------ | ------- |
|
||||
| [ERNIESage](./examples/text_graph/erniesage)| 基于[飞桨PGL](https://github.com/PaddlePaddle/PGL)图学习框架结合PaddleNLP Transformer API实现的文本与图结构融合的模型。|
|
||||
|
||||
#### 模型压缩 (Model Compression)
|
||||
|
||||
| 模型 | 简介 |
|
||||
| :--------------------------------------------------------- | ------------------------------------------------------------ |
|
||||
| [MiniLMv2](examples/model_compression/minilmv2) :star2: | 基于[MiniLMv2: Multi-Head Self-Attention Relation Distillation for Compressing Pretrained Transformers](https://arxiv.org/abs/2012.15828)论文策略的实现,是一种通用蒸馏方法。本实例以`bert-base-chinese`为教师模型,利用中文数据进行了通用蒸馏。 |
|
||||
| [TinyBERT](./examples/model_compression/tinybert) | 基于论文[TinyBERT: Distilling BERT for Natural Language Understanding](https://arxiv.org/abs/1909.10351)的实现,提供了通用蒸馏和下游任务蒸馏的脚本。本实例利用开源模型`tinybert-6l-768d-v2`初始化,在GLUE的7个数据集上进行下游任务的蒸馏,最终模型参数量缩小1/2,预测速度提升2倍,同时保证模型精度几乎无损,其中精度可达教师模型`bert-base-uncased`的 98.90%。 |
|
||||
| [OFA-BERT](./examples/model_compression/ofa/) :star2: | 基于PaddleSlim Once-For-ALL(OFA)策略对BERT在GLUE任务的下游模型进行压缩,在精度无损的情况下可减少33%参数量,达到模型小型化的提速的效果。 |
|
||||
| [Distill-LSTM](./examples/model_compression/distill_lstm/) | 基于[Distilling Task-Specific Knowledge from BERT into Simple Neural Networks](https://arxiv.org/abs/1903.12136)论文策略的实现,将BERT中英文分类的下游模型知识通过蒸馏的方式迁移至LSTM的小模型结构中,取得比LSTM单独训练更好的效果。 |
|
||||
|
||||
#### 小样本学习 (Few-Shot Learning)
|
||||
|
||||
| 算法 | 简介 |
|
||||
| :--------------- | ------- |
|
||||
| [PET](./examples/few_shot/pet/) | 基于[Exploiting Cloze Questions for Few Shot Text Classification and Natural Language Inference](https://arxiv.org/abs/2001.07676) 论文策略实现, 基于人工知识设计 Prompt, 将下游目标任务转换为完形填空任务来充分挖掘预训练模型中的知识, 显著提升模型效果。|
|
||||
| [P-Tuning](./examples/few_shot/p-tuning/) |基于[GPT Understands, Too](https://arxiv.org/pdf/2103.10385.pdf) 论文策略实现, 首次提出连续可学习的模板参数,在全参数空间对模板进行连续优化,大幅提升模型稳定性和模型效果。|
|
||||
| [EFL](./examples/few_shot/efl/) | 基于[Entailment as Few-Shot Learner](https://arxiv.org/abs/2104.14690) 论文策略实现,将下游目标任务转换为蕴含任务降低模型预测空间,显著提升模型效果。|
|
||||
|
||||
## 交互式Notebook教程
|
||||
|
||||
- [使用Seq2Vec模块进行句子情感分类](https://aistudio.baidu.com/aistudio/projectdetail/1283423)
|
||||
- [如何通过预训练模型Fine-tune下游任务](https://aistudio.baidu.com/aistudio/projectdetail/1294333)
|
||||
- [使用BiGRU-CRF模型完成快递单信息抽取](https://aistudio.baidu.com/aistudio/projectdetail/1317771)
|
||||
- [使用预训练模型ERNIE优化快递单信息抽取](https://aistudio.baidu.com/aistudio/projectdetail/1329361)
|
||||
- [使用Seq2Seq模型完成自动对联](https://aistudio.baidu.com/aistudio/projectdetail/1321118)
|
||||
- [使用预训练模型ERNIE-GEN实现智能写诗](https://aistudio.baidu.com/aistudio/projectdetail/1339888)
|
||||
- [使用TCN网络完成新冠疫情病例数预测](https://aistudio.baidu.com/aistudio/projectdetail/1290873)
|
||||
|
||||
更多教程参见[PaddleNLP on AI Studio](https://aistudio.baidu.com/aistudio/personalcenter/thirdview/574995)。
|
||||
|
||||
## 社区贡献与技术交流
|
||||
|
||||
### 特殊兴趣小组
|
||||
|
||||
- 欢迎您加入PaddleNLP的SIG社区,贡献优秀的模型实现、公开数据集、教程与案例等。
|
||||
|
||||
### QQ
|
||||
|
||||
- 现在就加入PaddleNLP的QQ技术交流群,一起交流NLP技术吧!⬇️
|
||||
|
||||
<div align="center">
|
||||
<img src="./docs/imgs/qq.png" width="200" height="200" />
|
||||
</div>
|
||||
|
||||
## 版本更新
|
||||
|
||||
更多版本更新说明请查看[ChangeLog](./docs/changelog.md)
|
||||
|
||||
## License
|
||||
|
||||
PaddleNLP遵循[Apache-2.0开源协议](./LICENSE)。
|
||||
358
README_cn.md
Normal file
358
README_cn.md
Normal file
@@ -0,0 +1,358 @@
|
||||
**简体中文**🀄 | [English🌎](./README_en.md)
|
||||
|
||||
<p align="center">
|
||||
<img src="https://user-images.githubusercontent.com/1371212/175816733-8ec25eb0-9af3-4380-9218-27c154518258.png" align="middle" width="500" />
|
||||
</p>
|
||||
|
||||
------------------------------------------------------------------------------------------
|
||||
|
||||
<p align="center">
|
||||
<a href="./LICENSE"><img src="https://img.shields.io/badge/license-Apache%202-dfd.svg"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/releases"><img src="https://img.shields.io/github/v/release/PaddlePaddle/PaddleNLP?color=ffa"></a>
|
||||
<a href=""><img src="https://img.shields.io/badge/python-3.6.2+-aff.svg"></a>
|
||||
<a href=""><img src="https://img.shields.io/badge/os-linux%2C%20win%2C%20mac-pink.svg"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/graphs/contributors"><img src="https://img.shields.io/github/contributors/PaddlePaddle/PaddleNLP?color=9ea"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/commits"><img src="https://img.shields.io/github/commit-activity/m/PaddlePaddle/PaddleNLP?color=3af"></a>
|
||||
<a href="https://pypi.org/project/paddlenlp/"><img src="https://img.shields.io/pypi/dm/paddlenlp?color=9cf"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/issues"><img src="https://img.shields.io/github/issues/PaddlePaddle/PaddleNLP?color=9cc"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/stargazers"><img src="https://img.shields.io/github/stars/PaddlePaddle/PaddleNLP?color=ccf"></a>
|
||||
</p>
|
||||
|
||||
|
||||
<h4 align="center">
|
||||
<a href=#特性> 特性 </a> |
|
||||
<a href=#安装> 安装 </a> |
|
||||
<a href=#快速开始> 快速开始 </a> |
|
||||
<a href=#api文档> API文档 </a> |
|
||||
<a href=#社区交流> 社区交流 </a>
|
||||
</h4>
|
||||
|
||||
**PaddleNLP**是一款**简单易用**且**功能强大**的自然语言处理开发库。聚合业界**优质预训练模型**并提供**开箱即用**的开发体验,覆盖NLP多场景的模型库搭配**产业实践范例**可满足开发者**灵活定制**的需求。
|
||||
|
||||
## News 📢
|
||||
* 🔥 **2022.10.27 发布 [PaddleNLP v2.4.2](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.2)**
|
||||
* NLG能力扩充:新增📄[**基于Pegasus的中文文本摘要方案**](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_summarization/pegasus),效果领先;新增❓[**问题生成解决方案**](./examples/question_generation),提供基于业界领先模型UNIMO-Text和大规模多领域问题生成数据集训练的通用问题生成预训练模型。均支持Taskflow一键调用,支持FasterGeneration高性能推理,训练推理部署全流程打通。
|
||||
* 发布 🖼[**PPDiffusers**](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/ppdiffusers):支持跨模态(如图像与语音)训练和推理的扩散模型(Diffusion Model)工具箱,可快速体验、二次开发 **Stable Diffusion**,持续支持更多模型。
|
||||
|
||||
* 🔥 **2022.10.14 发布 [PaddleNLP v2.4.1](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.1)**
|
||||
* 🧾 发布多语言跨模态布局增强文档智能大模型 [**ERNIE-Layout**](./model_zoo/ernie-layout/),刷新11项任务SOTA。同步发布基于ERNIE-Layout的**文档抽取问答模型DocPrompt** 🔖,精准理解文档图片布局与语义信息,轻松应对各类业务场景。
|
||||
|
||||
* 🔥 **2022.9.6 发布 [PaddleNLP v2.4](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.0)**
|
||||
* 💎 NLP工具:**[NLP 流水线系统 Pipelines](./pipelines)** 发布,支持快速搭建搜索引擎、问答系统,可扩展支持各类NLP系统,让解决 NLP 任务像搭积木一样便捷、灵活、高效!
|
||||
* 💢 产业应用:新增 **[文本分类全流程应用方案](./applications/text_classification)** ,覆盖多分类、多标签、层次分类各类场景,支持 **小样本学习** 和 **TrustAI** 可信计算模型训练与调优;[**通用信息抽取 UIE 能力升级**](./model_zoo/uie),发布 **UIE-M**,支持中英文混合抽取,新增**UIE 数据蒸馏**方案,打破 UIE 推理瓶颈,推理速度提升 100 倍以上;
|
||||
* 🍭 AIGC 内容生成:新增代码生成 SOTA 模型[**CodeGen**](./examples/code_generation/codegen),支持多种编程语言代码生成;集成[**文图生成潮流模型**](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/model_zoo/taskflow.md#%E6%96%87%E5%9B%BE%E7%94%9F%E6%88%90) DALL·E Mini、Disco Diffusion、Stable Diffusion,更多趣玩模型等你来玩;新增[**中文文本摘要应用**](./applications/text_summarization),基于大规模语料的中文摘要模型首次发布,可支持 Taskflow 一键调用和定制训练;
|
||||
* 💪 框架升级:[**模型自动压缩 API**](./docs/compression.md) 发布,自动对模型进行裁减和量化,大幅降低模型压缩技术使用门槛;[**小样本 Prompt**](./applications/text_classification/multi_class/few-shot)能力发布,集成 PET、P-Tuning、RGL 等经典算法。
|
||||
|
||||
|
||||
## 社区交流
|
||||
|
||||
- 微信扫描二维码并填写问卷,回复小助手关键词(NLP)之后,即可加入交流群领取福利
|
||||
|
||||
- 与众多社区开发者以及官方团队深度交流。
|
||||
- 10G重磅NLP学习大礼包!
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/200770385-a2c02093-0e1d-4189-b324-8b0251cba316.jpg" width="150" height="150" />
|
||||
</div>
|
||||
## 特性
|
||||
|
||||
#### <a href=#开箱即用的nlp工具集> 📦 开箱即用的NLP工具集 </a>
|
||||
|
||||
#### <a href=#丰富完备的中文模型库> 🤗 丰富完备的中文模型库 </a>
|
||||
|
||||
#### <a href=#产业级端到端系统范例> 🎛️ 产业级端到端系统范例 </a>
|
||||
|
||||
#### <a href=#高性能分布式训练与推理> 🚀 高性能分布式训练与推理 </a>
|
||||
|
||||
|
||||
### 开箱即用的NLP工具集
|
||||
|
||||
Taskflow提供丰富的**📦开箱即用**的产业级NLP预置模型,覆盖自然语言理解与生成两大场景,提供**💪产业级的效果**与**⚡️极致的推理性能**。
|
||||
|
||||
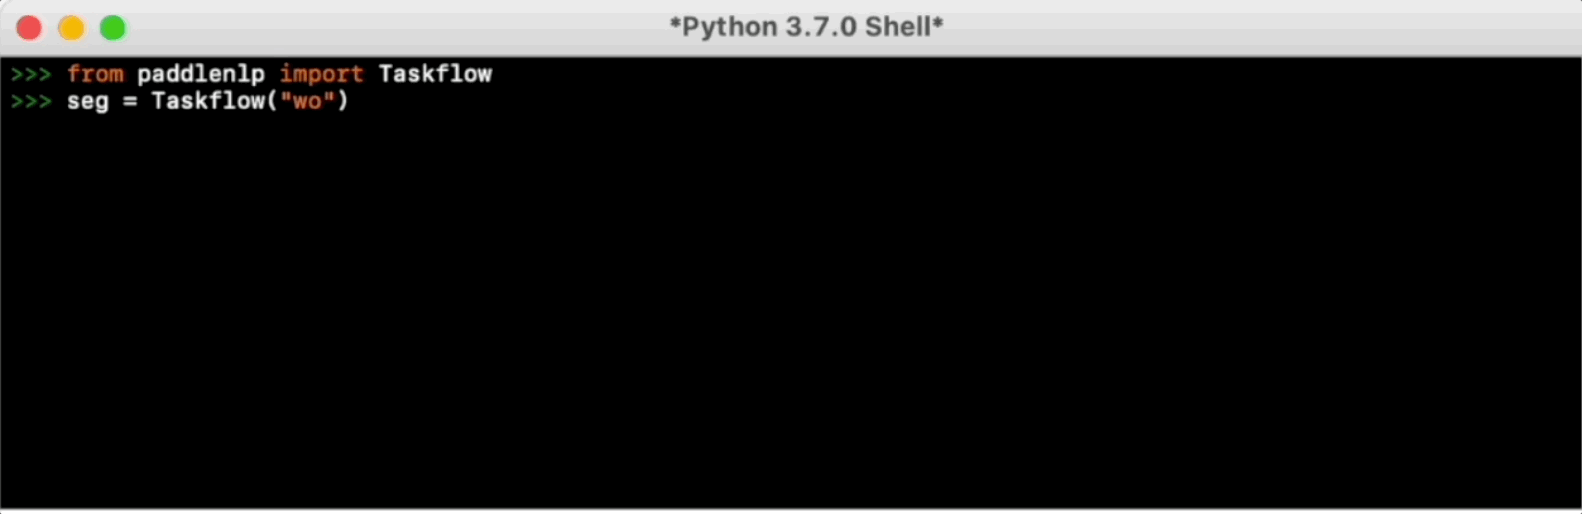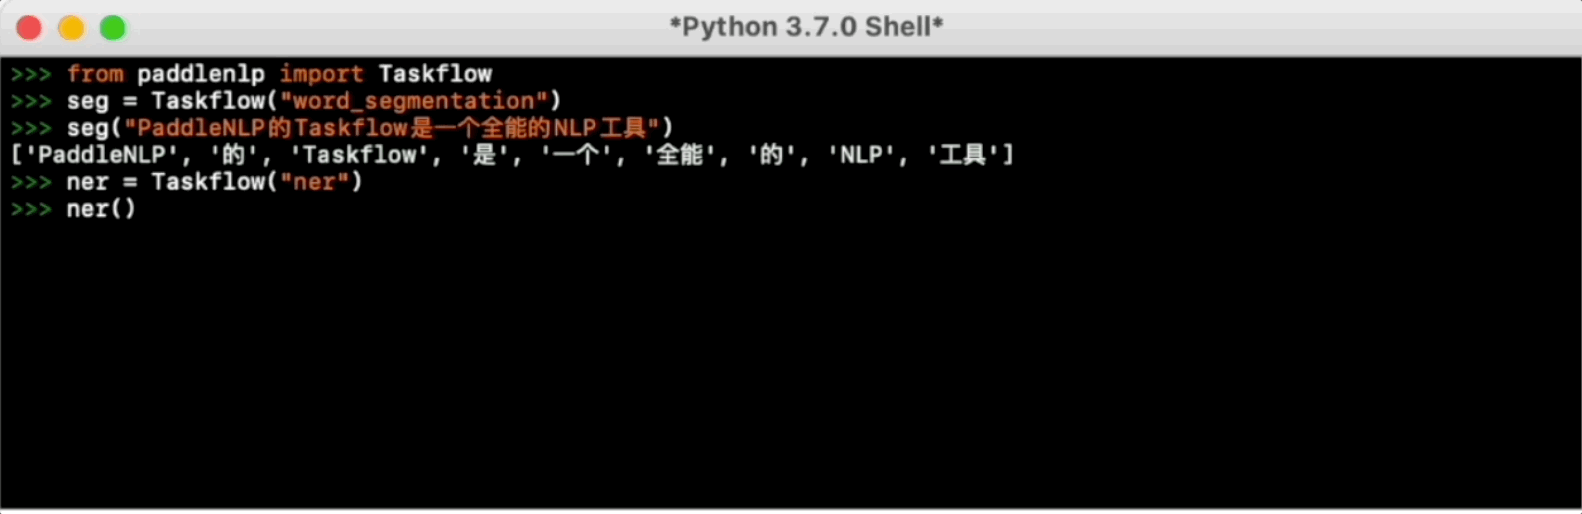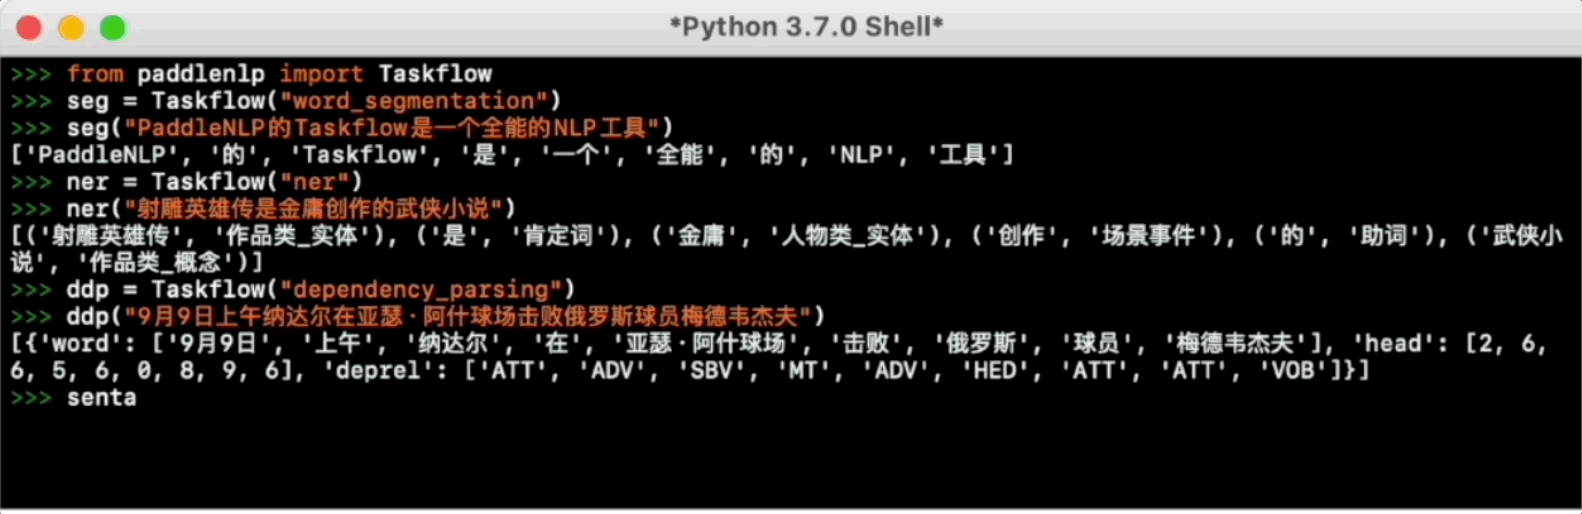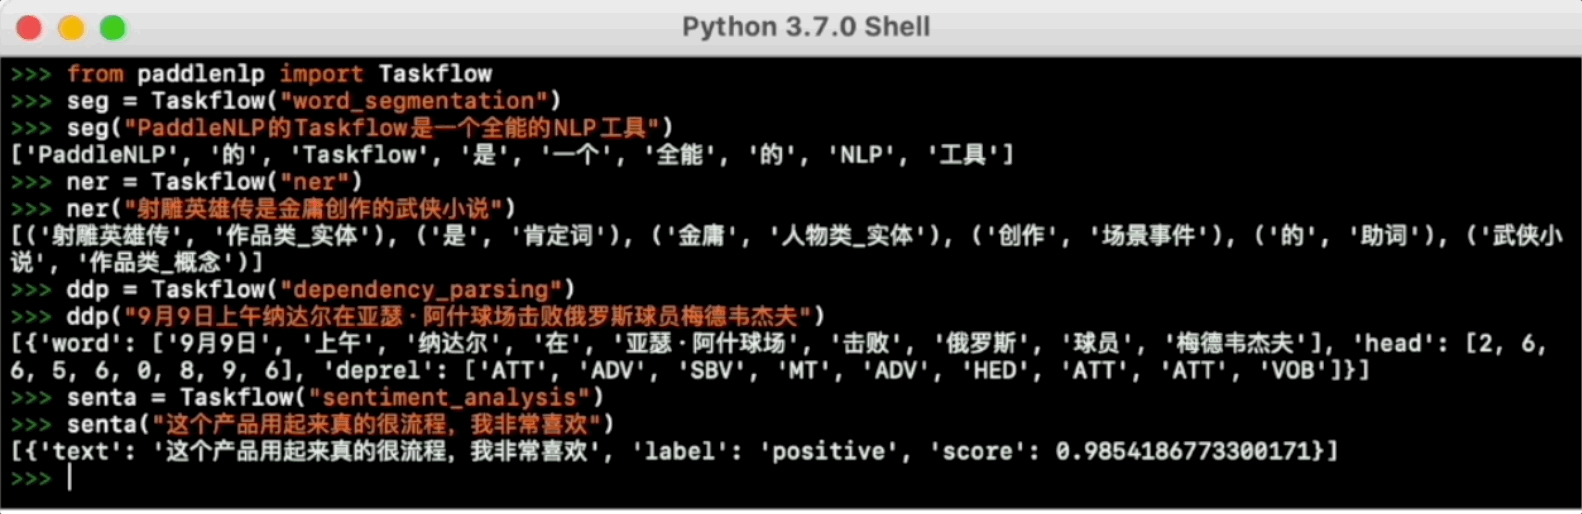
|
||||
|
||||
Taskflow最新集成了文生图的趣玩应用,三行代码体验 **Stable Diffusion**
|
||||
```python
|
||||
from paddlenlp import Taskflow
|
||||
text_to_image = Taskflow("text_to_image", model="CompVis/stable-diffusion-v1-4")
|
||||
image_list = text_to_image('"In the morning light,Chinese ancient buildings in the mountains,Magnificent and fantastic John Howe landscape,lake,clouds,farm,Fairy tale,light effect,Dream,Greg Rutkowski,James Gurney,artstation"')
|
||||
```
|
||||
<img width="300" alt="image" src="https://user-images.githubusercontent.com/16698950/194882669-f7cc7c98-d63a-45f4-99c1-0514c6712368.png">
|
||||
|
||||
更多使用方法可参考[Taskflow文档](./docs/model_zoo/taskflow.md)。
|
||||
|
||||
### 丰富完备的中文模型库
|
||||
|
||||
#### 🀄 业界最全的中文预训练模型
|
||||
|
||||
精选 45+ 个网络结构和 500+ 个预训练模型参数,涵盖业界最全的中文预训练模型:既包括文心NLP大模型的ERNIE、PLATO等,也覆盖BERT、GPT、RoBERTa、T5等主流结构。通过`AutoModel` API一键⚡**高速下载**⚡。
|
||||
|
||||
```python
|
||||
from paddlenlp.transformers import *
|
||||
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-medium-zh')
|
||||
bert = AutoModel.from_pretrained('bert-wwm-chinese')
|
||||
albert = AutoModel.from_pretrained('albert-chinese-tiny')
|
||||
roberta = AutoModel.from_pretrained('roberta-wwm-ext')
|
||||
electra = AutoModel.from_pretrained('chinese-electra-small')
|
||||
gpt = AutoModelForPretraining.from_pretrained('gpt-cpm-large-cn')
|
||||
```
|
||||
|
||||
针对预训练模型计算瓶颈,可以使用API一键使用文心ERNIE-Tiny全系列轻量化模型,降低预训练模型部署难度。
|
||||
|
||||
```python
|
||||
# 6L768H
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-medium-zh')
|
||||
# 6L384H
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-mini-zh')
|
||||
# 4L384H
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-micro-zh')
|
||||
# 4L312H
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-nano-zh')
|
||||
```
|
||||
|
||||
对预训练模型应用范式如语义表示、文本分类、句对匹配、序列标注、问答等,提供统一的API体验。
|
||||
|
||||
```python
|
||||
import paddle
|
||||
from paddlenlp.transformers import *
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('ernie-3.0-medium-zh')
|
||||
text = tokenizer('自然语言处理')
|
||||
|
||||
# 语义表示
|
||||
model = AutoModel.from_pretrained('ernie-3.0-medium-zh')
|
||||
sequence_output, pooled_output = model(input_ids=paddle.to_tensor([text['input_ids']]))
|
||||
# 文本分类 & 句对匹配
|
||||
model = AutoModelForSequenceClassification.from_pretrained('ernie-3.0-medium-zh')
|
||||
# 序列标注
|
||||
model = AutoModelForTokenClassification.from_pretrained('ernie-3.0-medium-zh')
|
||||
# 问答
|
||||
model = AutoModelForQuestionAnswering.from_pretrained('ernie-3.0-medium-zh')
|
||||
```
|
||||
|
||||
#### 💯 全场景覆盖的应用示例
|
||||
|
||||
覆盖从学术到产业的NLP应用示例,涵盖NLP基础技术、NLP系统应用以及拓展应用。全面基于飞桨核心框架2.0全新API体系开发,为开发者提供飞桨文本领域的最佳实践。
|
||||
|
||||
精选预训练模型示例可参考[Model Zoo](./model_zoo),更多场景示例文档可参考[examples目录](./examples)。更有免费算力支持的[AI Studio](https://aistudio.baidu.com)平台的[Notbook交互式教程](https://aistudio.baidu.com/aistudio/personalcenter/thirdview/574995)提供实践。
|
||||
|
||||
<details><summary> PaddleNLP预训练模型适用任务汇总(<b>点击展开详情</b>)</summary><div>
|
||||
|
||||
| Model | Sequence Classification | Token Classification | Question Answering | Text Generation | Multiple Choice |
|
||||
| :----------------- | ----------------------- | -------------------- | ------------------ | --------------- | --------------- |
|
||||
| ALBERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| BART | ✅ | ✅ | ✅ | ✅ | ❌ |
|
||||
| BERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| BlenderBot | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| ChineseBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| ConvBERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| CTRL | ✅ | ❌ | ❌ | ❌ | ❌ |
|
||||
| DistilBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| ELECTRA | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| ERNIE | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| ERNIE-CTM | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| ERNIE-Doc | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| ERNIE-GEN | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| ERNIE-Gram | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| ERNIE-M | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| FNet | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| Funnel-Transformer | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| GPT | ✅ | ✅ | ❌ | ✅ | ❌ |
|
||||
| LayoutLM | ✅ | ✅ | ❌ | ❌ | ❌ |
|
||||
| LayoutLMv2 | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| LayoutXLM | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| LUKE | ❌ | ✅ | ✅ | ❌ | ❌ |
|
||||
| mBART | ✅ | ❌ | ✅ | ❌ | ✅ |
|
||||
| MegatronBERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| MobileBERT | ✅ | ❌ | ✅ | ❌ | ❌ |
|
||||
| MPNet | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| NEZHA | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| PP-MiniLM | ✅ | ❌ | ❌ | ❌ | ❌ |
|
||||
| ProphetNet | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| Reformer | ✅ | ❌ | ✅ | ❌ | ❌ |
|
||||
| RemBERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| RoBERTa | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| RoFormer | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| SKEP | ✅ | ✅ | ❌ | ❌ | ❌ |
|
||||
| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| T5 | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| TinyBERT | ✅ | ❌ | ❌ | ❌ | ❌ |
|
||||
| UnifiedTransformer | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| XLNet | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
|
||||
</div></details>
|
||||
|
||||
可参考[Transformer 文档](/docs/model_zoo/index.rst) 查看目前支持的预训练模型结构、参数和详细用法。
|
||||
|
||||
### 产业级端到端系统范例
|
||||
|
||||
PaddleNLP针对信息抽取、语义检索、智能问答、情感分析等高频NLP场景,提供了端到端系统范例,打通*数据标注*-*模型训练*-*模型调优*-*预测部署*全流程,持续降低NLP技术产业落地门槛。更多详细的系统级产业范例使用说明请参考[Applications](./applications)。
|
||||
|
||||
#### 🔍 语义检索系统
|
||||
|
||||
针对无监督数据、有监督数据等多种数据情况,结合SimCSE、In-batch Negatives、ERNIE-Gram单塔模型等,推出前沿的语义检索方案,包含召回、排序环节,打通训练、调优、高效向量检索引擎建库和查询全流程。
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168514909-8817d79a-72c4-4be1-8080-93d1f682bb46.gif" width="400">
|
||||
</div>
|
||||
|
||||
|
||||
更多使用说明请参考[语义检索系统](./applications/neural_search)。
|
||||
|
||||
#### ❓ 智能问答系统
|
||||
|
||||
基于[🚀RocketQA](https://github.com/PaddlePaddle/RocketQA)技术的检索式问答系统,支持FAQ问答、说明书问答等多种业务场景。
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168514868-1babe981-c675-4f89-9168-dd0a3eede315.gif" width="400">
|
||||
</div>
|
||||
|
||||
|
||||
更多使用说明请参考[智能问答系统](./applications/question_answering)与[文档智能问答](./applications/document_intelligence/doc_vqa)
|
||||
|
||||
#### 💌 评论观点抽取与情感分析
|
||||
|
||||
基于情感知识增强预训练模型SKEP,针对产品评论进行评价维度和观点抽取,以及细粒度的情感分析。
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168407260-b7f92800-861c-4207-98f3-2291e0102bbe.png" width="400">
|
||||
</div>
|
||||
|
||||
更多使用说明请参考[情感分析](./applications/sentiment_analysis)。
|
||||
|
||||
#### 🎙️ 智能语音指令解析
|
||||
|
||||
集成了[PaddleSpeech](https://github.com/PaddlePaddle/PaddleSpeech)和[百度开放平台](https://ai.baidu.com/)的的语音识别和[UIE](./model_zoo/uie)通用信息抽取等技术,打造智能一体化的语音指令解析系统范例,该方案可应用于智能语音填单、智能语音交互、智能语音检索等场景,提高人机交互效率。
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/16698950/168589100-a6c6f346-97bb-47b2-ac26-8d50e71fddc5.png" width="400">
|
||||
</div>
|
||||
|
||||
更多使用说明请参考[智能语音指令解析](./applications/speech_cmd_analysis)。
|
||||
|
||||
### 高性能分布式训练与推理
|
||||
|
||||
#### ⚡ FasterTokenizer:高性能文本处理库
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168407921-b4395b1d-44bd-41a0-8c58-923ba2b703ef.png" width="400">
|
||||
</div>
|
||||
|
||||
```python
|
||||
AutoTokenizer.from_pretrained("ernie-3.0-medium-zh", use_faster=True)
|
||||
```
|
||||
|
||||
为了实现更极致的模型部署性能,安装FastTokenizers后只需在`AutoTokenizer` API上打开 `use_faster=True`选项,即可调用C++实现的高性能分词算子,轻松获得超Python百余倍的文本处理加速,更多使用说明可参考[FasterTokenizer文档](./faster_tokenizer)。
|
||||
|
||||
#### ⚡️ FasterGeneration:高性能生成加速库
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168407831-914dced0-3a5a-40b8-8a65-ec82bf13e53c.gif" width="400">
|
||||
</div>
|
||||
|
||||
```python
|
||||
model = GPTLMHeadModel.from_pretrained('gpt-cpm-large-cn')
|
||||
...
|
||||
outputs, _ = model.generate(
|
||||
input_ids=inputs_ids, max_length=10, decode_strategy='greedy_search',
|
||||
use_faster=True)
|
||||
```
|
||||
|
||||
简单地在`generate()`API上打开`use_faster=True`选项,轻松在Transformer、GPT、BART、PLATO、UniLM等生成式预训练模型上获得5倍以上GPU加速,更多使用说明可参考[FasterGeneration文档](./faster_generation)。
|
||||
|
||||
#### 🚀 Fleet:飞桨4D混合并行分布式训练技术
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168515134-513f13e0-9902-40ef-98fa-528271dcccda.png" width="300">
|
||||
</div>
|
||||
|
||||
|
||||
更多关于千亿级AI模型的分布式训练使用说明可参考[GPT-3](./examples/language_model/gpt-3)。
|
||||
|
||||
## 安装
|
||||
|
||||
### 环境依赖
|
||||
|
||||
- python >= 3.6
|
||||
- paddlepaddle >= 2.2
|
||||
|
||||
### pip安装
|
||||
|
||||
```shell
|
||||
pip install --upgrade paddlenlp
|
||||
```
|
||||
|
||||
更多关于PaddlePaddle和PaddleNLP安装的详细教程请查看[Installation](./docs/get_started/installation.rst)。
|
||||
|
||||
## 快速开始
|
||||
|
||||
这里以信息抽取-命名实体识别任务,UIE模型为例,来说明如何快速使用PaddleNLP:
|
||||
|
||||
### 一键预测
|
||||
|
||||
PaddleNLP提供[一键预测功能](./docs/model_zoo/taskflow.md),无需训练,直接输入数据即可开放域抽取结果:
|
||||
|
||||
```python
|
||||
>>> from pprint import pprint
|
||||
>>> from paddlenlp import Taskflow
|
||||
|
||||
>>> schema = ['时间', '选手', '赛事名称'] # Define the schema for entity extraction
|
||||
>>> ie = Taskflow('information_extraction', schema=schema)
|
||||
>>> pprint(ie("2月8日上午北京冬奥会自由式滑雪女子大跳台决赛中中国选手谷爱凌以188.25分获得金牌!"))
|
||||
[{'时间': [{'end': 6,
|
||||
'probability': 0.9857378532924486,
|
||||
'start': 0,
|
||||
'text': '2月8日上午'}],
|
||||
'赛事名称': [{'end': 23,
|
||||
'probability': 0.8503089953268272,
|
||||
'start': 6,
|
||||
'text': '北京冬奥会自由式滑雪女子大跳台决赛'}],
|
||||
'选手': [{'end': 31,
|
||||
'probability': 0.8981548639781138,
|
||||
'start': 28,
|
||||
'text': '谷爱凌'}]}]
|
||||
```
|
||||
|
||||
### 小样本学习
|
||||
|
||||
如果对一键预测效果不满意,也可以使用少量数据进行模型精调,进一步提升特定场景的效果,详见[UIE小样本定制训练](./model_zoo/uie/)。
|
||||
|
||||
更多PaddleNLP内容可参考:
|
||||
- [精选模型库](./model_zoo),包含优质预训练模型的端到端全流程使用。
|
||||
- [多场景示例](./examples),了解如何使用PaddleNLP解决NLP多种技术问题,包含基础技术、系统应用与拓展应用。
|
||||
- [交互式教程](https://aistudio.baidu.com/aistudio/personalcenter/thirdview/574995),在🆓免费算力平台AI Studio上快速学习PaddleNLP。
|
||||
|
||||
|
||||
## API文档
|
||||
|
||||
PaddleNLP提供全流程的文本领域API,可大幅提升NLP任务建模的效率:
|
||||
|
||||
- 支持[千言](https://www.luge.ai)等丰富中文数据集加载的[Dataset API](https://paddlenlp.readthedocs.io/zh/latest/data_prepare/dataset_list.html)。
|
||||
- 提供🤗Hugging Face Style的API,支持 **500+** 优质预训练模型加载的[Transformers API](https://paddlenlp.readthedocs.io/zh/latest/model_zoo/index.html)。
|
||||
- 提供30+多语言词向量的[Embedding API](https://paddlenlp.readthedocs.io/zh/latest/model_zoo/embeddings.html)
|
||||
|
||||
更多使用方法请参考[API文档](https://paddlenlp.readthedocs.io/zh/latest/)。
|
||||
|
||||
|
||||
## Citation
|
||||
|
||||
如果PaddleNLP对您的研究有帮助,欢迎引用
|
||||
|
||||
```
|
||||
@misc{=paddlenlp,
|
||||
title={PaddleNLP: An Easy-to-use and High Performance NLP Library},
|
||||
author={PaddleNLP Contributors},
|
||||
howpublished = {\url{https://github.com/PaddlePaddle/PaddleNLP}},
|
||||
year={2021}
|
||||
}
|
||||
```
|
||||
|
||||
## Acknowledge
|
||||
|
||||
我们借鉴了Hugging Face的[Transformers](https://github.com/huggingface/transformers)🤗关于预训练模型使用的优秀设计,在此对Hugging Face作者及其开源社区表示感谢。
|
||||
|
||||
## License
|
||||
|
||||
PaddleNLP遵循[Apache-2.0开源协议](./LICENSE)。
|
||||
434
README_en.md
434
README_en.md
@@ -1,41 +1,270 @@
|
||||
English | [简体中文](./README.md)
|
||||
[简体中文🀄](./README_cn.md) | **English**🌎
|
||||
|
||||
<p align="center">
|
||||
<img src="./docs/imgs/paddlenlp.png" width="718" height ="100" />
|
||||
<img src="https://user-images.githubusercontent.com/1371212/175816733-8ec25eb0-9af3-4380-9218-27c154518258.png" align="middle" width="500" />
|
||||
</p>
|
||||
|
||||
------------------------------------------------------------------------------------------
|
||||
[](https://pypi.org/project/paddlenlp/)
|
||||
[](https://pypi.org/project/paddlenlp/)
|
||||
[](https://pepy.tech/project/paddlenlp)
|
||||

|
||||

|
||||

|
||||
|
||||
## News <img src="./docs/imgs/news_icon.png" width="40"/>
|
||||
<p align="center">
|
||||
<a href="./LICENSE"><img src="https://img.shields.io/badge/license-Apache%202-dfd.svg"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/releases"><img src="https://img.shields.io/github/v/release/PaddlePaddle/PaddleNLP?color=ffa"></a>
|
||||
<a href=""><img src="https://img.shields.io/badge/python-3.6.2+-aff.svg"></a>
|
||||
<a href=""><img src="https://img.shields.io/badge/os-linux%2C%20win%2C%20mac-pink.svg"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/graphs/contributors"><img src="https://img.shields.io/github/contributors/PaddlePaddle/PaddleNLP?color=9ea"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/commits"><img src="https://img.shields.io/github/commit-activity/m/PaddlePaddle/PaddleNLP?color=3af"></a>
|
||||
<a href="https://pypi.org/project/paddlenlp/"><img src="https://img.shields.io/pypi/dm/paddlenlp?color=9cf"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/issues"><img src="https://img.shields.io/github/issues/PaddlePaddle/PaddleNLP?color=9cc"></a>
|
||||
<a href="https://github.com/PaddlePaddle/PaddleNLP/stargazers"><img src="https://img.shields.io/github/stars/PaddlePaddle/PaddleNLP?color=ccf"></a>
|
||||
</p>
|
||||
|
||||
* [2021-10-12] PaddleNLP 2.1 has been officially relealsed! :tada: For more information please refer to [Release Note](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.1.0).
|
||||
<h4 align="center">
|
||||
<a href=#features> Features </a> |
|
||||
<a href=#installation> Installation </a> |
|
||||
<a href=#quick-start> Quick Start </a> |
|
||||
<a href=#api-reference> API Reference </a> |
|
||||
<a href=#community> Community </a>
|
||||
</h4>
|
||||
|
||||
## Introduction
|
||||
**PaddleNLP** is an *easy-to-use* and *powerful* NLP library with **Awesome** pre-trained model zoo, supporting wide-range of NLP tasks from research to industrial applications.
|
||||
|
||||
**PaddleNLP** is a powerful NLP library with **Awesome** pre-trained Transformer models and easy-to-use interface, supporting wide-range of NLP tasks from research to industrial applications.
|
||||
## News 📢
|
||||
|
||||
* 🔥 **2022.10.27 [PaddleNLP v2.4.2](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.2) Released!**
|
||||
* NLG Upgrade: 📄 Release [**Solution of Text Summarization**](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_summarization/pegasus) based on Pegasus;❓ Release [**Solution of Problem Generation**](./examples/question_generation), providing **general problem generation pre-trained model** based on Baidu's UNIMO Text and large-scale multi domain problem generation dataset。Supporting high-performance inference ability based on FasterGeneration , and covering the whole process of training , inference and deployment.
|
||||
* 🔥 **2022.10.14 [PaddleNLP v2.4.1](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.1) Released!**
|
||||
* 🧾 Release multilingual/cross-lingual pre-trained models [**ERNIE-Layout**](./model_zoo/ernie-layout/) which achieves new SOTA results in 11 downstream tasks. **DocPrompt** 🔖 based on ERNIE-Layout is also released which has the ability for multilingual document information extraction and question ansering.
|
||||
* 🔥 **2022.9.6 [PaddleNLPv2.4](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.0) Released!**
|
||||
|
||||
* 💎 NLP Tool:**[Pipelines](./pipelines)** released. Supports for fast construction of search engine and question answering systems, and it is expandable to all kinds of NLP systems. Building end-to-end pipelines for NLP tasks like playing Lego!
|
||||
|
||||
* 💢 Industrial application:Release **[Complete Solution of Text Classification](./applications/text_classification)** covering various scenarios of text classification: multi-class, multi-label and hierarchical, it also supports for **few-shot learning** and the training and optimization of **TrustAI**. Upgrade for [**Universal Information Extraction**](./model_zoo/uie) and release **UIE-M**, support both Chinese and English information extraction in a single model; release the data distillation solution for UIE to break the bottleneck of time-consuming of inference.
|
||||
|
||||
* 🍭 AIGC: Release code generation SOTA model [**CodeGen**](./examples/code_generation/codegen), supports for multiple programming languages code generation. Integrate [**Text to Image Model**](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/model_zoo/taskflow.md#%E6%96%87%E5%9B%BE%E7%94%9F%E6%88%90) DALL·E Mini, Disco Diffusion, Stable Diffusion, let's play and have some fun! Release [**Chinese Text Summarization Application**](./applications/text_summarization), first release of chinese text summarization model pretrained on a large scale of corpus, it can be use via Taskflow API and support for finetuning on your own data.
|
||||
|
||||
* 💪 Framework upgrade: Release [**Auto Model Compression API**](./docs/compression.md), supports for pruning and quantization automatically, lower the barriers of model compression; Release [**Few-shot Prompt**](./applications/text_classification/multi_class/few-shot), includes the algorithms such as PET, P-Tuning and RGL.
|
||||
|
||||
|
||||
* **Easy-to-Use API**
|
||||
- The API is fully integrated with PaddlePaddle 2.0 high-level API system. It minimizes the number of user actions required for common use cases like data loading, text pre-processing, awesome transfomer models, and fast inference, which enables developer to deal with text problems more productively.
|
||||
|
||||
* **Wide-range NLP Task Support**
|
||||
- PaddleNLP support NLP task from research to industrial applications, including Lexical Analysis, Text Classification, Text Matching, Text Generation, Information Extraction, Machine Translation, General Dialogue and Question Answering etc.
|
||||
|
||||
* **High Performance Distributed Training**
|
||||
- We provide an industrial level training pipeline for super large-scale Transformer model based on **Auto Mixed Precision** and Fleet distributed training API by PaddlePaddle, which can support customized model pre-training efficiently.
|
||||
## Features
|
||||
|
||||
#### <a href=#out-of-box-nlp-toolset> 📦 Out-of-Box NLP Toolset </a>
|
||||
|
||||
#### <a href=#awesome-chinese-model-zoo> 🤗 Awesome Chinese Model Zoo </a>
|
||||
|
||||
#### <a href=#industrial-end-to-end-system> 🎛️ Industrial End-to-end System </a>
|
||||
|
||||
#### <a href=#high-performance-distributed-training-and-inference> 🚀 High Performance Distributed Training and Inference </a>
|
||||
|
||||
|
||||
### Out-of-Box NLP Toolset
|
||||
|
||||
Taskflow aims to provide off-the-shelf NLP pre-built task covering NLU and NLG technique, in the meanwhile with extreamly fast infernece satisfying industrial scenario.
|
||||
|
||||

|
||||
|
||||
For more usage please refer to [Taskflow Docs](./docs/model_zoo/taskflow.md).
|
||||
|
||||
### Awesome Chinese Model Zoo
|
||||
|
||||
#### 🀄 Comprehensive Chinese Transformer Models
|
||||
|
||||
We provide **45+** network architectures and over **500+** pretrained models. Not only includes all the SOTA model like ERNIE, PLATO and SKEP released by Baidu, but also integrates most of the high-quality Chinese pretrained model developed by other organizations. Use `AutoModel` API to **⚡SUPER FAST⚡** download pretrained models of different architecture. We welcome all developers to contribute your Transformer models to PaddleNLP!
|
||||
|
||||
```python
|
||||
from paddlenlp.transformers import *
|
||||
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-medium-zh')
|
||||
bert = AutoModel.from_pretrained('bert-wwm-chinese')
|
||||
albert = AutoModel.from_pretrained('albert-chinese-tiny')
|
||||
roberta = AutoModel.from_pretrained('roberta-wwm-ext')
|
||||
electra = AutoModel.from_pretrained('chinese-electra-small')
|
||||
gpt = AutoModelForPretraining.from_pretrained('gpt-cpm-large-cn')
|
||||
```
|
||||
|
||||
Due to the computation limitation, you can use the ERNIE-Tiny light models to accelerate the deployment of pretrained models.
|
||||
```python
|
||||
# 6L768H
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-medium-zh')
|
||||
# 6L384H
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-mini-zh')
|
||||
# 4L384H
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-micro-zh')
|
||||
# 4L312H
|
||||
ernie = AutoModel.from_pretrained('ernie-3.0-nano-zh')
|
||||
```
|
||||
Unified API experience for NLP task like semantic representation, text classification, sentence matching, sequence labeling, question answering, etc.
|
||||
|
||||
```python
|
||||
import paddle
|
||||
from paddlenlp.transformers import *
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('ernie-3.0-medium-zh')
|
||||
text = tokenizer('natural language processing')
|
||||
|
||||
# Semantic Representation
|
||||
model = AutoModel.from_pretrained('ernie-3.0-medium-zh')
|
||||
sequence_output, pooled_output = model(input_ids=paddle.to_tensor([text['input_ids']]))
|
||||
# Text Classificaiton and Matching
|
||||
model = AutoModelForSequenceClassification.from_pretrained('ernie-3.0-medium-zh')
|
||||
# Sequence Labeling
|
||||
model = AutoModelForTokenClassification.from_pretrained('ernie-3.0-medium-zh')
|
||||
# Question Answering
|
||||
model = AutoModelForQuestionAnswering.from_pretrained('ernie-3.0-medium-zh')
|
||||
```
|
||||
|
||||
#### Wide-range NLP Task Support
|
||||
|
||||
PaddleNLP provides rich examples covering mainstream NLP task to help developers accelerate problem solving. You can find our powerful transformer [Model Zoo](./model_zoo), and wide-range NLP application [exmaples](./examples) with detailed instructions.
|
||||
|
||||
Also you can run our interactive [Notebook tutorial](https://aistudio.baidu.com/aistudio/personalcenter/thirdview/574995) on AI Studio, a powerful platform with **FREE** computing resource.
|
||||
|
||||
<details><summary> PaddleNLP Transformer model summary (<b>click to show details</b>) </summary><div>
|
||||
|
||||
| Model | Sequence Classification | Token Classification | Question Answering | Text Generation | Multiple Choice |
|
||||
| :----------------- | ----------------------- | -------------------- | ------------------ | --------------- | --------------- |
|
||||
| ALBERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| BART | ✅ | ✅ | ✅ | ✅ | ❌ |
|
||||
| BERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| BlenderBot | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| ChineseBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| ConvBERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| CTRL | ✅ | ❌ | ❌ | ❌ | ❌ |
|
||||
| DistilBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| ELECTRA | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| ERNIE | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| ERNIE-CTM | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| ERNIE-Doc | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| ERNIE-GEN | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| ERNIE-Gram | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| ERNIE-M | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| FNet | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| Funnel-Transformer | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| GPT | ✅ | ✅ | ❌ | ✅ | ❌ |
|
||||
| LayoutLM | ✅ | ✅ | ❌ | ❌ | ❌ |
|
||||
| LayoutLMv2 | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| LayoutXLM | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| LUKE | ❌ | ✅ | ✅ | ❌ | ❌ |
|
||||
| mBART | ✅ | ❌ | ✅ | ❌ | ✅ |
|
||||
| MegatronBERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| MobileBERT | ✅ | ❌ | ✅ | ❌ | ❌ |
|
||||
| MPNet | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| NEZHA | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| PP-MiniLM | ✅ | ❌ | ❌ | ❌ | ❌ |
|
||||
| ProphetNet | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| Reformer | ✅ | ❌ | ✅ | ❌ | ❌ |
|
||||
| RemBERT | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| RoBERTa | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
| RoFormer | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| SKEP | ✅ | ✅ | ❌ | ❌ | ❌ |
|
||||
| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
|
||||
| T5 | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| TinyBERT | ✅ | ❌ | ❌ | ❌ | ❌ |
|
||||
| UnifiedTransformer | ❌ | ❌ | ❌ | ✅ | ❌ |
|
||||
| XLNet | ✅ | ✅ | ✅ | ❌ | ✅ |
|
||||
|
||||
</div></details>
|
||||
|
||||
For more pretrained model usage, please refer to [Transformer API Docs](./docs/model_zoo/index.rst).
|
||||
|
||||
### Industrial End-to-end System
|
||||
|
||||
We provide high value scenarios including information extraction, semantic retrieval, questionn answering high-value.
|
||||
|
||||
For more details industial cases please refer to [Applications](./applications).
|
||||
|
||||
|
||||
#### 🔍 Neural Search System
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168514909-8817d79a-72c4-4be1-8080-93d1f682bb46.gif" width="400">
|
||||
</div>
|
||||
|
||||
|
||||
For more details please refer to [Neural Search](./applications/neural_search).
|
||||
|
||||
#### ❓ Question Answering System
|
||||
|
||||
We provide question answering pipeline which can support FAQ system, Document-level Visual Question answering system based on [🚀RocketQA](https://github.com/PaddlePaddle/RocketQA).
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168514868-1babe981-c675-4f89-9168-dd0a3eede315.gif" width="400">
|
||||
</div>
|
||||
|
||||
|
||||
For more details please refer to [Question Answering](./applications/question_answering) and [Document VQA](./applications/document_intelligence/doc_vqa).
|
||||
|
||||
|
||||
#### 💌 Opinion Extraction and Sentiment Analysis
|
||||
|
||||
We build an opinion extraction system for product review and fine-grained sentiment analysis based on [SKEP](https://arxiv.org/abs/2005.05635) Model.
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168407260-b7f92800-861c-4207-98f3-2291e0102bbe.png" width="300">
|
||||
</div>
|
||||
|
||||
|
||||
For more details please refer to [Sentiment Analysis](./applications/sentiment_analysis).
|
||||
|
||||
#### 🎙️ Speech Command Analysis
|
||||
|
||||
Integrated ASR Model, Information Extraction, we provide a speech command analysis pipeline that show how to use PaddleNLP and [PaddleSpeech](https://github.com/PaddlePaddle/PaddleSpeech) to solve Speech + NLP real scenarios.
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168412618-04897a47-79c9-4fe7-a054-5dc1f6a1f75c.png" width="500">
|
||||
</div>
|
||||
|
||||
|
||||
For more details please refer to [Speech Command Analysis](./applications/speech_cmd_analysis).
|
||||
|
||||
### High Performance Distributed Training and Inference
|
||||
|
||||
#### ⚡ FasterTokenizer: High Performance Text Preprocessing Library
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168407921-b4395b1d-44bd-41a0-8c58-923ba2b703ef.png" width="400">
|
||||
</div>
|
||||
|
||||
```python
|
||||
AutoTokenizer.from_pretrained("ernie-3.0-medium-zh", use_faster=True)
|
||||
```
|
||||
|
||||
Set `use_faster=True` to use C++ Tokenizer kernel to achieve 100x faster on text pre-processing. For more usage please refer to [FasterTokenizer](./faster_tokenizer).
|
||||
|
||||
#### ⚡ FasterGeneration: High Perforance Generation Library
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168407831-914dced0-3a5a-40b8-8a65-ec82bf13e53c.gif" width="400">
|
||||
</div>
|
||||
|
||||
```python
|
||||
model = GPTLMHeadModel.from_pretrained('gpt-cpm-large-cn')
|
||||
...
|
||||
outputs, _ = model.generate(
|
||||
input_ids=inputs_ids, max_length=10, decode_strategy='greedy_search',
|
||||
use_faster=True)
|
||||
```
|
||||
|
||||
Set `use_faster=True` to achieve 5x speedup for Transformer, GPT, BART, PLATO, UniLM text generation. For more usage please refer to [FasterGeneration](./faster_generation).
|
||||
|
||||
#### 🚀 Fleet: 4D Hybrid Distributed Training
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/168515134-513f13e0-9902-40ef-98fa-528271dcccda.png" width="300">
|
||||
</div>
|
||||
|
||||
|
||||
For more super large-scale model pre-training details please refer to [GPT-3](./examples/language_model/gpt-3).
|
||||
|
||||
|
||||
## Installation
|
||||
|
||||
### Prerequisites
|
||||
|
||||
* python >= 3.6
|
||||
* paddlepaddle >= 2.1
|
||||
* paddlepaddle >= 2.2
|
||||
|
||||
More information about PaddlePaddle installation please refer to [PaddlePaddle's Website](https://www.paddlepaddle.org.cn/install/quick?docurl=/documentation/docs/zh/install/conda/linux-conda.html).
|
||||
|
||||
@@ -45,11 +274,9 @@ More information about PaddlePaddle installation please refer to [PaddlePaddle's
|
||||
pip install --upgrade paddlenlp
|
||||
```
|
||||
|
||||
## Easy-to-use API
|
||||
## Quick Start
|
||||
|
||||
### Taskflow:Off-the-shelf Industial NLP Pre-built Task
|
||||
|
||||
Taskflow aims to provide **off-the-shelf** NLP pre-built task covering NLU and NLG scenario, in the meanwhile with extreamly fast infernece satisfying industrial applications.
|
||||
**Taskflow** aims to provide off-the-shelf NLP pre-built task covering NLU and NLG scenario, in the meanwhile with extreamly fast infernece satisfying industrial applications.
|
||||
|
||||
```python
|
||||
from paddlenlp import Taskflow
|
||||
@@ -71,155 +298,54 @@ ner("《孤女》是2010年九州出版社出版的小说,作者是余兼羽")
|
||||
|
||||
# Dependency Parsing
|
||||
ddp = Taskflow("dependency_parsing")
|
||||
ddp("百度是一家高科技公司")
|
||||
>>> [{'word': ['百度', '是', '一家', '高科技', '公司'], 'head': ['2', '0', '5', '5', '2'], 'deprel': ['SBV', 'HED', 'ATT', 'ATT', 'VOB']}]
|
||||
ddp("9月9日上午纳达尔在亚瑟·阿什球场击败俄罗斯球员梅德韦杰夫")
|
||||
>>> [{'word': ['9月9日', '上午', '纳达尔', '在', '亚瑟·阿什球场', '击败', '俄罗斯', '球员', '梅德韦杰夫'], 'head': [2, 6, 6, 5, 6, 0, 8, 9, 6], 'deprel': ['ATT', 'ADV', 'SBV', 'MT', 'ADV', 'HED', 'ATT', 'ATT', 'VOB']}]
|
||||
|
||||
# Sentiment Analysis
|
||||
senta = Taskflow("sentiment_analysis")
|
||||
senta("怀着十分激动的心情放映,可是看着看着发现,在放映完毕后,出现一集米老鼠的动画片")
|
||||
>>> [{'text': '怀着十分激动的心情放映,可是看着看着发现,在放映完毕后,出现一集米老鼠的动画片', 'label': 'negative', 'score': 0.6691398620605469}]
|
||||
senta("这个产品用起来真的很流畅,我非常喜欢")
|
||||
>>> [{'text': '这个产品用起来真的很流畅,我非常喜欢', 'label': 'positive', 'score': 0.9938690066337585}]
|
||||
```
|
||||
|
||||
For more usage please refer to [Taskflow Docs](./docs/model_zoo/taskflow.md)
|
||||
## API Reference
|
||||
|
||||
### Transformer API: Awesome Pre-trained Model Ecosystem
|
||||
- Support [LUGE](https://www.luge.ai/) dataset loading and compatible with Hugging Face [Datasets](https://huggingface.co/datasets). For more details please refer to [Dataset API](https://paddlenlp.readthedocs.io/zh/latest/data_prepare/dataset_list.html).
|
||||
- Using Hugging Face style API to load 500+ selected transformer models and download with fast speed. For more information please refer to [Transformers API](https://paddlenlp.readthedocs.io/zh/latest/model_zoo/index.html).
|
||||
- One-line of code to load pre-trained word embedding. For more usage please refer to [Embedding API](https://paddlenlp.readthedocs.io/zh/latest/model_zoo/embeddings.html).
|
||||
|
||||
We provide **22** network architectures and over **90** pretrained models. Not only includes all the SOTA model like ERNIE, PLATO and SKEP released by Baidu, but also integrates most of the high quality Chinese pretrained model developed by other organizations. We welcome all developers to contribute your Transformer models to PaddleNLP! 🤗
|
||||
|
||||
```python
|
||||
from paddlenlp.transformers import *
|
||||
|
||||
ernie = ErnieModel.from_pretrained('ernie-1.0')
|
||||
ernie_gram = ErnieGramModel.from_pretrained('ernie-gram-zh')
|
||||
bert = BertModel.from_pretrained('bert-wwm-chinese')
|
||||
albert = AlbertModel.from_pretrained('albert-chinese-tiny')
|
||||
roberta = RobertaModel.from_pretrained('roberta-wwm-ext')
|
||||
electra = ElectraModel.from_pretrained('chinese-electra-small')
|
||||
gpt = GPTForPretraining.from_pretrained('gpt-cpm-large-cn')
|
||||
```
|
||||
|
||||
PaddleNLP also provides unified API experience for NLP task like semantic representation, text classification, sentence matching, sequence labeling, question answering, etc.
|
||||
|
||||
```python
|
||||
import paddle
|
||||
from paddlenlp.transformers import ErnieTokenizer, ErnieModel
|
||||
|
||||
tokenizer = ErnieTokenizer.from_pretrained('ernie-1.0')
|
||||
text = tokenizer('natural language understanding')
|
||||
|
||||
# Semantic Representation
|
||||
model = ErnieModel.from_pretrained('ernie-1.0')
|
||||
sequence_output, pooled_output = model(input_ids=paddle.to_tensor([text['input_ids']]))
|
||||
# Text Classificaiton and Matching
|
||||
model = ErnieForSequenceClassification.from_pretrained('ernie-1.0')
|
||||
# Sequence Labeling
|
||||
model = ErnieForTokenClassification.from_pretrained('ernie-1.0')
|
||||
# Question Answering
|
||||
model = ErnieForQuestionAnswering.from_pretrained('ernie-1.0')
|
||||
```
|
||||
|
||||
For more pretrained model usage, please refer to [Transformer API](./docs/model_zoo/transformers.rst)
|
||||
|
||||
### Dataset API: Abundant Dataset Integration and Quick Loading
|
||||
|
||||
```python
|
||||
from paddlenlp.datasets import load_dataset
|
||||
|
||||
train_ds, dev_ds, test_ds = load_dataset("chnsenticorp", splits=["train", "dev", "test"])
|
||||
```
|
||||
|
||||
For more dataset API usage please refer to [Dataset API](./docs/datasets.md).
|
||||
|
||||
### Embedding API: Quick Loading for Word Embedding
|
||||
|
||||
```python
|
||||
from paddlenlp.embeddings import TokenEmbedding
|
||||
|
||||
wordemb = TokenEmbedding("fasttext.wiki-news.target.word-word.dim300.en")
|
||||
wordemb.cosine_sim("king", "queen")
|
||||
>>> 0.77053076
|
||||
wordemb.cosine_sim("apple", "rail")
|
||||
>>> 0.29207364
|
||||
```
|
||||
|
||||
For more `TokenEmbedding` usage, please refer to [Embedding API](./docs/model_zoo/embeddings.md)
|
||||
|
||||
### More API Usage
|
||||
|
||||
- [Transformer API](./docs/model_zoo/transformers.rst)
|
||||
- [Data API](./docs/data.md)
|
||||
- [Dataset API](./docs/datasets.md)
|
||||
- [Embedding API](./docs/model_zoo/embeddings.md)
|
||||
- [Metrics API](./docs/metrics.md)
|
||||
|
||||
Please find more API Reference from our [readthedocs](https://paddlenlp.readthedocs.io/).
|
||||
|
||||
## Wide-range NLP Task Support
|
||||
|
||||
PaddleNLP provides rich application examples covering mainstream NLP task to help developers accelerate problem solving.
|
||||
|
||||
### NLP Basic Technique
|
||||
|
||||
- [Word Embedding](./examples/word_embedding/)
|
||||
- [Lexical Analysis](./examples/lexical_analysis/)
|
||||
- [Language Model](./examples/language_model/)
|
||||
- [Semantic Parsing (Text to SQL)](./examples/text_to_sql):star:
|
||||
- [Text Classification](./examples/text_classification/)
|
||||
- [Text Matching](./examples/text_matching/)
|
||||
- [Text Generation](./examples/text_generation/)
|
||||
- [Text Correction](./examples/text_correction/):star:
|
||||
- [Semantic Indexing](./examples/semantic_indexing/)
|
||||
- [Information Extraction](./examples/information_extraction/)
|
||||
|
||||
### NLP System
|
||||
|
||||
- [Sentiment Analysis](./examples/sentiment_analysis/):star2:
|
||||
- [General Dialogue System](./examples/dialogue/)
|
||||
- [Machine Translation](./examples/machine_translation/)
|
||||
- [Simultaneous Translation](././examples/simultaneous_translation/)
|
||||
- [Machine Reading Comprehension](./examples/machine_reading_comprehension/)
|
||||
|
||||
### NLP Extented Applications
|
||||
|
||||
- [Few-shot Learning](./examples/few_shot/):star2:
|
||||
- [Text Knowledge Mining](./examples/text_to_knowledge/):star2:
|
||||
- [Model Compression](./examples/model_compression/)
|
||||
- [Text Graph Learning](./examples/text_graph/erniesage/)
|
||||
- [Time Series Prediction](./examples/time_series/)
|
||||
|
||||
## Tutorials
|
||||
|
||||
Please refer to our official AI Studio account for more interactive tutorials: [PaddleNLP on AI Studio](https://aistudio.baidu.com/aistudio/personalcenter/thirdview/574995)
|
||||
|
||||
* [What's Seq2Vec?](https://aistudio.baidu.com/aistudio/projectdetail/1283423) shows how to use simple API to finish LSTM model and solve sentiment analysis task.
|
||||
|
||||
* [Sentiment Analysis with ERNIE](https://aistudio.baidu.com/aistudio/projectdetail/1294333) shows how to exploit the pretrained ERNIE to solve sentiment analysis problem.
|
||||
|
||||
* [Waybill Information Extraction with BiGRU-CRF Model](https://aistudio.baidu.com/aistudio/projectdetail/1317771) shows how to make use of Bi-GRU plus CRF to finish information extraction task.
|
||||
|
||||
* [Waybill Information Extraction with ERNIE](https://aistudio.baidu.com/aistudio/projectdetail/1329361) shows how to use ERNIE, the Chinese pre-trained model improve information extraction performance.
|
||||
|
||||
* [Use TCN Model to predict COVID-19 confirmed cases](https://aistudio.baidu.com/aistudio/projectdetail/1290873)
|
||||
Please find all PaddleNLP API Reference from our [readthedocs](https://paddlenlp.readthedocs.io/).
|
||||
|
||||
## Community
|
||||
|
||||
### Special Interest Group (SIG)
|
||||
|
||||
Welcome to join [PaddleNLP SIG](https://iwenjuan.baidu.com/?code=bkypg8) for contribution, eg. Dataset, Models and Toolkit.
|
||||
|
||||
### Slack
|
||||
|
||||
To connect with other users and contributors, welcome to join our [Slack channel](https://paddlenlp.slack.com/).
|
||||
|
||||
### QQ
|
||||
Join our QQ Technical Group for technical exchange right now! ⬇️
|
||||
### WeChat
|
||||
|
||||
Scan the QR code below with your Wechat⬇️. You can access to official technical exchange group. Look forward to your participation.
|
||||
|
||||
<div align="center">
|
||||
<img src="./docs/imgs/qq.png" width="200" height="200" />
|
||||
<img src="https://user-images.githubusercontent.com/11793384/200770385-a2c02093-0e1d-4189-b324-8b0251cba316.jpg" width="150" height="150" />
|
||||
</div>
|
||||
|
||||
## ChangeLog
|
||||
|
||||
For more details about our release, please refer to [ChangeLog](./docs/changelog.md)
|
||||
|
||||
## Citation
|
||||
|
||||
If you find PaddleNLP useful in your research, please consider cite
|
||||
```
|
||||
@misc{=paddlenlp,
|
||||
title={PaddleNLP: An Easy-to-use and High Performance NLP Library},
|
||||
author={PaddleNLP Contributors},
|
||||
howpublished = {\url{https://github.com/PaddlePaddle/PaddleNLP}},
|
||||
year={2021}
|
||||
}
|
||||
```
|
||||
|
||||
## Acknowledge
|
||||
|
||||
We have borrowed from Hugging Face's [Transformers](https://github.com/huggingface/transformers)🤗 excellent design on pretrained models usage, and we would like to express our gratitude to the authors of Hugging Face and its open source community.
|
||||
|
||||
## License
|
||||
|
||||
|
||||
188
applications/document_intelligence/README.md
Normal file
188
applications/document_intelligence/README.md
Normal file
@@ -0,0 +1,188 @@
|
||||
# 文档智能应用
|
||||
|
||||
**目录**
|
||||
- [1. 文档智能应用简介](#文档智能应用简介)
|
||||
- [2. 技术特色介绍](#技术特色介绍)
|
||||
- [2.1 多语言跨模态训练基座](#多语言跨模态训练基座)
|
||||
- [2.2 多场景覆盖](#多场景覆盖)
|
||||
- [3. 快速开始](#快速开始)
|
||||
- [3.1 开箱即用](#开箱即用)
|
||||
- [3.2 产业级流程方案](#产业级流程方案)
|
||||
|
||||
## 1. 文档智能应用简介
|
||||
|
||||
文档智能(DI, Document Intelligence)主要指**对于网页、数字文档或扫描文档所包含的文本以及丰富的排版格式等信息,通过人工智能技术进行理解、分类、提取以及信息归纳**的过程。文档智能技术广泛应用于金融、保险、能源、物流、医疗等行业,常见的应用场景包括财务报销单、招聘简历、企业财报、合同文书、动产登记证、法律判决书、物流单据等多模态文档的关键信息抽取、文档解析、文档比对等。
|
||||
|
||||
在实际应用中,需要解决文档格式繁杂、布局多样、信息模态多样、需求开放、业务数据少等多重难题。针对文档智能领域的痛点和难点,PaddleNLP将持续开源一系列产业实践范例,解决开发者们实际应用难题。
|
||||
|
||||
<div align="center">
|
||||
<img width="1000" height="270" alt="文档智能技术一般流程" src="https://user-images.githubusercontent.com/40840292/196361583-6b1c66d1-6a9b-4193-949a-71e2d420a82a.png">
|
||||
</div>
|
||||
|
||||
<a name="技术特色介绍"></a>
|
||||
|
||||
## 2. 技术特色介绍
|
||||
|
||||
<a name="多语言跨模态训练基座"></a>
|
||||
|
||||
### 2.1 多语言跨模态训练基座
|
||||
|
||||
近期,百度文心文档智能,基于多语言跨模态布局增强的文档智能大模型[ERNIE-Layout](http://arxiv.org/abs/2210.06155),刷新了五类11项文档智能任务效果。依托文心ERNIE大模型,基于布局知识增强技术,融合文本、图像、布局等信息进行联合建模,能够对多模态文档(如文档图片、PDF 文件、扫描件等)进行深度理解与分析,为各类上层应用提供SOTA模型底座。
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/196373896-597f6178-4c78-41a1-bb12-796546644b32.png width="600"/>
|
||||
</div>
|
||||
|
||||
<a name="多场景覆盖"></a>
|
||||
|
||||
### 2.2 多场景覆盖
|
||||
|
||||
以下是文档智能技术的一些应用场景展示:
|
||||
|
||||
- 发票抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/196118171-fd3e49a0-b9f1-4536-a904-c48f709a2dec.png height=350 width=1000 hspace='10'/>
|
||||
</div>
|
||||
|
||||
- 海报抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195610368-04230855-62de-439e-b708-2c195b70461f.png height=600 width=1000 hspace='15'/>
|
||||
</div>
|
||||
|
||||
- 网页抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195611613-bdbe692e-d7f2-4a2b-b548-1a933463b0b9.png height=350 width=1000 hspace='10'/>
|
||||
</div>
|
||||
|
||||
|
||||
- 表格抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195610692-8367f1c8-32c2-4b5d-9514-a149795cf609.png height=350 width=1000 hspace='10'/>
|
||||
</div>
|
||||
|
||||
|
||||
- 试卷抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195823294-d891d95a-2ef8-4519-be59-0fedb96c00de.png height=700 width=1000 hspace='10'/>
|
||||
</div>
|
||||
|
||||
|
||||
- 英文票据多语种(中、英、日、泰、西班牙、俄语)抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195610820-7fb88608-b317-45fc-a6ab-97bf3b20a4ac.png height=400 width=1000 hspace='15'/>
|
||||
</div>
|
||||
|
||||
- 中文票据多语种(中简、中繁、英、日、法语)抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195611075-9323ce9f-134b-4657-ab1c-f4892075d909.png height=350 width=1000 hspace='15'/>
|
||||
</div>
|
||||
|
||||
- Demo图片可在此[下载](https://bj.bcebos.com/paddlenlp/taskflow/document_intelligence/demo.zip)
|
||||
|
||||
<a name="快速开始"></a>
|
||||
|
||||
## 3. 快速开始
|
||||
|
||||
<a name="开箱即用"></a>
|
||||
|
||||
### 3.1 开箱即用
|
||||
|
||||
开源DocPrompt开放文档抽取问答模型,以ERNIE-Layout为底座,可精准理解图文信息,推理学习附加知识,准备捕捉图片、PDF等多模态文档中的每个细节。
|
||||
|
||||
🧾 通过[Huggingface网页](https://huggingface.co/spaces/PaddlePaddle/ERNIE-Layout)体验DocPrompt功能:
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195749427-864d7744-1fd1-455e-99c6-53a260776483.jpg height=700 width=1100 hspace='10'/>
|
||||
</div>
|
||||
|
||||
#### Taskflow
|
||||
|
||||
通过``paddlenlp.Taskflow``三行代码调用DocPrompt功能,具备多语言文档抽取问答能力,部分应用场景展示如下:
|
||||
|
||||
- 输入格式
|
||||
|
||||
```
|
||||
[
|
||||
{"doc": "./invoice.jpg", "prompt": ["发票号码是多少?", "校验码是多少?"]},
|
||||
{"doc": "./resume.png", "prompt": ["五百丁本次想要担任的是什么职位?", "五百丁是在哪里上的大学?", "大学学的是什么专业?"]}
|
||||
]
|
||||
```
|
||||
|
||||
默认使用PaddleOCR进行OCR识别,同时支持用户通过``word_boxes``传入自己的OCR结果,格式为``List[str, List[float, float, float, float]]``。
|
||||
|
||||
```
|
||||
[
|
||||
{"doc": doc_path, "prompt": prompt, "word_boxes": word_boxes}
|
||||
]
|
||||
```
|
||||
|
||||
- 支持单条、批量预测
|
||||
|
||||
- 支持本地图片路径输入
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/194748579-f9e8aa86-7f65-4827-bfae-824c037228b3.png height=800 hspace='20'/>
|
||||
</div>
|
||||
|
||||
```python
|
||||
>>> from pprint import pprint
|
||||
>>> from paddlenlp import Taskflow
|
||||
|
||||
>>> docprompt = Taskflow("document_intelligence")
|
||||
>>> pprint(docprompt([{"doc": "./resume.png", "prompt": ["五百丁本次想要担任的是什么职位?", "五百丁是在哪里上的大学?", "大学学的是什么专业?"]}]))
|
||||
[{'prompt': '五百丁本次想要担任的是什么职位?',
|
||||
'result': [{'end': 7, 'prob': 1.0, 'start': 4, 'value': '客户经理'}]},
|
||||
{'prompt': '五百丁是在哪里上的大学?',
|
||||
'result': [{'end': 37, 'prob': 1.0, 'start': 31, 'value': '广州五百丁学院'}]},
|
||||
{'prompt': '大学学的是什么专业?',
|
||||
'result': [{'end': 44, 'prob': 0.82, 'start': 38, 'value': '金融学(本科)'}]}]
|
||||
```
|
||||
|
||||
- http图片链接输入
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/194748592-e20b2a5f-d36b-46fb-8057-86755d188af0.jpg height=400 hspace='10'/>
|
||||
</div>
|
||||
|
||||
```python
|
||||
>>> from pprint import pprint
|
||||
>>> from paddlenlp import Taskflow
|
||||
|
||||
>>> docprompt = Taskflow("document_intelligence")
|
||||
>>> pprint(docprompt([{"doc": "https://bj.bcebos.com/paddlenlp/taskflow/document_intelligence/images/invoice.jpg", "prompt": ["发票号码是多少?", "校验码是多少?"]}]))
|
||||
[{'prompt': '发票号码是多少?',
|
||||
'result': [{'end': 2, 'prob': 0.74, 'start': 2, 'value': 'No44527206'}]},
|
||||
{'prompt': '校验码是多少?',
|
||||
'result': [{'end': 233,
|
||||
'prob': 1.0,
|
||||
'start': 231,
|
||||
'value': '01107 555427109891646'}]}]
|
||||
```
|
||||
|
||||
- 可配置参数说明
|
||||
* `batch_size`:批处理大小,请结合机器情况进行调整,默认为1。
|
||||
* `lang`:选择PaddleOCR的语言,`ch`可在中英混合的图片中使用,`en`在英文图片上的效果更好,默认为`ch`。
|
||||
* `topn`: 如果模型识别出多个结果,将返回前n个概率值最高的结果,默认为1。
|
||||
|
||||
<a name="产业级流程方案"></a>
|
||||
|
||||
### 3.2 产业级流程方案
|
||||
|
||||
针对文档智能领域的痛点和难点,PaddleNLP将持续开源一系列文档智能产业实践范例,解决开发者们实际应用难题。
|
||||
|
||||
- 👉 [汽车说明书跨模态智能问答](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/document_intelligence/doc_vqa#readme)
|
||||
|
||||
更多:百度TextMind智能文档分析平台可提供包括文档信息抽取、文本内容审查、企业文档管理、文档格式解析、文档内容比对等全方位一站式的文档智能服务,已形成一套完整的企业文档场景化解决方案,满足银行、券商、法律、能源、传媒、通信、物流等不同行业和场景的文档处理需求,以AI助力企业的办公智能化升级和数字化转型。欢迎深度交流与商业合作,了解详情:https://ai.baidu.com/tech/nlp/Textanalysis
|
||||
|
||||
## References
|
||||
|
||||
- [文档智能:数据集、模型和应用](http://jcip.cipsc.org.cn/CN/abstract/abstract3331.shtml)
|
||||
|
||||
- [ERNIE-Layout: Layout-Knowledge Enhanced Multi-modal Pre-training for Document Understanding](http://arxiv.org/abs/2210.06155)
|
||||
17
applications/document_intelligence/doc_vqa/.gitignore
vendored
Normal file
17
applications/document_intelligence/doc_vqa/.gitignore
vendored
Normal file
@@ -0,0 +1,17 @@
|
||||
OCR_process/*.json
|
||||
*.png
|
||||
*.json
|
||||
answers/*
|
||||
checkpoints/*
|
||||
__pycache__/*
|
||||
OCR_process/demo_pics/*
|
||||
Rerank/log/*
|
||||
Rerank/checkpoints/*
|
||||
Rerank/data/*
|
||||
Rerank/output/*
|
||||
Rerank/__pycache__/*
|
||||
Extraction/log/*
|
||||
Extraction/checkpoints/*
|
||||
Extraction/data/*
|
||||
Extraction/output/*
|
||||
Extraction/__pycache__/*
|
||||
@@ -0,0 +1,51 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import json
|
||||
import numpy as np
|
||||
|
||||
|
||||
def get_top1_from_ranker(path):
|
||||
with open(path, "r", encoding="utf-8") as f:
|
||||
scores = [float(line.strip()) for line in f.readlines()]
|
||||
top_id = np.argmax(scores)
|
||||
|
||||
return top_id
|
||||
|
||||
|
||||
def get_ocr_result_by_id(path, top_id):
|
||||
with open(path, "r", encoding="utf-8") as f:
|
||||
reses = f.readlines()
|
||||
res = reses[top_id]
|
||||
return json.loads(res)
|
||||
|
||||
|
||||
def write_to_file(doc, path):
|
||||
with open(path, "w", encoding="utf-8") as f:
|
||||
json.dump(doc, f, ensure_ascii=False)
|
||||
f.write("\n")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
question = sys.argv[1]
|
||||
ranker_result_path = "../Rerank/data/demo.score"
|
||||
ocr_result_path = "../OCR_process/demo_ocr_res.json"
|
||||
save_path = "data/demo_test.json"
|
||||
top_id = get_top1_from_ranker(ranker_result_path)
|
||||
doc = get_ocr_result_by_id(ocr_result_path, top_id)
|
||||
doc["question"] = question
|
||||
doc["img_id"] = str(top_id + 1)
|
||||
|
||||
write_to_file(doc, save_path)
|
||||
382
applications/document_intelligence/doc_vqa/Extraction/docvqa.py
Executable file
382
applications/document_intelligence/doc_vqa/Extraction/docvqa.py
Executable file
@@ -0,0 +1,382 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import os
|
||||
import cv2
|
||||
import sys
|
||||
import json
|
||||
import copy
|
||||
import collections
|
||||
import numpy as np
|
||||
from tqdm import tqdm
|
||||
|
||||
import paddle
|
||||
from paddle.io import Dataset
|
||||
|
||||
sys.path.insert(0, "../")
|
||||
|
||||
|
||||
class DocVQAExample(object):
|
||||
|
||||
def __init__(self,
|
||||
question,
|
||||
doc_tokens,
|
||||
doc_boxes=[],
|
||||
answer=None,
|
||||
labels=None,
|
||||
image=None):
|
||||
self.question = question
|
||||
self.doc_tokens = doc_tokens
|
||||
self.doc_boxes = doc_boxes
|
||||
self.image = image
|
||||
self.answer = answer
|
||||
self.labels = labels
|
||||
|
||||
|
||||
class DocVQAFeatures(object):
|
||||
"""A single set of features of data."""
|
||||
|
||||
def __init__(self,
|
||||
example_index,
|
||||
input_ids,
|
||||
input_mask,
|
||||
segment_ids,
|
||||
boxes=None,
|
||||
label=None):
|
||||
self.example_index = example_index
|
||||
self.input_ids = input_ids
|
||||
self.input_mask = input_mask
|
||||
self.segment_ids = segment_ids
|
||||
self.boxes = boxes
|
||||
self.label = label
|
||||
|
||||
|
||||
class DocVQA(Dataset):
|
||||
|
||||
def __init__(self,
|
||||
args,
|
||||
tokenizer,
|
||||
label2id_map,
|
||||
max_seq_len=512,
|
||||
max_query_length=20,
|
||||
max_doc_length=512,
|
||||
max_span_num=1):
|
||||
super(DocVQA, self).__init__()
|
||||
self.tokenizer = tokenizer
|
||||
self.label2id_map = label2id_map
|
||||
self.max_seq_len = max_seq_len
|
||||
self.max_query_length = max_query_length
|
||||
self.max_doc_length = max_doc_length
|
||||
self.max_span_num = max_span_num
|
||||
self.sample_list = None
|
||||
self.args = args
|
||||
|
||||
self.docvqa_inputs = self.docvqa_input()
|
||||
|
||||
def check_is_max_context(self, doc_spans, cur_span_index, position):
|
||||
"""Check if this is the 'max context' doc span for the token."""
|
||||
|
||||
# Because of the sliding window approach taken to scoring documents, a single
|
||||
# token can appear in multiple documents. E.g.
|
||||
# Doc: the man went to the store and bought a gallon of milk
|
||||
# Span A: the man went to the
|
||||
# Span B: to the store and bought
|
||||
# Span C: and bought a gallon of
|
||||
# ...
|
||||
#
|
||||
# Now the word 'bought' will have two scores from spans B and C. We only
|
||||
# want to consider the score with "maximum context", which we define as
|
||||
# the *minimum* of its left and right context (the *sum* of left and
|
||||
# right context will always be the same, of course).
|
||||
#
|
||||
# In the example the maximum context for 'bought' would be span C since
|
||||
# it has 1 left context and 3 right context, while span B has 4 left context
|
||||
# and 0 right context.
|
||||
best_score = None
|
||||
best_span_index = None
|
||||
for (span_index, doc_span) in enumerate(doc_spans):
|
||||
end = doc_span.start + doc_span.length - 1
|
||||
if position < doc_span.start:
|
||||
continue
|
||||
if position > end:
|
||||
continue
|
||||
num_left_context = position - doc_span.start
|
||||
num_right_context = end - position
|
||||
score = min(num_left_context,
|
||||
num_right_context) + 0.01 * doc_span.length
|
||||
if best_score is None or score > best_score:
|
||||
best_score = score
|
||||
best_span_index = span_index
|
||||
|
||||
return cur_span_index == best_span_index
|
||||
|
||||
def convert_examples_to_features(self, examples, tokenizer, label_map,
|
||||
max_seq_length, max_span_num,
|
||||
max_doc_length, max_query_length):
|
||||
|
||||
if "[CLS]" in self.tokenizer.get_vocab():
|
||||
start_token = "[CLS]"
|
||||
end_token = "[SEP]"
|
||||
else:
|
||||
start_token = "<s>"
|
||||
end_token = "</s>"
|
||||
|
||||
features = []
|
||||
total = len(examples)
|
||||
for (example_index, example) in enumerate(examples):
|
||||
query_tokens = tokenizer.tokenize(example.question)
|
||||
if len(query_tokens) > max_query_length:
|
||||
query_tokens = query_tokens[0:max_query_length]
|
||||
|
||||
all_doc_tokens = example.doc_tokens
|
||||
all_doc_boxes_tokens = example.doc_boxes
|
||||
|
||||
cls_token_box = [0, 0, 0, 0]
|
||||
sep_token_box = [1000, 1000, 1000, 1000]
|
||||
pad_token_box = [0, 0, 0, 0]
|
||||
ques_token_box = [0, 0, 0, 0]
|
||||
|
||||
# The -3 accounts for [CLS], [SEP] and [SEP]
|
||||
max_tokens_for_doc = max_seq_length - len(query_tokens) - 3
|
||||
|
||||
# We can have documents that are longer than the maximum sequence length.
|
||||
# To deal with this we do a sliding window approach, where we take chunks
|
||||
# of the up to our max length with a stride of `doc_stride`.
|
||||
_DocSpan = collections.namedtuple("DocSpan", ["start", "length"])
|
||||
doc_spans = []
|
||||
start_offset = 0
|
||||
while start_offset < len(all_doc_tokens):
|
||||
length = len(all_doc_tokens) - start_offset
|
||||
if length > max_tokens_for_doc:
|
||||
length = max_tokens_for_doc
|
||||
doc_spans.append(_DocSpan(start=start_offset, length=length))
|
||||
if start_offset + length == len(all_doc_tokens):
|
||||
break
|
||||
start_offset += length
|
||||
|
||||
spans_input_ids = []
|
||||
spans_input_mask = []
|
||||
spans_segment_ids = []
|
||||
spans_boxes_tokens = []
|
||||
for (doc_span_index, doc_span) in enumerate(doc_spans):
|
||||
if doc_span_index == max_span_num:
|
||||
break
|
||||
tokens = []
|
||||
boxes_tokens = []
|
||||
token_is_max_context = {}
|
||||
segment_ids = []
|
||||
tokens.append(start_token)
|
||||
boxes_tokens.append(cls_token_box)
|
||||
segment_ids.append(0)
|
||||
for token in query_tokens:
|
||||
tokens.append(token)
|
||||
boxes_tokens.append(ques_token_box)
|
||||
segment_ids.append(0)
|
||||
tokens.append(end_token)
|
||||
boxes_tokens.append(sep_token_box)
|
||||
segment_ids.append(0)
|
||||
for i in range(doc_span.length):
|
||||
split_token_index = doc_span.start + i
|
||||
is_max_context = self.check_is_max_context(
|
||||
doc_spans, doc_span_index, split_token_index)
|
||||
token_is_max_context[len(tokens)] = is_max_context
|
||||
tokens.append(all_doc_tokens[split_token_index])
|
||||
boxes_tokens.append(all_doc_boxes_tokens[split_token_index])
|
||||
segment_ids.append(0)
|
||||
|
||||
tokens.append(end_token)
|
||||
boxes_tokens.append(sep_token_box)
|
||||
segment_ids.append(0)
|
||||
input_ids = tokenizer.convert_tokens_to_ids(tokens)
|
||||
# The mask has 1 for real tokens and 0 for padding tokens. Only real
|
||||
# tokens are attended to.
|
||||
input_mask = [1] * len(input_ids)
|
||||
# Zero-pad up to the sequence length.
|
||||
while len(input_ids) < max_seq_length:
|
||||
input_ids.append(0)
|
||||
input_mask.append(0)
|
||||
segment_ids.append(0)
|
||||
boxes_tokens.append(pad_token_box)
|
||||
assert len(input_ids) == max_seq_length
|
||||
assert len(input_mask) == max_seq_length
|
||||
assert len(segment_ids) == max_seq_length
|
||||
assert len(boxes_tokens) == max_seq_length
|
||||
|
||||
spans_input_ids.append(input_ids)
|
||||
spans_input_mask.append(input_mask)
|
||||
spans_segment_ids.append(segment_ids)
|
||||
spans_boxes_tokens.append(boxes_tokens)
|
||||
|
||||
# Padding
|
||||
# padding spans
|
||||
# max_span_num: max_seg_num
|
||||
# spans_input_ids: the tokens in each segment
|
||||
if len(spans_input_ids) > max_span_num:
|
||||
spans_input_ids = spans_input_ids[0:max_span_num]
|
||||
spans_input_mask = spans_input_mask[0:max_span_num]
|
||||
spans_segment_ids = spans_segment_ids[0:max_span_num]
|
||||
spans_boxes_tokens = spans_boxes_tokens[0:max_span_num]
|
||||
while len(spans_input_ids) < max_span_num:
|
||||
tokens = []
|
||||
boxes_tokens = []
|
||||
segment_ids = []
|
||||
tokens.append(start_token)
|
||||
boxes_tokens.append(cls_token_box)
|
||||
segment_ids.append(0)
|
||||
for token in query_tokens:
|
||||
tokens.append(token)
|
||||
boxes_tokens.append(ques_token_box)
|
||||
segment_ids.append(0)
|
||||
tokens.append(end_token)
|
||||
boxes_tokens.append(sep_token_box)
|
||||
segment_ids.append(0)
|
||||
tokens.append(end_token)
|
||||
boxes_tokens.append(sep_token_box)
|
||||
segment_ids.append(0)
|
||||
input_ids = tokenizer.convert_tokens_to_ids(tokens)
|
||||
input_mask = [1] * len(input_ids)
|
||||
while len(input_ids) < max_seq_length:
|
||||
input_ids.append(0)
|
||||
input_mask.append(0)
|
||||
segment_ids.append(0)
|
||||
boxes_tokens.append(pad_token_box)
|
||||
spans_input_ids.append(input_ids)
|
||||
spans_input_mask.append(input_mask)
|
||||
spans_segment_ids.append(segment_ids)
|
||||
spans_boxes_tokens.append(boxes_tokens)
|
||||
|
||||
# padding labels
|
||||
labels = example.labels
|
||||
sep_id = tokenizer.convert_tokens_to_ids(end_token)
|
||||
labels = ["O"] * (spans_input_ids[0].index(sep_id) + 1) + labels
|
||||
if len(labels) > 512:
|
||||
labels = labels[:512]
|
||||
|
||||
if len(labels) < 512:
|
||||
labels += ["O"] * (512 - len(labels))
|
||||
assert len(spans_input_ids[0]) == len(labels)
|
||||
|
||||
label_ids = []
|
||||
for lid, l in enumerate(labels):
|
||||
if l not in label_map:
|
||||
label_ids.append(0)
|
||||
else:
|
||||
label_ids.append(label_map[l])
|
||||
|
||||
feature = DocVQAFeatures(
|
||||
example_index=example_index,
|
||||
input_ids=spans_input_ids,
|
||||
input_mask=spans_input_mask,
|
||||
segment_ids=spans_segment_ids,
|
||||
boxes=spans_boxes_tokens,
|
||||
label=label_ids,
|
||||
)
|
||||
features.append(feature)
|
||||
return features
|
||||
|
||||
def create_examples(self, data, is_test=False):
|
||||
"""Creates examples for the training and dev sets."""
|
||||
examples = []
|
||||
for sample in tqdm(data, total=len(data)):
|
||||
question = sample["question"]
|
||||
doc_tokens = sample["document"]
|
||||
doc_boxes = sample["document_bbox"]
|
||||
labels = sample['labels'] if not is_test else []
|
||||
|
||||
x_min, y_min = min(doc_boxes, key=lambda x: x[0])[0], min(
|
||||
doc_boxes, key=lambda x: x[2])[2]
|
||||
x_max, y_max = max(doc_boxes, key=lambda x: x[1])[1], max(
|
||||
doc_boxes, key=lambda x: x[3])[3]
|
||||
width = x_max - x_min
|
||||
height = y_max - y_min
|
||||
|
||||
if max(width, height) < 1000:
|
||||
scale_x = 1
|
||||
scale_y = 1
|
||||
else:
|
||||
scale_x = 1000 / max(width, height)
|
||||
scale_y = 1000 / max(width, height)
|
||||
|
||||
scaled_doc_boxes = [[
|
||||
round((b[0] - x_min) * scale_x),
|
||||
round((b[2] - y_min) * scale_y),
|
||||
round((b[1] - x_min) * scale_x),
|
||||
round((b[3] - y_min) * scale_y)
|
||||
] for b in doc_boxes]
|
||||
|
||||
for box, oribox in zip(scaled_doc_boxes, doc_boxes):
|
||||
if box[0] < 0:
|
||||
print(box, oribox)
|
||||
if box[2] - box[0] < 0:
|
||||
print(box, oribox)
|
||||
if box[3] - box[1] < 0:
|
||||
print(box, oribox)
|
||||
for pos in box:
|
||||
if pos > 1000:
|
||||
print(width, height, box, oribox)
|
||||
|
||||
example = DocVQAExample(question=question,
|
||||
doc_tokens=doc_tokens,
|
||||
doc_boxes=scaled_doc_boxes,
|
||||
labels=labels)
|
||||
examples.append(example)
|
||||
return examples
|
||||
|
||||
def docvqa_input(self):
|
||||
data = []
|
||||
if self.args.do_train:
|
||||
dataset = self.args.train_file
|
||||
elif self.args.do_test:
|
||||
dataset = self.args.test_file
|
||||
with open(dataset, 'r', encoding='utf8') as f:
|
||||
for index, line in enumerate(f):
|
||||
data.append(json.loads(line.strip()))
|
||||
|
||||
# read the examples from train/test xlm files
|
||||
examples = self.create_examples(data, is_test=self.args.do_test)
|
||||
|
||||
features = self.convert_examples_to_features(
|
||||
examples,
|
||||
self.tokenizer,
|
||||
self.label2id_map,
|
||||
max_seq_length=self.max_seq_len,
|
||||
max_doc_length=self.max_doc_length,
|
||||
max_span_num=self.max_span_num,
|
||||
max_query_length=self.max_query_length)
|
||||
|
||||
all_input_ids = paddle.to_tensor([f.input_ids for f in features],
|
||||
dtype="int64")
|
||||
all_input_mask = paddle.to_tensor([f.input_mask for f in features],
|
||||
dtype="int64")
|
||||
all_segment_ids = paddle.to_tensor([f.segment_ids for f in features],
|
||||
dtype="int64")
|
||||
all_bboxes = paddle.to_tensor([f.boxes for f in features],
|
||||
dtype="int64")
|
||||
all_labels = paddle.to_tensor([f.label for f in features],
|
||||
dtype="int64")
|
||||
self.sample_list = [
|
||||
np.array(all_input_ids),
|
||||
np.array(all_input_mask),
|
||||
np.array(all_segment_ids),
|
||||
np.array(all_bboxes),
|
||||
np.array(all_labels)
|
||||
]
|
||||
|
||||
def __getitem__(self, idx):
|
||||
return self.sample_list[0][idx], self.sample_list[1][
|
||||
idx], self.sample_list[2][idx], self.sample_list[3][
|
||||
idx], self.sample_list[4][idx]
|
||||
|
||||
def __len__(self, ):
|
||||
return self.sample_list[0].shape[0]
|
||||
243
applications/document_intelligence/doc_vqa/Extraction/model.py
Normal file
243
applications/document_intelligence/doc_vqa/Extraction/model.py
Normal file
@@ -0,0 +1,243 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import numpy as np
|
||||
|
||||
import paddle
|
||||
import paddle.nn as nn
|
||||
import paddle.fluid as fluid
|
||||
from paddlenlp.transformers import LayoutXLMPretrainedModel
|
||||
|
||||
|
||||
class Crf_decoding(paddle.fluid.dygraph.Layer):
|
||||
|
||||
def __init__(self, param_attr, size=None, is_test=True, dtype='float32'):
|
||||
super(Crf_decoding, self).__init__()
|
||||
|
||||
self._dtype = dtype
|
||||
self._size = size
|
||||
self._is_test = is_test
|
||||
self._param_attr = param_attr
|
||||
self._transition = self.create_parameter(
|
||||
attr=self._param_attr,
|
||||
shape=[self._size + 2, self._size],
|
||||
dtype=self._dtype)
|
||||
|
||||
@property
|
||||
def weight(self):
|
||||
return self._transition
|
||||
|
||||
@weight.setter
|
||||
def weight(self, value):
|
||||
self._transition = value
|
||||
|
||||
def forward(self, input, label=None, length=None):
|
||||
|
||||
viterbi_path = self._helper.create_variable_for_type_inference(
|
||||
dtype=self._dtype)
|
||||
this_inputs = {
|
||||
"Emission": [input],
|
||||
"Transition": self._transition,
|
||||
"Label": label
|
||||
}
|
||||
if length is not None:
|
||||
this_inputs['Length'] = [length]
|
||||
self._helper.append_op(type='crf_decoding',
|
||||
inputs=this_inputs,
|
||||
outputs={"ViterbiPath": [viterbi_path]},
|
||||
attrs={
|
||||
"is_test": self._is_test,
|
||||
})
|
||||
return viterbi_path
|
||||
|
||||
|
||||
class Chunk_eval(paddle.fluid.dygraph.Layer):
|
||||
|
||||
def __init__(self,
|
||||
num_chunk_types,
|
||||
chunk_scheme,
|
||||
excluded_chunk_types=None):
|
||||
super(Chunk_eval, self).__init__()
|
||||
self.num_chunk_types = num_chunk_types
|
||||
self.chunk_scheme = chunk_scheme
|
||||
self.excluded_chunk_types = excluded_chunk_types
|
||||
|
||||
def forward(self, input, label, seq_length=None):
|
||||
|
||||
precision = self._helper.create_variable_for_type_inference(
|
||||
dtype="float32")
|
||||
recall = self._helper.create_variable_for_type_inference(
|
||||
dtype="float32")
|
||||
f1_score = self._helper.create_variable_for_type_inference(
|
||||
dtype="float32")
|
||||
num_infer_chunks = self._helper.create_variable_for_type_inference(
|
||||
dtype="int64")
|
||||
num_label_chunks = self._helper.create_variable_for_type_inference(
|
||||
dtype="int64")
|
||||
num_correct_chunks = self._helper.create_variable_for_type_inference(
|
||||
dtype="int64")
|
||||
|
||||
this_input = {"Inference": [input], "Label": [label]}
|
||||
if seq_length is not None:
|
||||
this_input["SeqLength"] = [seq_length]
|
||||
|
||||
self._helper.append_op(type='chunk_eval',
|
||||
inputs=this_input,
|
||||
outputs={
|
||||
"Precision": [precision],
|
||||
"Recall": [recall],
|
||||
"F1-Score": [f1_score],
|
||||
"NumInferChunks": [num_infer_chunks],
|
||||
"NumLabelChunks": [num_label_chunks],
|
||||
"NumCorrectChunks": [num_correct_chunks]
|
||||
},
|
||||
attrs={
|
||||
"num_chunk_types":
|
||||
self.num_chunk_types,
|
||||
"chunk_scheme":
|
||||
self.chunk_scheme,
|
||||
"excluded_chunk_types":
|
||||
self.excluded_chunk_types or []
|
||||
})
|
||||
return (precision, recall, f1_score, num_infer_chunks, num_label_chunks,
|
||||
num_correct_chunks)
|
||||
|
||||
|
||||
class Linear_chain_crf(paddle.fluid.dygraph.Layer):
|
||||
|
||||
def __init__(self, param_attr, size=None, is_test=False, dtype='float32'):
|
||||
super(Linear_chain_crf, self).__init__()
|
||||
|
||||
self._param_attr = param_attr
|
||||
self._dtype = dtype
|
||||
self._size = size
|
||||
self._is_test = is_test
|
||||
self._transition = self.create_parameter(
|
||||
attr=self._param_attr,
|
||||
shape=[self._size + 2, self._size],
|
||||
dtype=self._dtype)
|
||||
|
||||
@property
|
||||
def weight(self):
|
||||
return self._transition
|
||||
|
||||
@weight.setter
|
||||
def weight(self, value):
|
||||
self._transition = value
|
||||
|
||||
def forward(self, input, label, length=None):
|
||||
|
||||
alpha = self._helper.create_variable_for_type_inference(
|
||||
dtype=self._dtype)
|
||||
emission_exps = self._helper.create_variable_for_type_inference(
|
||||
dtype=self._dtype)
|
||||
transition_exps = self._helper.create_variable_for_type_inference(
|
||||
dtype=self._dtype)
|
||||
log_likelihood = self._helper.create_variable_for_type_inference(
|
||||
dtype=self._dtype)
|
||||
this_inputs = {
|
||||
"Emission": [input],
|
||||
"Transition": self._transition,
|
||||
"Label": [label]
|
||||
}
|
||||
if length is not None:
|
||||
this_inputs['Length'] = [length]
|
||||
self._helper.append_op(type='linear_chain_crf',
|
||||
inputs=this_inputs,
|
||||
outputs={
|
||||
"Alpha": [alpha],
|
||||
"EmissionExps": [emission_exps],
|
||||
"TransitionExps": transition_exps,
|
||||
"LogLikelihood": log_likelihood
|
||||
},
|
||||
attrs={
|
||||
"is_test": self._is_test,
|
||||
})
|
||||
return log_likelihood
|
||||
|
||||
|
||||
class LayoutXLMForTokenClassification_with_CRF(LayoutXLMPretrainedModel):
|
||||
|
||||
def __init__(self, layoutxlm, num_classes, dropout=None):
|
||||
super(LayoutXLMForTokenClassification_with_CRF, self).__init__()
|
||||
self.num_classes = num_classes
|
||||
if isinstance(layoutxlm, dict):
|
||||
self.layoutxlm = LayoutXLMModel(**layoutxlm)
|
||||
else:
|
||||
self.layoutxlm = layoutxlm
|
||||
self.dropout = nn.Dropout(dropout if dropout is not None else self.
|
||||
layoutxlm.config["hidden_dropout_prob"])
|
||||
self.emission_classifier = nn.Linear(
|
||||
self.layoutxlm.config["hidden_size"], self.num_classes)
|
||||
self.emission_classifier.apply(self.init_weights)
|
||||
self.linear_chain_crf = Linear_chain_crf(
|
||||
size=self.num_classes,
|
||||
param_attr=paddle.fluid.ParamAttr(name='liner_chain_crfw'))
|
||||
self.crf_decoding = Crf_decoding(
|
||||
param_attr=paddle.fluid.ParamAttr(name='crfw_decode'),
|
||||
size=self.num_classes)
|
||||
self.crf_decoding.weight = self.linear_chain_crf.weight
|
||||
self.crfw = fluid.layers.create_parameter(
|
||||
shape=[self.num_classes + 2, self.num_classes],
|
||||
dtype='float32',
|
||||
name='crfw')
|
||||
self.mask_crfw = fluid.layers.create_parameter(
|
||||
shape=[self.num_classes + 2, self.num_classes],
|
||||
dtype='float32',
|
||||
name='mask_matrix')
|
||||
|
||||
def get_input_embeddings(self):
|
||||
return self.layoutxlm.embeddings.word_embeddings
|
||||
|
||||
def forward(self,
|
||||
input_ids=None,
|
||||
bbox=None,
|
||||
attention_mask=None,
|
||||
token_type_ids=None,
|
||||
labels=None,
|
||||
image=None,
|
||||
position_ids=None,
|
||||
head_mask=None,
|
||||
is_train=False):
|
||||
|
||||
input_ids = input_ids.squeeze(axis=1)
|
||||
bbox = bbox.squeeze(axis=1)
|
||||
attention_mask = attention_mask.squeeze(axis=1)
|
||||
token_type_ids = token_type_ids.squeeze(axis=1)
|
||||
outputs = self.layoutxlm(
|
||||
input_ids=input_ids,
|
||||
bbox=bbox,
|
||||
image=image,
|
||||
attention_mask=attention_mask,
|
||||
token_type_ids=token_type_ids,
|
||||
position_ids=position_ids,
|
||||
head_mask=head_mask,
|
||||
)
|
||||
seq_length = input_ids.shape[1]
|
||||
# sequence out and image out
|
||||
sequence_logits, image_output = outputs[0][:, :seq_length], outputs[
|
||||
0][:, seq_length:]
|
||||
emission = self.emission_classifier(sequence_logits)
|
||||
length = paddle.sum(attention_mask, axis=1)
|
||||
labels = labels.reshape([-1, seq_length, 1])
|
||||
|
||||
# standard crf loss
|
||||
crf_cost = self.linear_chain_crf(input=emission,
|
||||
label=labels,
|
||||
length=length)
|
||||
crf_decode = self.crf_decoding(input=emission, length=length)
|
||||
if is_train:
|
||||
return [crf_cost]
|
||||
else:
|
||||
return [crf_cost, crf_decode]
|
||||
464
applications/document_intelligence/doc_vqa/Extraction/run_docvqa.py
Executable file
464
applications/document_intelligence/doc_vqa/Extraction/run_docvqa.py
Executable file
@@ -0,0 +1,464 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import os
|
||||
import sys
|
||||
import copy
|
||||
import json
|
||||
import random
|
||||
import logging
|
||||
import warnings
|
||||
import argparse
|
||||
import numpy as np
|
||||
from collections import OrderedDict, Counter
|
||||
|
||||
import paddle
|
||||
from paddle.static import InputSpec
|
||||
from paddle.jit import to_static
|
||||
from paddlenlp.transformers import LayoutXLMModel, LayoutXLMTokenizer
|
||||
|
||||
from docvqa import DocVQA
|
||||
from model import LayoutXLMForTokenClassification_with_CRF
|
||||
|
||||
warnings.filterwarnings("ignore")
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def parse_args():
|
||||
parser = argparse.ArgumentParser()
|
||||
# yapf: disable
|
||||
parser.add_argument("--model_name_or_path", default=None, type=str, required=True)
|
||||
parser.add_argument("--do_train", default=False, type=bool, required=False)
|
||||
parser.add_argument("--do_test", default=False, type=bool, required=False)
|
||||
parser.add_argument("--test_file", default=None, type=str, required=False)
|
||||
parser.add_argument("--train_file", default=None, type=str, required=False)
|
||||
parser.add_argument("--output_dir", default=None, type=str, required=True)
|
||||
parser.add_argument("--max_seq_len", default=512, type=int)
|
||||
parser.add_argument("--max_query_length", default=20, type=int)
|
||||
parser.add_argument("--max_doc_length", default=512, type=int)
|
||||
parser.add_argument("--max_span_num", default=1, type=int)
|
||||
parser.add_argument("--per_gpu_train_batch_size", default=8, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument("--per_gpu_eval_batch_size", default=8, type=int, help="Batch size per GPU/CPU for eval.")
|
||||
parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
|
||||
parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
|
||||
parser.add_argument("--adam_epsilon", default=1e-8, type=float, help="Epsilon for Adam optimizer.")
|
||||
parser.add_argument("--num_train_epochs", default=3, type=int, help="Total number of training epochs to perform.")
|
||||
parser.add_argument("--warmup_steps", default=0, type=int, help="Linear warmup over warmup_steps.")
|
||||
parser.add_argument("--eval_steps", type=int, default=10, help="eval every X updates steps.")
|
||||
parser.add_argument("--save_steps", type=int, default=50, help="Save checkpoint every X updates steps.")
|
||||
parser.add_argument("--seed", type=int, default=42, help="random seed for initialization")
|
||||
parser.add_argument("--init_checkpoint", type=str, default=None, help="the initialized checkpoint")
|
||||
parser.add_argument("--save_path", type=str, default=None, help="the initialized checkpoint")
|
||||
# yapf: enable
|
||||
args = parser.parse_args()
|
||||
return args
|
||||
|
||||
|
||||
def set_seed(args):
|
||||
random.seed(args.seed)
|
||||
np.random.seed(args.seed)
|
||||
paddle.seed(args.seed)
|
||||
|
||||
|
||||
def get_label_maps():
|
||||
labels = ["O", "I-ans", "B-ans", "E-ans"]
|
||||
label2id_map = {label: idx for idx, label in enumerate(labels)}
|
||||
id2label_map = {idx: label for idx, label in enumerate(labels)}
|
||||
return label2id_map, id2label_map
|
||||
|
||||
|
||||
def main(args):
|
||||
os.makedirs(args.output_dir, exist_ok=True)
|
||||
logging.basicConfig(
|
||||
filename=os.path.join(args.output_dir, "train.log")
|
||||
if paddle.distributed.get_rank() == 0 else None,
|
||||
format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
|
||||
datefmt="%m/%d/%Y %H:%M:%S",
|
||||
level=logging.INFO
|
||||
if paddle.distributed.get_rank() == 0 else logging.WARN,
|
||||
)
|
||||
|
||||
ch = logging.StreamHandler()
|
||||
ch.setLevel(logging.DEBUG)
|
||||
logger.addHandler(ch)
|
||||
|
||||
label2id_map, id2label_map = get_label_maps()
|
||||
pad_token_label_id = paddle.nn.CrossEntropyLoss().ignore_index
|
||||
|
||||
# dist mode
|
||||
if paddle.distributed.get_world_size() > 1:
|
||||
paddle.distributed.init_parallel_env()
|
||||
|
||||
tokenizer = LayoutXLMTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
if args.do_test:
|
||||
model = LayoutXLMForTokenClassification_with_CRF.from_pretrained(
|
||||
args.init_checkpoint)
|
||||
evaluate(args,
|
||||
model,
|
||||
tokenizer,
|
||||
label2id_map,
|
||||
id2label_map,
|
||||
pad_token_label_id,
|
||||
global_step=0)
|
||||
exit(0)
|
||||
|
||||
if args.init_checkpoint:
|
||||
logger.info('Init checkpoint from {}'.format(args.init_checkpoint))
|
||||
model = LayoutXLMForTokenClassification_with_CRF.from_pretrained(
|
||||
args.init_checkpoint)
|
||||
else:
|
||||
base_model = LayoutXLMModel.from_pretrained(args.model_name_or_path)
|
||||
model = LayoutXLMForTokenClassification_with_CRF(
|
||||
base_model, num_classes=len(label2id_map), dropout=None)
|
||||
|
||||
# dist mode
|
||||
if paddle.distributed.get_world_size() > 1:
|
||||
model = paddle.DataParallel(model)
|
||||
|
||||
train_dataset = DocVQA(args,
|
||||
tokenizer,
|
||||
label2id_map,
|
||||
max_seq_len=args.max_seq_len,
|
||||
max_query_length=args.max_query_length,
|
||||
max_doc_length=args.max_doc_length,
|
||||
max_span_num=args.max_span_num)
|
||||
|
||||
train_sampler = paddle.io.DistributedBatchSampler(
|
||||
train_dataset, batch_size=args.per_gpu_train_batch_size, shuffle=False)
|
||||
|
||||
args.train_batch_size = args.per_gpu_train_batch_size * max(
|
||||
1, paddle.distributed.get_world_size())
|
||||
|
||||
train_dataloader = paddle.io.DataLoader(train_dataset,
|
||||
batch_sampler=train_sampler,
|
||||
num_workers=0,
|
||||
use_shared_memory=True,
|
||||
collate_fn=None)
|
||||
|
||||
t_total = len(train_dataloader) * args.num_train_epochs
|
||||
# build linear decay with warmup lr sch
|
||||
lr_scheduler = paddle.optimizer.lr.PolynomialDecay(
|
||||
learning_rate=args.learning_rate,
|
||||
decay_steps=t_total,
|
||||
end_lr=0.0,
|
||||
power=1.0)
|
||||
if args.warmup_steps > 0:
|
||||
lr_scheduler = paddle.optimizer.lr.LinearWarmup(
|
||||
lr_scheduler,
|
||||
args.warmup_steps,
|
||||
start_lr=0,
|
||||
end_lr=args.learning_rate)
|
||||
|
||||
optimizer = paddle.optimizer.AdamW(learning_rate=lr_scheduler,
|
||||
parameters=model.parameters(),
|
||||
epsilon=args.adam_epsilon,
|
||||
weight_decay=args.weight_decay)
|
||||
|
||||
logger.info("***** Running training *****")
|
||||
logger.info(" Num examples = %d", len(train_dataset))
|
||||
logger.info(" Num Epochs = %d", args.num_train_epochs)
|
||||
logger.info(" Instantaneous batch size per GPU = %d",
|
||||
args.per_gpu_train_batch_size)
|
||||
logger.info(
|
||||
" Total train batch size (w. parallel, distributed) = %d",
|
||||
args.train_batch_size * paddle.distributed.get_world_size(),
|
||||
)
|
||||
logger.info(" Total optimization steps = %d", t_total)
|
||||
|
||||
global_step = 0
|
||||
tr_loss = 0.0
|
||||
set_seed(args)
|
||||
best_metrics = None
|
||||
for epoch_id in range(args.num_train_epochs):
|
||||
print('epoch id:{}'.format(epoch_id))
|
||||
for step, batch in enumerate(train_dataloader):
|
||||
model.train()
|
||||
input_ids, input_mask, segment_ids, bboxes, labels = batch
|
||||
if input_ids.shape[0] != args.per_gpu_train_batch_size:
|
||||
continue
|
||||
outputs = model(input_ids=input_ids,
|
||||
bbox=bboxes,
|
||||
attention_mask=input_mask,
|
||||
token_type_ids=segment_ids,
|
||||
labels=labels,
|
||||
is_train=True)
|
||||
# model outputs are always tuple in paddlenlp (see doc)
|
||||
loss = outputs[0]
|
||||
loss = loss.mean()
|
||||
if global_step % 50 == 0:
|
||||
logger.info(
|
||||
"[epoch {}/{}][iter: {}/{}] lr: {:.5f}, train loss: {:.5f}, "
|
||||
.format(epoch_id, args.num_train_epochs, step,
|
||||
len(train_dataloader), lr_scheduler.get_lr(),
|
||||
loss.numpy()[0]))
|
||||
|
||||
loss.backward()
|
||||
tr_loss += loss.item()
|
||||
optimizer.step()
|
||||
lr_scheduler.step() # Update learning rate schedule
|
||||
optimizer.clear_grad()
|
||||
global_step += 1
|
||||
|
||||
if paddle.distributed.get_rank(
|
||||
) == 0 and args.save_steps > 0 and global_step % args.save_steps == 0:
|
||||
# Save model checkpoint
|
||||
output_dir = os.path.join(args.output_dir,
|
||||
"checkpoint-{}".format(global_step))
|
||||
os.makedirs(output_dir, exist_ok=True)
|
||||
if paddle.distributed.get_rank() == 0:
|
||||
model.save_pretrained(output_dir)
|
||||
tokenizer.save_pretrained(output_dir)
|
||||
paddle.save(args,
|
||||
os.path.join(output_dir, "training_args.bin"))
|
||||
logger.info("Saving model checkpoint to %s", output_dir)
|
||||
|
||||
|
||||
def _tokenize_chinese_chars(text):
|
||||
"""
|
||||
:param text: input text, unicode string
|
||||
:return:
|
||||
tokenized text, list
|
||||
"""
|
||||
|
||||
def _is_chinese_char(cp):
|
||||
"""Checks whether CP is the codepoint of a CJK character."""
|
||||
# This defines a "chinese character" as anything in the CJK Unicode block:
|
||||
# https://en.wikipedia.org/wiki/CJK_Unified_Ideographs_(Unicode_block)
|
||||
#
|
||||
# Note that the CJK Unicode block is NOT all Japanese and Korean characters,
|
||||
# despite its name. The modern Korean Hangul alphabet is a different block,
|
||||
# as is Japanese Hiragana and Katakana. Those alphabets are used to write
|
||||
# space-separated words, so they are not treated specially and handled
|
||||
# like the all of the other languages.
|
||||
if ((cp >= 0x4E00 and cp <= 0x9FFF) or #
|
||||
(cp >= 0x3400 and cp <= 0x4DBF) or #
|
||||
(cp >= 0x20000 and cp <= 0x2A6DF) or #
|
||||
(cp >= 0x2A700 and cp <= 0x2B73F) or #
|
||||
(cp >= 0x2B740 and cp <= 0x2B81F) or #
|
||||
(cp >= 0x2B820 and cp <= 0x2CEAF) or
|
||||
(cp >= 0xF900 and cp <= 0xFAFF) or #
|
||||
(cp >= 0x2F800 and cp <= 0x2FA1F)): #
|
||||
return True
|
||||
|
||||
return False
|
||||
|
||||
output = []
|
||||
buff = ""
|
||||
for char in text:
|
||||
cp = ord(char)
|
||||
if _is_chinese_char(cp) or char == "=":
|
||||
if buff != "":
|
||||
output.append(buff)
|
||||
buff = ""
|
||||
output.append(char)
|
||||
else:
|
||||
buff += char
|
||||
|
||||
if buff != "":
|
||||
output.append(buff)
|
||||
|
||||
return output
|
||||
|
||||
|
||||
def fast_f1(text1, text2):
|
||||
common_char = Counter(text1) & Counter(text2)
|
||||
len_seq1 = len(text1)
|
||||
len_seq2 = len(text2)
|
||||
len_common = sum(common_char.values())
|
||||
if len_common == 0:
|
||||
return 0.0
|
||||
precision = 1.0 * len_common / len_seq2
|
||||
recall = 1.0 * len_common / len_seq1
|
||||
return (2.0 * precision * recall) / (precision + recall)
|
||||
|
||||
|
||||
def _normalize(in_str):
|
||||
"""
|
||||
normalize the input unicode string
|
||||
"""
|
||||
in_str = in_str.lower()
|
||||
sp_char = [
|
||||
u':', u'_', u'`', u',', u'。', u':', u'?', u'!', u'(', u')', u'“', u'”',
|
||||
u';', u'’', u'《', u'》', u'……', u'·', u'、', u',', u'「', u'」', u'(', u')',
|
||||
u'-', u'~', u'『', u'』', '|'
|
||||
]
|
||||
out_segs = []
|
||||
for char in in_str:
|
||||
if char in sp_char:
|
||||
continue
|
||||
else:
|
||||
out_segs.append(char)
|
||||
return ''.join(out_segs)
|
||||
|
||||
|
||||
def calc_f1_score(answer, prediction):
|
||||
f1_scores = []
|
||||
ans_segs = _tokenize_chinese_chars(_normalize(answer))
|
||||
prediction_segs = _tokenize_chinese_chars(_normalize(prediction))
|
||||
f1 = fast_f1(prediction_segs, ans_segs)
|
||||
return f1
|
||||
|
||||
|
||||
def decode(tokenizer, res):
|
||||
sep_id = tokenizer._convert_token_to_id("</s>")
|
||||
text_res = []
|
||||
all_f1 = []
|
||||
save_f1 = []
|
||||
for i in range(len(res)):
|
||||
input_ids, label_ids, predict_ids, bbox = res[i]
|
||||
remove_pos = len(' '.join(
|
||||
[str(x) for x in input_ids]).split('2 6 ')[0].strip(' ').split(
|
||||
' ')) + 2 # remove the question bbox and sep bbox
|
||||
start_pos = input_ids.index(sep_id)
|
||||
query_text = []
|
||||
for idx in range(1, start_pos):
|
||||
input_id = input_ids[idx]
|
||||
query_text.append(tokenizer._convert_id_to_token(int(input_id)))
|
||||
|
||||
#label texts and predict texts
|
||||
text_label, text_predict = [], []
|
||||
label_bbox_index, predict_bbox_index = [], []
|
||||
for idx in range(start_pos + 1, len(input_ids)):
|
||||
input_id, label_id, predict_id = input_ids[idx], label_ids[
|
||||
idx], predict_ids[idx]
|
||||
|
||||
if label_id in [1, 2, 3]:
|
||||
text_label.append(tokenizer._convert_id_to_token(int(input_id)))
|
||||
label_bbox_index.append(idx - remove_pos + 1)
|
||||
if predict_id in [1, 2, 3]:
|
||||
text_predict.append(
|
||||
tokenizer._convert_id_to_token(int(input_id)))
|
||||
predict_bbox_index.append(idx - remove_pos + 1)
|
||||
text_res.append([
|
||||
''.join(query_text), ''.join(text_label), ''.join(text_predict),
|
||||
label_bbox_index, predict_bbox_index
|
||||
])
|
||||
|
||||
f1 = calc_f1_score(''.join(text_label), ''.join(text_predict))
|
||||
save_f1.append(f1)
|
||||
|
||||
if len(''.join(text_label)) > 10:
|
||||
all_f1.append(f1)
|
||||
if len(all_f1) > 0:
|
||||
print("F1: ", sum(all_f1) / len(all_f1))
|
||||
|
||||
assert len(text_res) == len(save_f1)
|
||||
return text_res
|
||||
|
||||
|
||||
def evaluate(args,
|
||||
model,
|
||||
tokenizer,
|
||||
label2id_map,
|
||||
id2label_map,
|
||||
pad_token_label_id,
|
||||
prefix="",
|
||||
global_step=0):
|
||||
|
||||
eval_dataset = DocVQA(args,
|
||||
tokenizer,
|
||||
label2id_map,
|
||||
max_seq_len=512,
|
||||
max_query_length=20,
|
||||
max_doc_length=512,
|
||||
max_span_num=1)
|
||||
|
||||
args.eval_batch_size = args.per_gpu_eval_batch_size * max(
|
||||
1, paddle.distributed.get_world_size())
|
||||
|
||||
eval_dataloader = paddle.io.DataLoader(eval_dataset,
|
||||
batch_size=args.eval_batch_size,
|
||||
num_workers=0,
|
||||
use_shared_memory=True,
|
||||
collate_fn=None)
|
||||
|
||||
# Eval!
|
||||
logger.info("***** Running evaluation %s *****", prefix)
|
||||
logger.info(" Num examples = %d", len(eval_dataset))
|
||||
logger.info(" Batch size = %d", args.eval_batch_size)
|
||||
model.eval()
|
||||
res = []
|
||||
for idx, batch in enumerate(eval_dataloader):
|
||||
with paddle.no_grad():
|
||||
input_ids, input_mask, segment_ids, bboxes, labels = batch
|
||||
|
||||
if input_ids.shape[0] != args.eval_batch_size:
|
||||
continue
|
||||
outputs = model(input_ids=input_ids,
|
||||
bbox=bboxes,
|
||||
attention_mask=input_mask,
|
||||
token_type_ids=segment_ids,
|
||||
labels=labels,
|
||||
is_train=False)
|
||||
labels = labels.numpy()
|
||||
crf_decode = outputs[1].numpy()
|
||||
bboxes = bboxes.squeeze().numpy()
|
||||
input_ids = input_ids.squeeze(axis=1).numpy()
|
||||
|
||||
for index in range(input_ids.shape[0]):
|
||||
res.append([
|
||||
list(input_ids[index]),
|
||||
list(labels[index]),
|
||||
list(crf_decode[index]), bboxes[index]
|
||||
])
|
||||
|
||||
origin_inputs = []
|
||||
with open(args.test_file, 'r', encoding='utf8') as f:
|
||||
for line in f:
|
||||
line = json.loads(line.strip())
|
||||
origin_inputs.append({
|
||||
'img_name': line['img_name'],
|
||||
'question': line['question'],
|
||||
'bboxes': line['document_bbox'],
|
||||
'img_id': line['img_id']
|
||||
})
|
||||
|
||||
text_res = decode(tokenizer, res)
|
||||
|
||||
with open(args.save_path, 'w', encoding='utf8') as f:
|
||||
for line_res, line_text, line_label in zip(res, text_res,
|
||||
origin_inputs):
|
||||
line_json = {}
|
||||
line_json['img_name'] = line_label['img_name']
|
||||
line_json['img_id'] = line_label['img_id']
|
||||
line_json['question'] = line_label['question']
|
||||
line_json['label_answer'] = line_text[1]
|
||||
line_json['predict_answer'] = line_text[2]
|
||||
all_boxes = line_res[3]
|
||||
label_bbox_index, predict_bbox_index = line_text[3], line_text[4]
|
||||
label_bboxes, predict_bboxes = [], []
|
||||
for i in range(len(line_label['bboxes'])):
|
||||
if i in label_bbox_index:
|
||||
label_bboxes.append(line_label['bboxes'][i])
|
||||
if i in predict_bbox_index:
|
||||
predict_bboxes.append(line_label['bboxes'][i])
|
||||
line_json['label_bboxes'] = label_bboxes
|
||||
line_json['predict_bboxes'] = predict_bboxes
|
||||
json.dump(line_json, f, ensure_ascii=False)
|
||||
f.write('\n')
|
||||
|
||||
|
||||
def print_arguments(args):
|
||||
"""print arguments"""
|
||||
print('----------- Configuration Arguments -----------')
|
||||
for arg, value in sorted(vars(args).items()):
|
||||
print('%s: %s' % (arg, value))
|
||||
print('------------------------------------------------')
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_args()
|
||||
print_arguments(args)
|
||||
main(args)
|
||||
38
applications/document_intelligence/doc_vqa/Extraction/run_test.sh
Executable file
38
applications/document_intelligence/doc_vqa/Extraction/run_test.sh
Executable file
@@ -0,0 +1,38 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
QUESTION=$1
|
||||
|
||||
python3 change_to_mrc.py ${QUESTION}
|
||||
|
||||
python3 ./run_docvqa.py \
|
||||
--model_name_or_path "layoutxlm-base-uncased" \
|
||||
--max_seq_len 512 \
|
||||
--do_test true \
|
||||
--test_file "data/demo_test.json" \
|
||||
--num_train_epochs 100 \
|
||||
--eval_steps 6000 \
|
||||
--save_steps 6000 \
|
||||
--output_dir "output/" \
|
||||
--save_path "data/decode_res.json" \
|
||||
--init_checkpoint "./checkpoints/layoutxlm/" \
|
||||
--learning_rate 3e-5 \
|
||||
--warmup_steps 12000 \
|
||||
--per_gpu_train_batch_size 4 \
|
||||
--per_gpu_eval_batch_size 1 \
|
||||
--seed 2048
|
||||
|
||||
python3 view.py
|
||||
32
applications/document_intelligence/doc_vqa/Extraction/run_train.sh
Executable file
32
applications/document_intelligence/doc_vqa/Extraction/run_train.sh
Executable file
@@ -0,0 +1,32 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
python3 ./run_docvqa.py \
|
||||
--model_name_or_path "layoutxlm-base-uncased" \
|
||||
--max_seq_len 512 \
|
||||
--train_file "data/train.json" \
|
||||
--init_checkpoint "checkpoints/base_model" \
|
||||
--do_train true \
|
||||
--num_train_epochs 50 \
|
||||
--eval_steps 24000 \
|
||||
--save_steps 40 \
|
||||
--output_dir "output" \
|
||||
--save_path "data/decode_res.json" \
|
||||
--learning_rate 3e-5 \
|
||||
--warmup_steps 40 \
|
||||
--per_gpu_train_batch_size 4 \
|
||||
--per_gpu_eval_batch_size 4 \
|
||||
--seed 2048
|
||||
67
applications/document_intelligence/doc_vqa/Extraction/view.py
Executable file
67
applications/document_intelligence/doc_vqa/Extraction/view.py
Executable file
@@ -0,0 +1,67 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import cv2
|
||||
import json
|
||||
import numpy as np
|
||||
|
||||
|
||||
def view_ocr_result(img_path, bboxes, opath):
|
||||
image = cv2.imread(img_path)
|
||||
for char_bbox in bboxes:
|
||||
x_min, x_max, y_min, y_max = char_bbox
|
||||
cv2.rectangle(image, (x_min, y_min), (x_max, y_max), (0, 0, 255), 1)
|
||||
cv2.imwrite(opath, image)
|
||||
|
||||
|
||||
def _highlight_bbox(img, bbox):
|
||||
x = bbox[0]
|
||||
w = bbox[1] - x
|
||||
y = bbox[2]
|
||||
h = bbox[3] - y
|
||||
sub_img = img[y:y + h, x:x + w]
|
||||
colored_rect = np.zeros(sub_img.shape, dtype=np.uint8)
|
||||
colored_rect[:, :, 2] = 255
|
||||
colored_rect[:, :, 1] = 255
|
||||
res = cv2.addWeighted(sub_img, 0.5, colored_rect, 0.5, 1.0)
|
||||
img[y:y + h, x:x + w] = res
|
||||
|
||||
|
||||
def highlight_ans(source_img_path, output_img_path, ans_bbox):
|
||||
image = cv2.imread(source_img_path)
|
||||
for bbox in ans_bbox:
|
||||
_highlight_bbox(image, bbox)
|
||||
cv2.imwrite(output_img_path, image)
|
||||
|
||||
|
||||
def highlight_img(source_img_path, output_img_path):
|
||||
image = cv2.imread(source_img_path)
|
||||
height = image.shape[0]
|
||||
width = image.shape[1]
|
||||
bbox = [0, width - 1, 0, height - 1]
|
||||
_highlight_bbox(image, bbox)
|
||||
cv2.imwrite(output_img_path, image)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
res_path = "./data/decode_res.json"
|
||||
result = {}
|
||||
with open(res_path, "r", encoding="utf-8") as f:
|
||||
line = f.readline()
|
||||
result = json.loads(line.strip())
|
||||
|
||||
img_path = '../OCR_process/demo_pics/demo_{}.png'.format(result["img_id"])
|
||||
img_save_path = "../answer.png"
|
||||
highlight_ans(img_path, img_save_path, result['predict_bboxes'])
|
||||
print("extraction result has been saved to answer.png")
|
||||
287
applications/document_intelligence/doc_vqa/OCR_process/ocr_process.py
Executable file
287
applications/document_intelligence/doc_vqa/OCR_process/ocr_process.py
Executable file
@@ -0,0 +1,287 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import os
|
||||
import json
|
||||
from paddleocr import PaddleOCR
|
||||
import numpy as np
|
||||
import re
|
||||
import time
|
||||
import sys
|
||||
from multiprocessing import Process, Queue
|
||||
|
||||
from paddlenlp.transformers import LayoutXLMTokenizer
|
||||
|
||||
tokenizer = LayoutXLMTokenizer.from_pretrained("layoutxlm-base-uncased")
|
||||
|
||||
|
||||
def get_all_chars(tokenizer):
|
||||
all_chr = []
|
||||
for i in range(30000):
|
||||
tok_chr = tokenizer.tokenize(chr(i))
|
||||
tok_chr = [tc.replace("▁", "") for tc in tok_chr]
|
||||
while "" in tok_chr:
|
||||
tok_chr.remove("")
|
||||
tok_chr = ''.join(tok_chr)
|
||||
if len(tok_chr) != 1:
|
||||
all_chr.append(i)
|
||||
return all_chr
|
||||
|
||||
|
||||
def merge_bbox(tok_bboxes):
|
||||
min_gx = min([box[0] for box in tok_bboxes])
|
||||
max_gx = max([box[1] for box in tok_bboxes])
|
||||
min_gy = min([box[2] for box in tok_bboxes])
|
||||
max_gy = max([box[3] for box in tok_bboxes])
|
||||
height_g = max_gy - min_gy
|
||||
width_g = max_gx - min_gx
|
||||
height_m = 0
|
||||
width_m = 0
|
||||
for box in tok_bboxes:
|
||||
x_min, x_max, y_min, y_max = box
|
||||
height_m += y_max - y_min
|
||||
width_m += x_max - x_min
|
||||
height_m = height_m / len(tok_bboxes)
|
||||
if (height_g -
|
||||
height_m) < 0.5 * height_m and width_g - width_m < 0.1 * width_m:
|
||||
return False, [min_gx, max_gx, min_gy, max_gy]
|
||||
else:
|
||||
return True, tok_bboxes[0]
|
||||
|
||||
|
||||
def xlm_parse(ocr_res, tokenizer):
|
||||
|
||||
doc_tokens, doc_bboxes = [], []
|
||||
all_chr = get_all_chars(tokenizer)
|
||||
|
||||
try:
|
||||
new_tokens, new_token_boxes = [], []
|
||||
for item in ocr_res:
|
||||
new_tokens.extend(item["tokens"])
|
||||
new_token_boxes.extend(item["token_box"])
|
||||
|
||||
# get layoutxlm tokenizer results and get the final results
|
||||
temp_span_text = ''.join(new_tokens)
|
||||
temp_span_bbox = new_token_boxes
|
||||
span_text = ""
|
||||
span_bbox = []
|
||||
# drop blank space
|
||||
for text, bbox in zip(temp_span_text, temp_span_bbox):
|
||||
if text == " ":
|
||||
continue
|
||||
else:
|
||||
span_text += text
|
||||
span_bbox += [bbox]
|
||||
|
||||
# span_tokens starts with "_"
|
||||
span_tokens = tokenizer.tokenize(span_text)
|
||||
span_tokens[0] = span_tokens[0].replace("▁", "")
|
||||
while "" in span_tokens:
|
||||
span_tokens.remove("")
|
||||
|
||||
doc_bboxes = []
|
||||
i = 0
|
||||
for tid, tok in enumerate(span_tokens):
|
||||
tok = tok.replace("▁", "")
|
||||
if tok == "":
|
||||
doc_bboxes.append(span_bbox[i])
|
||||
continue
|
||||
if tok == "<unk>":
|
||||
if tid + 1 == len(span_tokens):
|
||||
tok_len = 1
|
||||
else:
|
||||
if span_tokens[tid + 1] == "<unk>":
|
||||
tok_len = 1
|
||||
else:
|
||||
for j in range(i, len(span_text)):
|
||||
if span_text[j].lower() == span_tokens[tid + 1][0]:
|
||||
break
|
||||
tok_len = j - i
|
||||
elif ord(span_text[i]) in all_chr:
|
||||
if tid + 1 == len(span_tokens):
|
||||
tok_len = 1
|
||||
elif "°" in tok and "C" in span_tokens[tid + 1]:
|
||||
tok_len = len(tok) - 1
|
||||
if tok_len == 0:
|
||||
doc_bboxes.append(span_bbox[i])
|
||||
continue
|
||||
elif span_text[i] == "ⅱ":
|
||||
if tok == "ii":
|
||||
if span_text[i + 1] != "i":
|
||||
tok_len = len(tok) - 1
|
||||
else:
|
||||
tok_len = len(tok)
|
||||
elif tok == "i":
|
||||
tok_len = len(tok) - 1
|
||||
if tok_len == 0:
|
||||
doc_bboxes.append(span_bbox[i])
|
||||
continue
|
||||
elif "m" in tok and "2" == span_tokens[tid + 1][0]:
|
||||
tok_len = len(tok) - 1
|
||||
if tok_len == 0:
|
||||
doc_bboxes.append(span_bbox[i])
|
||||
continue
|
||||
elif ord(span_text[i + 1]) in all_chr:
|
||||
tok_len = 1
|
||||
else:
|
||||
for j in range(i, len(span_text)):
|
||||
if span_text[j].lower() == span_tokens[tid + 1][0]:
|
||||
break
|
||||
if span_text[j].lower() == "," and span_tokens[
|
||||
tid + 1][0] == ",":
|
||||
break
|
||||
if span_text[j].lower() == ";" and span_tokens[
|
||||
tid + 1][0] == ";":
|
||||
break
|
||||
if span_text[j].lower() == ")" and span_tokens[
|
||||
tid + 1][0] == ")":
|
||||
break
|
||||
if span_text[j].lower() == "(" and span_tokens[
|
||||
tid + 1][0] == "(":
|
||||
break
|
||||
if span_text[j].lower() == "¥" and span_tokens[
|
||||
tid + 1][0] == "¥":
|
||||
break
|
||||
|
||||
tok_len = j - i
|
||||
|
||||
else:
|
||||
if "<EFBFBD>" == span_text[i]:
|
||||
tok_len = len(tok) + 1
|
||||
elif tok == "......" and "…" in span_text[i:i + 6]:
|
||||
tok_len = len(tok) - 2
|
||||
elif "ⅱ" in span_text[i + len(tok) - 1]:
|
||||
if tok == "i":
|
||||
tok_len = 1
|
||||
else:
|
||||
tok_len = len(tok) - 1
|
||||
elif "°" in tok and "C" in span_tokens[tid + 1]:
|
||||
tok_len = len(tok) - 1
|
||||
else:
|
||||
tok_len = len(tok)
|
||||
|
||||
assert i + tok_len <= len(span_bbox)
|
||||
tok_bboxes = span_bbox[i:i + tok_len]
|
||||
_, merged_bbox = merge_bbox(tok_bboxes)
|
||||
|
||||
doc_bboxes.append(merged_bbox)
|
||||
i = i + tok_len
|
||||
except:
|
||||
print('Error')
|
||||
span_tokens = ['▁'] * 512
|
||||
doc_bboxes = [[0, 0, 0, 0]] * 512
|
||||
|
||||
return span_tokens, doc_bboxes
|
||||
|
||||
|
||||
def tokenize_ocr_res(ocr_reses):
|
||||
'''
|
||||
input:
|
||||
ocr_res: the ocr result of the image
|
||||
return:
|
||||
new_reses: {
|
||||
pid: {
|
||||
"text": all text in each ocr_res,
|
||||
"bounding_box": the bounding box of the ocr_res,
|
||||
"tokens": all chars in ocr_res,
|
||||
"token_box: bounding box of each chars in ocr_res
|
||||
}
|
||||
}
|
||||
'''
|
||||
new_reses = []
|
||||
for img_name, ocr_res in ocr_reses:
|
||||
new_res = []
|
||||
for para in ocr_res:
|
||||
text = para["text"]
|
||||
text_box = para["bbox"]
|
||||
x_min, y_min = [int(min(idx)) for idx in zip(*text_box)]
|
||||
x_max, y_max = [int(max(idx)) for idx in zip(*text_box)]
|
||||
text_chars = list(text.lower())
|
||||
char_num = 0
|
||||
for char in text_chars:
|
||||
if re.match("[^\x00-\xff]", char):
|
||||
char_num += 2
|
||||
else:
|
||||
char_num += 1
|
||||
width = x_max - x_min
|
||||
shift = x_min
|
||||
new_token_boxes, new_tokens = [], []
|
||||
for char in text_chars:
|
||||
if re.match("[^\x00-\xff]", char):
|
||||
tok_x_max = shift + width / char_num * 2
|
||||
else:
|
||||
tok_x_max = shift + width / char_num * 1
|
||||
tok_x_min = shift
|
||||
tok_y_min = y_min
|
||||
tok_y_max = y_max
|
||||
|
||||
shift = tok_x_max
|
||||
new_token_boxes.append(
|
||||
[round(tok_x_min),
|
||||
round(tok_x_max), tok_y_min, tok_y_max])
|
||||
new_tokens.append(char)
|
||||
new_res.append({
|
||||
"text": para["text"],
|
||||
"bounding_box": para["bbox"],
|
||||
"tokens": new_tokens,
|
||||
"token_box": new_token_boxes
|
||||
})
|
||||
new_reses.append((img_name, new_res))
|
||||
return new_reses
|
||||
|
||||
|
||||
def process_input(ocr_reses, tokenizer, save_ocr_path):
|
||||
ocr_reses = tokenize_ocr_res(ocr_reses)
|
||||
|
||||
examples = []
|
||||
for img_name, ocr_res in ocr_reses:
|
||||
doc_tokens, doc_bboxes = xlm_parse(ocr_res, tokenizer)
|
||||
doc_tokens.insert(0, '▁')
|
||||
doc_bboxes.insert(0, doc_bboxes[0])
|
||||
example = {
|
||||
"img_name": img_name,
|
||||
"document": doc_tokens,
|
||||
"document_bbox": doc_bboxes
|
||||
}
|
||||
examples.append(example)
|
||||
|
||||
with open(save_ocr_path, 'w', encoding='utf8') as f:
|
||||
for example in examples:
|
||||
json.dump(example, f, ensure_ascii=False)
|
||||
f.write('\n')
|
||||
|
||||
print(f"ocr parsing results has been save to: {save_ocr_path}")
|
||||
|
||||
|
||||
def ocr_preprocess(img_dir):
|
||||
ocr = PaddleOCR(use_angle_cls=True, lang="ch", use_gpu=True)
|
||||
ocr_reses = []
|
||||
img_names = sorted(os.listdir(img_dir),
|
||||
key=lambda x: int(x.split("_")[1].split(".")[0]))
|
||||
for img_name in img_names:
|
||||
img_path = os.path.join(img_dir, img_name)
|
||||
parsing_res = ocr.ocr(img_path, cls=True)
|
||||
ocr_res = []
|
||||
for para in parsing_res:
|
||||
ocr_res.append({"text": para[1][0], "bbox": para[0]})
|
||||
ocr_reses.append((img_name, ocr_res))
|
||||
|
||||
return ocr_reses
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
img_dir = "./demo_pics"
|
||||
save_path = "./demo_ocr_res.json"
|
||||
ocr_results = ocr_preprocess(img_dir)
|
||||
process_input(ocr_results, tokenizer, save_path)
|
||||
131
applications/document_intelligence/doc_vqa/README.md
Normal file
131
applications/document_intelligence/doc_vqa/README.md
Normal file
@@ -0,0 +1,131 @@
|
||||
# 汽车说明书跨模态智能问答
|
||||
|
||||
## 1. 项目说明
|
||||
|
||||
**跨模态文档问答** 是跨模态的文档抽取任务,要求文档智能模型在文档中抽取能够回答文档相关问题的答案,需要模型在抽取和理解文档中文本信息的同时,还能充分利用文档的布局、字体、颜色等视觉信息,这比单一模态的信息抽取任务更具挑战性。
|
||||
|
||||
这种基于跨模态文档阅读理解技术的智能问答能力,可以深度解析非结构化文档中排版复杂的图文/图表内容,直接定位问题答案。
|
||||
|
||||
本项目将基于跨模态文档问答技术实现**汽车说明书问答系统**,该系统能够对用户提出的问题,自动从汽车说明书中寻找答案并进行回答。
|
||||
|
||||
如下图所示, 用户提出问题:"如何更换前风窗玻璃的刮水片",跨模态文档问答引擎将从库中寻找相关的文档,然后通过跨模态阅读理解模型抽取出相应的答案,并进行了高亮展示。
|
||||
|
||||
<center><img width="883" alt="image" src="https://user-images.githubusercontent.com/35913314/169781111-0734729d-3c7b-400d-8e92-e56548bb7dc5.png"></center>
|
||||
|
||||
通过使用汽车说明书问答系统,能够极大地解决传统汽车售后的压力:
|
||||
- 用户:用户没有耐心查阅说明书,打客服电话需要等待
|
||||
- 售后客服:需要配置大量客服人员,且客服专业知识培训周期长
|
||||
- 构建问题库:需要投入大量人力整理常见问题库,并且固定的问题库难以覆盖灵活多变的提问
|
||||
|
||||
对于用户来说,汽车说明书问答系统能够支持通过车机助手/APP/小程序为用户提供即问即答的的功能。对于常见问题,用户不再需要查阅说明书,也无需打客服电话,从而缓解了人工客服的压力。
|
||||
|
||||
对于客服来讲,汽车说明书问答系统帮助客服人员快速定位答案,高效查阅文档,提高客服的专业水平,同时也能够缩短客服的培训周期。
|
||||
|
||||
## 2. 安装说明
|
||||
|
||||
#### 环境要求
|
||||
|
||||
- paddlepaddle >= 2.2.0
|
||||
- paddlenlp >= 2.3.1
|
||||
- paddleocr >= 2.5
|
||||
|
||||
安装相关问题可参考[PaddlePaddle](https://www.paddlepaddle.org.cn/install/quick?docurl=/documentation/docs/zh/install/pip/linux-pip.html)和[PaddleNLP](https://paddlenlp.readthedocs.io/zh/latest/get_started/installation.html)文档。
|
||||
|
||||
|
||||
## 3. 整体流程
|
||||
|
||||
汽车说明书问答系统针对用户提出的汽车使用相关问题,智能化地在汽车说明书中找出对应答案,并返回给用户。本项目提供的汽车说明书问答系统的使用流程如下图所示。本项目提供的汽车说明书问答系统主要包括 3 个模块:OCR处理模块、排序模块和跨模态阅读理解模块。
|
||||
|
||||
在使用汽车说明书问答模型回答问题之前,需要先使用PaddleOCR对离线提供的汽车说明书文档进解析,并将解析结果保存下来,以备后续排序模块使用。
|
||||
|
||||
对于用户提问的问题,首先会被传入排序模块,排序模块会针对该问题对解析的文档进行排序打分,其结果将会被传入跨模态阅读理解模块。阅读理解模块将从分数最高的说明书文档中,抽取用户问题的答案,并返回给用户。
|
||||
|
||||
<center><img width="864" alt="image" src="https://user-images.githubusercontent.com/35913314/170222662-c438ff2a-a1df-44e5-8a83-f14dc0814b9d.png"></center>
|
||||
|
||||
下面将具体介绍各个模块的功能。
|
||||
|
||||
## 4. OCR处理模块
|
||||
|
||||
本项目提供了包含10张图片的汽车说明书,为方便后续处理,首先需要通过 PaddleOCR 对汽车说明书进行识别,记录汽车说明书上的文字和文字布局信息, 以方便后续使用计算机视觉和自然语言处理方面的技术进行问答任务。
|
||||
|
||||
本项目提供的汽车说明书图片可点击[这里](https://paddlenlp.bj.bcebos.com/images/applications/automobile.tar.gz)进行下载,下载后解压放至 `./OCR_process/demo_pics` 目录下,然后通过如下命令,使用 PaddleOCR 对图片进行解析。
|
||||
|
||||
```shell
|
||||
cd OCR_process/
|
||||
python3 ocr_process.py
|
||||
cd ..
|
||||
```
|
||||
|
||||
解析后的结果存放至 `./OCR_process/demo_ocr_res.json` 中。
|
||||
|
||||
## 5. 排序模块
|
||||
对于用户提出的问题,如果从所有的汽车说明书图片中去寻找答案会比较耗时且耗费资源。因此这里使用了一个基于[RocketQA](https://arxiv.org/pdf/2010.08191.pdf)的排序模块,该模块将根据用户提出的问题对汽车说明书的不同图片进行打分排序,这样便可以获取和问题最相关的图片,并使用跨模态阅读理解模块在该问题上进行抽取答案。
|
||||
|
||||
本项目提供了140条汽车说明书相关的训练样本,用于排序模型的训练, 同时也提供了一个基于RocketQA的预先训练好的基线模型 base_model。 本模块可以使用 base_model 在汽车说明书训练样本上进一步微调。
|
||||
|
||||
其中,汽车说明书的训练集可点击[这里](https://paddlenlp.bj.bcebos.com/data/automobile_rerank_train.tsv) 进行下载,下载后将其重命名为 `train.tsv` ,存放至 `./Rerank/data/` 目录下。
|
||||
|
||||
同时,base_model 是 [Dureader retrieval](https://arxiv.org/abs/2203.10232) 数据集训练的排序模型, 可点击[这里](https://paddlenlp.bj.bcebos.com/models/base_ranker.tar.gz) 进行下载,解压后可获得包含模型的目录 `base_model`,将其放至 `./Rerank/checkpoints` 目录下。
|
||||
|
||||
可使用如下代码进行训练:
|
||||
|
||||
```shell
|
||||
cd Rerank
|
||||
bash run_train.sh ./data/train.tsv ./checkpoints/base_model 50 1
|
||||
cd ..
|
||||
```
|
||||
其中,参数依次为训练数据地址,base_model 地址,训练轮次,节点数。
|
||||
|
||||
在模型训练完成后,可将模型重命名为 `ranker` 存放至 `./checkpoints/` 目录下,接下来便可以使用如下命令,根据给定的汽车说明书相关问题,对汽车说明书的图片进行打分。代码如下:
|
||||
|
||||
```shell
|
||||
cd Rerank
|
||||
bash run_test.sh 后备箱怎么开
|
||||
cd ..
|
||||
```
|
||||
|
||||
其中,后一项为用户问题,命令执行完成后,分数文件将会保存至 `./Rerank/data/demo.score` 中。
|
||||
|
||||
|
||||
## 6. 跨模态阅读理解模块
|
||||
本项目首先获取排序模块输出的结果中评分最高的图片,然后将会使用跨模态的语言模型 LayoutXLM 从该图片中去抽取用户提问的答案。在获取答案后,将会对答案在该图片中进行高亮显示并返回用户。
|
||||
|
||||
本项目提供了28条汽车说明书相关的训练样本,用于跨模态阅读理解模型的训练, 同时也提供了一个预先训练好的基线模型 base_model。 本模块可以使用 base_model 在汽车说明书训练样本上进一步微调,增强模型对汽车说明书领域的理解。
|
||||
|
||||
其中,汽车说明书的阅读理解训练集可点击[这里](https://paddlenlp.bj.bcebos.com/data/automobile_mrc_train.json) 进行下载,下载后将其重命名为 `train.json`,存放至 `./Extraction/data/` 目录下。
|
||||
|
||||
同时,base_model 是 [Dureader VIS](https://aclanthology.org/2022.findings-acl.105.pdf) 数据集训练的跨模态阅读理解模型, 可点击[这里](https://paddlenlp.bj.bcebos.com/models/base_mrc.tar.gz) 进行下载,解压后可获得包含模型的目录 `base_model`,将其放至 `./Extraction/checkpoints` 目录下。
|
||||
|
||||
可使用如下代码进行训练:
|
||||
|
||||
```shell
|
||||
cd Extraction
|
||||
bash run_train.sh
|
||||
cd ..
|
||||
```
|
||||
|
||||
在模型训练完成后,可将模型重命名为 `layoutxlm` 存放至 `./checkpoints/` 目录下,接下来便可以使用如下命令,根据给定的汽车说明书相关问题,从得分最高的汽车说明书图片中抽取答案。代码如下:
|
||||
|
||||
```shell
|
||||
cd Extraction
|
||||
bash run_test.sh 后备箱怎么开
|
||||
cd ..
|
||||
```
|
||||
|
||||
其中,后一项为用户问题,命令执行完成后,最终结果将会保存至 `./answer.png` 中。
|
||||
|
||||
## 7. 全流程预测
|
||||
本项目提供了全流程预测的功能,可通过如下命令进行一键式预测:
|
||||
|
||||
```shell
|
||||
bash run_test.sh 后备箱怎么开
|
||||
```
|
||||
|
||||
其中,后一项参数为用户问题,最终结果将会保存至 `./answer.png` 中。
|
||||
|
||||
**备注**:在运行命令前,请确保已使用第4节介绍的命令对原始汽车说明书图片完成了文档解析。
|
||||
|
||||
|
||||
下图展示了用户提问的三个问题:"后备箱怎么开","钥匙怎么充电" 和 "NFC解锁注意事项", 可以看到,本项目的汽车说明书问答系统能够精准地找到答案并进行高亮显示。
|
||||
|
||||
<center><img src="https://user-images.githubusercontent.com/35913314/169012902-1a42bd14-976f-4da8-b5b5-d8e7352b68df.png"/></center>
|
||||
@@ -0,0 +1,33 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import json
|
||||
|
||||
question = sys.argv[1]
|
||||
|
||||
with open('../OCR_process/demo_ocr_res.json', 'r', encoding='utf8') as f:
|
||||
paras = []
|
||||
for line in f:
|
||||
line = json.loads(line.strip())
|
||||
document = line['document']
|
||||
para = []
|
||||
for token in document:
|
||||
token = token.replace('▁', '')
|
||||
para.append(token)
|
||||
paras.append(''.join(para))
|
||||
|
||||
with open('./data/demo.tsv', 'w', encoding='utf8') as f:
|
||||
for para in paras:
|
||||
f.write('{}\t\t{}\t0\n'.format(question, para))
|
||||
@@ -0,0 +1,12 @@
|
||||
{
|
||||
"attention_probs_dropout_prob": 0.1,
|
||||
"hidden_act": "relu",
|
||||
"hidden_dropout_prob": 0.1,
|
||||
"hidden_size": 768,
|
||||
"initializer_range": 0.02,
|
||||
"max_position_embeddings": 513,
|
||||
"num_attention_heads": 12,
|
||||
"num_hidden_layers": 12,
|
||||
"type_vocab_size": 2,
|
||||
"vocab_size": 18000
|
||||
}
|
||||
17964
applications/document_intelligence/doc_vqa/Rerank/config/ernie_base_1.0_CN/vocab.txt
Executable file
17964
applications/document_intelligence/doc_vqa/Rerank/config/ernie_base_1.0_CN/vocab.txt
Executable file
File diff suppressed because it is too large
Load Diff
45
applications/document_intelligence/doc_vqa/Rerank/run_test.sh
Executable file
45
applications/document_intelligence/doc_vqa/Rerank/run_test.sh
Executable file
@@ -0,0 +1,45 @@
|
||||
#!/bin/bash
|
||||
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
QUESTION=$1
|
||||
|
||||
if [ ! -d output ]; then
|
||||
mkdir output
|
||||
fi
|
||||
if [ ! -d log ]; then
|
||||
mkdir log
|
||||
fi
|
||||
|
||||
python3 change_to_rerank.py ${QUESTION}
|
||||
|
||||
python3 -u ./src/train_ce.py \
|
||||
--use_cuda true \
|
||||
--verbose true \
|
||||
--do_train false \
|
||||
--do_val false \
|
||||
--do_test true \
|
||||
--batch_size 128 \
|
||||
--init_checkpoint "./checkpoints/ranker" \
|
||||
--test_set "./data/demo.tsv" \
|
||||
--test_save "data/demo.score" \
|
||||
--max_seq_len 384 \
|
||||
--for_cn true \
|
||||
--vocab_path "config/ernie_base_1.0_CN/vocab.txt" \
|
||||
--ernie_config_path "config/ernie_base_1.0_CN/ernie_config.json"
|
||||
1>>log/train.log 2>&1
|
||||
|
||||
72
applications/document_intelligence/doc_vqa/Rerank/run_train.sh
Executable file
72
applications/document_intelligence/doc_vqa/Rerank/run_train.sh
Executable file
@@ -0,0 +1,72 @@
|
||||
#!/bin/bash
|
||||
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
if [ $# != 4 ];then
|
||||
echo "USAGE: sh run_train.sh \$TRAIN_SET \$MODEL_PATH \$epoch \$nodes_count"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
TRAIN_SET=$1
|
||||
MODEL_PATH=$2
|
||||
epoch=$3
|
||||
node=$4
|
||||
|
||||
CHECKPOINT_PATH=output
|
||||
if [ ! -d output ]; then
|
||||
mkdir output
|
||||
fi
|
||||
if [ ! -d log ]; then
|
||||
mkdir log
|
||||
fi
|
||||
|
||||
lr=1e-5
|
||||
batch_size=32
|
||||
train_exampls=`cat $TRAIN_SET | wc -l`
|
||||
save_steps=$[$train_exampls/$batch_size/$node]
|
||||
data_size=$[$save_steps*$batch_size*$node]
|
||||
new_save_steps=$[$save_steps*$epoch/2]
|
||||
|
||||
python3 -m paddle.distributed.launch \
|
||||
--log_dir log \
|
||||
./src/train_ce.py \
|
||||
--use_cuda true \
|
||||
--verbose true \
|
||||
--do_train true \
|
||||
--do_val false \
|
||||
--do_test false \
|
||||
--use_mix_precision false \
|
||||
--train_data_size ${data_size} \
|
||||
--batch_size ${batch_size} \
|
||||
--init_pretraining_params ${MODEL_PATH} \
|
||||
--train_set ${TRAIN_SET} \
|
||||
--save_steps ${new_save_steps} \
|
||||
--validation_steps ${new_save_steps} \
|
||||
--checkpoints ${CHECKPOINT_PATH} \
|
||||
--weight_decay 0.01 \
|
||||
--warmup_proportion 0.0 \
|
||||
--epoch $epoch \
|
||||
--max_seq_len 384 \
|
||||
--for_cn true \
|
||||
--vocab_path config/ernie_base_1.0_CN/vocab.txt \
|
||||
--ernie_config_path config/ernie_base_1.0_CN/ernie_config.json \
|
||||
--learning_rate ${lr} \
|
||||
--skip_steps 10 \
|
||||
--num_iteration_per_drop_scope 1 \
|
||||
--num_labels 2 \
|
||||
--random_seed 1
|
||||
|
||||
77
applications/document_intelligence/doc_vqa/Rerank/src/batching.py
Executable file
77
applications/document_intelligence/doc_vqa/Rerank/src/batching.py
Executable file
@@ -0,0 +1,77 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""Mask, padding and batching."""
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
|
||||
import numpy as np
|
||||
from six.moves import xrange
|
||||
|
||||
|
||||
def pad_batch_data(insts,
|
||||
pad_idx=0,
|
||||
return_pos=False,
|
||||
return_input_mask=False,
|
||||
return_max_len=False,
|
||||
return_num_token=False,
|
||||
return_seq_lens=False):
|
||||
"""
|
||||
Pad the instances to the max sequence length in batch, and generate the
|
||||
corresponding position data and attention bias.
|
||||
"""
|
||||
return_list = []
|
||||
max_len = max(len(inst) for inst in insts)
|
||||
# Any token included in dict can be used to pad, since the paddings' loss
|
||||
# will be masked out by weights and make no effect on parameter gradients.
|
||||
|
||||
inst_data = np.array(
|
||||
[inst + list([pad_idx] * (max_len - len(inst))) for inst in insts])
|
||||
return_list += [inst_data.astype("int64").reshape([-1, max_len, 1])]
|
||||
|
||||
# position data
|
||||
if return_pos:
|
||||
inst_pos = np.array([
|
||||
list(range(0, len(inst))) + [pad_idx] * (max_len - len(inst))
|
||||
for inst in insts
|
||||
])
|
||||
|
||||
return_list += [inst_pos.astype("int64").reshape([-1, max_len, 1])]
|
||||
|
||||
if return_input_mask:
|
||||
# This is used to avoid attention on paddings.
|
||||
input_mask_data = np.array(
|
||||
[[1] * len(inst) + [0] * (max_len - len(inst)) for inst in insts])
|
||||
input_mask_data = np.expand_dims(input_mask_data, axis=-1)
|
||||
return_list += [input_mask_data.astype("float32")]
|
||||
|
||||
if return_max_len:
|
||||
return_list += [max_len]
|
||||
|
||||
if return_num_token:
|
||||
num_token = 0
|
||||
for inst in insts:
|
||||
num_token += len(inst)
|
||||
return_list += [num_token]
|
||||
|
||||
if return_seq_lens:
|
||||
seq_lens = np.array([len(inst) for inst in insts])
|
||||
return_list += [seq_lens.astype("int64").reshape([-1, 1])]
|
||||
|
||||
return return_list if len(return_list) > 1 else return_list[0]
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
pass
|
||||
336
applications/document_intelligence/doc_vqa/Rerank/src/cross_encoder.py
Executable file
336
applications/document_intelligence/doc_vqa/Rerank/src/cross_encoder.py
Executable file
@@ -0,0 +1,336 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""Model for classifier."""
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
from __future__ import absolute_import
|
||||
|
||||
import time
|
||||
import logging
|
||||
import numpy as np
|
||||
from six.moves import xrange
|
||||
from scipy.stats import pearsonr, spearmanr
|
||||
|
||||
import paddle.fluid as fluid
|
||||
|
||||
from model.ernie import ErnieModel
|
||||
|
||||
log = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def create_model(args,
|
||||
pyreader_name,
|
||||
ernie_config,
|
||||
is_prediction=False,
|
||||
task_name=""):
|
||||
pyreader = fluid.layers.py_reader(capacity=50,
|
||||
shapes=[[-1, args.max_seq_len, 1],
|
||||
[-1, args.max_seq_len, 1],
|
||||
[-1, args.max_seq_len, 1],
|
||||
[-1, args.max_seq_len, 1],
|
||||
[-1, args.max_seq_len, 1],
|
||||
[-1, 1], [-1, 1]],
|
||||
dtypes=[
|
||||
'int64', 'int64', 'int64', 'int64',
|
||||
'float32', 'int64', 'int64'
|
||||
],
|
||||
lod_levels=[0, 0, 0, 0, 0, 0, 0],
|
||||
name=task_name + "_" + pyreader_name,
|
||||
use_double_buffer=True)
|
||||
|
||||
(src_ids, sent_ids, pos_ids, task_ids, input_mask, labels,
|
||||
qids) = fluid.layers.read_file(pyreader)
|
||||
|
||||
def _model(is_noise=False):
|
||||
ernie = ErnieModel(src_ids=src_ids,
|
||||
position_ids=pos_ids,
|
||||
sentence_ids=sent_ids,
|
||||
task_ids=task_ids,
|
||||
input_mask=input_mask,
|
||||
config=ernie_config,
|
||||
is_noise=is_noise)
|
||||
|
||||
cls_feats = ernie.get_pooled_output()
|
||||
if not is_noise:
|
||||
cls_feats = fluid.layers.dropout(
|
||||
x=cls_feats,
|
||||
dropout_prob=0.1,
|
||||
dropout_implementation="upscale_in_train")
|
||||
logits = fluid.layers.fc(
|
||||
input=cls_feats,
|
||||
size=args.num_labels,
|
||||
param_attr=fluid.ParamAttr(
|
||||
name=task_name + "_cls_out_w",
|
||||
initializer=fluid.initializer.TruncatedNormal(scale=0.02)),
|
||||
bias_attr=fluid.ParamAttr(
|
||||
name=task_name + "_cls_out_b",
|
||||
initializer=fluid.initializer.Constant(0.)))
|
||||
"""
|
||||
if is_prediction:
|
||||
probs = fluid.layers.softmax(logits)
|
||||
feed_targets_name = [
|
||||
src_ids.name, sent_ids.name, pos_ids.name, input_mask.name
|
||||
]
|
||||
if ernie_version == "2.0":
|
||||
feed_targets_name += [task_ids.name]
|
||||
return pyreader, probs, feed_targets_name
|
||||
"""
|
||||
|
||||
num_seqs = fluid.layers.create_tensor(dtype='int64')
|
||||
## add focal loss
|
||||
ce_loss, probs = fluid.layers.softmax_with_cross_entropy(
|
||||
logits=logits, label=labels, return_softmax=True)
|
||||
loss = fluid.layers.mean(x=ce_loss)
|
||||
accuracy = fluid.layers.accuracy(input=probs,
|
||||
label=labels,
|
||||
total=num_seqs)
|
||||
graph_vars = {
|
||||
"loss": loss,
|
||||
"probs": probs,
|
||||
"accuracy": accuracy,
|
||||
"labels": labels,
|
||||
"num_seqs": num_seqs,
|
||||
"qids": qids
|
||||
}
|
||||
return graph_vars
|
||||
|
||||
if not is_prediction:
|
||||
graph_vars = _model(is_noise=True)
|
||||
old_loss = graph_vars["loss"]
|
||||
token_emb = fluid.default_main_program().global_block().var(
|
||||
"word_embedding")
|
||||
# print(token_emb)
|
||||
token_emb.stop_gradient = False
|
||||
token_gradient = fluid.gradients(old_loss, token_emb)[0]
|
||||
token_gradient.stop_gradient = False
|
||||
epsilon = 1e-8
|
||||
norm = (fluid.layers.sqrt(
|
||||
fluid.layers.reduce_sum(fluid.layers.square(token_gradient)) +
|
||||
epsilon))
|
||||
gp = (0.01 * token_gradient) / norm
|
||||
gp.stop_gradient = True
|
||||
fluid.layers.assign(token_emb + gp, token_emb)
|
||||
graph_vars = _model()
|
||||
fluid.layers.assign(token_emb - gp, token_emb)
|
||||
else:
|
||||
graph_vars = _model()
|
||||
|
||||
return pyreader, graph_vars
|
||||
|
||||
|
||||
def evaluate_mrr(preds):
|
||||
last_qid = None
|
||||
total_mrr = 0.0
|
||||
qnum = 0.0
|
||||
rank = 0.0
|
||||
correct = False
|
||||
for qid, score, label in preds:
|
||||
if qid != last_qid:
|
||||
rank = 0.0
|
||||
qnum += 1
|
||||
correct = False
|
||||
last_qid = qid
|
||||
|
||||
rank += 1
|
||||
if not correct and label != 0:
|
||||
total_mrr += 1.0 / rank
|
||||
correct = True
|
||||
|
||||
return total_mrr / qnum
|
||||
|
||||
|
||||
def evaluate(exe,
|
||||
test_program,
|
||||
test_pyreader,
|
||||
graph_vars,
|
||||
eval_phase,
|
||||
use_multi_gpu_test=False,
|
||||
metric='simple_accuracy'):
|
||||
train_fetch_list = [
|
||||
graph_vars["loss"].name, graph_vars["accuracy"].name,
|
||||
graph_vars["num_seqs"].name
|
||||
]
|
||||
|
||||
if eval_phase == "train":
|
||||
if "learning_rate" in graph_vars:
|
||||
train_fetch_list.append(graph_vars["learning_rate"].name)
|
||||
outputs = exe.run(fetch_list=train_fetch_list, program=test_program)
|
||||
ret = {"loss": np.mean(outputs[0]), "accuracy": np.mean(outputs[1])}
|
||||
if "learning_rate" in graph_vars:
|
||||
ret["learning_rate"] = float(outputs[3][0])
|
||||
return ret
|
||||
|
||||
test_pyreader.start()
|
||||
total_cost = 0.0
|
||||
total_acc = 0.0
|
||||
total_num_seqs = 0.0
|
||||
total_label_pos_num = 0.0
|
||||
total_pred_pos_num = 0.0
|
||||
total_correct_num = 0.0
|
||||
qids, labels, scores, preds = [], [], [], []
|
||||
time_begin = time.time()
|
||||
|
||||
fetch_list = [
|
||||
graph_vars["loss"].name, graph_vars["accuracy"].name,
|
||||
graph_vars["probs"].name, graph_vars["labels"].name,
|
||||
graph_vars["num_seqs"].name, graph_vars["qids"].name
|
||||
]
|
||||
while True:
|
||||
try:
|
||||
if use_multi_gpu_test:
|
||||
np_loss, np_acc, np_probs, np_labels, np_num_seqs, np_qids = exe.run(
|
||||
fetch_list=fetch_list)
|
||||
else:
|
||||
np_loss, np_acc, np_probs, np_labels, np_num_seqs, np_qids = exe.run(
|
||||
program=test_program, fetch_list=fetch_list)
|
||||
total_cost += np.sum(np_loss * np_num_seqs)
|
||||
total_acc += np.sum(np_acc * np_num_seqs)
|
||||
total_num_seqs += np.sum(np_num_seqs)
|
||||
labels.extend(np_labels.reshape((-1)).tolist())
|
||||
if np_qids is None:
|
||||
np_qids = np.array([])
|
||||
qids.extend(np_qids.reshape(-1).tolist())
|
||||
scores.extend(np_probs[:, 1].reshape(-1).tolist())
|
||||
np_preds = np.argmax(np_probs, axis=1).astype(np.float32)
|
||||
preds.extend(np_preds)
|
||||
total_label_pos_num += np.sum(np_labels)
|
||||
total_pred_pos_num += np.sum(np_preds)
|
||||
total_correct_num += np.sum(np.dot(np_preds, np_labels))
|
||||
except fluid.core.EOFException:
|
||||
test_pyreader.reset()
|
||||
break
|
||||
time_end = time.time()
|
||||
cost = total_cost / total_num_seqs
|
||||
elapsed_time = time_end - time_begin
|
||||
|
||||
evaluate_info = ""
|
||||
if metric == 'acc_and_f1':
|
||||
ret = acc_and_f1(preds, labels)
|
||||
evaluate_info = "[%s evaluation] ave loss: %f, ave_acc: %f, f1: %f, data_num: %d, elapsed time: %f s" \
|
||||
% (eval_phase, cost, ret['acc'], ret['f1'], total_num_seqs, elapsed_time)
|
||||
elif metric == 'matthews_corrcoef':
|
||||
ret = matthews_corrcoef(preds, labels)
|
||||
evaluate_info = "[%s evaluation] ave loss: %f, matthews_corrcoef: %f, data_num: %d, elapsed time: %f s" \
|
||||
% (eval_phase, cost, ret, total_num_seqs, elapsed_time)
|
||||
elif metric == 'pearson_and_spearman':
|
||||
ret = pearson_and_spearman(scores, labels)
|
||||
evaluate_info = "[%s evaluation] ave loss: %f, pearson:%f, spearman:%f, corr:%f, data_num: %d, elapsed time: %f s" \
|
||||
% (eval_phase, cost, ret['pearson'], ret['spearman'], ret['corr'], total_num_seqs, elapsed_time)
|
||||
elif metric == 'simple_accuracy':
|
||||
ret = simple_accuracy(preds, labels)
|
||||
evaluate_info = "[%s evaluation] ave loss: %f, acc:%f, data_num: %d, elapsed time: %f s" \
|
||||
% (eval_phase, cost, ret, total_num_seqs, elapsed_time)
|
||||
elif metric == "acc_and_f1_and_mrr":
|
||||
ret_a = acc_and_f1(preds, labels)
|
||||
preds = sorted(zip(qids, scores, labels),
|
||||
key=lambda elem: (elem[0], -elem[1]))
|
||||
ret_b = evaluate_mrr(preds)
|
||||
evaluate_info = "[%s evaluation] ave loss: %f, acc: %f, f1: %f, mrr: %f, data_num: %d, elapsed time: %f s" \
|
||||
% (eval_phase, cost, ret_a['acc'], ret_a['f1'], ret_b, total_num_seqs, elapsed_time)
|
||||
else:
|
||||
raise ValueError('unsupported metric {}'.format(metric))
|
||||
return evaluate_info
|
||||
|
||||
|
||||
def matthews_corrcoef(preds, labels):
|
||||
preds = np.array(preds)
|
||||
labels = np.array(labels)
|
||||
tp = np.sum((labels == 1) & (preds == 1))
|
||||
tn = np.sum((labels == 0) & (preds == 0))
|
||||
fp = np.sum((labels == 0) & (preds == 1))
|
||||
fn = np.sum((labels == 1) & (preds == 0))
|
||||
|
||||
mcc = ((tp * tn) - (fp * fn)) / np.sqrt(
|
||||
(tp + fp) * (tp + fn) * (tn + fp) * (tn + fn))
|
||||
return mcc
|
||||
|
||||
|
||||
def f1_score(preds, labels):
|
||||
preds = np.array(preds)
|
||||
labels = np.array(labels)
|
||||
|
||||
tp = np.sum((labels == 1) & (preds == 1))
|
||||
tn = np.sum((labels == 0) & (preds == 0))
|
||||
fp = np.sum((labels == 0) & (preds == 1))
|
||||
fn = np.sum((labels == 1) & (preds == 0))
|
||||
p = tp / (tp + fp)
|
||||
r = tp / (tp + fn)
|
||||
f1 = (2 * p * r) / (p + r + 1e-8)
|
||||
return f1
|
||||
|
||||
|
||||
def pearson_and_spearman(preds, labels):
|
||||
preds = np.array(preds)
|
||||
labels = np.array(labels)
|
||||
|
||||
pearson_corr = pearsonr(preds, labels)[0]
|
||||
spearman_corr = spearmanr(preds, labels)[0]
|
||||
return {
|
||||
"pearson": pearson_corr,
|
||||
"spearmanr": spearman_corr,
|
||||
"corr": (pearson_corr + spearman_corr) / 2,
|
||||
}
|
||||
|
||||
|
||||
def acc_and_f1(preds, labels):
|
||||
preds = np.array(preds)
|
||||
labels = np.array(labels)
|
||||
|
||||
acc = simple_accuracy(preds, labels)
|
||||
f1 = f1_score(preds, labels)
|
||||
return {
|
||||
"acc": acc,
|
||||
"f1": f1,
|
||||
"acc_and_f1": (acc + f1) / 2,
|
||||
}
|
||||
|
||||
|
||||
def simple_accuracy(preds, labels):
|
||||
preds = np.array(preds)
|
||||
labels = np.array(labels)
|
||||
return (preds == labels).mean()
|
||||
|
||||
|
||||
def predict(exe, test_program, test_pyreader, graph_vars, dev_count=1):
|
||||
test_pyreader.start()
|
||||
qids, scores, probs = [], [], []
|
||||
preds = []
|
||||
|
||||
fetch_list = [graph_vars["probs"].name, graph_vars["qids"].name]
|
||||
|
||||
while True:
|
||||
try:
|
||||
if dev_count == 1:
|
||||
np_probs, np_qids = exe.run(program=test_program,
|
||||
fetch_list=fetch_list)
|
||||
else:
|
||||
np_probs, np_qids = exe.run(fetch_list=fetch_list)
|
||||
|
||||
if np_qids is None:
|
||||
np_qids = np.array([])
|
||||
qids.extend(np_qids.reshape(-1).tolist())
|
||||
np_preds = np.argmax(np_probs, axis=1).astype(np.float32)
|
||||
preds.extend(np_preds)
|
||||
probs.append(np_probs)
|
||||
|
||||
except fluid.core.EOFException:
|
||||
test_pyreader.reset()
|
||||
break
|
||||
|
||||
probs = np.concatenate(probs, axis=0).reshape([len(preds), -1])
|
||||
|
||||
return qids, preds, probs
|
||||
117
applications/document_intelligence/doc_vqa/Rerank/src/finetune_args.py
Executable file
117
applications/document_intelligence/doc_vqa/Rerank/src/finetune_args.py
Executable file
@@ -0,0 +1,117 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
from __future__ import absolute_import
|
||||
|
||||
import os
|
||||
import time
|
||||
import argparse
|
||||
|
||||
from utils.args import ArgumentGroup
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser(__doc__)
|
||||
model_g = ArgumentGroup(parser, "model", "model configuration and paths.")
|
||||
model_g.add_arg("ernie_config_path", str, None, "Path to the json file for ernie model config.")
|
||||
model_g.add_arg("init_checkpoint", str, None, "Init checkpoint to resume training from.")
|
||||
model_g.add_arg("init_pretraining_params", str, None,
|
||||
"Init pre-training params which preforms fine-tuning from. If the "
|
||||
"arg 'init_checkpoint' has been set, this argument wouldn't be valid.")
|
||||
model_g.add_arg("checkpoints", str, "checkpoints", "Path to save checkpoints.")
|
||||
|
||||
model_g.add_arg("is_classify", bool, True, "is_classify")
|
||||
model_g.add_arg("is_regression", bool, False, "is_regression")
|
||||
model_g.add_arg("task_id", int, 0, "task id")
|
||||
|
||||
train_g = ArgumentGroup(parser, "training", "training options.")
|
||||
train_g.add_arg("epoch", int, 3, "Number of epoches for fine-tuning.")
|
||||
train_g.add_arg("learning_rate", float, 5e-5, "Learning rate used to train with warmup.")
|
||||
train_g.add_arg("lr_scheduler", str, "linear_warmup_decay",
|
||||
"scheduler of learning rate.", choices=['linear_warmup_decay', 'noam_decay'])
|
||||
train_g.add_arg("weight_decay", float, 0.01, "Weight decay rate for L2 regularizer.")
|
||||
train_g.add_arg("warmup_proportion", float, 0.1,
|
||||
"Proportion of training steps to perform linear learning rate warmup for.")
|
||||
train_g.add_arg("save_steps", int, 10000, "The steps interval to save checkpoints.")
|
||||
train_g.add_arg("validation_steps", int, 1000, "The steps interval to evaluate model performance.")
|
||||
train_g.add_arg("use_recompute", bool, False, "Whether to use recompute optimizer for training.")
|
||||
train_g.add_arg("use_mix_precision", bool, False, "Whether to use mix-precision optimizer for training.")
|
||||
train_g.add_arg("use_cross_batch", bool, False, "Whether to use cross-batch for training.")
|
||||
train_g.add_arg("use_lamb", bool, False, "Whether to use LambOptimizer for training.")
|
||||
train_g.add_arg("use_dynamic_loss_scaling", bool, True, "Whether to use dynamic loss scaling.")
|
||||
|
||||
train_g.add_arg("test_save", str, "./checkpoints/test_result", "test_save")
|
||||
train_g.add_arg("metric", str, "simple_accuracy", "metric")
|
||||
train_g.add_arg("incr_every_n_steps", int, 100, "Increases loss scaling every n consecutive.")
|
||||
train_g.add_arg("decr_every_n_nan_or_inf", int, 2,
|
||||
"Decreases loss scaling every n accumulated steps with nan or inf gradients.")
|
||||
train_g.add_arg("incr_ratio", float, 2.0,
|
||||
"The multiplier to use when increasing the loss scaling.")
|
||||
train_g.add_arg("decr_ratio", float, 0.8,
|
||||
"The less-than-one-multiplier to use when decreasing.")
|
||||
|
||||
|
||||
|
||||
log_g = ArgumentGroup(parser, "logging", "logging related.")
|
||||
log_g.add_arg("skip_steps", int, 10, "The steps interval to print loss.")
|
||||
log_g.add_arg("verbose", bool, False, "Whether to output verbose log.")
|
||||
|
||||
data_g = ArgumentGroup(parser, "data", "Data paths, vocab paths and data processing options")
|
||||
data_g.add_arg("tokenizer", str, "FullTokenizer",
|
||||
"ATTENTION: the INPUT must be splited by Word with blank while using SentencepieceTokenizer or WordsegTokenizer")
|
||||
data_g.add_arg("train_set", str, None, "Path to training data.")
|
||||
data_g.add_arg("test_set", str, None, "Path to test data.")
|
||||
data_g.add_arg("dev_set", str, None, "Path to validation data.")
|
||||
data_g.add_arg("vocab_path", str, None, "Vocabulary path.")
|
||||
data_g.add_arg("max_seq_len", int, 512, "Number of words of the longest seqence.")
|
||||
data_g.add_arg("q_max_seq_len", int, 32, "Number of words of the longest seqence.")
|
||||
data_g.add_arg("p_max_seq_len", int, 256, "Number of words of the longest seqence.")
|
||||
data_g.add_arg("train_data_size", int, 0, "Number of training data's total examples. Set for distribute.")
|
||||
data_g.add_arg("batch_size", int, 32, "Total examples' number in batch for training. see also --in_tokens.")
|
||||
data_g.add_arg("predict_batch_size", int, None, "Total examples' number in batch for predict. see also --in_tokens.")
|
||||
data_g.add_arg("in_tokens", bool, False,
|
||||
"If set, the batch size will be the maximum number of tokens in one batch. "
|
||||
"Otherwise, it will be the maximum number of examples in one batch.")
|
||||
data_g.add_arg("do_lower_case", bool, True,
|
||||
"Whether to lower case the input text. Should be True for uncased models and False for cased models.")
|
||||
data_g.add_arg("random_seed", int, None, "Random seed.")
|
||||
data_g.add_arg("label_map_config", str, None, "label_map_path.")
|
||||
data_g.add_arg("num_labels", int, 2, "label number")
|
||||
data_g.add_arg("diagnostic", str, None, "GLUE Diagnostic Dataset")
|
||||
data_g.add_arg("diagnostic_save", str, None, "GLUE Diagnostic save f")
|
||||
data_g.add_arg("max_query_length", int, 64, "Max query length.")
|
||||
data_g.add_arg("max_answer_length", int, 100, "Max answer length.")
|
||||
data_g.add_arg("doc_stride", int, 128,
|
||||
"When splitting up a long document into chunks, how much stride to take between chunks.")
|
||||
data_g.add_arg("n_best_size", int, 20,
|
||||
"The total number of n-best predictions to generate in the nbest_predictions.json output file.")
|
||||
data_g.add_arg("chunk_scheme", type=str, default="IOB", choices=["IO", "IOB", "IOE", "IOBES"], help="chunk scheme")
|
||||
|
||||
run_type_g = ArgumentGroup(parser, "run_type", "running type options.")
|
||||
run_type_g.add_arg("use_cuda", bool, True, "If set, use GPU for training.")
|
||||
run_type_g.add_arg("is_distributed", bool, False, "If set, then start distributed training.")
|
||||
run_type_g.add_arg("use_fast_executor", bool, False, "If set, use fast parallel executor (in experiment).")
|
||||
run_type_g.add_arg("num_iteration_per_drop_scope", int, 10, "Iteration intervals to drop scope.")
|
||||
run_type_g.add_arg("do_train", bool, True, "Whether to perform training.")
|
||||
run_type_g.add_arg("do_val", bool, True, "Whether to perform evaluation on dev data set.")
|
||||
run_type_g.add_arg("do_test", bool, True, "Whether to perform evaluation on test data set.")
|
||||
run_type_g.add_arg("output_item", int, 3, "Test output format.")
|
||||
run_type_g.add_arg("output_file_name", str, None, "Test output file name")
|
||||
run_type_g.add_arg("test_data_cnt", int, 1110000 , "total cnt of testset")
|
||||
run_type_g.add_arg("use_multi_gpu_test", bool, False, "Whether to perform evaluation using multiple gpu cards")
|
||||
run_type_g.add_arg("metrics", bool, True, "Whether to perform evaluation on test data set.")
|
||||
run_type_g.add_arg("shuffle", bool, True, "")
|
||||
run_type_g.add_arg("for_cn", bool, False, "model train for cn or for other langs.")
|
||||
85
applications/document_intelligence/doc_vqa/Rerank/src/index_search.py
Executable file
85
applications/document_intelligence/doc_vqa/Rerank/src/index_search.py
Executable file
@@ -0,0 +1,85 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import time
|
||||
import faiss
|
||||
import math
|
||||
import numpy as np
|
||||
|
||||
|
||||
def read_embed(file_name, dim=768, bs=3000):
|
||||
if file_name.endswith('npy'):
|
||||
i = 0
|
||||
emb_np = np.load(file_name)
|
||||
while (i < len(emb_np)):
|
||||
vec_list = emb_np[i:i + bs]
|
||||
i += bs
|
||||
yield vec_list
|
||||
else:
|
||||
vec_list = []
|
||||
with open(file_name) as inp:
|
||||
for line in inp:
|
||||
data = line.strip()
|
||||
vector = [float(item) for item in data.split(' ')]
|
||||
assert len(vector) == dim
|
||||
vec_list.append(vector)
|
||||
if len(vec_list) == bs:
|
||||
yield vec_list
|
||||
vec_list = []
|
||||
if vec_list:
|
||||
yield vec_list
|
||||
|
||||
|
||||
def load_qid(file_name):
|
||||
qid_list = []
|
||||
with open(file_name) as inp:
|
||||
for line in inp:
|
||||
line = line.strip()
|
||||
qid = line.split('\t')[0]
|
||||
qid_list.append(qid)
|
||||
return qid_list
|
||||
|
||||
|
||||
def search(index, emb_file, qid_list, outfile, top_k):
|
||||
q_idx = 0
|
||||
with open(outfile, 'w') as out:
|
||||
for batch_vec in read_embed(emb_file):
|
||||
q_emb_matrix = np.array(batch_vec)
|
||||
res_dist, res_p_id = index.search(q_emb_matrix.astype('float32'),
|
||||
top_k)
|
||||
for i in range(len(q_emb_matrix)):
|
||||
qid = qid_list[q_idx]
|
||||
for j in range(top_k):
|
||||
pid = res_p_id[i][j]
|
||||
score = res_dist[i][j]
|
||||
out.write('%s\t%s\t%s\t%s\n' % (qid, pid, j + 1, score))
|
||||
q_idx += 1
|
||||
|
||||
|
||||
def main():
|
||||
part = sys.argv[1]
|
||||
topk = int(sys.argv[2])
|
||||
q_text_file = sys.argv[3]
|
||||
outfile = 'output/res.top%s-part%s' % (topk, part)
|
||||
|
||||
qid_list = load_qid(q_text_file)
|
||||
|
||||
engine = faiss.read_index("output/para.index.part%s" % part)
|
||||
emb_file = 'output/query.emb.npy'
|
||||
search(engine, emb_file, qid_list, outfile, topk)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
62
applications/document_intelligence/doc_vqa/Rerank/src/merge.py
Executable file
62
applications/document_intelligence/doc_vqa/Rerank/src/merge.py
Executable file
@@ -0,0 +1,62 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
|
||||
shift = int(sys.argv[1])
|
||||
top = int(sys.argv[2])
|
||||
total_part = int(sys.argv[3])
|
||||
|
||||
f_list = []
|
||||
for part in range(total_part):
|
||||
f0 = open('output/res.top%s-part%s' % (top, part))
|
||||
f_list.append(f0)
|
||||
|
||||
line_list = []
|
||||
for part in range(total_part):
|
||||
line = f_list[part].readline()
|
||||
line_list.append(line)
|
||||
|
||||
out = open('output/dev.res.top%s' % top, 'w')
|
||||
last_q = ''
|
||||
ans_list = {}
|
||||
while line_list[-1]:
|
||||
cur_list = []
|
||||
for line in line_list:
|
||||
sub = line.strip().split('\t')
|
||||
cur_list.append(sub)
|
||||
|
||||
if last_q == '':
|
||||
last_q = cur_list[0][0]
|
||||
if cur_list[0][0] != last_q:
|
||||
rank = sorted(ans_list.items(), key=lambda a: a[1], reverse=True)
|
||||
for i in range(top):
|
||||
out.write("%s\t%s\t%s\t%s\n" %
|
||||
(last_q, rank[i][0], i + 1, rank[i][1]))
|
||||
ans_list = {}
|
||||
for i, sub in enumerate(cur_list):
|
||||
ans_list[int(sub[1]) + shift * i] = float(sub[-1])
|
||||
last_q = cur_list[0][0]
|
||||
|
||||
line_list = []
|
||||
for f0 in f_list:
|
||||
line = f0.readline()
|
||||
line_list.append(line)
|
||||
|
||||
rank = sorted(ans_list.items(), key=lambda a: a[1], reverse=True)
|
||||
for i in range(top):
|
||||
out.write("%s\t%s\t%s\t%s\n" % (last_q, rank[i][0], i + 1, rank[i][1]))
|
||||
out.close()
|
||||
|
||||
print('output/dev.res.top%s' % top)
|
||||
284
applications/document_intelligence/doc_vqa/Rerank/src/model/ernie.py
Executable file
284
applications/document_intelligence/doc_vqa/Rerank/src/model/ernie.py
Executable file
@@ -0,0 +1,284 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""Ernie model."""
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
from __future__ import absolute_import
|
||||
|
||||
import json
|
||||
import six
|
||||
import logging
|
||||
from io import open
|
||||
|
||||
import paddle.fluid as fluid
|
||||
|
||||
from model.transformer_encoder import encoder, pre_process_layer
|
||||
|
||||
log = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class ErnieConfig(object):
|
||||
|
||||
def __init__(self, config_path):
|
||||
self._config_dict = self._parse(config_path)
|
||||
|
||||
def _parse(self, config_path):
|
||||
try:
|
||||
with open(config_path, 'r', encoding='utf8') as json_file:
|
||||
config_dict = json.load(json_file)
|
||||
except Exception:
|
||||
raise IOError("Error in parsing Ernie model config file '%s'" %
|
||||
config_path)
|
||||
else:
|
||||
return config_dict
|
||||
|
||||
def __getitem__(self, key):
|
||||
return self._config_dict.get(key, None)
|
||||
|
||||
def print_config(self):
|
||||
for arg, value in sorted(six.iteritems(self._config_dict)):
|
||||
log.info('%s: %s' % (arg, value))
|
||||
log.info('------------------------------------------------')
|
||||
|
||||
|
||||
class ErnieModel(object):
|
||||
|
||||
def __init__(self,
|
||||
src_ids,
|
||||
position_ids,
|
||||
sentence_ids,
|
||||
task_ids,
|
||||
input_mask,
|
||||
config,
|
||||
weight_sharing=True,
|
||||
model_name='',
|
||||
is_noise=False):
|
||||
|
||||
self._emb_size = config['hidden_size']
|
||||
self._n_layer = config['num_hidden_layers']
|
||||
self._n_head = config['num_attention_heads']
|
||||
self._voc_size = config['vocab_size']
|
||||
self._max_position_seq_len = config['max_position_embeddings']
|
||||
if config['sent_type_vocab_size']:
|
||||
self._sent_types = config['sent_type_vocab_size']
|
||||
else:
|
||||
self._sent_types = config['type_vocab_size']
|
||||
|
||||
self._use_task_id = config['use_task_id']
|
||||
if self._use_task_id:
|
||||
self._task_types = config['task_type_vocab_size']
|
||||
self._hidden_act = config['hidden_act']
|
||||
self._prepostprocess_dropout = config['hidden_dropout_prob']
|
||||
self._attention_dropout = config['attention_probs_dropout_prob']
|
||||
if is_noise:
|
||||
self._prepostprocess_dropout = 0
|
||||
self._attention_dropout = 0
|
||||
self._weight_sharing = weight_sharing
|
||||
self.checkpoints = []
|
||||
|
||||
self._word_emb_name = "word_embedding"
|
||||
self._pos_emb_name = "pos_embedding"
|
||||
self._sent_emb_name = "sent_embedding"
|
||||
self._task_emb_name = "task_embedding"
|
||||
self._emb_dtype = "float32"
|
||||
|
||||
# Initialize all weigths by truncated normal initializer, and all biases
|
||||
# will be initialized by constant zero by default.
|
||||
self._param_initializer = fluid.initializer.TruncatedNormal(
|
||||
scale=config['initializer_range'])
|
||||
|
||||
self._build_model(model_name, src_ids, position_ids, sentence_ids,
|
||||
task_ids, input_mask)
|
||||
|
||||
def _build_model(self, model_name, src_ids, position_ids, sentence_ids,
|
||||
task_ids, input_mask):
|
||||
# padding id in vocabulary must be set to 0
|
||||
emb_out = fluid.layers.embedding(
|
||||
input=src_ids,
|
||||
size=[self._voc_size, self._emb_size],
|
||||
dtype=self._emb_dtype,
|
||||
param_attr=fluid.ParamAttr(name=model_name + self._word_emb_name,
|
||||
initializer=self._param_initializer),
|
||||
is_sparse=False)
|
||||
|
||||
position_emb_out = fluid.layers.embedding(
|
||||
input=position_ids,
|
||||
size=[self._max_position_seq_len, self._emb_size],
|
||||
dtype=self._emb_dtype,
|
||||
param_attr=fluid.ParamAttr(name=model_name + self._pos_emb_name,
|
||||
initializer=self._param_initializer))
|
||||
|
||||
sent_emb_out = fluid.layers.embedding(
|
||||
sentence_ids,
|
||||
size=[self._sent_types, self._emb_size],
|
||||
dtype=self._emb_dtype,
|
||||
param_attr=fluid.ParamAttr(name=model_name + self._sent_emb_name,
|
||||
initializer=self._param_initializer))
|
||||
|
||||
emb_out = emb_out + position_emb_out
|
||||
emb_out = emb_out + sent_emb_out
|
||||
|
||||
if self._use_task_id:
|
||||
task_emb_out = fluid.layers.embedding(
|
||||
task_ids,
|
||||
size=[self._task_types, self._emb_size],
|
||||
dtype=self._emb_dtype,
|
||||
param_attr=fluid.ParamAttr(name=model_name +
|
||||
self._task_emb_name,
|
||||
initializer=self._param_initializer))
|
||||
|
||||
emb_out = emb_out + task_emb_out
|
||||
|
||||
emb_out = pre_process_layer(emb_out,
|
||||
'nd',
|
||||
self._prepostprocess_dropout,
|
||||
name=model_name + 'pre_encoder')
|
||||
|
||||
self_attn_mask = fluid.layers.matmul(x=input_mask,
|
||||
y=input_mask,
|
||||
transpose_y=True)
|
||||
|
||||
self_attn_mask = fluid.layers.scale(x=self_attn_mask,
|
||||
scale=10000.0,
|
||||
bias=-1.0,
|
||||
bias_after_scale=False)
|
||||
n_head_self_attn_mask = fluid.layers.stack(x=[self_attn_mask] *
|
||||
self._n_head,
|
||||
axis=1)
|
||||
n_head_self_attn_mask.stop_gradient = True
|
||||
|
||||
self._enc_out, self.checkpoints = encoder(
|
||||
enc_input=emb_out,
|
||||
attn_bias=n_head_self_attn_mask,
|
||||
n_layer=self._n_layer,
|
||||
n_head=self._n_head,
|
||||
d_key=self._emb_size // self._n_head,
|
||||
d_value=self._emb_size // self._n_head,
|
||||
d_model=self._emb_size,
|
||||
d_inner_hid=self._emb_size * 4,
|
||||
prepostprocess_dropout=self._prepostprocess_dropout,
|
||||
attention_dropout=self._attention_dropout,
|
||||
relu_dropout=0,
|
||||
hidden_act=self._hidden_act,
|
||||
preprocess_cmd="",
|
||||
postprocess_cmd="dan",
|
||||
param_initializer=self._param_initializer,
|
||||
model_name=model_name,
|
||||
name=model_name + 'encoder')
|
||||
|
||||
def get_sequence_output(self):
|
||||
return self._enc_out
|
||||
|
||||
def get_cls_output(self):
|
||||
"""Get the first feature of each sequence for classification"""
|
||||
cls_output = fluid.layers.slice(input=self._enc_out,
|
||||
axes=[1],
|
||||
starts=[0],
|
||||
ends=[1])
|
||||
cls_output = fluid.layers.squeeze(cls_output, axes=[1])
|
||||
return cls_output
|
||||
|
||||
def get_pooled_output(self):
|
||||
"""Get the first feature of each sequence for classification"""
|
||||
next_sent_feat = fluid.layers.slice(input=self._enc_out,
|
||||
axes=[1],
|
||||
starts=[0],
|
||||
ends=[1])
|
||||
next_sent_feat = fluid.layers.fc(
|
||||
input=next_sent_feat,
|
||||
size=self._emb_size,
|
||||
act="tanh",
|
||||
param_attr=fluid.ParamAttr(name="pooled_fc.w_0",
|
||||
initializer=self._param_initializer),
|
||||
bias_attr="pooled_fc.b_0")
|
||||
return next_sent_feat
|
||||
|
||||
def get_lm_output(self, mask_label, mask_pos):
|
||||
"""Get the loss & accuracy for pretraining"""
|
||||
|
||||
mask_pos = fluid.layers.cast(x=mask_pos, dtype='int32')
|
||||
|
||||
# extract the first token feature in each sentence
|
||||
self.next_sent_feat = self.get_pooled_output()
|
||||
reshaped_emb_out = fluid.layers.reshape(x=self._enc_out,
|
||||
shape=[-1, self._emb_size])
|
||||
# extract masked tokens' feature
|
||||
mask_feat = fluid.layers.gather(input=reshaped_emb_out, index=mask_pos)
|
||||
|
||||
# transform: fc
|
||||
mask_trans_feat = fluid.layers.fc(
|
||||
input=mask_feat,
|
||||
size=self._emb_size,
|
||||
act=self._hidden_act,
|
||||
param_attr=fluid.ParamAttr(name='mask_lm_trans_fc.w_0',
|
||||
initializer=self._param_initializer),
|
||||
bias_attr=fluid.ParamAttr(name='mask_lm_trans_fc.b_0'))
|
||||
|
||||
# transform: layer norm
|
||||
mask_trans_feat = fluid.layers.layer_norm(
|
||||
mask_trans_feat,
|
||||
begin_norm_axis=len(mask_trans_feat.shape) - 1,
|
||||
param_attr=fluid.ParamAttr(
|
||||
name='mask_lm_trans_layer_norm_scale',
|
||||
initializer=fluid.initializer.Constant(1.)),
|
||||
bias_attr=fluid.ParamAttr(
|
||||
name='mask_lm_trans_layer_norm_bias',
|
||||
initializer=fluid.initializer.Constant(1.)))
|
||||
# transform: layer norm
|
||||
#mask_trans_feat = pre_process_layer(
|
||||
# mask_trans_feat, 'n', name='mask_lm_trans')
|
||||
|
||||
mask_lm_out_bias_attr = fluid.ParamAttr(
|
||||
name="mask_lm_out_fc.b_0",
|
||||
initializer=fluid.initializer.Constant(value=0.0))
|
||||
if self._weight_sharing:
|
||||
fc_out = fluid.layers.matmul(
|
||||
x=mask_trans_feat,
|
||||
y=fluid.default_main_program().global_block().var(
|
||||
self._word_emb_name),
|
||||
transpose_y=True)
|
||||
fc_out += fluid.layers.create_parameter(shape=[self._voc_size],
|
||||
dtype=self._emb_dtype,
|
||||
attr=mask_lm_out_bias_attr,
|
||||
is_bias=True)
|
||||
|
||||
else:
|
||||
fc_out = fluid.layers.fc(input=mask_trans_feat,
|
||||
size=self._voc_size,
|
||||
param_attr=fluid.ParamAttr(
|
||||
name="mask_lm_out_fc.w_0",
|
||||
initializer=self._param_initializer),
|
||||
bias_attr=mask_lm_out_bias_attr)
|
||||
|
||||
mask_lm_loss = fluid.layers.softmax_with_cross_entropy(logits=fc_out,
|
||||
label=mask_label)
|
||||
mean_mask_lm_loss = fluid.layers.mean(mask_lm_loss)
|
||||
|
||||
return mean_mask_lm_loss
|
||||
|
||||
def get_task_output(self, task, task_labels):
|
||||
task_fc_out = fluid.layers.fc(input=self.next_sent_feat,
|
||||
size=task["num_labels"],
|
||||
param_attr=fluid.ParamAttr(
|
||||
name=task["task_name"] + "_fc.w_0",
|
||||
initializer=self._param_initializer),
|
||||
bias_attr=task["task_name"] + "_fc.b_0")
|
||||
task_loss, task_softmax = fluid.layers.softmax_with_cross_entropy(
|
||||
logits=task_fc_out, label=task_labels, return_softmax=True)
|
||||
task_acc = fluid.layers.accuracy(input=task_softmax, label=task_labels)
|
||||
mean_task_loss = fluid.layers.mean(task_loss)
|
||||
return mean_task_loss, task_acc
|
||||
@@ -0,0 +1,336 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""Transformer encoder."""
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
|
||||
from functools import partial
|
||||
|
||||
import paddle.fluid as fluid
|
||||
import paddle.fluid.layers as layers
|
||||
|
||||
|
||||
def multi_head_attention(queries,
|
||||
keys,
|
||||
values,
|
||||
attn_bias,
|
||||
d_key,
|
||||
d_value,
|
||||
d_model,
|
||||
n_head=1,
|
||||
dropout_rate=0.,
|
||||
cache=None,
|
||||
param_initializer=None,
|
||||
name='multi_head_att'):
|
||||
"""
|
||||
Multi-Head Attention. Note that attn_bias is added to the logit before
|
||||
computing softmax activiation to mask certain selected positions so that
|
||||
they will not considered in attention weights.
|
||||
"""
|
||||
keys = queries if keys is None else keys
|
||||
values = keys if values is None else values
|
||||
|
||||
if not (len(queries.shape) == len(keys.shape) == len(values.shape) == 3):
|
||||
raise ValueError(
|
||||
"Inputs: quries, keys and values should all be 3-D tensors.")
|
||||
|
||||
def __compute_qkv(queries, keys, values, n_head, d_key, d_value):
|
||||
"""
|
||||
Add linear projection to queries, keys, and values.
|
||||
"""
|
||||
q = layers.fc(input=queries,
|
||||
size=d_key * n_head,
|
||||
num_flatten_dims=2,
|
||||
param_attr=fluid.ParamAttr(name=name + '_query_fc.w_0',
|
||||
initializer=param_initializer),
|
||||
bias_attr=name + '_query_fc.b_0')
|
||||
k = layers.fc(input=keys,
|
||||
size=d_key * n_head,
|
||||
num_flatten_dims=2,
|
||||
param_attr=fluid.ParamAttr(name=name + '_key_fc.w_0',
|
||||
initializer=param_initializer),
|
||||
bias_attr=name + '_key_fc.b_0')
|
||||
v = layers.fc(input=values,
|
||||
size=d_value * n_head,
|
||||
num_flatten_dims=2,
|
||||
param_attr=fluid.ParamAttr(name=name + '_value_fc.w_0',
|
||||
initializer=param_initializer),
|
||||
bias_attr=name + '_value_fc.b_0')
|
||||
return q, k, v
|
||||
|
||||
def __split_heads(x, n_head):
|
||||
"""
|
||||
Reshape the last dimension of inpunt tensor x so that it becomes two
|
||||
dimensions and then transpose. Specifically, input a tensor with shape
|
||||
[bs, max_sequence_length, n_head * hidden_dim] then output a tensor
|
||||
with shape [bs, n_head, max_sequence_length, hidden_dim].
|
||||
"""
|
||||
hidden_size = x.shape[-1]
|
||||
# The value 0 in shape attr means copying the corresponding dimension
|
||||
# size of the input as the output dimension size.
|
||||
reshaped = layers.reshape(x=x,
|
||||
shape=[0, 0, n_head, hidden_size // n_head],
|
||||
inplace=True)
|
||||
|
||||
# permuate the dimensions into:
|
||||
# [batch_size, n_head, max_sequence_len, hidden_size_per_head]
|
||||
return layers.transpose(x=reshaped, perm=[0, 2, 1, 3])
|
||||
|
||||
def __combine_heads(x):
|
||||
"""
|
||||
Transpose and then reshape the last two dimensions of inpunt tensor x
|
||||
so that it becomes one dimension, which is reverse to __split_heads.
|
||||
"""
|
||||
if len(x.shape) == 3: return x
|
||||
if len(x.shape) != 4:
|
||||
raise ValueError("Input(x) should be a 4-D Tensor.")
|
||||
|
||||
trans_x = layers.transpose(x, perm=[0, 2, 1, 3])
|
||||
# The value 0 in shape attr means copying the corresponding dimension
|
||||
# size of the input as the output dimension size.
|
||||
return layers.reshape(x=trans_x,
|
||||
shape=[0, 0, trans_x.shape[2] * trans_x.shape[3]],
|
||||
inplace=True)
|
||||
|
||||
def scaled_dot_product_attention(q, k, v, attn_bias, d_key, dropout_rate):
|
||||
"""
|
||||
Scaled Dot-Product Attention
|
||||
"""
|
||||
scaled_q = layers.scale(x=q, scale=d_key**-0.5)
|
||||
product = layers.matmul(x=scaled_q, y=k, transpose_y=True)
|
||||
if attn_bias:
|
||||
product += attn_bias
|
||||
weights = layers.softmax(product)
|
||||
if dropout_rate:
|
||||
weights = layers.dropout(weights,
|
||||
dropout_prob=dropout_rate,
|
||||
dropout_implementation="upscale_in_train",
|
||||
is_test=False)
|
||||
out = layers.matmul(weights, v)
|
||||
return out
|
||||
|
||||
q, k, v = __compute_qkv(queries, keys, values, n_head, d_key, d_value)
|
||||
|
||||
if cache is not None: # use cache and concat time steps
|
||||
# Since the inplace reshape in __split_heads changes the shape of k and
|
||||
# v, which is the cache input for next time step, reshape the cache
|
||||
# input from the previous time step first.
|
||||
k = cache["k"] = layers.concat(
|
||||
[layers.reshape(cache["k"], shape=[0, 0, d_model]), k], axis=1)
|
||||
v = cache["v"] = layers.concat(
|
||||
[layers.reshape(cache["v"], shape=[0, 0, d_model]), v], axis=1)
|
||||
|
||||
q = __split_heads(q, n_head)
|
||||
k = __split_heads(k, n_head)
|
||||
v = __split_heads(v, n_head)
|
||||
|
||||
ctx_multiheads = scaled_dot_product_attention(q, k, v, attn_bias, d_key,
|
||||
dropout_rate)
|
||||
|
||||
out = __combine_heads(ctx_multiheads)
|
||||
|
||||
# Project back to the model size.
|
||||
proj_out = layers.fc(input=out,
|
||||
size=d_model,
|
||||
num_flatten_dims=2,
|
||||
param_attr=fluid.ParamAttr(
|
||||
name=name + '_output_fc.w_0',
|
||||
initializer=param_initializer),
|
||||
bias_attr=name + '_output_fc.b_0')
|
||||
return proj_out
|
||||
|
||||
|
||||
def positionwise_feed_forward(x,
|
||||
d_inner_hid,
|
||||
d_hid,
|
||||
dropout_rate,
|
||||
hidden_act,
|
||||
param_initializer=None,
|
||||
name='ffn'):
|
||||
"""
|
||||
Position-wise Feed-Forward Networks.
|
||||
This module consists of two linear transformations with a ReLU activation
|
||||
in between, which is applied to each position separately and identically.
|
||||
"""
|
||||
hidden = layers.fc(input=x,
|
||||
size=d_inner_hid,
|
||||
num_flatten_dims=2,
|
||||
act=hidden_act,
|
||||
param_attr=fluid.ParamAttr(
|
||||
name=name + '_fc_0.w_0',
|
||||
initializer=param_initializer),
|
||||
bias_attr=name + '_fc_0.b_0')
|
||||
if dropout_rate:
|
||||
hidden = layers.dropout(hidden,
|
||||
dropout_prob=dropout_rate,
|
||||
dropout_implementation="upscale_in_train",
|
||||
is_test=False)
|
||||
out = layers.fc(input=hidden,
|
||||
size=d_hid,
|
||||
num_flatten_dims=2,
|
||||
param_attr=fluid.ParamAttr(name=name + '_fc_1.w_0',
|
||||
initializer=param_initializer),
|
||||
bias_attr=name + '_fc_1.b_0')
|
||||
return out
|
||||
|
||||
|
||||
def pre_post_process_layer(prev_out,
|
||||
out,
|
||||
process_cmd,
|
||||
dropout_rate=0.,
|
||||
name=''):
|
||||
"""
|
||||
Add residual connection, layer normalization and droput to the out tensor
|
||||
optionally according to the value of process_cmd.
|
||||
This will be used before or after multi-head attention and position-wise
|
||||
feed-forward networks.
|
||||
"""
|
||||
for cmd in process_cmd:
|
||||
if cmd == "a": # add residual connection
|
||||
out = out + prev_out if prev_out else out
|
||||
elif cmd == "n": # add layer normalization
|
||||
out_dtype = out.dtype
|
||||
if out_dtype == fluid.core.VarDesc.VarType.FP16:
|
||||
out = layers.cast(x=out, dtype="float32")
|
||||
out = layers.layer_norm(
|
||||
out,
|
||||
begin_norm_axis=len(out.shape) - 1,
|
||||
param_attr=fluid.ParamAttr(
|
||||
name=name + '_layer_norm_scale',
|
||||
initializer=fluid.initializer.Constant(1.)),
|
||||
bias_attr=fluid.ParamAttr(
|
||||
name=name + '_layer_norm_bias',
|
||||
initializer=fluid.initializer.Constant(0.)))
|
||||
if out_dtype == fluid.core.VarDesc.VarType.FP16:
|
||||
out = layers.cast(x=out, dtype="float16")
|
||||
elif cmd == "d": # add dropout
|
||||
if dropout_rate:
|
||||
out = layers.dropout(out,
|
||||
dropout_prob=dropout_rate,
|
||||
dropout_implementation="upscale_in_train",
|
||||
is_test=False)
|
||||
return out
|
||||
|
||||
|
||||
pre_process_layer = partial(pre_post_process_layer, None)
|
||||
post_process_layer = pre_post_process_layer
|
||||
|
||||
|
||||
def encoder_layer(enc_input,
|
||||
attn_bias,
|
||||
n_head,
|
||||
d_key,
|
||||
d_value,
|
||||
d_model,
|
||||
d_inner_hid,
|
||||
prepostprocess_dropout,
|
||||
attention_dropout,
|
||||
relu_dropout,
|
||||
hidden_act,
|
||||
preprocess_cmd="n",
|
||||
postprocess_cmd="da",
|
||||
param_initializer=None,
|
||||
name=''):
|
||||
"""The encoder layers that can be stacked to form a deep encoder.
|
||||
This module consits of a multi-head (self) attention followed by
|
||||
position-wise feed-forward networks and both the two components companied
|
||||
with the post_process_layer to add residual connection, layer normalization
|
||||
and droput.
|
||||
"""
|
||||
attn_output = multi_head_attention(pre_process_layer(enc_input,
|
||||
preprocess_cmd,
|
||||
prepostprocess_dropout,
|
||||
name=name +
|
||||
'_pre_att'),
|
||||
None,
|
||||
None,
|
||||
attn_bias,
|
||||
d_key,
|
||||
d_value,
|
||||
d_model,
|
||||
n_head,
|
||||
attention_dropout,
|
||||
param_initializer=param_initializer,
|
||||
name=name + '_multi_head_att')
|
||||
attn_output = post_process_layer(enc_input,
|
||||
attn_output,
|
||||
postprocess_cmd,
|
||||
prepostprocess_dropout,
|
||||
name=name + '_post_att')
|
||||
ffd_output = positionwise_feed_forward(pre_process_layer(
|
||||
attn_output,
|
||||
preprocess_cmd,
|
||||
prepostprocess_dropout,
|
||||
name=name + '_pre_ffn'),
|
||||
d_inner_hid,
|
||||
d_model,
|
||||
relu_dropout,
|
||||
hidden_act,
|
||||
param_initializer=param_initializer,
|
||||
name=name + '_ffn')
|
||||
return post_process_layer(attn_output,
|
||||
ffd_output,
|
||||
postprocess_cmd,
|
||||
prepostprocess_dropout,
|
||||
name=name + '_post_ffn'), ffd_output
|
||||
|
||||
|
||||
def encoder(enc_input,
|
||||
attn_bias,
|
||||
n_layer,
|
||||
n_head,
|
||||
d_key,
|
||||
d_value,
|
||||
d_model,
|
||||
d_inner_hid,
|
||||
prepostprocess_dropout,
|
||||
attention_dropout,
|
||||
relu_dropout,
|
||||
hidden_act,
|
||||
preprocess_cmd="n",
|
||||
postprocess_cmd="da",
|
||||
param_initializer=None,
|
||||
model_name='',
|
||||
name=''):
|
||||
"""
|
||||
The encoder is composed of a stack of identical layers returned by calling
|
||||
encoder_layer.
|
||||
"""
|
||||
checkpoints = []
|
||||
for i in range(n_layer):
|
||||
enc_output, cp = encoder_layer(enc_input,
|
||||
attn_bias,
|
||||
n_head,
|
||||
d_key,
|
||||
d_value,
|
||||
d_model,
|
||||
d_inner_hid,
|
||||
prepostprocess_dropout,
|
||||
attention_dropout,
|
||||
relu_dropout,
|
||||
hidden_act,
|
||||
preprocess_cmd,
|
||||
postprocess_cmd,
|
||||
param_initializer=param_initializer,
|
||||
name=name + '_layer_' + str(i))
|
||||
checkpoints.append(cp)
|
||||
enc_input = enc_output
|
||||
enc_output = pre_process_layer(enc_output,
|
||||
preprocess_cmd,
|
||||
prepostprocess_dropout,
|
||||
name=model_name + "post_encoder")
|
||||
|
||||
return enc_output, checkpoints
|
||||
137
applications/document_intelligence/doc_vqa/Rerank/src/optimization.py
Executable file
137
applications/document_intelligence/doc_vqa/Rerank/src/optimization.py
Executable file
@@ -0,0 +1,137 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""Optimization and learning rate scheduling."""
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
from __future__ import absolute_import
|
||||
|
||||
import numpy as np
|
||||
|
||||
import paddle.fluid as fluid
|
||||
from paddle.fluid.incubate.fleet.collective import fleet, DistributedStrategy
|
||||
|
||||
|
||||
def linear_warmup_decay(learning_rate, warmup_steps, num_train_steps):
|
||||
""" Applies linear warmup of learning rate from 0 and decay to 0."""
|
||||
with fluid.default_main_program()._lr_schedule_guard():
|
||||
lr = fluid.layers.tensor.create_global_var(
|
||||
shape=[1],
|
||||
value=0.0,
|
||||
dtype='float32',
|
||||
persistable=True,
|
||||
name="scheduled_learning_rate")
|
||||
|
||||
global_step = fluid.layers.learning_rate_scheduler._decay_step_counter()
|
||||
|
||||
with fluid.layers.control_flow.Switch() as switch:
|
||||
with switch.case(global_step < warmup_steps):
|
||||
warmup_lr = learning_rate * (global_step / warmup_steps)
|
||||
fluid.layers.tensor.assign(warmup_lr, lr)
|
||||
with switch.default():
|
||||
decayed_lr = fluid.layers.learning_rate_scheduler.polynomial_decay(
|
||||
learning_rate=learning_rate,
|
||||
decay_steps=num_train_steps,
|
||||
end_learning_rate=0.0,
|
||||
power=1.0,
|
||||
cycle=False)
|
||||
fluid.layers.tensor.assign(decayed_lr, lr)
|
||||
|
||||
return lr
|
||||
|
||||
|
||||
def optimization(loss,
|
||||
warmup_steps,
|
||||
num_train_steps,
|
||||
learning_rate,
|
||||
train_program,
|
||||
startup_prog,
|
||||
weight_decay,
|
||||
scheduler='linear_warmup_decay',
|
||||
use_dynamic_loss_scaling=False,
|
||||
incr_every_n_steps=1000,
|
||||
decr_every_n_nan_or_inf=2,
|
||||
incr_ratio=2.0,
|
||||
decr_ratio=0.8,
|
||||
dist_strategy=None,
|
||||
use_lamb=False):
|
||||
if warmup_steps > 0:
|
||||
if scheduler == 'noam_decay':
|
||||
scheduled_lr = fluid.layers.learning_rate_scheduler\
|
||||
.noam_decay(1/(warmup_steps *(learning_rate ** 2)),
|
||||
warmup_steps)
|
||||
elif scheduler == 'linear_warmup_decay':
|
||||
scheduled_lr = linear_warmup_decay(learning_rate, warmup_steps,
|
||||
num_train_steps)
|
||||
else:
|
||||
raise ValueError("Unkown learning rate scheduler, should be "
|
||||
"'noam_decay' or 'linear_warmup_decay'")
|
||||
if use_lamb:
|
||||
optimizer = fluid.optimizer.LambOptimizer(
|
||||
learning_rate=scheduled_lr)
|
||||
else:
|
||||
optimizer = fluid.optimizer.Adam(learning_rate=scheduled_lr)
|
||||
else:
|
||||
scheduled_lr = fluid.layers.create_global_var(
|
||||
name=fluid.unique_name.generate("learning_rate"),
|
||||
shape=[1],
|
||||
value=learning_rate,
|
||||
dtype='float32',
|
||||
persistable=True)
|
||||
if use_lamb:
|
||||
optimizer = fluid.optimizer.LambOptimizer(
|
||||
learning_rate=scheduled_lr)
|
||||
else:
|
||||
optimizer = fluid.optimizer.Adam(learning_rate=scheduled_lr)
|
||||
optimizer._learning_rate_map[
|
||||
fluid.default_main_program()] = scheduled_lr
|
||||
|
||||
fluid.clip.set_gradient_clip(clip=fluid.clip.GradientClipByGlobalNorm(
|
||||
clip_norm=1.0))
|
||||
|
||||
def exclude_from_weight_decay(name):
|
||||
if name.find("layer_norm") > -1:
|
||||
return True
|
||||
bias_suffix = ["_bias", "_b", ".b_0"]
|
||||
for suffix in bias_suffix:
|
||||
if name.endswith(suffix):
|
||||
return True
|
||||
return False
|
||||
|
||||
param_list = dict()
|
||||
|
||||
for param in train_program.global_block().all_parameters():
|
||||
param_list[param.name] = param * 1.0
|
||||
param_list[param.name].stop_gradient = True
|
||||
|
||||
if dist_strategy is not None:
|
||||
# use fleet api
|
||||
optimizer = fleet.distributed_optimizer(optimizer,
|
||||
strategy=dist_strategy)
|
||||
|
||||
_, param_grads = optimizer.minimize(loss)
|
||||
|
||||
if weight_decay > 0:
|
||||
for param, grad in param_grads:
|
||||
if exclude_from_weight_decay(param.name):
|
||||
continue
|
||||
with param.block.program._optimized_guard(
|
||||
[param, grad]), fluid.framework.name_scope("weight_decay"):
|
||||
updated_param = param - param_list[
|
||||
param.name] * weight_decay * scheduled_lr
|
||||
fluid.layers.assign(output=param, input=updated_param)
|
||||
|
||||
return scheduled_lr
|
||||
357
applications/document_intelligence/doc_vqa/Rerank/src/reader_ce.py
Executable file
357
applications/document_intelligence/doc_vqa/Rerank/src/reader_ce.py
Executable file
@@ -0,0 +1,357 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
from __future__ import absolute_import
|
||||
|
||||
import sys
|
||||
import os
|
||||
import json
|
||||
import random
|
||||
import logging
|
||||
import numpy as np
|
||||
import six
|
||||
from io import open
|
||||
from collections import namedtuple
|
||||
|
||||
import tokenization
|
||||
from batching import pad_batch_data
|
||||
|
||||
log = logging.getLogger(__name__)
|
||||
|
||||
if six.PY3:
|
||||
import io
|
||||
sys.stdout = io.TextIOWrapper(sys.stdout.buffer, encoding='utf-8')
|
||||
sys.stderr = io.TextIOWrapper(sys.stderr.buffer, encoding='utf-8')
|
||||
|
||||
|
||||
def csv_reader(fd, delimiter='\t', trainer_id=0, trainer_num=1):
|
||||
|
||||
def gen():
|
||||
for i, line in enumerate(fd):
|
||||
if i % trainer_num == trainer_id:
|
||||
slots = line.rstrip('\n').split(delimiter)
|
||||
if len(slots) == 1:
|
||||
yield slots,
|
||||
else:
|
||||
yield slots
|
||||
|
||||
return gen()
|
||||
|
||||
|
||||
class BaseReader(object):
|
||||
|
||||
def __init__(self,
|
||||
vocab_path,
|
||||
label_map_config=None,
|
||||
max_seq_len=512,
|
||||
total_num=0,
|
||||
do_lower_case=True,
|
||||
in_tokens=False,
|
||||
is_inference=False,
|
||||
random_seed=None,
|
||||
tokenizer="FullTokenizer",
|
||||
for_cn=True,
|
||||
task_id=0):
|
||||
self.max_seq_len = max_seq_len
|
||||
self.tokenizer = tokenization.FullTokenizer(vocab_file=vocab_path,
|
||||
do_lower_case=do_lower_case)
|
||||
self.vocab = self.tokenizer.vocab
|
||||
self.pad_id = self.vocab["[PAD]"]
|
||||
self.cls_id = self.vocab["[CLS]"]
|
||||
self.sep_id = self.vocab["[SEP]"]
|
||||
self.in_tokens = in_tokens
|
||||
self.is_inference = is_inference
|
||||
self.for_cn = for_cn
|
||||
self.task_id = task_id
|
||||
|
||||
np.random.seed(random_seed)
|
||||
|
||||
self.current_example = 0
|
||||
self.current_epoch = 0
|
||||
self.num_examples = 0
|
||||
self.total_num = total_num
|
||||
|
||||
if label_map_config:
|
||||
with open(label_map_config, encoding='utf8') as f:
|
||||
self.label_map = json.load(f)
|
||||
else:
|
||||
self.label_map = None
|
||||
|
||||
def get_train_progress(self):
|
||||
"""Gets progress for training phase."""
|
||||
return self.current_example, self.current_epoch
|
||||
|
||||
def _read_tsv(self, input_file, quotechar=None):
|
||||
"""Reads a tab separated value file."""
|
||||
with open(input_file, 'r', encoding='utf8') as f:
|
||||
reader = csv_reader(f)
|
||||
headers = next(reader)
|
||||
Example = namedtuple('Example', headers)
|
||||
|
||||
examples = []
|
||||
for line in reader:
|
||||
example = Example(*line)
|
||||
examples.append(example)
|
||||
return examples
|
||||
|
||||
def _truncate_seq_pair(self, tokens_a, tokens_b, max_length):
|
||||
"""Truncates a sequence pair in place to the maximum length."""
|
||||
|
||||
# This is a simple heuristic which will always truncate the longer sequence
|
||||
# one token at a time. This makes more sense than truncating an equal percent
|
||||
# of tokens from each, since if one sequence is very short then each token
|
||||
# that's truncated likely contains more information than a longer sequence.
|
||||
while True:
|
||||
total_length = len(tokens_a) + len(tokens_b)
|
||||
if total_length <= max_length:
|
||||
break
|
||||
if len(tokens_a) > len(tokens_b):
|
||||
tokens_a.pop()
|
||||
else:
|
||||
tokens_b.pop()
|
||||
|
||||
def _convert_example_to_record(self, example, max_seq_length, tokenizer):
|
||||
"""Converts a single `Example` into a single `Record`."""
|
||||
|
||||
query = tokenization.convert_to_unicode(example.query)
|
||||
tokens_a = tokenizer.tokenize(query)
|
||||
tokens_b = None
|
||||
|
||||
title = tokenization.convert_to_unicode(example.title)
|
||||
tokens_b = tokenizer.tokenize(title)
|
||||
|
||||
para = tokenization.convert_to_unicode(example.para)
|
||||
tokens_para = tokenizer.tokenize(para)
|
||||
|
||||
tokens_b.extend(tokens_para)
|
||||
|
||||
self._truncate_seq_pair(tokens_a, tokens_b, max_seq_length - 3)
|
||||
|
||||
# The convention in BERT/ERNIE is:
|
||||
# (a) For sequence pairs:
|
||||
# tokens: [CLS] is this jack ##son ##ville ? [SEP] no it is not . [SEP]
|
||||
# type_ids: 0 0 0 0 0 0 0 0 1 1 1 1 1 1
|
||||
# (b) For single sequences:
|
||||
# tokens: [CLS] the dog is hairy . [SEP]
|
||||
# type_ids: 0 0 0 0 0 0 0
|
||||
#
|
||||
# Where "type_ids" are used to indicate whether this is the first
|
||||
# sequence or the second sequence. The embedding vectors for `type=0` and
|
||||
# `type=1` were learned during pre-training and are added to the wordpiece
|
||||
# embedding vector (and position vector). This is not *strictly* necessary
|
||||
# since the [SEP] token unambiguously separates the sequences, but it makes
|
||||
# it easier for the model to learn the concept of sequences.
|
||||
#
|
||||
# For classification tasks, the first vector (corresponding to [CLS]) is
|
||||
# used as as the "sentence vector". Note that this only makes sense because
|
||||
# the entire model is fine-tuned.
|
||||
tokens = []
|
||||
text_type_ids = []
|
||||
tokens.append("[CLS]")
|
||||
text_type_ids.append(0)
|
||||
for token in tokens_a:
|
||||
tokens.append(token)
|
||||
text_type_ids.append(0)
|
||||
tokens.append("[SEP]")
|
||||
text_type_ids.append(0)
|
||||
|
||||
if tokens_b:
|
||||
for token in tokens_b:
|
||||
tokens.append(token)
|
||||
text_type_ids.append(1)
|
||||
tokens.append("[SEP]")
|
||||
text_type_ids.append(1)
|
||||
|
||||
token_ids = tokenizer.convert_tokens_to_ids(tokens)
|
||||
position_ids = list(range(len(token_ids)))
|
||||
|
||||
if self.is_inference:
|
||||
Record = namedtuple('Record',
|
||||
['token_ids', 'text_type_ids', 'position_ids'])
|
||||
record = Record(token_ids=token_ids,
|
||||
text_type_ids=text_type_ids,
|
||||
position_ids=position_ids)
|
||||
else:
|
||||
if self.label_map:
|
||||
label_id = self.label_map[example.label]
|
||||
else:
|
||||
label_id = example.label
|
||||
|
||||
Record = namedtuple('Record', [
|
||||
'token_ids', 'text_type_ids', 'position_ids', 'label_id', 'qid'
|
||||
])
|
||||
|
||||
qid = None
|
||||
if "qid" in example._fields:
|
||||
qid = example.qid
|
||||
|
||||
record = Record(token_ids=token_ids,
|
||||
text_type_ids=text_type_ids,
|
||||
position_ids=position_ids,
|
||||
label_id=label_id,
|
||||
qid=qid)
|
||||
return record
|
||||
|
||||
def _prepare_batch_data(self, examples, batch_size, phase=None):
|
||||
"""generate batch records"""
|
||||
batch_records, max_len = [], 0
|
||||
for index, example in enumerate(examples):
|
||||
if phase == "train":
|
||||
self.current_example = index
|
||||
record = self._convert_example_to_record(example, self.max_seq_len,
|
||||
self.tokenizer)
|
||||
max_len = max(max_len, len(record.token_ids))
|
||||
if self.in_tokens:
|
||||
to_append = (len(batch_records) + 1) * max_len <= batch_size
|
||||
else:
|
||||
to_append = len(batch_records) < batch_size
|
||||
if to_append:
|
||||
batch_records.append(record)
|
||||
else:
|
||||
yield self._pad_batch_records(batch_records)
|
||||
batch_records, max_len = [record], len(record.token_ids)
|
||||
|
||||
if batch_records:
|
||||
yield self._pad_batch_records(batch_records)
|
||||
|
||||
def get_num_examples(self, input_file):
|
||||
# examples = self._read_tsv(input_file)
|
||||
# return len(examples)
|
||||
return self.num_examples
|
||||
|
||||
def data_generator(self,
|
||||
input_file,
|
||||
batch_size,
|
||||
epoch,
|
||||
dev_count=1,
|
||||
trainer_id=0,
|
||||
trainer_num=1,
|
||||
shuffle=True,
|
||||
phase=None):
|
||||
|
||||
if phase == 'train':
|
||||
# examples = examples[trainer_id: (len(examples) //trainer_num) * trainer_num : trainer_num]
|
||||
self.num_examples_per_node = self.total_num // trainer_num
|
||||
self.num_examples = self.num_examples_per_node * trainer_num
|
||||
examples = self._read_tsv(input_file,
|
||||
trainer_id=trainer_id,
|
||||
trainer_num=trainer_num,
|
||||
num_examples=self.num_examples_per_node)
|
||||
log.info('apply sharding %d/%d' % (trainer_id, trainer_num))
|
||||
else:
|
||||
examples = self._read_tsv(input_file)
|
||||
|
||||
def wrapper():
|
||||
all_dev_batches = []
|
||||
for epoch_index in range(epoch):
|
||||
if phase == "train":
|
||||
self.current_example = 0
|
||||
self.current_epoch = epoch_index
|
||||
if shuffle:
|
||||
np.random.shuffle(examples)
|
||||
|
||||
for batch_data in self._prepare_batch_data(examples,
|
||||
batch_size,
|
||||
phase=phase):
|
||||
if len(all_dev_batches) < dev_count:
|
||||
all_dev_batches.append(batch_data)
|
||||
if len(all_dev_batches) == dev_count:
|
||||
for batch in all_dev_batches:
|
||||
yield batch
|
||||
all_dev_batches = []
|
||||
|
||||
def f():
|
||||
try:
|
||||
for i in wrapper():
|
||||
yield i
|
||||
except Exception as e:
|
||||
import traceback
|
||||
traceback.print_exc()
|
||||
|
||||
return f
|
||||
|
||||
|
||||
class ClassifyReader(BaseReader):
|
||||
|
||||
def _read_tsv(self,
|
||||
input_file,
|
||||
quotechar=None,
|
||||
trainer_id=0,
|
||||
trainer_num=1,
|
||||
num_examples=0):
|
||||
"""Reads a tab separated value file."""
|
||||
with open(input_file, 'r', encoding='utf8') as f:
|
||||
reader = csv_reader(f,
|
||||
trainer_id=trainer_id,
|
||||
trainer_num=trainer_num)
|
||||
# headers = next(reader)
|
||||
headers = 'query\ttitle\tpara\tlabel'.split('\t')
|
||||
text_indices = [
|
||||
index for index, h in enumerate(headers) if h != "label"
|
||||
]
|
||||
Example = namedtuple('Example', headers)
|
||||
|
||||
examples = []
|
||||
for cnt, line in enumerate(reader):
|
||||
if num_examples != 0 and cnt == num_examples:
|
||||
break
|
||||
for index, text in enumerate(line):
|
||||
if index in text_indices:
|
||||
if self.for_cn:
|
||||
line[index] = text.replace(' ', '')
|
||||
else:
|
||||
line[index] = text
|
||||
example = Example(*line)
|
||||
examples.append(example)
|
||||
return examples
|
||||
|
||||
def _pad_batch_records(self, batch_records):
|
||||
batch_token_ids = [record.token_ids for record in batch_records]
|
||||
batch_text_type_ids = [record.text_type_ids for record in batch_records]
|
||||
batch_position_ids = [record.position_ids for record in batch_records]
|
||||
|
||||
if not self.is_inference:
|
||||
batch_labels = [record.label_id for record in batch_records]
|
||||
batch_labels = np.array(batch_labels).astype("int64").reshape(
|
||||
[-1, 1])
|
||||
|
||||
if batch_records[0].qid:
|
||||
batch_qids = [record.qid for record in batch_records]
|
||||
batch_qids = np.array(batch_qids).astype("int64").reshape(
|
||||
[-1, 1])
|
||||
else:
|
||||
batch_qids = np.array([]).astype("int64").reshape([-1, 1])
|
||||
|
||||
# padding
|
||||
padded_token_ids, input_mask = pad_batch_data(batch_token_ids,
|
||||
pad_idx=self.pad_id,
|
||||
return_input_mask=True)
|
||||
padded_text_type_ids = pad_batch_data(batch_text_type_ids,
|
||||
pad_idx=self.pad_id)
|
||||
padded_position_ids = pad_batch_data(batch_position_ids,
|
||||
pad_idx=self.pad_id)
|
||||
padded_task_ids = np.ones_like(padded_token_ids,
|
||||
dtype="int64") * self.task_id
|
||||
|
||||
return_list = [
|
||||
padded_token_ids, padded_text_type_ids, padded_position_ids,
|
||||
padded_task_ids, input_mask
|
||||
]
|
||||
if not self.is_inference:
|
||||
return_list += [batch_labels, batch_qids]
|
||||
|
||||
return return_list
|
||||
421
applications/document_intelligence/doc_vqa/Rerank/src/tokenization.py
Executable file
421
applications/document_intelligence/doc_vqa/Rerank/src/tokenization.py
Executable file
@@ -0,0 +1,421 @@
|
||||
# coding=utf-8
|
||||
# Copyright 2018 The Google AI Language Team Authors.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""Tokenization classes."""
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
from __future__ import absolute_import
|
||||
|
||||
import six
|
||||
import collections
|
||||
import unicodedata
|
||||
from io import open
|
||||
|
||||
|
||||
def convert_to_unicode(text):
|
||||
"""Converts `text` to Unicode (if it's not already), assuming utf-8 input."""
|
||||
if six.PY3:
|
||||
if isinstance(text, str):
|
||||
return text
|
||||
elif isinstance(text, bytes):
|
||||
return text.decode("utf-8", "ignore")
|
||||
else:
|
||||
raise ValueError("Unsupported string type: %s" % (type(text)))
|
||||
elif six.PY2:
|
||||
if isinstance(text, str):
|
||||
return text.decode("utf-8", "ignore")
|
||||
elif isinstance(text, unicode):
|
||||
return text
|
||||
else:
|
||||
raise ValueError("Unsupported string type: %s" % (type(text)))
|
||||
else:
|
||||
raise ValueError("Not running on Python2 or Python 3?")
|
||||
|
||||
|
||||
def printable_text(text):
|
||||
"""Returns text encoded in a way suitable for print or `tf.logging`."""
|
||||
|
||||
# These functions want `str` for both Python2 and Python3, but in one case
|
||||
# it's a Unicode string and in the other it's a byte string.
|
||||
if six.PY3:
|
||||
if isinstance(text, str):
|
||||
return text
|
||||
elif isinstance(text, bytes):
|
||||
return text.decode("utf-8", "ignore")
|
||||
else:
|
||||
raise ValueError("Unsupported string type: %s" % (type(text)))
|
||||
elif six.PY2:
|
||||
if isinstance(text, str):
|
||||
return text
|
||||
elif isinstance(text, unicode):
|
||||
return text.encode("utf-8")
|
||||
else:
|
||||
raise ValueError("Unsupported string type: %s" % (type(text)))
|
||||
else:
|
||||
raise ValueError("Not running on Python2 or Python 3?")
|
||||
|
||||
|
||||
def load_vocab(vocab_file):
|
||||
"""Loads a vocabulary file into a dictionary."""
|
||||
vocab = collections.OrderedDict()
|
||||
with open(vocab_file, encoding='utf8') as fin:
|
||||
for num, line in enumerate(fin):
|
||||
items = convert_to_unicode(line.strip()).split("\t")
|
||||
if len(items) > 2:
|
||||
break
|
||||
token = items[0]
|
||||
index = items[1] if len(items) == 2 else num
|
||||
token = token.strip()
|
||||
vocab[token] = int(index)
|
||||
return vocab
|
||||
|
||||
|
||||
def convert_by_vocab(vocab, items):
|
||||
"""Converts a sequence of [tokens|ids] using the vocab."""
|
||||
output = []
|
||||
for item in items:
|
||||
output.append(vocab[item])
|
||||
return output
|
||||
|
||||
|
||||
def convert_tokens_to_ids(vocab, tokens):
|
||||
return convert_by_vocab(vocab, tokens)
|
||||
|
||||
|
||||
def convert_ids_to_tokens(inv_vocab, ids):
|
||||
return convert_by_vocab(inv_vocab, ids)
|
||||
|
||||
|
||||
def whitespace_tokenize(text):
|
||||
"""Runs basic whitespace cleaning and splitting on a peice of text."""
|
||||
text = text.strip()
|
||||
if not text:
|
||||
return []
|
||||
tokens = text.split()
|
||||
return tokens
|
||||
|
||||
|
||||
class FullTokenizer(object):
|
||||
"""Runs end-to-end tokenziation."""
|
||||
|
||||
def __init__(self, vocab_file, do_lower_case=True):
|
||||
self.vocab = load_vocab(vocab_file)
|
||||
self.inv_vocab = {v: k for k, v in self.vocab.items()}
|
||||
self.basic_tokenizer = BasicTokenizer(do_lower_case=do_lower_case)
|
||||
self.wordpiece_tokenizer = WordpieceTokenizer(vocab=self.vocab)
|
||||
|
||||
def tokenize(self, text):
|
||||
split_tokens = []
|
||||
for token in self.basic_tokenizer.tokenize(text):
|
||||
for sub_token in self.wordpiece_tokenizer.tokenize(token):
|
||||
split_tokens.append(sub_token)
|
||||
|
||||
return split_tokens
|
||||
|
||||
def convert_tokens_to_ids(self, tokens):
|
||||
return convert_by_vocab(self.vocab, tokens)
|
||||
|
||||
def convert_ids_to_tokens(self, ids):
|
||||
return convert_by_vocab(self.inv_vocab, ids)
|
||||
|
||||
|
||||
class CharTokenizer(object):
|
||||
"""Runs end-to-end tokenziation."""
|
||||
|
||||
def __init__(self, vocab_file, do_lower_case=True):
|
||||
self.vocab = load_vocab(vocab_file)
|
||||
self.inv_vocab = {v: k for k, v in self.vocab.items()}
|
||||
self.wordpiece_tokenizer = WordpieceTokenizer(vocab=self.vocab)
|
||||
|
||||
def tokenize(self, text):
|
||||
split_tokens = []
|
||||
for token in text.lower().split(" "):
|
||||
for sub_token in self.wordpiece_tokenizer.tokenize(token):
|
||||
split_tokens.append(sub_token)
|
||||
|
||||
return split_tokens
|
||||
|
||||
def convert_tokens_to_ids(self, tokens):
|
||||
return convert_by_vocab(self.vocab, tokens)
|
||||
|
||||
def convert_ids_to_tokens(self, ids):
|
||||
return convert_by_vocab(self.inv_vocab, ids)
|
||||
|
||||
|
||||
class BasicTokenizer(object):
|
||||
"""Runs basic tokenization (punctuation splitting, lower casing, etc.)."""
|
||||
|
||||
def __init__(self, do_lower_case=True):
|
||||
"""Constructs a BasicTokenizer.
|
||||
|
||||
Args:
|
||||
do_lower_case: Whether to lower case the input.
|
||||
"""
|
||||
self.do_lower_case = do_lower_case
|
||||
|
||||
def tokenize(self, text):
|
||||
"""Tokenizes a piece of text."""
|
||||
text = convert_to_unicode(text)
|
||||
text = self._clean_text(text)
|
||||
|
||||
# This was added on November 1st, 2018 for the multilingual and Chinese
|
||||
# models. This is also applied to the English models now, but it doesn't
|
||||
# matter since the English models were not trained on any Chinese data
|
||||
# and generally don't have any Chinese data in them (there are Chinese
|
||||
# characters in the vocabulary because Wikipedia does have some Chinese
|
||||
# words in the English Wikipedia.).
|
||||
text = self._tokenize_chinese_chars(text)
|
||||
|
||||
orig_tokens = whitespace_tokenize(text)
|
||||
split_tokens = []
|
||||
for token in orig_tokens:
|
||||
if self.do_lower_case:
|
||||
token = token.lower()
|
||||
token = self._run_strip_accents(token)
|
||||
split_tokens.extend(self._run_split_on_punc(token))
|
||||
|
||||
output_tokens = whitespace_tokenize(" ".join(split_tokens))
|
||||
return output_tokens
|
||||
|
||||
def _run_strip_accents(self, text):
|
||||
"""Strips accents from a piece of text."""
|
||||
text = unicodedata.normalize("NFD", text)
|
||||
output = []
|
||||
for char in text:
|
||||
cat = unicodedata.category(char)
|
||||
if cat == "Mn":
|
||||
continue
|
||||
output.append(char)
|
||||
return "".join(output)
|
||||
|
||||
def _run_split_on_punc(self, text):
|
||||
"""Splits punctuation on a piece of text."""
|
||||
chars = list(text)
|
||||
i = 0
|
||||
start_new_word = True
|
||||
output = []
|
||||
while i < len(chars):
|
||||
char = chars[i]
|
||||
if _is_punctuation(char):
|
||||
output.append([char])
|
||||
start_new_word = True
|
||||
else:
|
||||
if start_new_word:
|
||||
output.append([])
|
||||
start_new_word = False
|
||||
output[-1].append(char)
|
||||
i += 1
|
||||
|
||||
return ["".join(x) for x in output]
|
||||
|
||||
def _tokenize_chinese_chars(self, text):
|
||||
"""Adds whitespace around any CJK character."""
|
||||
output = []
|
||||
for char in text:
|
||||
cp = ord(char)
|
||||
if self._is_chinese_char(cp):
|
||||
output.append(" ")
|
||||
output.append(char)
|
||||
output.append(" ")
|
||||
else:
|
||||
output.append(char)
|
||||
return "".join(output)
|
||||
|
||||
def _is_chinese_char(self, cp):
|
||||
"""Checks whether CP is the codepoint of a CJK character."""
|
||||
# This defines a "chinese character" as anything in the CJK Unicode block:
|
||||
# https://en.wikipedia.org/wiki/CJK_Unified_Ideographs_(Unicode_block)
|
||||
#
|
||||
# Note that the CJK Unicode block is NOT all Japanese and Korean characters,
|
||||
# despite its name. The modern Korean Hangul alphabet is a different block,
|
||||
# as is Japanese Hiragana and Katakana. Those alphabets are used to write
|
||||
# space-separated words, so they are not treated specially and handled
|
||||
# like the all of the other languages.
|
||||
if ((cp >= 0x4E00 and cp <= 0x9FFF) or #
|
||||
(cp >= 0x3400 and cp <= 0x4DBF) or #
|
||||
(cp >= 0x20000 and cp <= 0x2A6DF) or #
|
||||
(cp >= 0x2A700 and cp <= 0x2B73F) or #
|
||||
(cp >= 0x2B740 and cp <= 0x2B81F) or #
|
||||
(cp >= 0x2B820 and cp <= 0x2CEAF) or
|
||||
(cp >= 0xF900 and cp <= 0xFAFF) or #
|
||||
(cp >= 0x2F800 and cp <= 0x2FA1F)): #
|
||||
return True
|
||||
|
||||
return False
|
||||
|
||||
def _clean_text(self, text):
|
||||
"""Performs invalid character removal and whitespace cleanup on text."""
|
||||
output = []
|
||||
for char in text:
|
||||
cp = ord(char)
|
||||
if cp == 0 or cp == 0xfffd or _is_control(char):
|
||||
continue
|
||||
if _is_whitespace(char):
|
||||
output.append(" ")
|
||||
else:
|
||||
output.append(char)
|
||||
return "".join(output)
|
||||
|
||||
|
||||
class WordpieceTokenizer(object):
|
||||
"""Runs WordPiece tokenziation."""
|
||||
|
||||
def __init__(self, vocab, unk_token="[UNK]", max_input_chars_per_word=100):
|
||||
self.vocab = vocab
|
||||
self.unk_token = unk_token
|
||||
self.max_input_chars_per_word = max_input_chars_per_word
|
||||
|
||||
def tokenize(self, text):
|
||||
"""Tokenizes a piece of text into its word pieces.
|
||||
|
||||
This uses a greedy longest-match-first algorithm to perform tokenization
|
||||
using the given vocabulary.
|
||||
|
||||
For example:
|
||||
input = "unaffable"
|
||||
output = ["un", "##aff", "##able"]
|
||||
|
||||
Args:
|
||||
text: A single token or whitespace separated tokens. This should have
|
||||
already been passed through `BasicTokenizer.
|
||||
|
||||
Returns:
|
||||
A list of wordpiece tokens.
|
||||
"""
|
||||
|
||||
text = convert_to_unicode(text)
|
||||
|
||||
output_tokens = []
|
||||
for token in whitespace_tokenize(text):
|
||||
chars = list(token)
|
||||
if len(chars) > self.max_input_chars_per_word:
|
||||
output_tokens.append(self.unk_token)
|
||||
continue
|
||||
|
||||
is_bad = False
|
||||
start = 0
|
||||
sub_tokens = []
|
||||
while start < len(chars):
|
||||
end = len(chars)
|
||||
cur_substr = None
|
||||
while start < end:
|
||||
substr = "".join(chars[start:end])
|
||||
if start > 0:
|
||||
substr = "##" + substr
|
||||
if substr in self.vocab:
|
||||
cur_substr = substr
|
||||
break
|
||||
end -= 1
|
||||
if cur_substr is None:
|
||||
is_bad = True
|
||||
break
|
||||
sub_tokens.append(cur_substr)
|
||||
start = end
|
||||
|
||||
if is_bad:
|
||||
output_tokens.append(self.unk_token)
|
||||
else:
|
||||
output_tokens.extend(sub_tokens)
|
||||
return output_tokens
|
||||
|
||||
|
||||
def _is_whitespace(char):
|
||||
"""Checks whether `chars` is a whitespace character."""
|
||||
# \t, \n, and \r are technically contorl characters but we treat them
|
||||
# as whitespace since they are generally considered as such.
|
||||
if char == " " or char == "\t" or char == "\n" or char == "\r":
|
||||
return True
|
||||
cat = unicodedata.category(char)
|
||||
if cat == "Zs":
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def _is_control(char):
|
||||
"""Checks whether `chars` is a control character."""
|
||||
# These are technically control characters but we count them as whitespace
|
||||
# characters.
|
||||
if char == "\t" or char == "\n" or char == "\r":
|
||||
return False
|
||||
cat = unicodedata.category(char)
|
||||
if cat.startswith("C"):
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def _is_punctuation(char):
|
||||
"""Checks whether `chars` is a punctuation character."""
|
||||
cp = ord(char)
|
||||
# We treat all non-letter/number ASCII as punctuation.
|
||||
# Characters such as "^", "$", and "`" are not in the Unicode
|
||||
# Punctuation class but we treat them as punctuation anyways, for
|
||||
# consistency.
|
||||
if ((cp >= 33 and cp <= 47) or (cp >= 58 and cp <= 64)
|
||||
or (cp >= 91 and cp <= 96) or (cp >= 123 and cp <= 126)):
|
||||
return True
|
||||
cat = unicodedata.category(char)
|
||||
if cat.startswith("P"):
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def tokenize_chinese_chars(text):
|
||||
"""Adds whitespace around any CJK character."""
|
||||
|
||||
def _is_chinese_char(cp):
|
||||
"""Checks whether CP is the codepoint of a CJK character."""
|
||||
# This defines a "chinese character" as anything in the CJK Unicode block:
|
||||
# https://en.wikipedia.org/wiki/CJK_Unified_Ideographs_(Unicode_block)
|
||||
#
|
||||
# Note that the CJK Unicode block is NOT all Japanese and Korean characters,
|
||||
# despite its name. The modern Korean Hangul alphabet is a different block,
|
||||
# as is Japanese Hiragana and Katakana. Those alphabets are used to write
|
||||
# space-separated words, so they are not treated specially and handled
|
||||
# like the all of the other languages.
|
||||
if ((cp >= 0x4E00 and cp <= 0x9FFF) or #
|
||||
(cp >= 0x3400 and cp <= 0x4DBF) or #
|
||||
(cp >= 0x20000 and cp <= 0x2A6DF) or #
|
||||
(cp >= 0x2A700 and cp <= 0x2B73F) or #
|
||||
(cp >= 0x2B740 and cp <= 0x2B81F) or #
|
||||
(cp >= 0x2B820 and cp <= 0x2CEAF) or
|
||||
(cp >= 0xF900 and cp <= 0xFAFF) or #
|
||||
(cp >= 0x2F800 and cp <= 0x2FA1F)): #
|
||||
return True
|
||||
|
||||
return False
|
||||
|
||||
def _is_whitespace(c):
|
||||
if c == " " or c == "\t" or c == "\r" or c == "\n" or ord(c) == 0x202F:
|
||||
return True
|
||||
return False
|
||||
|
||||
output = []
|
||||
buff = ""
|
||||
for char in text:
|
||||
cp = ord(char)
|
||||
if _is_chinese_char(cp) or _is_whitespace(char):
|
||||
if buff != "":
|
||||
output.append(buff)
|
||||
buff = ""
|
||||
output.append(char)
|
||||
else:
|
||||
buff += char
|
||||
|
||||
if buff != "":
|
||||
output.append(buff)
|
||||
|
||||
return output
|
||||
392
applications/document_intelligence/doc_vqa/Rerank/src/train_ce.py
Executable file
392
applications/document_intelligence/doc_vqa/Rerank/src/train_ce.py
Executable file
@@ -0,0 +1,392 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""Finetuning on classification tasks."""
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
from __future__ import absolute_import
|
||||
|
||||
import os
|
||||
import time
|
||||
import logging
|
||||
import warnings
|
||||
import multiprocessing
|
||||
|
||||
# NOTE(paddle-dev): All of these flags should be
|
||||
# set before `import paddle`. Otherwise, it would
|
||||
# not take any effect.
|
||||
os.environ['FLAGS_eager_delete_tensor_gb'] = '0' # enable gc
|
||||
|
||||
import paddle
|
||||
import paddle.fluid as fluid
|
||||
if hasattr(paddle, 'enable_static'):
|
||||
paddle.enable_static()
|
||||
from paddle.fluid.incubate.fleet.collective import fleet, DistributedStrategy
|
||||
import paddle.fluid.incubate.fleet.base.role_maker as role_maker
|
||||
|
||||
import reader_ce as reader_ce
|
||||
from model.ernie import ErnieConfig
|
||||
from cross_encoder import create_model, evaluate, predict
|
||||
from optimization import optimization
|
||||
from utils.args import print_arguments, check_cuda, prepare_logger
|
||||
from utils.init import init_pretraining_params, init_checkpoint
|
||||
from finetune_args import parser
|
||||
|
||||
warnings.filterwarnings("ignore")
|
||||
args = parser.parse_args()
|
||||
log = logging.getLogger()
|
||||
|
||||
|
||||
def main(args):
|
||||
ernie_config = ErnieConfig(args.ernie_config_path)
|
||||
ernie_config.print_config()
|
||||
|
||||
if args.use_cuda:
|
||||
dev_list = fluid.cuda_places()
|
||||
place = dev_list[0]
|
||||
dev_count = len(dev_list)
|
||||
else:
|
||||
place = fluid.CPUPlace()
|
||||
dev_count = int(os.environ.get('CPU_NUM', multiprocessing.cpu_count()))
|
||||
exe = fluid.Executor(place)
|
||||
|
||||
reader = reader_ce.ClassifyReader(vocab_path=args.vocab_path,
|
||||
label_map_config=args.label_map_config,
|
||||
max_seq_len=args.max_seq_len,
|
||||
total_num=args.train_data_size,
|
||||
do_lower_case=args.do_lower_case,
|
||||
in_tokens=args.in_tokens,
|
||||
random_seed=args.random_seed,
|
||||
tokenizer=args.tokenizer,
|
||||
for_cn=args.for_cn,
|
||||
task_id=args.task_id)
|
||||
|
||||
if not (args.do_train or args.do_val or args.do_test):
|
||||
raise ValueError("For args `do_train`, `do_val` and `do_test`, at "
|
||||
"least one of them must be True.")
|
||||
|
||||
if args.do_test:
|
||||
assert args.test_save is not None
|
||||
startup_prog = fluid.Program()
|
||||
if args.random_seed is not None:
|
||||
startup_prog.random_seed = args.random_seed
|
||||
|
||||
if args.predict_batch_size == None:
|
||||
args.predict_batch_size = args.batch_size
|
||||
|
||||
if args.do_train:
|
||||
role = role_maker.PaddleCloudRoleMaker(is_collective=True)
|
||||
fleet.init(role)
|
||||
dev_count = fleet.worker_num()
|
||||
|
||||
train_data_generator = reader.data_generator(
|
||||
input_file=args.train_set,
|
||||
batch_size=args.batch_size,
|
||||
epoch=args.epoch,
|
||||
dev_count=1,
|
||||
trainer_id=fleet.worker_index(),
|
||||
trainer_num=fleet.worker_num(),
|
||||
shuffle=True,
|
||||
phase="train")
|
||||
|
||||
num_train_examples = reader.get_num_examples(args.train_set)
|
||||
|
||||
if args.in_tokens:
|
||||
max_train_steps = args.epoch * num_train_examples // (
|
||||
args.batch_size // args.max_seq_len) // dev_count
|
||||
else:
|
||||
max_train_steps = args.epoch * num_train_examples // args.batch_size // dev_count
|
||||
|
||||
warmup_steps = int(max_train_steps * args.warmup_proportion)
|
||||
log.info("Device count: %d" % dev_count)
|
||||
log.info("Num train examples: %d" % num_train_examples)
|
||||
log.info("Max train steps: %d" % max_train_steps)
|
||||
log.info("Num warmup steps: %d" % warmup_steps)
|
||||
|
||||
train_program = fluid.Program()
|
||||
|
||||
# use fleet api
|
||||
exec_strategy = fluid.ExecutionStrategy()
|
||||
if args.use_fast_executor:
|
||||
exec_strategy.use_experimental_executor = True
|
||||
exec_strategy.num_threads = dev_count
|
||||
if args.is_distributed:
|
||||
exec_strategy.num_threads = 3
|
||||
|
||||
exec_strategy.num_iteration_per_drop_scope = args.num_iteration_per_drop_scope
|
||||
|
||||
dist_strategy = DistributedStrategy()
|
||||
dist_strategy.exec_strategy = exec_strategy
|
||||
dist_strategy.nccl_comm_num = 1
|
||||
if args.is_distributed:
|
||||
dist_strategy.nccl_comm_num = 2
|
||||
dist_strategy.use_hierarchical_allreduce = True
|
||||
|
||||
if args.use_mix_precision:
|
||||
dist_strategy.use_amp = True
|
||||
|
||||
with fluid.program_guard(train_program, startup_prog):
|
||||
with fluid.unique_name.guard():
|
||||
train_pyreader, graph_vars = create_model(
|
||||
args,
|
||||
pyreader_name='train_reader',
|
||||
ernie_config=ernie_config)
|
||||
scheduled_lr = optimization(
|
||||
loss=graph_vars["loss"],
|
||||
warmup_steps=warmup_steps,
|
||||
num_train_steps=max_train_steps,
|
||||
learning_rate=args.learning_rate,
|
||||
train_program=train_program,
|
||||
startup_prog=startup_prog,
|
||||
weight_decay=args.weight_decay,
|
||||
scheduler=args.lr_scheduler,
|
||||
use_dynamic_loss_scaling=args.use_dynamic_loss_scaling,
|
||||
incr_every_n_steps=args.incr_every_n_steps,
|
||||
decr_every_n_nan_or_inf=args.decr_every_n_nan_or_inf,
|
||||
incr_ratio=args.incr_ratio,
|
||||
decr_ratio=args.decr_ratio,
|
||||
dist_strategy=dist_strategy)
|
||||
|
||||
if args.verbose:
|
||||
if args.in_tokens:
|
||||
lower_mem, upper_mem, unit = fluid.contrib.memory_usage(
|
||||
program=train_program,
|
||||
batch_size=args.batch_size // args.max_seq_len)
|
||||
else:
|
||||
lower_mem, upper_mem, unit = fluid.contrib.memory_usage(
|
||||
program=train_program, batch_size=args.batch_size)
|
||||
log.info("Theoretical memory usage in training: %.3f - %.3f %s" %
|
||||
(lower_mem, upper_mem, unit))
|
||||
|
||||
if args.do_val or args.do_test:
|
||||
test_prog = fluid.Program()
|
||||
with fluid.program_guard(test_prog, startup_prog):
|
||||
with fluid.unique_name.guard():
|
||||
test_pyreader, graph_vars = create_model(
|
||||
args,
|
||||
pyreader_name='test_reader',
|
||||
ernie_config=ernie_config,
|
||||
is_prediction=True)
|
||||
|
||||
test_prog = test_prog.clone(for_test=True)
|
||||
|
||||
train_program = fleet.main_program
|
||||
|
||||
exe = fluid.Executor(place)
|
||||
exe.run(startup_prog)
|
||||
|
||||
if args.do_train:
|
||||
if args.init_checkpoint and args.init_pretraining_params:
|
||||
log.warning(
|
||||
"WARNING: args 'init_checkpoint' and 'init_pretraining_params' "
|
||||
"both are set! Only arg 'init_checkpoint' is made valid.")
|
||||
if args.init_checkpoint:
|
||||
init_checkpoint(exe,
|
||||
args.init_checkpoint,
|
||||
main_program=startup_prog)
|
||||
elif args.init_pretraining_params:
|
||||
init_pretraining_params(exe,
|
||||
args.init_pretraining_params,
|
||||
main_program=startup_prog)
|
||||
elif args.do_val or args.do_test:
|
||||
if not args.init_checkpoint:
|
||||
raise ValueError("args 'init_checkpoint' should be set if"
|
||||
"only doing validation or testing!")
|
||||
init_checkpoint(exe, args.init_checkpoint, main_program=startup_prog)
|
||||
|
||||
if args.do_train:
|
||||
train_exe = exe
|
||||
train_pyreader.decorate_tensor_provider(train_data_generator)
|
||||
else:
|
||||
train_exe = None
|
||||
|
||||
test_exe = exe
|
||||
|
||||
current_epoch = 0
|
||||
steps = 0
|
||||
if args.do_train:
|
||||
train_pyreader.start()
|
||||
if warmup_steps > 0:
|
||||
graph_vars["learning_rate"] = scheduled_lr
|
||||
|
||||
ce_info = []
|
||||
time_begin = time.time()
|
||||
last_epoch = 0
|
||||
while True:
|
||||
try:
|
||||
steps += 1
|
||||
|
||||
if fleet.worker_index() != 0:
|
||||
train_exe.run(fetch_list=[], program=train_program)
|
||||
continue
|
||||
|
||||
if steps % args.skip_steps != 0:
|
||||
train_exe.run(fetch_list=[], program=train_program)
|
||||
|
||||
else:
|
||||
outputs = evaluate(train_exe,
|
||||
train_program,
|
||||
train_pyreader,
|
||||
graph_vars,
|
||||
"train",
|
||||
metric=args.metric)
|
||||
|
||||
if args.verbose:
|
||||
verbose = "train pyreader queue size: %d, " % train_pyreader.queue.size(
|
||||
)
|
||||
verbose += "learning rate: %f" % (
|
||||
outputs["learning_rate"]
|
||||
if warmup_steps > 0 else args.learning_rate)
|
||||
log.info(verbose)
|
||||
|
||||
current_example, current_epoch = reader.get_train_progress()
|
||||
time_end = time.time()
|
||||
used_time = time_end - time_begin
|
||||
|
||||
log.info(
|
||||
"epoch: %d, progress: %d/%d, step: %d, ave loss: %f, "
|
||||
"ave acc: %f, speed: %f steps/s" %
|
||||
(current_epoch, current_example * dev_count,
|
||||
num_train_examples, steps, outputs["loss"],
|
||||
outputs["accuracy"], args.skip_steps / used_time))
|
||||
ce_info.append(
|
||||
[outputs["loss"], outputs["accuracy"], used_time])
|
||||
|
||||
time_begin = time.time()
|
||||
|
||||
if steps % args.save_steps == 0:
|
||||
save_path = os.path.join(args.checkpoints,
|
||||
"step_" + str(steps))
|
||||
fluid.io.save_persistables(exe, save_path,
|
||||
fleet._origin_program)
|
||||
|
||||
if steps % args.validation_steps == 0:
|
||||
# evaluate dev set
|
||||
if args.do_val:
|
||||
evaluate_wrapper(args, reader, exe, test_prog,
|
||||
test_pyreader, graph_vars,
|
||||
current_epoch, steps)
|
||||
|
||||
if args.do_test:
|
||||
predict_wrapper(args, reader, exe, test_prog,
|
||||
test_pyreader, graph_vars,
|
||||
current_epoch, steps)
|
||||
|
||||
if last_epoch != current_epoch:
|
||||
last_epoch = current_epoch
|
||||
|
||||
except fluid.core.EOFException:
|
||||
save_path = os.path.join(args.checkpoints, "step_" + str(steps))
|
||||
fluid.io.save_persistables(exe, save_path,
|
||||
fleet._origin_program)
|
||||
train_pyreader.reset()
|
||||
break
|
||||
|
||||
# final eval on dev set
|
||||
if args.do_val:
|
||||
evaluate_wrapper(args, reader, exe, test_prog, test_pyreader,
|
||||
graph_vars, current_epoch, steps)
|
||||
|
||||
# final eval on test set
|
||||
if args.do_test:
|
||||
predict_wrapper(args, reader, exe, test_prog, test_pyreader, graph_vars)
|
||||
|
||||
# final eval on dianostic, hack for glue-ax
|
||||
if args.diagnostic:
|
||||
test_pyreader.decorate_tensor_provider(
|
||||
reader.data_generator(args.diagnostic,
|
||||
batch_size=args.batch_size,
|
||||
epoch=1,
|
||||
dev_count=1,
|
||||
shuffle=False))
|
||||
|
||||
log.info("Final diagnostic")
|
||||
qids, preds, probs = predict(test_exe, test_prog, test_pyreader,
|
||||
graph_vars)
|
||||
assert len(qids) == len(preds), '{} v.s. {}'.format(
|
||||
len(qids), len(preds))
|
||||
with open(args.diagnostic_save, 'w') as f:
|
||||
for id, s, p in zip(qids, preds, probs):
|
||||
f.write('{}\t{}\t{}\n'.format(id, s, p))
|
||||
|
||||
log.info("Done final diagnostic, saving to {}".format(
|
||||
args.diagnostic_save))
|
||||
|
||||
|
||||
def evaluate_wrapper(args, reader, exe, test_prog, test_pyreader, graph_vars,
|
||||
epoch, steps):
|
||||
# evaluate dev set
|
||||
for ds in args.dev_set.split(','):
|
||||
test_pyreader.decorate_tensor_provider(
|
||||
reader.data_generator(ds,
|
||||
batch_size=args.predict_batch_size,
|
||||
epoch=1,
|
||||
dev_count=1,
|
||||
shuffle=False))
|
||||
log.info("validation result of dataset {}:".format(ds))
|
||||
evaluate_info = evaluate(exe,
|
||||
test_prog,
|
||||
test_pyreader,
|
||||
graph_vars,
|
||||
"dev",
|
||||
metric=args.metric)
|
||||
log.info(evaluate_info +
|
||||
', file: {}, epoch: {}, steps: {}'.format(ds, epoch, steps))
|
||||
|
||||
|
||||
def predict_wrapper(args,
|
||||
reader,
|
||||
exe,
|
||||
test_prog,
|
||||
test_pyreader,
|
||||
graph_vars,
|
||||
epoch=None,
|
||||
steps=None):
|
||||
test_sets = args.test_set.split(',')
|
||||
save_dirs = args.test_save.split(',')
|
||||
assert len(test_sets) == len(save_dirs)
|
||||
|
||||
for test_f, save_f in zip(test_sets, save_dirs):
|
||||
test_pyreader.decorate_tensor_provider(
|
||||
reader.data_generator(test_f,
|
||||
batch_size=args.predict_batch_size,
|
||||
epoch=1,
|
||||
dev_count=1,
|
||||
shuffle=False))
|
||||
|
||||
if epoch is not None or steps is not None:
|
||||
save_path = save_f + '.' + str(epoch) + '.' + str(steps)
|
||||
else:
|
||||
save_path = save_f
|
||||
log.info("testing {}, save to {}".format(test_f, save_path))
|
||||
qids, preds, probs = predict(exe, test_prog, test_pyreader, graph_vars)
|
||||
|
||||
save_dir = os.path.dirname(save_path)
|
||||
if not os.path.exists(save_dir):
|
||||
os.makedirs(save_dir)
|
||||
else:
|
||||
log.warning('save dir exsits: %s, will skip saving' % save_dir)
|
||||
|
||||
with open(save_path, 'w') as f:
|
||||
for p in probs:
|
||||
f.write('{}\n'.format(p[1]))
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
prepare_logger(log)
|
||||
print_arguments(args)
|
||||
check_cuda(args.use_cuda)
|
||||
main(args)
|
||||
91
applications/document_intelligence/doc_vqa/Rerank/src/utils/args.py
Executable file
91
applications/document_intelligence/doc_vqa/Rerank/src/utils/args.py
Executable file
@@ -0,0 +1,91 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""Arguments for configuration."""
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
from __future__ import absolute_import
|
||||
|
||||
import six
|
||||
import os
|
||||
import sys
|
||||
import argparse
|
||||
import logging
|
||||
|
||||
import paddle.fluid as fluid
|
||||
|
||||
log = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def prepare_logger(logger, debug=False, save_to_file=None):
|
||||
formatter = logging.Formatter(
|
||||
fmt=
|
||||
'[%(levelname)s] %(asctime)s [%(filename)12s:%(lineno)5d]:\t%(message)s'
|
||||
)
|
||||
console_hdl = logging.StreamHandler()
|
||||
console_hdl.setFormatter(formatter)
|
||||
logger.addHandler(console_hdl)
|
||||
if save_to_file is not None and not os.path.exists(save_to_file):
|
||||
file_hdl = logging.FileHandler(save_to_file)
|
||||
file_hdl.setFormatter(formatter)
|
||||
logger.addHandler(file_hdl)
|
||||
logger.setLevel(logging.DEBUG)
|
||||
logger.propagate = False
|
||||
|
||||
|
||||
def str2bool(v):
|
||||
# because argparse does not support to parse "true, False" as python
|
||||
# boolean directly
|
||||
return v.lower() in ("true", "t", "1")
|
||||
|
||||
|
||||
class ArgumentGroup(object):
|
||||
|
||||
def __init__(self, parser, title, des):
|
||||
self._group = parser.add_argument_group(title=title, description=des)
|
||||
|
||||
def add_arg(self,
|
||||
name,
|
||||
type,
|
||||
default,
|
||||
help,
|
||||
positional_arg=False,
|
||||
**kwargs):
|
||||
prefix = "" if positional_arg else "--"
|
||||
type = str2bool if type == bool else type
|
||||
self._group.add_argument(prefix + name,
|
||||
default=default,
|
||||
type=type,
|
||||
help=help + ' Default: %(default)s.',
|
||||
**kwargs)
|
||||
|
||||
|
||||
def print_arguments(args):
|
||||
log.info('----------- Configuration Arguments -----------')
|
||||
for arg, value in sorted(six.iteritems(vars(args))):
|
||||
log.info('%s: %s' % (arg, value))
|
||||
log.info('------------------------------------------------')
|
||||
|
||||
|
||||
def check_cuda(use_cuda, err = \
|
||||
"\nYou can not set use_cuda = True in the model because you are using paddlepaddle-cpu.\n \
|
||||
Please: 1. Install paddlepaddle-gpu to run your models on GPU or 2. Set use_cuda = False to run models on CPU.\n"
|
||||
):
|
||||
try:
|
||||
if use_cuda == True and fluid.is_compiled_with_cuda() == False:
|
||||
log.error(err)
|
||||
sys.exit(1)
|
||||
except Exception as e:
|
||||
pass
|
||||
73
applications/document_intelligence/doc_vqa/Rerank/src/utils/init.py
Executable file
73
applications/document_intelligence/doc_vqa/Rerank/src/utils/init.py
Executable file
@@ -0,0 +1,73 @@
|
||||
# Copyright (c) 2019 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
from __future__ import absolute_import
|
||||
|
||||
import os
|
||||
import six
|
||||
import ast
|
||||
import copy
|
||||
import logging
|
||||
import numpy as np
|
||||
|
||||
import paddle.fluid as fluid
|
||||
|
||||
log = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def init_checkpoint(exe, init_checkpoint_path, main_program):
|
||||
assert os.path.exists(
|
||||
init_checkpoint_path), "[%s] cann't be found." % init_checkpoint_path
|
||||
|
||||
def existed_persitables(var):
|
||||
if not fluid.io.is_persistable(var):
|
||||
return False
|
||||
if not os.path.exists(os.path.join(init_checkpoint_path, var.name)):
|
||||
print("Var not exists: [%s]\t%s" %
|
||||
(var.name, os.path.join(init_checkpoint_path, var.name)))
|
||||
#else:
|
||||
# print ("Var exists: [%s]" % (var.name))
|
||||
return os.path.exists(os.path.join(init_checkpoint_path, var.name))
|
||||
|
||||
fluid.io.load_vars(exe,
|
||||
init_checkpoint_path,
|
||||
main_program=main_program,
|
||||
predicate=existed_persitables)
|
||||
log.info("Load model from {}".format(init_checkpoint_path))
|
||||
|
||||
|
||||
def init_pretraining_params(exe, pretraining_params_path, main_program):
|
||||
assert os.path.exists(pretraining_params_path
|
||||
), "[%s] cann't be found." % pretraining_params_path
|
||||
|
||||
def existed_params(var):
|
||||
if not isinstance(var, fluid.framework.Parameter):
|
||||
return False
|
||||
if not os.path.exists(os.path.join(pretraining_params_path, var.name)):
|
||||
print("Var not exists: [%s]\t%s" %
|
||||
(var.name, os.path.join(pretraining_params_path, var.name)))
|
||||
#else:
|
||||
# print ("Var exists: [%s]" % (var.name))
|
||||
return os.path.exists(os.path.join(pretraining_params_path, var.name))
|
||||
|
||||
fluid.io.load_vars(exe,
|
||||
pretraining_params_path,
|
||||
main_program=main_program,
|
||||
predicate=existed_params)
|
||||
log.info(
|
||||
"Load pretraining parameters from {}.".format(pretraining_params_path))
|
||||
34
applications/document_intelligence/doc_vqa/run_test.sh
Normal file
34
applications/document_intelligence/doc_vqa/run_test.sh
Normal file
@@ -0,0 +1,34 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
QUESTION=$1
|
||||
|
||||
# Question: NFC咋开门
|
||||
|
||||
if [ $# != 1 ];then
|
||||
echo "USAGE: sh script/run_cross_encoder_test.sh \$QUESTION"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# compute scores for QUESTION and OCR parsing results with Rerank module
|
||||
cd Rerank
|
||||
bash run_test.sh ${QUESTION}
|
||||
cd ..
|
||||
|
||||
# extraction answer for QUESTION from the top1 of rank
|
||||
cd Extraction
|
||||
bash run_test.sh ${QUESTION}
|
||||
cd ..
|
||||
1
applications/document_intelligence/docprompt
Symbolic link
1
applications/document_intelligence/docprompt
Symbolic link
@@ -0,0 +1 @@
|
||||
../../model_zoo/ernie-layout
|
||||
495
applications/neural_search/README.md
Normal file
495
applications/neural_search/README.md
Normal file
@@ -0,0 +1,495 @@
|
||||
# 手把手搭建一个语义检索系统
|
||||
|
||||
## 1. 场景概述
|
||||
|
||||
检索系统存在于我们日常使用的很多产品中,比如商品搜索系统、学术文献检索系等等,本方案提供了检索系统完整实现。限定场景是用户通过输入检索词 Query,快速在海量数据中查找相似文档。
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/12107462/191490721-90a8f526-ad64-4f2b-b9b4-34ab06c6749b.png" width="500px">
|
||||
</div>
|
||||
|
||||
所谓语义检索(也称基于向量的检索,如上图所示),是指检索系统不再拘泥于用户 Query 字面本身,而是能精准捕捉到用户 Query 后面的真正意图并以此来搜索,从而更准确地向用户返回最符合的结果。通过使用最先进的语义索引模型找到文本的向量表示,在高维向量空间中对它们进行索引,并度量查询向量与索引文档的相似程度,从而解决了关键词索引带来的缺陷。
|
||||
|
||||
例如下面两组文本 Pair,如果基于关键词去计算相似度,两组的相似度是相同的。而从实际语义上看,第一组相似度高于第二组。
|
||||
|
||||
```
|
||||
车头如何放置车牌 前牌照怎么装
|
||||
车头如何放置车牌 后牌照怎么装
|
||||
```
|
||||
|
||||
语义检索系统的关键就在于,采用语义而非关键词方式进行召回,达到更精准、更广泛得召回相似结果的目的。想快速体验搜索的效果,请参考[Pipelines的实现](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/pipelines)
|
||||
|
||||
## 2. 产品功能介绍
|
||||
|
||||
通常检索业务的数据都比较庞大,都会分为召回(索引)、排序两个环节。召回阶段主要是从至少千万级别的候选集合里面,筛选出相关的文档,这样候选集合的数目就会大大降低,在之后的排序阶段就可以使用一些复杂的模型做精细化或者个性化的排序。一般采用多路召回策略(例如关键词召回、热点召回、语义召回结合等),多路召回结果聚合后,经过统一的打分以后选出最优的 TopK 的结果。
|
||||
|
||||
### 2.1 系统特色
|
||||
|
||||
+ 低门槛
|
||||
+ 手把手搭建起检索系统
|
||||
+ 无需标注数据也能构建检索系统
|
||||
+ 提供 训练、预测、ANN 引擎一站式能力
|
||||
|
||||
+ 效果好
|
||||
+ 针对多种数据场景的专业方案
|
||||
+ 仅有无监督数据: SimCSE
|
||||
+ 仅有有监督数据: InBatchNegative
|
||||
+ 兼具无监督数据 和 有监督数据:融合模型
|
||||
+ 进一步优化方案: 面向领域的预训练 Domain-adaptive Pretraining
|
||||
+ 性能快
|
||||
+ Paddle Inference 快速抽取向量
|
||||
+ Milvus 快速查询和高性能建库
|
||||
+ Paddle Serving服务化部署
|
||||
|
||||
### 2.2 功能架构
|
||||
|
||||
索引环节有两类方法:基于字面的关键词索引;语义索引。语义索引能够较好地表征语义信息,解决字面不相似但语义相似的情形。本系统给出的是语义索引方案,实际业务中可融合其他方案使用。下面就详细介绍整个方案的架构和功能。
|
||||
|
||||
#### 2.2.1 整体介绍
|
||||
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/12107462/191469309-42a54a67-a3a3-4e43-b6b1-b12be81ddf3d.png" width="800px">
|
||||
</div>
|
||||
|
||||
以上是nerual_search的系统流程图,其中左侧为召回环节,核心是语义向量抽取模块;右侧是排序环节,核心是排序模型。召回环节需要用户通过自己的语料构建向量索引库,用户发起query了之后,就可以检索出相似度最高的向量,然后找出该向量对应的文本;排序环节主要是对召回的文本进行重新排序。下面我们分别介绍召回中的语义向量抽取模块,以及排序模型。
|
||||
|
||||
|
||||
#### 2.2.2 召回模块
|
||||
|
||||
召回模块需要从千万量级数据中快速召回候选数据。首先需要抽取语料库中文本的 Embedding,然后借助向量搜索引擎实现高效 ANN,从而实现候选集召回。
|
||||
|
||||
我们针对不同的数据情况推出三种语义索引方案,如下图所示,您可以参照此方案,快速建立语义索引:
|
||||
|
||||
| ⭐️ 无监督数据 | ⭐️ 有监督数据 | **召回方案** |
|
||||
| ------------ | ------------ | ------------ |
|
||||
| 多 | 无 | SimCSE |
|
||||
| 无 | 多 | In-batch Negatives|
|
||||
| 有 | 有 | SimCSE+ In-batch Negatives |
|
||||
|
||||
最基本的情况是只有无监督数据,我们推荐您使用 SimCSE 进行无监督训练;另一种方案是只有有监督数据,我们推荐您使用 In-batch Negatives 的方法进行有监督训练。
|
||||
|
||||
如果想进一步提升模型效果:还可以使用大规模业务数据,对预训练模型进行 Domain-adaptive Pretraining,训练完以后得到预训练模型,再进行无监督的 SimCSE。
|
||||
|
||||
此外,如果您同时拥有监督数据和无监督数据,我们推荐将两种方案结合使用,这样能训练出更加强大的语义索引模型。
|
||||
|
||||
#### 2.2.3 排序模块
|
||||
|
||||
召回模型负责从海量(千万级)候选文本中快速(毫秒级)筛选出与 Query 相关性较高的 TopK Doc,排序模型会在召回模型筛选出的 TopK Doc 结果基础之上针对每一个 (Query, Doc) Pair 对进行两两匹配计算相关性,排序效果更精准。
|
||||
|
||||
排序模块有2种选择,第一种基于前沿的预训练模型 ERNIE,训练 Pair-wise 语义匹配模型;第二种是基于RocketQA模型训练的Cross Encoder模形。第一种是Pair-wise的排序算法,基本思路是对样本构建偏序文档对,两两比较,从比较中学习顺序,第二种是Poinet-Wise的算法,只考虑当前Query和每个文档的绝对相关度,并没有考虑其他文档与Query的相关度,但是建模方式比较简单。第一种Pair-wise模型可以说是第二种point-wise模型的改进版本,但对于噪声数据更为敏感,即一个错误的标注会导致多个pair对的错误,用户可以先使用基于Point-wise的Cross Encoder构建一个基础模型,需要进一步优化可以使用Pair-wise的方法优化。
|
||||
|
||||
## 3. 文献检索实践
|
||||
|
||||
### 3.1 技术方案和评估指标
|
||||
|
||||
#### 3.1.1 技术方案
|
||||
|
||||
**语义索引**:由于我们既有无监督数据,又有有监督数据,所以结合 SimCSE 和 In-batch Negatives 方案,并采取 Domain-adaptive Pretraining 优化模型效果。
|
||||
|
||||
首先是利用 ERNIE模型进行 Domain-adaptive Pretraining,在得到的预训练模型基础上,进行无监督的 SimCSE 训练,最后利用 In-batch Negatives 方法进行微调,得到最终的语义索引模型,把建库的文本放入模型中抽取特征向量,然后把抽取后的向量放到语义索引引擎 milvus 中,利用 milvus 就可以很方便得实现召回了。
|
||||
|
||||
**排序**:使用 ERNIE-Gram 的单塔结构/RocketQA的Cross Encoder对召回后的数据精排序。
|
||||
|
||||
#### 3.1.2 评估指标
|
||||
|
||||
**模型效果指标**
|
||||
* 在语义索引召回阶段使用的指标是 Recall@K,表示的是预测的前topK(从最后的按得分排序的召回列表中返回前K个结果)结果和语料库中真实的前 K 个相关结果的重叠率,衡量的是检索系统的查全率。
|
||||
|
||||
* 在排序阶段使用的指标为AUC,AUC反映的是分类器对样本的排序能力,如果完全随机得对样本分类,那么AUC应该接近0.5。分类器越可能把真正的正样本排在前面,AUC越大,分类性能越好。
|
||||
|
||||
**性能指标**
|
||||
* 基于 Paddle Inference 快速抽取向量
|
||||
|
||||
* 建库性能和 ANN 查询性能快
|
||||
|
||||
### 3.2 预置数据说明
|
||||
|
||||
数据集来源于某文献检索系统,既有大量无监督数据,又有有监督数据。
|
||||
|
||||
(1)采用文献的 query, title,keywords,abstract 四个字段内容,构建无标签数据集进行 Domain-adaptive Pretraining;
|
||||
|
||||
(2)采用文献的 query,title,keywords 三个字段内容,构造无标签数据集,进行无监督召回训练SimCSE;
|
||||
|
||||
(3)使用文献的的query, title, keywords,构造带正标签的数据集,不包含负标签样本,基于 In-batch Negatives 策略进行训练;
|
||||
|
||||
(4)在排序阶段,使用点击(作为正样本)和展现未点击(作为负样本)数据构造排序阶段的训练集,进行精排训练。
|
||||
|
||||
| 阶段 |模型 | 训练集 | 评估集(用于评估模型效果) | 召回库 |测试集 |
|
||||
| ------------ | ------------ |------------ | ------------ | ------------ | ------------ |
|
||||
| 召回 | Domain-adaptive Pretraining | 2kw | - | - | - |
|
||||
| 召回 | 无监督预训练 - SimCSE | 798w | 20000 | 300000| 1000 |
|
||||
| 召回 | 有监督训练 - In-batch Negatives | 3998 | 20000 |300000 | 1000 |
|
||||
| 排序 | 有监督训练 - ERNIE-Gram单塔 Pairwise/RocketQA Cross Encoder| 1973538 | 57811 | - | 1000 |
|
||||
|
||||
我们将除 Domain-adaptive Pretraining 之外的其他数据集全部开源,下载地址:
|
||||
|
||||
- [literature_search_data](https://bj.bcebos.com/v1/paddlenlp/data/literature_search_data.zip)
|
||||
- [literature_search_rank](https://paddlenlp.bj.bcebos.com/applications/literature_search_rank.zip)
|
||||
|
||||
```
|
||||
├── milvus # milvus建库数据集
|
||||
├── milvus_data.csv. # 构建召回库的数据(模拟实际业务线上的语料库,实际语料库远大于这里的规模),用于直观演示相关文献召回效果
|
||||
├── recall # 召回阶段数据集
|
||||
├── train_unsupervised.csv # 无监督训练集,用于训练 SimCSE
|
||||
├── train.csv # 有监督训练集,用于训练 In-batch Negative
|
||||
├── dev.csv # 召回阶段验证集,用于评估召回模型的效果,SimCSE 和 In-batch Negative 共用
|
||||
├── corpus.csv # 构建召回库的数据(模拟实际业务线上的语料库,实际语料库远大于这里的规模),用于评估召回阶段模型效果,SimCSE 和 In-batch Negative 共用
|
||||
├── test.csv # 召回阶段测试数据,预测文本之间的相似度,SimCSE 和 In-batch Negative 共用
|
||||
├── data # RocketQA排序数据集
|
||||
├── test.csv # 测试集
|
||||
├── dev_pairwise.csv # 验证集
|
||||
└── train.csv # 训练集
|
||||
├── sort # 排序阶段数据集
|
||||
├── train_pairwise.csv # 排序训练集
|
||||
├── dev_pairwise.csv # 排序验证集
|
||||
└── test_pairwise.csv # 排序测试集
|
||||
```
|
||||
|
||||
|
||||
### 3.3 数据格式
|
||||
|
||||
1. 对于无监督SimCSE的训练方法,格式参考`train_unsupervised.csv`,即一行条文本即可,无需任何标注。对于召回模型训练需要规定格式的本地数据集,需要准备训练集文件`train.csv`,验证集`dev.csv`,召回集文件`corpus.csv`。
|
||||
|
||||
|
||||
训练数据集`train.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t 用户点击的title1
|
||||
query2 \t 用户点击的title2
|
||||
```
|
||||
训练集合`train.csv`的文件样例:
|
||||
```
|
||||
从《唐律疏义》看唐代封爵贵族的法律特权 从《唐律疏义》看唐代封爵贵族的法律特权《唐律疏义》,封爵贵族,法律特权
|
||||
宁夏社区图书馆服务体系布局现状分析 宁夏社区图书馆服务体系布局现状分析社区图书馆,社区图书馆服务,社区图书馆服务体系
|
||||
人口老龄化对京津冀经济 京津冀人口老龄化对区域经济增长的影响京津冀,人口老龄化,区域经济增长,固定效应模型
|
||||
英语广告中的模糊语 模糊语在英语广告中的应用及其功能模糊语,英语广告,表现形式,语用功能
|
||||
甘氨酸二肽的合成 甘氨酸二肽合成中缩合剂的选择甘氨酸,缩合剂,二肽
|
||||
......
|
||||
```
|
||||
|
||||
验证集`dev.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t 用户点击的title1
|
||||
query2 \t 用户点击的title2
|
||||
```
|
||||
|
||||
验证集合`train.csv`的文件样例:
|
||||
```
|
||||
试论我国海岸带经济开发的问题与前景 试论我国海岸带经济开发的问题与前景海岸带,经济开发,问题,前景
|
||||
外语阅读焦虑与英语成绩及性别的关系 外语阅读焦虑与英语成绩及性别的关系外语阅读焦虑,外语课堂焦虑,英语成绩,性别
|
||||
加油站风险分级管控 加油站工作危害风险分级研究加油站,工作危害分析(JHA),风险分级管控
|
||||
```
|
||||
召回集合`corpus.csv`主要作用是检验测试集合的句子对能否被正确召回,它的构造主要是提取验证集的第二列的句子,然后加入很多无关的句子,用来检验模型能够正确的从这些文本中找出测试集合对应的第二列的句子,格式如下:
|
||||
|
||||
```
|
||||
2002-2017年我国法定传染病发病率和死亡率时间变化趋势传染病,发病率,死亡率,病死率
|
||||
陕西省贫困地区城乡青春期少女生长发育调查青春期,生长发育,贫困地区
|
||||
五丈岩水库溢洪道加固工程中的新材料应用碳纤维布,粘钢加固技术,超细水泥,灌浆技术
|
||||
......
|
||||
```
|
||||
|
||||
2. 对于排序模型的训练,排序模型目前提供了2种,第一种是Pairwise训练的方式,第二种是RocketQA的排序模型,对于第一种排序模型,需要准备训练集`train_pairwise.csv`,验证集`dev_pairwise.csv`两个文件,除此之外还可以准备测试集文件`test.csv`或者`test_pairwise.csv`。
|
||||
|
||||
训练数据集`train_pairwise.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t 用户点击的title1 \t 用户未点击的title2
|
||||
query2 \t 用户点击的title3 \t 用户未点击的title4
|
||||
```
|
||||
|
||||
训练数据集`train_pairwise.csv`的示例如下:
|
||||
|
||||
```
|
||||
英语委婉语引起的跨文化交际障碍 英语委婉语引起的跨文化交际障碍及其翻译策略研究英语委婉语,跨文化交际障碍,翻译策略 委婉语在英语和汉语中的文化差异委婉语,文化,跨文化交际
|
||||
范迪慧 嘉兴市中医院 滋阴疏肝汤联合八穴隔姜灸治疗肾虚肝郁型卵巢功能低下的临床疗效滋阴疏肝汤,八穴隔姜灸,肾虚肝郁型卵巢功能低下,性脉甾类激素,妊娠 温针灸、中药薰蒸在半月板损伤术后康复中的疗效分析膝损伤,半月板,胫骨,中医康复,温针疗法,薰洗
|
||||
......
|
||||
```
|
||||
|
||||
验证数据集`dev_pairwise.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t title1 \t label
|
||||
query2 \t title2 \t label
|
||||
```
|
||||
验证数据集`dev_pairwise.csv`的示例如下:
|
||||
|
||||
```
|
||||
作者单位:南州中学 浅谈初中教学管理如何体现人文关怀初中教育,教学管理,人文关怀 1
|
||||
作者单位:南州中学 高中美术课堂教学中藏区本土民间艺术的融入路径藏区,传统民间艺术,美术课堂 0
|
||||
作者单位:南州中学 列宁关于资产阶级民主革命向 社会主义革命过渡的理论列宁,直接过渡,间接过渡,资产阶级民主革命,社会主义革命 0
|
||||
DAA髋关节置换 DAA前侧入路和后外侧入路髋关节置换疗效对比髋关节置换术;直接前侧入路;后外侧入路;髋关节功能;疼痛;并发症 1
|
||||
DAA髋关节置换 DAA全髋关节置换术治疗髋关节病变对患者髋关节运动功能的影响直接前侧入路全髋关节置换术,髋关节病变,髋关节运动功能 0
|
||||
DAA髋关节置换 护患沟通技巧在急诊输液护理中的应用分析急诊科,输液护理,护理沟通技巧,应用 0
|
||||
.......
|
||||
```
|
||||
训练数据集`test_pairwise.csv`的格式如下,其中这个score得分是召回算出来的相似度或者距离,仅供参考,可以忽略:
|
||||
|
||||
```
|
||||
query1 \t title1 \t score
|
||||
query2 \t title2 \t score
|
||||
```
|
||||
训练数据集`test_pairwise.csv`的示例如下:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异 中西方文化差异以及语言体现中西方文化,差异,语言体现 0.43203747272491455
|
||||
中西方语言与文化的差异 论中西方文化差异在非言语交际中的体现中西方文化,差异,非言语交际 0.4644506871700287
|
||||
中西方语言与文化的差异 中西方体态语文化差异跨文化,体态语,非语言交际,差异 0.4917311668395996
|
||||
中西方语言与文化的差异 由此便可以发现两种语言以及两种文化的差异。 0.5039259195327759
|
||||
.......
|
||||
```
|
||||
|
||||
对于第二种基于RocketQA的排序模型。
|
||||
|
||||
训练数据集`train.csv`,验证集`dev_pairwise.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t title1 \t label
|
||||
query2 \t title2 \t label
|
||||
```
|
||||
训练数据集`train.csv`,验证集`dev_pairwise.csv`的示例如下:
|
||||
|
||||
```
|
||||
(小学数学教材比较) 关键词:新加坡 新加坡与中国数学教材的特色比较数学教材,教材比较,问题解决 0
|
||||
徐慧新疆肿瘤医院 头颈部非霍奇金淋巴瘤扩散加权成像ADC值与Ki-67表达相关性分析淋巴瘤,非霍奇金,头颈部肿瘤,磁共振成像 1
|
||||
抗生素关性腹泻 鼠李糖乳杆菌GG防治消化系统疾病的研究进展鼠李糖乳杆菌,腹泻,功能性胃肠病,肝脏疾病,幽门螺杆菌 0
|
||||
德州市图书馆 图书馆智慧化建设与融合创新服务研究图书馆;智慧化;阅读服务;融合创新 1
|
||||
维生素c 综述 维生素C防治2型糖尿病研究进展维生素C;2型糖尿病;氧化应激;自由基;抗氧化剂 0
|
||||
.......
|
||||
```
|
||||
|
||||
训练数据集`test.csv`的格式如下,其中这个score得分是召回算出来的相似度或者距离,仅供参考,可以忽略:
|
||||
|
||||
```
|
||||
query1 \t title1 \t score
|
||||
query2 \t title2 \t score
|
||||
```
|
||||
训练数据集`test.csv`的示例如下:
|
||||
|
||||
```
|
||||
加强科研项目管理有效促进医学科研工作 科研项目管理策略科研项目,项目管理,实施,必要性,策略 0.32163668
|
||||
加强科研项目管理有效促进医学科研工作 关于推进我院科研发展进程的相关问题研究医院科研,主体,环境,信息化 0.32922596
|
||||
加强科研项目管理有效促进医学科研工作 深圳科技计划对高校科研项目资助现状分析与思考基础研究,高校,科技计划,科技创新 0.36869502
|
||||
加强科研项目管理有效促进医学科研工作 普通高校科研管理模式的优化与创新普通高校,科研,科研管理 0.3688045
|
||||
.......
|
||||
```
|
||||
|
||||
|
||||
### 3.4 运行环境和安装说明
|
||||
|
||||
|
||||
(1)运行环境
|
||||
|
||||
本实验采用了以下的运行环境进行,详细说明如下,用户也可以在自己 GPU 硬件环境进行:
|
||||
|
||||
a. 软件环境:
|
||||
|
||||
|
||||
- python >= 3.6
|
||||
- paddlenlp >= 2.2.1
|
||||
- paddlepaddle-gpu >=2.2
|
||||
- CUDA Version: 10.2
|
||||
- NVIDIA Driver Version: 440.64.00
|
||||
- Ubuntu 16.04.6 LTS (Docker)
|
||||
|
||||
|
||||
b. 硬件环境:
|
||||
|
||||
|
||||
- NVIDIA Tesla V100 16GB x4卡
|
||||
- Intel(R) Xeon(R) Gold 6148 CPU @ 2.40GHz
|
||||
|
||||
|
||||
c. 依赖安装:
|
||||
|
||||
```
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 4. Neural Search 快速体验实践
|
||||
|
||||
PaddleNLP已经基于ERNIE 1.0训练了一个基线模型,如果想快速搭建Neural Search的完整系统。
|
||||
|
||||
### 4.1. 召回
|
||||
|
||||
- 召回向量抽取服务的搭建请参考:[In-batch Negatives](./recall/in_batch_negative/), 只需要下载基于ERNIE 1.0的预训练模型,导出成Paddle Serving的格式,然后启动Pipeline Server服务即可
|
||||
|
||||
- 召回向量检索服务的搭建请参考:[Milvus](./recall/milvus/), 需要搭建Milvus并且插入检索数据的向量
|
||||
|
||||
【注意】如果使用Neural Search训练好的模型,由于该模型是基于ERNIE 1.0训练的,所以需要把 `model_name_or_path`指定为`ernie 1.0`,向量抽取结果才能正常。
|
||||
|
||||
|
||||
### 4.2. 排序
|
||||
|
||||
排序服务的搭建请参考 [ernie_matching](./ranking/ernie_matching/),只需要下载基于ERNIE Gram的预训练模型,导出成Paddle Serving的格式,最后需要启动 Pipeline Serving服务
|
||||
|
||||
【注意】如果使用Neural Search训练好的模型,由于该模型是基于ERNIE Gram训练的,所以需要把 `model_name_or_path`指定为`ernie-gram-zh`,向量抽取结果才能正常。
|
||||
|
||||
### 4.3. 系统运行
|
||||
|
||||
以上召回和排序模型都经过Paddle Serving服务化以后,就可以直接使用下面的命令运行体验:
|
||||
|
||||
```
|
||||
python3 run_system.py
|
||||
```
|
||||
输出的结果为:
|
||||
|
||||
```
|
||||
PipelineClient::predict pack_data time:1656991375.5521955
|
||||
PipelineClient::predict before time:1656991375.5529568
|
||||
Extract feature time to cost :0.0161135196685791 seconds
|
||||
Search milvus time cost is 0.8139839172363281 seconds
|
||||
PipelineClient::predict pack_data time:1656991376.3981335
|
||||
PipelineClient::predict before time:1656991376.3983877
|
||||
time to cost :0.05616641044616699 seconds
|
||||
```
|
||||
会输出2个文件 `recall_result.csv` 是召回检索的结果,`rank_result.csv` 是排序的结果。csv的示例输出下。
|
||||
|
||||
召回的结果:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异,港台文化对内地中小学生的负面影响,0.055068351328372955
|
||||
中西方语言与文化的差异,外来文化在越南的传播与融合,0.05621318891644478
|
||||
中西方语言与文化的差异,临终关怀中的“仪式”,0.05705389380455017
|
||||
中西方语言与文化的差异,历史的真实与艺术加工,0.05745899677276611
|
||||
......
|
||||
```
|
||||
|
||||
排序的结果:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异,论中西方教育差异,0.870943009853363
|
||||
中西方语言与文化的差异,浅析中西方问候语的差异,0.8468159437179565
|
||||
中西方语言与文化的差异,文化认同及其根源,0.8288694620132446
|
||||
中西方语言与文化的差异,从历史文化角度分析中西方学校教育的差异,0.8209370970726013
|
||||
中西方语言与文化的差异,中西医思维方式的差异,0.8150948882102966
|
||||
中西方语言与文化的差异,浅析中韩餐桌文化差异,0.7751647233963013
|
||||
......
|
||||
```
|
||||
|
||||
|
||||
|
||||
## 5. 从头开始搭建自己的检索系统
|
||||
|
||||
这里展示了能够从头至尾跑通的完整代码,您使用自己的业务数据,照着跑,能搭建出一个给定 Query,返回 topK 相关文档的小型检索系统。您可以参照我们给出的效果和性能数据来检查自己的运行过程是否正确。
|
||||
|
||||
### 5.1 召回阶段
|
||||
|
||||
**召回模型训练**
|
||||
|
||||
我们进行了多组实践,用来对比说明召回阶段各方案的效果:
|
||||
|
||||
| 模型 | Recall@1 | Recall@5 |Recall@10 |Recall@20 |Recall@50 |策略简要说明|
|
||||
| ------------ | ------------ | ------------ |--------- |--------- |--------- |--------- |
|
||||
| 有监督训练 Baseline | 30.077| 43.513| 48.633 | 53.448 |59.632| 标准 pair-wise 训练范式,通过随机采样产生负样本|
|
||||
| 有监督训练 In-batch Negatives | 51.301 | 65.309| 69.878| 73.996|78.881| In-batch Negatives 有监督训练|
|
||||
| 无监督训练 SimCSE | 42.374 | 57.505| 62.641| 67.09|72.331| SimCSE 无监督训练|
|
||||
| 无监督 + 有监督训练 SimCSE + In-batch Negatives | 55.976 | 71.849| 76.363| 80.49|84.809| SimCSE无监督训练,In-batch Negatives 有监督训练|
|
||||
| Domain-adaptive Pretraining + SimCSE | 51.031 | 66.648| 71.338 | 75.676 |80.144| ERNIE 预训练,SimCSE 无监督训练|
|
||||
| Domain-adaptive Pretraining + SimCSE + In-batch Negatives| **58.248** | **75.099**| **79.813**| **83.801**|**87.733**| ERNIE 预训练,SimCSE 无监督训训练,In-batch Negatives 有监督训练|
|
||||
|
||||
从上述表格可以看出,首先利用 ERNIE 3.0 做 Domain-adaptive Pretraining ,然后把训练好的模型加载到 SimCSE 上进行无监督训练,最后利用 In-batch Negatives 在有监督数据上进行训练能够获得最佳的性能。[模型下载](https://paddlenlp.bj.bcebos.com/models/inbatch_model_best.zip),模型的使用方式参考[In-batch Negatives](./recall/in_batch_negative/) 。
|
||||
|
||||
|
||||
这里采用 Domain-adaptive Pretraining + SimCSE + In-batch Negatives 方案:
|
||||
|
||||
第一步:无监督训练 Domain-adaptive Pretraining
|
||||
|
||||
训练用时 16hour55min,可参考:[ERNIE 1.0](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/model_zoo/ernie-1.0)
|
||||
|
||||
第二步:无监督训练 SimCSE
|
||||
|
||||
训练用时 16hour53min,可参考:[SimCSE](./recall/simcse/)
|
||||
|
||||
第三步:有监督训练
|
||||
|
||||
几分钟内训练完成,可参考 [In-batch Negatives](./recall/in_batch_negative/)
|
||||
|
||||
|
||||
**召回系统搭建**
|
||||
|
||||
召回系统使用索引引擎 Milvus,可参考 [milvus_system](./recall/milvus/)。
|
||||
我们展示一下系统的效果,输入的文本如下:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异
|
||||
|
||||
```
|
||||
下面是召回的部分结果,第一个是召回的title,第二个数字是计算的相似度距离
|
||||
|
||||
```
|
||||
跨文化中的文化习俗对翻译的影响翻译,跨文化,文化习俗 0.615584135055542
|
||||
试论翻译过程中的文化差异与语言空缺翻译过程,文化差异,语言空缺,文化对比 0.6155391931533813
|
||||
中英文化差异及习语翻译习语,文化差异,翻译 0.6153547763824463
|
||||
英语中的中国文化元素英语,中国文化,语言交流 0.6151996850967407
|
||||
跨文化交际中的文化误读研究文化误读,影响,中华文化,西方文明 0.6137217283248901
|
||||
在语言学习中了解中法文化差异文化差异,对话交际,语言 0.6134252548217773
|
||||
从翻译视角看文化差异影响下的中式英语的应对策略文化差异;中式英语现;汉英翻译;动态对等理论 0.6127341389656067
|
||||
归化与异化在跨文化传播中的动态平衡归化,异化,翻译策略,跨文化传播,文化外译 0.6127211451530457
|
||||
浅谈中西言语交际行为中的文化差异交际用语,文化差异,中国,西方 0.6125463843345642
|
||||
翻译中的文化因素--异化与归化文化翻译,文化因素,异化与归化 0.6111845970153809
|
||||
历史与文化差异对翻译影响的分析研究历史与文化差异,法汉翻译,翻译方法 0.6107486486434937
|
||||
从中、韩、美看跨文化交际中的东西方文化差异跨文化交际,东西方,文化差异 0.6091923713684082
|
||||
试论文化差异对翻译工作的影响文化差异,翻译工作,影响 0.6084284782409668
|
||||
从归化与异化看翻译中的文化冲突现象翻译,文化冲突,归化与异化,跨文化交际 0.6063553690910339
|
||||
中西方问候语的文化差异问候语,文化差异,文化背景 0.6054259538650513
|
||||
中英思维方式的差异对翻译的影响中英文化的差异,中英思维方式的差异,翻译 0.6026732921600342
|
||||
略论中西方语言文字的特性与差异语言,会意,确意,特性,差异 0.6009351015090942
|
||||
......
|
||||
|
||||
```
|
||||
|
||||
|
||||
### 5.2 排序阶段
|
||||
|
||||
排序阶段有2种方案,第一种是[ernie_matching](./ranking/ernie_matching/)使用的模型是 ERNIE-3.0-Medium-zh,用时 20h;第二种是基于RocketQA的排序模型[cross_encoder](./ranking/cross_encoder/),训练用时也是20h左右。
|
||||
|
||||
|
||||
排序阶段的效果评估:
|
||||
|
||||
| 模型 | AUC |
|
||||
| ------------ | ------------ |
|
||||
| Baseline: In-batch Negatives | 0.582 |
|
||||
| pairwise ERNIE-Gram |0.801 |
|
||||
| CrossEncoder:rocketqa-base-cross-encoder |**0.835** |
|
||||
|
||||
|
||||
同样输入文本:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异
|
||||
```
|
||||
排序阶段的结果展示如下,第一个是 Title ,第二个数字是计算的概率,显然经排序阶段筛选的文档与 Query 更相关:
|
||||
|
||||
```
|
||||
中西方文化差异以及语言体现中西方文化,差异,语言体现 0.999848484992981
|
||||
论中西方语言与文化差异的历史渊源中西方语言,中西方文化,差异,历史渊源 0.9998375177383423
|
||||
从日常生活比较中西方语言与文化的差异中西方,语言,文化,比较 0.9985846281051636
|
||||
试论中西方语言文化教育的差异比较与融合中西方,语言文化教育,差异 0.9972485899925232
|
||||
中西方文化差异对英语学习的影响中西方文化,差异,英语,学习 0.9831035137176514
|
||||
跨文化视域下的中西文化差异研究跨文化,中西,文化差异 0.9781349897384644
|
||||
中西方文化差异对跨文化交际的影响分析文化差异,跨文化交际,影响 0.9735479354858398
|
||||
探析跨文化交际中的中西方语言差异跨文化交际,中西方,语言差异 0.9668175578117371
|
||||
中西方文化差异解读中英文差异表达中西文化,差异表达,跨文化交际 0.9629314541816711
|
||||
中西方文化差异对英语翻译的影响中西方文化差异,英语翻译,翻译策略,影响 0.9538986086845398
|
||||
论跨文化交际中的中西方文化冲突跨文化交际,冲突,文化差异,交际策略,全球化 0.9493677616119385
|
||||
中西方文化差异对英汉翻译的影响中西方文化,文化差异,英汉翻译,影响 0.9430705904960632
|
||||
中西方文化差异与翻译中西方,文化差异,翻译影响,策略方法,译者素质 0.9401137828826904
|
||||
外语教学中的中西文化差异外语教学,文化,差异 0.9397934675216675
|
||||
浅析西语国家和中国的文化差异-以西班牙为例跨文化交际,西语国家,文化差异 0.9373322129249573
|
||||
中英文化差异在语言应用中的体现中英文化,汉语言,语言应用,语言差异 0.9359155297279358
|
||||
....
|
||||
```
|
||||
|
||||
|
||||
## Reference
|
||||
|
||||
[1] Tianyu Gao, Xingcheng Yao, Danqi Chen: [SimCSE: Simple Contrastive Learning of Sentence Embeddings](https://arxiv.org/abs/2104.08821). EMNLP (1) 2021: 6894-6910
|
||||
|
||||
[2] Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, Wen-tau Yih, [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906). Preprint 2020.
|
||||
|
||||
[3] Dongling Xiao, Yu-Kun Li, Han Zhang, Yu Sun, Hao Tian, Hua Wu, Haifeng Wang:
|
||||
[ERNIE-Gram: Pre-Training with Explicitly N-Gram Masked Language Modeling for Natural Language Understanding](https://arxiv.org/abs/2010.12148). NAACL-HLT 2021: 1702-1715
|
||||
|
||||
[4] Yu Sun, Shuohuan Wang, Yu-Kun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu:
|
||||
[ERNIE: Enhanced Representation through Knowledge Integration](https://arxiv.org/abs/1904.09223). CoRR abs/1904.09223 (2019)
|
||||
BIN
applications/neural_search/img/attu.png
Normal file
BIN
applications/neural_search/img/attu.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 52 KiB |
BIN
applications/neural_search/img/system_pipeline.png
Normal file
BIN
applications/neural_search/img/system_pipeline.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 92 KiB |
399
applications/neural_search/ranking/cross_encoder/README.md
Normal file
399
applications/neural_search/ranking/cross_encoder/README.md
Normal file
@@ -0,0 +1,399 @@
|
||||
|
||||
**目录**
|
||||
|
||||
* [背景介绍](#背景介绍)
|
||||
* [CrossEncoder](#CrossEncoder)
|
||||
* [1. 技术方案和评估指标](#技术方案)
|
||||
* [2. 环境依赖](#环境依赖)
|
||||
* [3. 代码结构](#代码结构)
|
||||
* [4. 数据准备](#数据准备)
|
||||
* [5. 模型训练](#模型训练)
|
||||
* [6. 评估](#开始评估)
|
||||
* [7. 预测](#预测)
|
||||
* [8. 部署](#部署)
|
||||
|
||||
<a name="背景介绍"></a>
|
||||
|
||||
# 背景介绍
|
||||
|
||||
基于RocketQA的CrossEncoder训练的单塔模型,该模型用于搜索的排序阶段,对召回的结果进行重新排序的作用。
|
||||
|
||||
|
||||
<a name="CrossEncoder"></a>
|
||||
|
||||
# CrossEncoder
|
||||
|
||||
<a name="技术方案"></a>
|
||||
|
||||
## 1. 技术方案和评估指标
|
||||
|
||||
### 技术方案
|
||||
|
||||
加载基于ERNIE 3.0训练过的RocketQA单塔CrossEncoder模型。
|
||||
|
||||
|
||||
### 评估指标
|
||||
|
||||
(1)采用 AUC 指标来评估排序模型的排序效果。
|
||||
|
||||
**效果评估**
|
||||
|
||||
| 训练方式 | 模型 | AUC |
|
||||
| ------------ | ------------ |------------ |
|
||||
| pairwise| ERNIE-Gram |0.801 |
|
||||
| CrossEncoder | rocketqa-base-cross-encoder |**0.835** |
|
||||
|
||||
<a name="环境依赖"></a>
|
||||
|
||||
## 2. 环境依赖和安装说明
|
||||
|
||||
**环境依赖**
|
||||
|
||||
* python >= 3.7
|
||||
* paddlepaddle >= 2.3.7
|
||||
* paddlenlp >= 2.3
|
||||
* pandas >= 0.25.1
|
||||
* scipy >= 1.3.1
|
||||
|
||||
<a name="代码结构"></a>
|
||||
|
||||
## 3. 代码结构
|
||||
|
||||
以下是本项目主要代码结构及说明:
|
||||
|
||||
```
|
||||
ernie_matching/
|
||||
├── deply # 部署
|
||||
├── cpp
|
||||
├── rpc_client.py # RPC 客户端的bash脚本
|
||||
├── http_client.py # http 客户端的bash文件
|
||||
└── start_server.sh # 启动C++服务的脚本
|
||||
└── python
|
||||
├── deploy.sh # 预测部署bash脚本
|
||||
├── config_nlp.yml # Pipeline 的配置文件
|
||||
├── web_service.py # Pipeline 服务端的脚本
|
||||
├── rpc_client.py # Pipeline RPC客户端的脚本
|
||||
└── predict.py # python 预测部署示例
|
||||
|—— scripts
|
||||
├── export_model.sh # 动态图参数导出静态图参数的bash文件
|
||||
├── export_to_serving.sh # 导出 Paddle Serving 模型格式的bash文件
|
||||
├── train_ce.sh # 匹配模型训练的bash文件
|
||||
├── evaluate_ce.sh # 评估验证文件bash脚本
|
||||
├── predict_ce.sh # 匹配模型预测脚本的bash文件
|
||||
├── export_model.py # 动态图参数导出静态图参数脚本
|
||||
├── export_to_serving.py # 导出 Paddle Serving 模型格式的脚本
|
||||
├── data.py # 训练样本的转换逻辑
|
||||
├── train_ce.py # 模型训练脚本
|
||||
├── evaluate.py # 评估验证文件
|
||||
├── predict.py # Pair-wise 模型预测脚本,输出文本对是相似度
|
||||
|
||||
```
|
||||
|
||||
<a name="数据准备"></a>
|
||||
|
||||
## 4. 数据准备
|
||||
|
||||
### 数据集说明
|
||||
|
||||
样例数据如下:
|
||||
```
|
||||
(小学数学教材比较) 关键词:新加坡 新加坡与中国数学教材的特色比较数学教材,教材比较,问题解决 0
|
||||
徐慧新疆肿瘤医院 头颈部非霍奇金淋巴瘤扩散加权成像ADC值与Ki-67表达相关性分析淋巴瘤,非霍奇金,头颈部肿瘤,磁共振成像 1
|
||||
抗生素关性腹泻 鼠李糖乳杆菌GG防治消化系统疾病的研究进展鼠李糖乳杆菌,腹泻,功能性胃肠病,肝脏疾病,幽门螺杆菌 0
|
||||
德州市图书馆 图书馆智慧化建设与融合创新服务研究图书馆;智慧化;阅读服务;融合创新 1
|
||||
维生素c 综述 维生素C防治2型糖尿病研究进展维生素C;2型糖尿病;氧化应激;自由基;抗氧化剂 0
|
||||
(白藜芦醇) 关键词:2型糖尿病 2型糖尿病大鼠心肌缺血再灌注损伤转录因子E2相关因子2/血红素氧合酶1信号通路的表达及白藜芦醇的干预研究糖尿病,2型,心肌缺血,再灌注损伤,白藜芦醇 1
|
||||
融资偏好 创新型企业产业风险、融资偏好与融资选择融资偏好;产业风险;融资选择 1
|
||||
星载激光雷达 星载激光雷达望远镜主镜超轻量化结构设计超轻量化;拓扑优化;集成优化;RMS;有限元仿真 1
|
||||
```
|
||||
|
||||
|
||||
### 数据集下载
|
||||
|
||||
|
||||
- [literature_search_rank](https://paddlenlp.bj.bcebos.com/applications/literature_search_rank.zip)
|
||||
|
||||
```
|
||||
├── data # 排序数据集
|
||||
├── test.csv # 测试集
|
||||
├── dev_pairwise.csv # 验证集
|
||||
└── train.csv # 训练集
|
||||
```
|
||||
|
||||
<a name="模型训练"></a>
|
||||
|
||||
## 5. 模型训练
|
||||
|
||||
**排序模型下载链接:**
|
||||
|
||||
|
||||
|Model|训练参数配置|硬件|MD5|
|
||||
| ------------ | ------------ | ------------ |-----------|
|
||||
|[ERNIE-Gram-Sort](https://bj.bcebos.com/v1/paddlenlp/models/ernie_gram_sort.zip)|<div style="width: 150pt">epoch:3 lr:5E-5 bs:64 max_len:64 </div>|<div style="width: 100pt">4卡 v100-16g</div>|d24ece68b7c3626ce6a24baa58dd297d|
|
||||
|
||||
|
||||
### 训练环境说明
|
||||
|
||||
|
||||
- NVIDIA Driver Version: 440.64.00
|
||||
- Ubuntu 16.04.6 LTS (Docker)
|
||||
- Intel(R) Xeon(R) Gold 6148 CPU @ 2.40GHz
|
||||
|
||||
|
||||
### 单机单卡训练/单机多卡训练
|
||||
|
||||
这里采用单机多卡方式进行训练,通过如下命令,指定 GPU 0,1,2,3 卡。如果采用单机单卡训练,只需要把`--gpu`参数设置成单卡的卡号即可
|
||||
|
||||
训练的命令如下:
|
||||
|
||||
```
|
||||
unset CUDA_VISIBLE_DEVICES
|
||||
python -u -m paddle.distributed.launch --gpus "0,1,2,3" --log_dir="logs" train_ce.py \
|
||||
--device gpu \
|
||||
--train_set data/train.csv \
|
||||
--test_file data/dev_pairwise.csv \
|
||||
--save_dir ./checkpoints \
|
||||
--model_name_or_path rocketqa-base-cross-encoder \
|
||||
--batch_size 32 \
|
||||
--save_steps 10000 \
|
||||
--max_seq_len 384 \
|
||||
--learning_rate 1E-5 \
|
||||
--weight_decay 0.01 \
|
||||
--warmup_proportion 0.0 \
|
||||
--logging_steps 10 \
|
||||
--seed 1 \
|
||||
--epochs 3 \
|
||||
--eval_step 1000
|
||||
```
|
||||
也可以运行bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/train_ce.sh
|
||||
```
|
||||
|
||||
<a name="评估"></a>
|
||||
|
||||
## 6. 评估
|
||||
|
||||
|
||||
```
|
||||
python evaluate.py --model_name_or_path rocketqa-base-cross-encoder \
|
||||
--init_from_ckpt checkpoints/model_80000/model_state.pdparams \
|
||||
--test_file data/dev_pairwise.csv
|
||||
```
|
||||
也可以运行bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/evaluate_ce.sh
|
||||
```
|
||||
|
||||
|
||||
成功运行后会输出下面的指标:
|
||||
|
||||
```
|
||||
eval_dev auc:0.829
|
||||
```
|
||||
|
||||
<a name="预测"></a>
|
||||
|
||||
## 7. 预测
|
||||
|
||||
### 准备预测数据
|
||||
|
||||
待预测数据为 tab 分隔的 tsv 文件,每一行为 1 个文本 Pair,和文本pair的语义索引相似度,(该相似度由召回模型算出,仅供参考),部分示例如下:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异 第二语言习得的一大障碍就是文化差异。 0.5160342454910278
|
||||
中西方语言与文化的差异 跨文化视角下中国文化对外传播路径琐谈跨文化,中国文化,传播,翻译 0.5145505666732788
|
||||
中西方语言与文化的差异 从中西方民族文化心理的差异看英汉翻译语言,文化,民族文化心理,思维方式,翻译 0.5141439437866211
|
||||
中西方语言与文化的差异 中英文化差异对翻译的影响中英文化,差异,翻译的影响 0.5138794183731079
|
||||
中西方语言与文化的差异 浅谈文化与语言习得文化,语言,文化与语言的关系,文化与语言习得意识,跨文化交际 0.5131710171699524
|
||||
```
|
||||
|
||||
|
||||
|
||||
### 开始预测
|
||||
|
||||
以上述 demo 数据为例,运行如下命令基于我们开源的rocketqa模型开始计算文本 Pair 的语义相似度:
|
||||
|
||||
```shell
|
||||
unset CUDA_VISIBLE_DEVICES
|
||||
python predict.py \
|
||||
--device 'gpu' \
|
||||
--params_path checkpoints/model_80000/model_state.pdparams \
|
||||
--model_name_or_path rocketqa-base-cross-encoder \
|
||||
--test_set data/test.csv \
|
||||
--topk 10 \
|
||||
--batch_size 128 \
|
||||
--max_seq_length 384
|
||||
```
|
||||
也可以直接执行下面的命令:
|
||||
|
||||
```
|
||||
sh scripts/predict_ce.sh
|
||||
```
|
||||
得到下面的输出,分别是query,title和对应的预测概率:
|
||||
|
||||
```
|
||||
{'text_a': '加强科研项目管理有效促进医学科研工作', 'text_b': '高校\\十四五\\规划中学科建设要处理好五对关系\\十四五\\规划,学科建设,科技创新,人才培养', 'pred_prob': 0.7076062}
|
||||
{'text_a': '加强科研项目管理有效促进医学科研工作', 'text_b': '校企科研合作项目管理模式创新校企科研合作项目,管理模式,问题,创新', 'pred_prob': 0.64633846}
|
||||
{'text_a': '加强科研项目管理有效促进医学科研工作', 'text_b': '科研项目管理策略科研项目,项目管理,实施,必要性,策略', 'pred_prob': 0.63166416}
|
||||
{'text_a': '加强科研项目管理有效促进医学科研工作', 'text_b': '高校科研项目经费管理流程优化研究——以z大学为例高校,科研项目经费\\全流程\\管理,流程优化', 'pred_prob': 0.60351866}
|
||||
{'text_a': '加强科研项目管理有效促进医学科研工作', 'text_b': '关于推进我院科研发展进程的相关问题研究医院科研,主体,环境,信息化', 'pred_prob': 0.5688347}
|
||||
{'text_a': '加强科研项目管理有效促进医学科研工作', 'text_b': '医学临床科研选题原则和方法医学临床,科学研究,选题', 'pred_prob': 0.55190295}
|
||||
```
|
||||
|
||||
<a name="部署"></a>
|
||||
|
||||
## 8. 部署
|
||||
|
||||
### 动转静导出
|
||||
|
||||
首先把动态图模型转换为静态图:
|
||||
|
||||
```
|
||||
python export_model.py \
|
||||
--params_path checkpoints/model_80000/model_state.pdparams \
|
||||
--model_name_or_path rocketqa-base-cross-encoder \
|
||||
--output_path=./output
|
||||
```
|
||||
也可以运行下面的bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/export_model.sh
|
||||
```
|
||||
|
||||
### Paddle Inference
|
||||
|
||||
使用PaddleInference
|
||||
|
||||
```
|
||||
python deploy/python/predict.py --model_dir ./output \
|
||||
--input_file data/test.csv \
|
||||
--model_name_or_path rocketqa-base-cross-encoder
|
||||
```
|
||||
也可以运行下面的bash脚本:
|
||||
|
||||
```
|
||||
sh deploy/python/deploy.sh
|
||||
```
|
||||
得到下面的输出,输出的是样本的query,title以及对应的概率:
|
||||
|
||||
```
|
||||
Data: {'query': '加强科研项目管理有效促进医学科研工作', 'title': '科研项目管理策略科研项目,项目管理,实施,必要性,策略'} prob: 0.5479063987731934
|
||||
Data: {'query': '加强科研项目管理有效促进医学科研工作', 'title': '关于推进我院科研发展进程的相关问题研究医院科研,主体,环境,信息化'} prob: 0.5151925086975098
|
||||
Data: {'query': '加强科研项目管理有效促进医学科研工作', 'title': '深圳科技计划对高校科研项目资助现状分析与思考基础研究,高校,科技计划,科技创新'} prob: 0.42983829975128174
|
||||
Data: {'query': '加强科研项目管理有效促进医学科研工作', 'title': '普通高校科研管理模式的优化与创新普通高校,科研,科研管理'} prob: 0.465454638004303
|
||||
```
|
||||
|
||||
### Paddle Serving部署
|
||||
|
||||
Paddle Serving 的详细文档请参考 [Pipeline_Design](https://github.com/PaddlePaddle/Serving/blob/v0.7.0/doc/Python_Pipeline/Pipeline_Design_CN.md)和[Serving_Design](https://github.com/PaddlePaddle/Serving/blob/v0.7.0/doc/Serving_Design_CN.md),首先把静态图模型转换成Serving的格式:
|
||||
|
||||
```
|
||||
python export_to_serving.py \
|
||||
--dirname "output" \
|
||||
--model_filename "inference.pdmodel" \
|
||||
--params_filename "inference.pdiparams" \
|
||||
--server_path "serving_server" \
|
||||
--client_path "serving_client" \
|
||||
--fetch_alias_names "predict"
|
||||
|
||||
```
|
||||
|
||||
参数含义说明
|
||||
* `dirname`: 需要转换的模型文件存储路径,Program 结构文件和参数文件均保存在此目录。
|
||||
* `model_filename`: 存储需要转换的模型 Inference Program 结构的文件名称。如果设置为 None ,则使用 `__model__` 作为默认的文件名
|
||||
* `params_filename`: 存储需要转换的模型所有参数的文件名称。当且仅当所有模型参数被保>存在一个单独的二进制文件中,它才需要被指定。如果模型参数是存储在各自分离的文件中,设置它的值为 None
|
||||
* `server_path`: 转换后的模型文件和配置文件的存储路径。默认值为 serving_server
|
||||
* `client_path`: 转换后的客户端配置文件存储路径。默认值为 serving_client
|
||||
* `fetch_alias_names`: 模型输出的别名设置,比如输入的 input_ids 等,都可以指定成其他名字,默认不指定
|
||||
* `feed_alias_names`: 模型输入的别名设置,比如输出 pooled_out 等,都可以重新指定成其他模型,默认不指定
|
||||
|
||||
也可以运行下面的 bash 脚本:
|
||||
```
|
||||
sh scripts/export_to_serving.sh
|
||||
```
|
||||
Paddle Serving的部署有两种方式,第一种方式是Pipeline的方式,第二种是C++的方式,下面分别介绍这两种方式的用法:
|
||||
|
||||
#### Pipeline方式
|
||||
|
||||
修改对应预训练模型的`Tokenizer`:
|
||||
|
||||
```
|
||||
self.tokenizer = AutoTokenizer.from_pretrained('rocketqa-base-cross-encoder')
|
||||
```
|
||||
|
||||
启动 Pipeline Server:
|
||||
|
||||
```
|
||||
python web_service.py
|
||||
```
|
||||
|
||||
启动客户端调用 Server。
|
||||
|
||||
首先修改rpc_client.py中需要预测的样本:
|
||||
|
||||
```
|
||||
list_data = [{"query":"加强科研项目管理有效促进医学科研工作","title":"科研项目管理策略科研项目,项目管理,实施,必要性,策略"}]`
|
||||
```
|
||||
然后运行:
|
||||
```
|
||||
python rpc_client.py
|
||||
```
|
||||
模型的输出为:
|
||||
|
||||
```
|
||||
PipelineClient::predict pack_data time:1662354188.422532
|
||||
PipelineClient::predict before time:1662354188.423034
|
||||
time to cost :0.016808509826660156 seconds
|
||||
(1,)
|
||||
[0.5479064]
|
||||
```
|
||||
可以看到客户端发送了1条文本,这条文本的相似的概率值。
|
||||
|
||||
#### C++的方式
|
||||
|
||||
启动C++的Serving:
|
||||
|
||||
```
|
||||
python -m paddle_serving_server.serve --model serving_server --port 8600 --gpu_id 0 --thread 5 --ir_optim True
|
||||
```
|
||||
也可以使用脚本:
|
||||
|
||||
```
|
||||
sh deploy/cpp/start_server.sh
|
||||
```
|
||||
Client 可以使用 http 或者 rpc 两种方式,rpc 的方式为:
|
||||
|
||||
```
|
||||
python deploy/cpp/rpc_client.py
|
||||
```
|
||||
运行的输出为:
|
||||
|
||||
```
|
||||
I0905 05:38:28.876770 28507 general_model.cpp:490] [client]logid=0,client_cost=158.124ms,server_cost=156.385ms.
|
||||
time to cost :0.15848731994628906 seconds
|
||||
[0.54790646]
|
||||
```
|
||||
可以看到服务端返回了相似度结果
|
||||
|
||||
或者使用 http 的客户端访问模式:
|
||||
|
||||
```
|
||||
python deploy/cpp/http_client.py
|
||||
```
|
||||
运行的输出为:
|
||||
```
|
||||
time to cost :0.13054680824279785 seconds
|
||||
0.5479064707850817
|
||||
```
|
||||
可以看到服务端返回了相似度结果
|
||||
|
||||
|
||||
## Reference
|
||||
|
||||
[1] Xiao, Dongling, Yu-Kun Li, Han Zhang, Yu Sun, Hao Tian, Hua Wu, and Haifeng Wang. “ERNIE-Gram: Pre-Training with Explicitly N-Gram Masked Language Modeling for Natural Language Understanding.” ArXiv:2010.12148 [Cs].
|
||||
|
||||
[2] Yingqi Qu, Yuchen Ding, Jing Liu, Kai Liu, Ruiyang Ren, Wayne Xin Zhao, Daxiang Dong, Hua Wu, Haifeng Wang:
|
||||
RocketQA: An Optimized Training Approach to Dense Passage Retrieval for Open-Domain Question Answering. NAACL-HLT 2021: 5835-5847
|
||||
116
applications/neural_search/ranking/cross_encoder/data.py
Normal file
116
applications/neural_search/ranking/cross_encoder/data.py
Normal file
@@ -0,0 +1,116 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
import numpy as np
|
||||
import paddle
|
||||
|
||||
|
||||
def convert_example(example,
|
||||
tokenizer,
|
||||
max_seq_length=512,
|
||||
is_test=False,
|
||||
is_pair=False):
|
||||
"""
|
||||
Builds model inputs from a sequence or a pair of sequence for sequence classification tasks
|
||||
by concatenating and adding special tokens. And creates a mask from the two sequences passed
|
||||
to be used in a sequence-pair classification task.
|
||||
|
||||
A BERT sequence has the following format:
|
||||
|
||||
- single sequence: ``[CLS] X [SEP]``
|
||||
|
||||
It returns the first portion of the mask (0's).
|
||||
|
||||
|
||||
Args:
|
||||
example(obj:`list[str]`): List of input data, containing text and label if it have label.
|
||||
tokenizer(obj:`PretrainedTokenizer`): This tokenizer inherits from :class:`~paddlenlp.transformers.PretrainedTokenizer`
|
||||
which contains most of the methods. Users should refer to the superclass for more information regarding methods.
|
||||
max_seq_len(obj:`int`): The maximum total input sequence length after tokenization.
|
||||
Sequences longer than this will be truncated, sequences shorter will be padded.
|
||||
is_test(obj:`False`, defaults to `False`): Whether the example contains label or not.
|
||||
|
||||
Returns:
|
||||
input_ids(obj:`list[int]`): The list of token ids.
|
||||
token_type_ids(obj: `list[int]`): List of sequence pair mask.
|
||||
label(obj:`numpy.array`, data type of int64, optional): The input label if not is_test.
|
||||
"""
|
||||
|
||||
if is_pair:
|
||||
text = example["text_a"]
|
||||
text_pair = example["text_b"]
|
||||
else:
|
||||
text = example["text"]
|
||||
text_pair = None
|
||||
encoded_inputs = tokenizer(text=text,
|
||||
text_pair=text_pair,
|
||||
max_seq_len=max_seq_length)
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
if is_test:
|
||||
return input_ids, token_type_ids
|
||||
label = np.array([example["label"]], dtype="int64")
|
||||
return input_ids, token_type_ids, label
|
||||
|
||||
|
||||
def read_text_pair(data_path):
|
||||
"""Reads data."""
|
||||
with open(data_path, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
data = line.rstrip().split("\t")
|
||||
if len(data) != 3:
|
||||
continue
|
||||
yield {'text_a': data[0], 'text_b': data[1]}
|
||||
|
||||
|
||||
def read_data(data_path):
|
||||
"""Reads data."""
|
||||
with open(data_path, 'r', encoding='utf-8', errors='ignore') as f:
|
||||
for i, line in enumerate(f):
|
||||
# Skip column name
|
||||
if (i == 0):
|
||||
continue
|
||||
data = line.rstrip('\n').split("\t")
|
||||
if (len(data) != 3):
|
||||
print(data)
|
||||
continue
|
||||
query = data[0]
|
||||
title = data[1]
|
||||
label = data[-1]
|
||||
# breakpoint()
|
||||
yield {'text_a': query, 'text_b': title, 'label': int(label)}
|
||||
|
||||
|
||||
def create_dataloader(dataset,
|
||||
mode='train',
|
||||
batch_size=1,
|
||||
batchify_fn=None,
|
||||
trans_fn=None):
|
||||
if trans_fn:
|
||||
dataset = dataset.map(trans_fn)
|
||||
|
||||
shuffle = True if mode == 'train' else False
|
||||
if mode == 'train':
|
||||
batch_sampler = paddle.io.DistributedBatchSampler(dataset,
|
||||
batch_size=batch_size,
|
||||
shuffle=shuffle)
|
||||
else:
|
||||
batch_sampler = paddle.io.BatchSampler(dataset,
|
||||
batch_size=batch_size,
|
||||
shuffle=shuffle)
|
||||
|
||||
return paddle.io.DataLoader(dataset=dataset,
|
||||
batch_sampler=batch_sampler,
|
||||
collate_fn=batchify_fn,
|
||||
return_list=True)
|
||||
@@ -0,0 +1,78 @@
|
||||
# coding:utf-8
|
||||
# pylint: disable=doc-string-missing
|
||||
# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import time
|
||||
import numpy as np
|
||||
import requests
|
||||
import json
|
||||
|
||||
from paddle_serving_client.httpclient import HttpClient
|
||||
from scipy.special import expit
|
||||
from paddlenlp.transformers import AutoTokenizer
|
||||
import paddlenlp as ppnlp
|
||||
|
||||
|
||||
def convert_example(example, tokenizer, max_seq_length=512):
|
||||
|
||||
query, title = example["query"], example["title"]
|
||||
encoded_inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
return input_ids, token_type_ids
|
||||
|
||||
|
||||
# 启动python客户端
|
||||
endpoint_list = ['127.0.0.1:8600']
|
||||
client = HttpClient()
|
||||
client.load_client_config('serving_client')
|
||||
client.connect(endpoint_list)
|
||||
feed_names = client.feed_names_
|
||||
fetch_names = client.fetch_names_
|
||||
|
||||
# 创建tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained('rocketqa-base-cross-encoder')
|
||||
max_seq_len = 64
|
||||
|
||||
# 数据预处理
|
||||
list_data = [{
|
||||
"query": "加强科研项目管理有效促进医学科研工作",
|
||||
"title": "科研项目管理策略科研项目,项目管理,实施,必要性,策略"
|
||||
}]
|
||||
|
||||
input_ids, token_type_ids = [], []
|
||||
for example in list_data:
|
||||
input_id, token_type_id = convert_example(example,
|
||||
tokenizer,
|
||||
max_seq_length=max_seq_len)
|
||||
input_ids.append(input_id)
|
||||
token_type_ids.append(token_type_id)
|
||||
|
||||
feed_dict = {}
|
||||
feed_dict['input_ids'] = np.array(input_ids)
|
||||
feed_dict['token_type_ids'] = np.array(token_type_ids)
|
||||
# batch设置为True表示的是批量预测
|
||||
b_start = time.time()
|
||||
result = client.predict(feed=feed_dict, fetch=fetch_names, batch=True)
|
||||
b_end = time.time()
|
||||
print(result)
|
||||
print("time to cost :{} seconds".format(b_end - b_start))
|
||||
score = result.outputs[0].tensor[0].float_data
|
||||
sim_score = expit(np.array(score))[1]
|
||||
print(sim_score)
|
||||
@@ -0,0 +1,76 @@
|
||||
# coding:utf-8
|
||||
# pylint: disable=doc-string-missing
|
||||
# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import time
|
||||
import numpy as np
|
||||
|
||||
from paddle_serving_client import Client
|
||||
from scipy.special import expit
|
||||
from paddlenlp.transformers import AutoTokenizer
|
||||
import paddlenlp as ppnlp
|
||||
|
||||
|
||||
def convert_example(example, tokenizer, max_seq_length=512):
|
||||
|
||||
query, title = example["query"], example["title"]
|
||||
encoded_inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
return input_ids, token_type_ids
|
||||
|
||||
|
||||
# 启动python客户端
|
||||
endpoint_list = ['127.0.0.1:8600']
|
||||
client = Client()
|
||||
client.load_client_config('serving_client')
|
||||
client.connect(endpoint_list)
|
||||
feed_names = client.feed_names_
|
||||
fetch_names = client.fetch_names_
|
||||
|
||||
# 创建tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained('rocketqa-base-cross-encoder')
|
||||
max_seq_len = 64
|
||||
|
||||
# 数据预处理
|
||||
list_data = [{
|
||||
"query": "加强科研项目管理有效促进医学科研工作",
|
||||
"title": "科研项目管理策略科研项目,项目管理,实施,必要性,策略"
|
||||
}]
|
||||
|
||||
input_ids, token_type_ids = [], []
|
||||
for example in list_data:
|
||||
input_id, token_type_id = convert_example(example,
|
||||
tokenizer,
|
||||
max_seq_length=max_seq_len)
|
||||
input_ids.append(input_id)
|
||||
token_type_ids.append(token_type_id)
|
||||
|
||||
feed_dict = {}
|
||||
feed_dict['input_ids'] = np.array(input_ids)
|
||||
feed_dict['token_type_ids'] = np.array(token_type_ids)
|
||||
# batch设置为True表示的是批量预测
|
||||
b_start = time.time()
|
||||
result = client.predict(feed=feed_dict, fetch=fetch_names, batch=True)
|
||||
# breakpoint()
|
||||
sim_score = expit(result['predict'])[:, 1]
|
||||
b_end = time.time()
|
||||
print("time to cost :{} seconds".format(b_end - b_start))
|
||||
print(sim_score)
|
||||
@@ -0,0 +1 @@
|
||||
python -m paddle_serving_server.serve --model serving_server --port 8600 --gpu_id 0 --thread 5 --ir_optim True
|
||||
@@ -0,0 +1,34 @@
|
||||
# worker_num, 最大并发数。当build_dag_each_worker=True时, 框架会创建worker_num个进程,每个进程内构建grpcSever和DAG
|
||||
# 当build_dag_each_worker=False时,框架会设置主线程grpc线程池的max_workers=worker_num
|
||||
worker_num: 20
|
||||
# build_dag_each_worker, False,框架在进程内创建一条DAG;True,框架会每个进程内创建多个独立的DAG
|
||||
build_dag_each_worker: false
|
||||
|
||||
dag:
|
||||
# op资源类型, True, 为线程模型;False,为进程模型
|
||||
is_thread_op: False
|
||||
# 使用性能分析, True,生成Timeline性能数据,对性能有一定影响;False为不使用
|
||||
tracer:
|
||||
interval_s: 10
|
||||
# http端口, rpc_port和http_port不允许同时为空。当rpc_port可用且http_port为空时,不自动生成http_port
|
||||
http_port: 8088
|
||||
# rpc端口, rpc_port和http_port不允许同时为空。当rpc_port为空且http_port不为空时,会自动将rpc_port设置为http_port+1
|
||||
rpc_port: 8089
|
||||
op:
|
||||
ernie:
|
||||
# 并发数,is_thread_op=True时,为线程并发;否则为进程并发
|
||||
concurrency: 1
|
||||
# 当op配置没有server_endpoints时,从local_service_conf读取本地服务配置
|
||||
local_service_conf:
|
||||
# client类型,包括brpc, grpc和local_predictor.local_predictor不启动Serving服务,进程内预测
|
||||
client_type: local_predictor
|
||||
# ir_optim
|
||||
ir_optim: True
|
||||
# device_type, 0=cpu, 1=gpu, 2=tensorRT, 3=arm cpu, 4=kunlun xpu
|
||||
device_type: 1
|
||||
# 计算硬件ID,当devices为""或不写时为CPU预测;当devices为"0", "0,1,2"时为GPU预测,表示使用的GPU卡
|
||||
devices: "0"
|
||||
# Fetch结果列表,以client_config中fetch_var的alias_name为准, 如果没有设置则全部返回
|
||||
fetch_list: ['predict']
|
||||
# 模型路径
|
||||
model_config: ../../serving_server/
|
||||
@@ -0,0 +1,3 @@
|
||||
python deploy/python/predict.py --model_dir ./output \
|
||||
--input_file data/test.csv \
|
||||
--model_name_or_path rocketqa-base-cross-encoder
|
||||
@@ -0,0 +1,249 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import argparse
|
||||
import os
|
||||
import sys
|
||||
|
||||
from scipy.special import softmax
|
||||
from scipy.special import expit
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
import paddle
|
||||
from paddle import inference
|
||||
import paddle.nn.functional as F
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from paddlenlp.datasets import load_dataset
|
||||
from paddlenlp.utils.log import logger
|
||||
from paddlenlp.transformers import AutoTokenizer
|
||||
|
||||
sys.path.append('.')
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--model_dir", type=str, required=True,
|
||||
help="The directory to static model.")
|
||||
|
||||
parser.add_argument("--input_file", type=str, required=True,
|
||||
help="The test set file.")
|
||||
parser.add_argument("--max_seq_length", default=128, type=int,
|
||||
help="The maximum total input sequence length after tokenization. Sequences "
|
||||
"longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--batch_size", default=32, type=int,
|
||||
help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument('--device', choices=['cpu', 'gpu', 'xpu'], default="gpu",
|
||||
help="Select which device to train model, defaults to gpu.")
|
||||
|
||||
parser.add_argument('--use_tensorrt', default=False, type=eval, choices=[True, False],
|
||||
help='Enable to use tensorrt to speed up.')
|
||||
parser.add_argument("--precision", default="fp32", type=str, choices=["fp32", "fp16", "int8"],
|
||||
help='The tensorrt precision.')
|
||||
|
||||
parser.add_argument('--cpu_threads', default=10, type=int,
|
||||
help='Number of threads to predict when using cpu.')
|
||||
parser.add_argument('--enable_mkldnn', default=False, type=eval, choices=[True, False],
|
||||
help='Enable to use mkldnn to speed up when using cpu.')
|
||||
|
||||
parser.add_argument("--benchmark", type=eval, default=False,
|
||||
help="To log some information about environment and running.")
|
||||
parser.add_argument("--save_log_path", type=str, default="./log_output/",
|
||||
help="The file path to save log.")
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-base-cross-encoder", help="The pretrained model used for training")
|
||||
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
def read_text_pair(data_path):
|
||||
"""Reads data."""
|
||||
with open(data_path, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
data = line.rstrip().split("\t")
|
||||
if len(data) != 3:
|
||||
continue
|
||||
yield {'query': data[0], 'title': data[1]}
|
||||
|
||||
|
||||
def convert_example(example, tokenizer, max_seq_length=512, is_test=False):
|
||||
|
||||
query, title = example["query"], example["title"]
|
||||
|
||||
encoded_inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
if not is_test:
|
||||
label = np.array([example["label"]], dtype="int64")
|
||||
return input_ids, token_type_ids, label
|
||||
else:
|
||||
return input_ids, token_type_ids
|
||||
|
||||
|
||||
class Predictor(object):
|
||||
|
||||
def __init__(self,
|
||||
model_dir,
|
||||
device="gpu",
|
||||
max_seq_length=128,
|
||||
batch_size=32,
|
||||
use_tensorrt=False,
|
||||
precision="fp32",
|
||||
cpu_threads=10,
|
||||
enable_mkldnn=False):
|
||||
self.max_seq_length = max_seq_length
|
||||
self.batch_size = batch_size
|
||||
|
||||
model_file = model_dir + "/inference.pdmodel"
|
||||
params_file = model_dir + "/inference.pdiparams"
|
||||
if not os.path.exists(model_file):
|
||||
raise ValueError("not find model file path {}".format(model_file))
|
||||
if not os.path.exists(params_file):
|
||||
raise ValueError("not find params file path {}".format(params_file))
|
||||
config = paddle.inference.Config(model_file, params_file)
|
||||
|
||||
if device == "gpu":
|
||||
# set GPU configs accordingly
|
||||
# such as intialize the gpu memory, enable tensorrt
|
||||
config.enable_use_gpu(100, 0)
|
||||
precision_map = {
|
||||
"fp16": inference.PrecisionType.Half,
|
||||
"fp32": inference.PrecisionType.Float32,
|
||||
"int8": inference.PrecisionType.Int8
|
||||
}
|
||||
precision_mode = precision_map[precision]
|
||||
|
||||
if args.use_tensorrt:
|
||||
config.enable_tensorrt_engine(max_batch_size=batch_size,
|
||||
min_subgraph_size=30,
|
||||
precision_mode=precision_mode)
|
||||
elif device == "cpu":
|
||||
# set CPU configs accordingly,
|
||||
# such as enable_mkldnn, set_cpu_math_library_num_threads
|
||||
config.disable_gpu()
|
||||
if args.enable_mkldnn:
|
||||
# cache 10 different shapes for mkldnn to avoid memory leak
|
||||
config.set_mkldnn_cache_capacity(10)
|
||||
config.enable_mkldnn()
|
||||
config.set_cpu_math_library_num_threads(args.cpu_threads)
|
||||
elif device == "xpu":
|
||||
# set XPU configs accordingly
|
||||
config.enable_xpu(100)
|
||||
|
||||
config.switch_use_feed_fetch_ops(False)
|
||||
self.predictor = paddle.inference.create_predictor(config)
|
||||
self.input_handles = [
|
||||
self.predictor.get_input_handle(name)
|
||||
for name in self.predictor.get_input_names()
|
||||
]
|
||||
self.output_handle = self.predictor.get_output_handle(
|
||||
self.predictor.get_output_names()[0])
|
||||
|
||||
if args.benchmark:
|
||||
import auto_log
|
||||
pid = os.getpid()
|
||||
self.autolog = auto_log.AutoLogger(
|
||||
model_name=args.model_name_or_path,
|
||||
model_precision=precision,
|
||||
batch_size=self.batch_size,
|
||||
data_shape="dynamic",
|
||||
save_path=args.save_log_path,
|
||||
inference_config=config,
|
||||
pids=pid,
|
||||
process_name=None,
|
||||
gpu_ids=0,
|
||||
time_keys=[
|
||||
'preprocess_time', 'inference_time', 'postprocess_time'
|
||||
],
|
||||
warmup=0,
|
||||
logger=logger)
|
||||
|
||||
def predict(self, data, tokenizer):
|
||||
"""
|
||||
Predicts the data labels.
|
||||
|
||||
Args:
|
||||
data (obj:`List(str)`): The batch data whose each element is a raw text.
|
||||
tokenizer(obj:`PretrainedTokenizer`): This tokenizer inherits from :class:`~paddlenlp.transformers.PretrainedTokenizer`
|
||||
which contains most of the methods. Users should refer to the superclass for more information regarding methods.
|
||||
label_map(obj:`dict`): The label id (key) to label str (value) map.
|
||||
|
||||
Returns:
|
||||
results(obj:`dict`): All the predictions labels.
|
||||
"""
|
||||
if args.benchmark:
|
||||
self.autolog.times.start()
|
||||
|
||||
examples = []
|
||||
for text in data:
|
||||
input_ids, segment_ids = convert_example(
|
||||
text,
|
||||
tokenizer,
|
||||
max_seq_length=self.max_seq_length,
|
||||
is_test=True)
|
||||
examples.append((input_ids, segment_ids))
|
||||
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"), # input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"
|
||||
), # segment
|
||||
): fn(samples)
|
||||
|
||||
if args.benchmark:
|
||||
self.autolog.times.stamp()
|
||||
|
||||
input_ids, segment_ids = batchify_fn(examples)
|
||||
self.input_handles[0].copy_from_cpu(input_ids)
|
||||
self.input_handles[1].copy_from_cpu(segment_ids)
|
||||
self.predictor.run()
|
||||
sim_score = self.output_handle.copy_to_cpu()
|
||||
if args.benchmark:
|
||||
self.autolog.times.stamp()
|
||||
sim_score = expit(sim_score)[:, 1]
|
||||
|
||||
if args.benchmark:
|
||||
self.autolog.times.end(stamp=True)
|
||||
|
||||
return sim_score
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
# Define predictor to do prediction.
|
||||
predictor = Predictor(args.model_dir, args.device, args.max_seq_length,
|
||||
args.batch_size, args.use_tensorrt, args.precision,
|
||||
args.cpu_threads, args.enable_mkldnn)
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
test_ds = load_dataset(read_text_pair,
|
||||
data_path=args.input_file,
|
||||
lazy=False)
|
||||
|
||||
data = [{'query': d['query'], 'title': d['title']} for d in test_ds]
|
||||
|
||||
batches = [
|
||||
data[idx:idx + args.batch_size]
|
||||
for idx in range(0, len(data), args.batch_size)
|
||||
]
|
||||
|
||||
results = []
|
||||
for batch_data in batches:
|
||||
results.extend(predictor.predict(batch_data, tokenizer))
|
||||
for idx, text in enumerate(data):
|
||||
print('Data: {} \t prob: {}'.format(text, results[idx]))
|
||||
if args.benchmark:
|
||||
predictor.autolog.report()
|
||||
@@ -0,0 +1,37 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
import time
|
||||
import numpy as np
|
||||
|
||||
from paddle_serving_server.pipeline import PipelineClient
|
||||
|
||||
client = PipelineClient()
|
||||
client.connect(['127.0.0.1:8089'])
|
||||
|
||||
list_data = [{
|
||||
"query": "加强科研项目管理有效促进医学科研工作",
|
||||
"title": "科研项目管理策略科研项目,项目管理,实施,必要性,策略"
|
||||
}]
|
||||
feed = {}
|
||||
for i, item in enumerate(list_data):
|
||||
feed[str(i)] = str(item)
|
||||
|
||||
print(feed)
|
||||
start_time = time.time()
|
||||
ret = client.predict(feed_dict=feed)
|
||||
end_time = time.time()
|
||||
print("time to cost :{} seconds".format(end_time - start_time))
|
||||
result = np.array(eval(ret.value[0]))
|
||||
print(result.shape)
|
||||
print(result)
|
||||
@@ -0,0 +1,82 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import numpy as np
|
||||
import sys
|
||||
import json
|
||||
|
||||
from scipy.special import expit
|
||||
from paddle_serving_server.web_service import WebService, Op
|
||||
|
||||
|
||||
def convert_example(example, tokenizer, max_seq_length=512):
|
||||
|
||||
query, title = example["query"], example["title"]
|
||||
encoded_inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
return input_ids, token_type_ids
|
||||
|
||||
|
||||
class ErnieOp(Op):
|
||||
|
||||
def init_op(self):
|
||||
from paddlenlp.transformers import AutoTokenizer
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(
|
||||
'rocketqa-base-cross-encoder')
|
||||
|
||||
def preprocess(self, input_dicts, data_id, log_id):
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
|
||||
(_, input_dict), = input_dicts.items()
|
||||
print("input dict", input_dict)
|
||||
batch_size = len(input_dict.keys())
|
||||
examples = []
|
||||
for i in range(batch_size):
|
||||
example = json.loads(input_dict[str(i)].replace("\'", "\""))
|
||||
input_ids, segment_ids = convert_example(example, self.tokenizer)
|
||||
examples.append((input_ids, segment_ids))
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=self.tokenizer.pad_token_id, dtype="int64"
|
||||
), # input
|
||||
Pad(axis=0, pad_val=self.tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # segment
|
||||
): fn(samples)
|
||||
input_ids, segment_ids = batchify_fn(examples)
|
||||
feed_dict = {}
|
||||
feed_dict['input_ids'] = input_ids
|
||||
feed_dict['token_type_ids'] = segment_ids
|
||||
return feed_dict, False, None, ""
|
||||
|
||||
def postprocess(self, input_dicts, fetch_dict, data_id, log_id):
|
||||
new_dict = {}
|
||||
sim_score = expit(fetch_dict["predict"])[:, 1]
|
||||
new_dict["predict"] = str(sim_score)
|
||||
return new_dict, None, ""
|
||||
|
||||
|
||||
class ErnieService(WebService):
|
||||
|
||||
def get_pipeline_response(self, read_op):
|
||||
ernie_op = ErnieOp(name="ernie", input_ops=[read_op])
|
||||
return ernie_op
|
||||
|
||||
|
||||
ernie_service = ErnieService(name="ernie")
|
||||
ernie_service.prepare_pipeline_config("config_nlp.yml")
|
||||
ernie_service.run_service()
|
||||
125
applications/neural_search/ranking/cross_encoder/evaluate.py
Normal file
125
applications/neural_search/ranking/cross_encoder/evaluate.py
Normal file
@@ -0,0 +1,125 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import os
|
||||
import random
|
||||
import time
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
from tqdm import tqdm
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from paddlenlp.datasets import load_dataset
|
||||
from paddlenlp.transformers import LinearDecayWithWarmup, AutoModelForSequenceClassification, AutoTokenizer
|
||||
|
||||
from data import create_dataloader
|
||||
from data import convert_example, read_data
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--test_file", type=str, required=True, help="The full path of test file")
|
||||
parser.add_argument("--max_seq_length", default=128, type=int, help="The maximum total input sequence length after tokenization. "
|
||||
"Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--batch_size", default=32, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-base-cross-encoder", help="The pretrained model used for training")
|
||||
parser.add_argument("--init_from_ckpt", type=str, default=None, help="The path of checkpoint to be loaded.")
|
||||
parser.add_argument("--seed", type=int, default=1000, help="Random seed for initialization.")
|
||||
parser.add_argument('--device', choices=['cpu', 'gpu'], default="gpu", help="Select which device to train model, defaults to gpu.")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
def set_seed(seed):
|
||||
"""sets random seed"""
|
||||
random.seed(seed)
|
||||
np.random.seed(seed)
|
||||
paddle.seed(seed)
|
||||
|
||||
|
||||
@paddle.no_grad()
|
||||
def evaluate(model, metric, data_loader, phase="dev"):
|
||||
"""
|
||||
Given a dataset, it evals model and computes the metric.
|
||||
|
||||
Args:
|
||||
model(obj:`paddle.nn.Layer`): A model to classify texts.
|
||||
data_loader(obj:`paddle.io.DataLoader`): The dataset loader which generates batches.
|
||||
metric(obj:`paddle.metric.Metric`): The evaluation metric.
|
||||
"""
|
||||
model.eval()
|
||||
metric.reset()
|
||||
|
||||
for idx, batch in enumerate(data_loader):
|
||||
input_ids, token_type_ids, labels = batch
|
||||
|
||||
pos_probs = model(input_ids=input_ids, token_type_ids=token_type_ids)
|
||||
|
||||
sim_score = F.softmax(pos_probs)
|
||||
metric.update(preds=sim_score.numpy(), labels=labels)
|
||||
|
||||
print("eval_{} auc:{:.3}".format(phase, metric.accumulate()))
|
||||
metric.reset()
|
||||
model.train()
|
||||
|
||||
|
||||
def main():
|
||||
paddle.set_device(args.device)
|
||||
rank = paddle.distributed.get_rank()
|
||||
if paddle.distributed.get_world_size() > 1:
|
||||
paddle.distributed.init_parallel_env()
|
||||
|
||||
set_seed(args.seed)
|
||||
|
||||
dev_ds = load_dataset(read_data, data_path=args.test_file, lazy=False)
|
||||
|
||||
model = AutoModelForSequenceClassification.from_pretrained(
|
||||
args.model_name_or_path, num_classes=2)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
trans_func_eval = partial(convert_example,
|
||||
tokenizer=tokenizer,
|
||||
max_seq_length=args.max_seq_length,
|
||||
is_pair=True)
|
||||
|
||||
batchify_fn_eval = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"
|
||||
), # pair_input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # pair_segment
|
||||
Stack(dtype="int64") # label
|
||||
): [data for data in fn(samples)]
|
||||
|
||||
dev_data_loader = create_dataloader(dev_ds,
|
||||
mode='dev',
|
||||
batch_size=args.batch_size,
|
||||
batchify_fn=batchify_fn_eval,
|
||||
trans_fn=trans_func_eval)
|
||||
|
||||
if args.init_from_ckpt and os.path.isfile(args.init_from_ckpt):
|
||||
state_dict = paddle.load(args.init_from_ckpt)
|
||||
model.set_dict(state_dict)
|
||||
else:
|
||||
raise ValueError(
|
||||
"Please set --params_path with correct pretrained model file")
|
||||
|
||||
metric = paddle.metric.Auc()
|
||||
evaluate(model, metric, dev_data_loader, "dev")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,57 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import argparse
|
||||
import os
|
||||
|
||||
import numpy as np
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from paddlenlp.transformers import AutoModelForSequenceClassification, AutoTokenizer
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--params_path", type=str, required=True, default='./checkpoint/model_900/model_state.pdparams', help="The path to model parameters to be loaded.")
|
||||
parser.add_argument("--output_path", type=str, default='./output', help="The path of model parameter in static graph to be saved.")
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-base-cross-encoder", help="The pretrained model used for training")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
if __name__ == "__main__":
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
model = AutoModelForSequenceClassification.from_pretrained(
|
||||
args.model_name_or_path, num_classes=2)
|
||||
|
||||
if args.params_path and os.path.isfile(args.params_path):
|
||||
state_dict = paddle.load(args.params_path)
|
||||
model.set_dict(state_dict)
|
||||
print("Loaded parameters from %s" % args.params_path)
|
||||
else:
|
||||
raise ValueError(
|
||||
"Please set --params_path with correct pretrained model file")
|
||||
model.eval()
|
||||
|
||||
# Convert to static graph with specific input description
|
||||
model = paddle.jit.to_static(
|
||||
model,
|
||||
input_spec=[
|
||||
paddle.static.InputSpec(shape=[None, None],
|
||||
dtype="int64"), # input_ids
|
||||
paddle.static.InputSpec(shape=[None, None],
|
||||
dtype="int64") # segment_ids
|
||||
])
|
||||
# Save in static graph model.
|
||||
save_path = os.path.join(args.output_path, "inference")
|
||||
paddle.jit.save(model, save_path)
|
||||
@@ -0,0 +1,47 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import argparse
|
||||
import paddle_serving_client.io as serving_io
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--dirname", type=str, required=True,
|
||||
default='./output', help="Path of saved model files. Program file and parameter files are saved in this directory.")
|
||||
parser.add_argument("--model_filename", type=str, required=True,
|
||||
default='inference.pdmodel', help="The name of file to load the inference program. If it is None, the default filename __model__ will be used.")
|
||||
parser.add_argument("--params_filename", type=str, required=True,
|
||||
default='inference.pdiparams', help="The name of file to load all parameters. It is only used for the case that all parameters were saved in a single binary file. If parameters were saved in separate files, set it as None. Default: None.")
|
||||
parser.add_argument("--server_path", type=str, default='./serving_server',
|
||||
help="The path of server parameter in static graph to be saved.")
|
||||
parser.add_argument("--client_path", type=str, default='./serving_client',
|
||||
help="The path of client parameter in static graph to be saved.")
|
||||
parser.add_argument("--feed_alias_names", type=str, default=None,
|
||||
help='set alias names for feed vars, split by comma \',\', you should run --show_proto to check the number of feed vars')
|
||||
parser.add_argument("--fetch_alias_names", type=str, default=None,
|
||||
help='set alias names for feed vars, split by comma \',\', you should run --show_proto to check the number of fetch vars')
|
||||
parser.add_argument("--show_proto", type=bool, default=False,
|
||||
help='If yes, you can preview the proto and then determine your feed var alias name and fetch var alias name.')
|
||||
# yapf: enable
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parser.parse_args()
|
||||
serving_io.inference_model_to_serving(
|
||||
dirname=args.dirname,
|
||||
serving_server=args.server_path,
|
||||
serving_client=args.client_path,
|
||||
model_filename=args.model_filename,
|
||||
params_filename=args.params_filename,
|
||||
show_proto=args.show_proto,
|
||||
feed_alias_names=args.feed_alias_names,
|
||||
fetch_alias_names=args.fetch_alias_names)
|
||||
99
applications/neural_search/ranking/cross_encoder/predict.py
Normal file
99
applications/neural_search/ranking/cross_encoder/predict.py
Normal file
@@ -0,0 +1,99 @@
|
||||
# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import argparse
|
||||
import os
|
||||
from functools import partial
|
||||
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
from paddlenlp.datasets import load_dataset
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from tqdm import tqdm
|
||||
from paddlenlp.transformers import AutoTokenizer, AutoModel, AutoModelForSequenceClassification
|
||||
|
||||
from data import convert_example, read_text_pair, create_dataloader
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--params_path", type=str, required=True, default="checkpoints/model_900/model_state.pdparams", help="The path to model parameters to be loaded.")
|
||||
parser.add_argument("--max_seq_length", type=int, default=128, help="The maximum total input sequence length after tokenization. "
|
||||
"Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--batch_size", type=int, default=32, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument("--test_set", type=str, required=True, help="The full path of test_set.")
|
||||
parser.add_argument("--topk", type=int, default=10, help="The Topk texts.")
|
||||
parser.add_argument('--device', choices=['cpu', 'gpu', 'xpu', 'npu'], default="gpu", help="Select which device to train model, defaults to gpu.")
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-base-cross-encoder", help="The pretrained model used for training")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
@paddle.no_grad()
|
||||
def predict(model, data_loader):
|
||||
results = []
|
||||
model.eval()
|
||||
with paddle.no_grad():
|
||||
for batch in data_loader:
|
||||
input_ids, token_type_ids = batch
|
||||
logits = model(input_ids, token_type_ids)
|
||||
probs = F.softmax(logits)
|
||||
probs = probs.numpy()
|
||||
results.extend(probs[:, 1])
|
||||
return results
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
paddle.set_device(args.device)
|
||||
|
||||
test_ds = load_dataset(read_text_pair, data_path=args.test_set, lazy=False)
|
||||
model = AutoModelForSequenceClassification.from_pretrained(
|
||||
args.model_name_or_path, num_classes=2)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
trans_func = partial(convert_example,
|
||||
tokenizer=tokenizer,
|
||||
max_seq_length=args.max_seq_length,
|
||||
is_test=True,
|
||||
is_pair=True)
|
||||
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"), # input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # segment
|
||||
): [data for data in fn(samples)]
|
||||
|
||||
test_data_loader = create_dataloader(test_ds,
|
||||
mode='predict',
|
||||
batch_size=args.batch_size,
|
||||
batchify_fn=batchify_fn,
|
||||
trans_fn=trans_func)
|
||||
|
||||
if args.params_path and os.path.isfile(args.params_path):
|
||||
state_dict = paddle.load(args.params_path)
|
||||
model.set_dict(state_dict)
|
||||
print("Loaded parameters from %s" % args.params_path)
|
||||
else:
|
||||
raise ValueError(
|
||||
"Please set --params_path with correct pretrained model file")
|
||||
results = predict(model, test_data_loader)
|
||||
test_ds = load_dataset(read_text_pair, data_path=args.test_set, lazy=False)
|
||||
text_pairs = []
|
||||
for idx, prob in enumerate(results):
|
||||
text_pair = test_ds[idx]
|
||||
text_pair["pred_prob"] = prob
|
||||
text_pairs.append(text_pair)
|
||||
text_pairs = sorted(text_pairs, key=lambda x: x['pred_prob'],
|
||||
reverse=True)[:args.topk]
|
||||
for item in text_pairs:
|
||||
print(item)
|
||||
@@ -0,0 +1,3 @@
|
||||
python evaluate.py --model_name_or_path rocketqa-base-cross-encoder \
|
||||
--init_from_ckpt checkpoints/model_80000/model_state.pdparams \
|
||||
--test_file data/dev_pairwise.csv
|
||||
@@ -0,0 +1,4 @@
|
||||
python export_model.py \
|
||||
--params_path checkpoints/model_80000/model_state.pdparams \
|
||||
--model_name_or_path rocketqa-base-cross-encoder \
|
||||
--output_path=./output
|
||||
@@ -0,0 +1,7 @@
|
||||
python export_to_serving.py \
|
||||
--dirname "output" \
|
||||
--model_filename "inference.pdmodel" \
|
||||
--params_filename "inference.pdiparams" \
|
||||
--server_path "serving_server" \
|
||||
--client_path "serving_client" \
|
||||
--fetch_alias_names "predict"
|
||||
@@ -0,0 +1,11 @@
|
||||
#!/bin/bash
|
||||
unset CUDA_VISIBLE_DEVICES
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
python predict.py \
|
||||
--device 'gpu' \
|
||||
--params_path checkpoints/model_80000/model_state.pdparams \
|
||||
--model_name_or_path rocketqa-base-cross-encoder \
|
||||
--test_set data/test.csv \
|
||||
--topk 10 \
|
||||
--batch_size 128 \
|
||||
--max_seq_length 384
|
||||
@@ -0,0 +1,18 @@
|
||||
#!/bin/bash
|
||||
unset CUDA_VISIBLE_DEVICES
|
||||
python -u -m paddle.distributed.launch --gpus "0,1,2,3" --log_dir="logs" train_ce.py \
|
||||
--device gpu \
|
||||
--train_set data/train.csv \
|
||||
--test_file data/dev_pairwise.csv \
|
||||
--save_dir ./checkpoints \
|
||||
--model_name_or_path rocketqa-base-cross-encoder \
|
||||
--batch_size 32 \
|
||||
--save_steps 10000 \
|
||||
--max_seq_len 384 \
|
||||
--learning_rate 1E-5 \
|
||||
--weight_decay 0.01 \
|
||||
--warmup_proportion 0.0 \
|
||||
--logging_steps 10 \
|
||||
--seed 1 \
|
||||
--epochs 3 \
|
||||
--eval_step 1000
|
||||
206
applications/neural_search/ranking/cross_encoder/train_ce.py
Normal file
206
applications/neural_search/ranking/cross_encoder/train_ce.py
Normal file
@@ -0,0 +1,206 @@
|
||||
# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import os
|
||||
import random
|
||||
import time
|
||||
import distutils.util
|
||||
|
||||
import numpy as np
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from paddlenlp.datasets import load_dataset
|
||||
from paddlenlp.transformers import AutoTokenizer, AutoModel, AutoModelForSequenceClassification
|
||||
from paddlenlp.transformers import PolyDecayWithWarmup
|
||||
from paddle.distributed.fleet.utils.hybrid_parallel_util import fused_allreduce_gradients
|
||||
from data import convert_example, read_data, create_dataloader
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--save_dir", default='./checkpoint', type=str, help="The output directory where the model checkpoints will be written.")
|
||||
parser.add_argument("--train_set", type=str, required=True, help="The full path of train_set_file.")
|
||||
parser.add_argument("--test_file", type=str, required=True, help="The full path of test file")
|
||||
|
||||
parser.add_argument("--max_seq_length", default=128, type=int, help="The maximum total input sequence length after tokenization. "
|
||||
"Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--batch_size", default=32, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
|
||||
parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
|
||||
parser.add_argument("--epochs", default=3, type=int, help="Total number of training epochs to perform.")
|
||||
parser.add_argument("--warmup_proportion", default=0.0, type=float, help="Linear warmup proption over the training process.")
|
||||
parser.add_argument("--valid_steps", default=100, type=int, help="The interval steps to evaluate model performance.")
|
||||
parser.add_argument("--save_steps", default=100, type=int, help="The interval steps to save checkppoints.")
|
||||
parser.add_argument("--logging_steps", default=10, type=int, help="The interval steps to logging.")
|
||||
parser.add_argument("--init_from_ckpt", type=str, default=None, help="The path of checkpoint to be loaded.")
|
||||
parser.add_argument("--seed", type=int, default=1000, help="random seed for initialization")
|
||||
parser.add_argument('--device', choices=['cpu', 'gpu', 'xpu', 'npu'], default="gpu", help="Select which device to train model, defaults to gpu.")
|
||||
parser.add_argument("--use_amp", type=distutils.util.strtobool, default=False, help="Enable mixed precision training.")
|
||||
parser.add_argument("--scale_loss", type=float, default=2**15, help="The value of scale_loss for fp16.")
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-base-cross-encoder", help="The pretrained model used for training")
|
||||
parser.add_argument("--eval_step", default=200, type=int, help="Step interval for evaluation.")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
@paddle.no_grad()
|
||||
def evaluate(model, metric, data_loader, phase="dev"):
|
||||
"""
|
||||
Given a dataset, it evals model and computes the metric.
|
||||
|
||||
Args:
|
||||
model(obj:`paddle.nn.Layer`): A model to classify texts.
|
||||
data_loader(obj:`paddle.io.DataLoader`): The dataset loader which generates batches.
|
||||
metric(obj:`paddle.metric.Metric`): The evaluation metric.
|
||||
"""
|
||||
model.eval()
|
||||
metric.reset()
|
||||
|
||||
for idx, batch in enumerate(data_loader):
|
||||
input_ids, token_type_ids, labels = batch
|
||||
|
||||
pos_probs = model(input_ids=input_ids, token_type_ids=token_type_ids)
|
||||
|
||||
sim_score = F.softmax(pos_probs)
|
||||
|
||||
metric.update(preds=sim_score.numpy(), labels=labels)
|
||||
|
||||
print("eval_{} auc:{:.3}".format(phase, metric.accumulate()))
|
||||
metric.reset()
|
||||
model.train()
|
||||
|
||||
|
||||
def set_seed(seed):
|
||||
"""sets random seed"""
|
||||
random.seed(seed)
|
||||
np.random.seed(seed)
|
||||
paddle.seed(seed)
|
||||
|
||||
|
||||
def do_train():
|
||||
paddle.set_device(args.device)
|
||||
rank = paddle.distributed.get_rank()
|
||||
if paddle.distributed.get_world_size() > 1:
|
||||
paddle.distributed.init_parallel_env()
|
||||
dev_count = paddle.distributed.get_world_size()
|
||||
set_seed(args.seed)
|
||||
|
||||
train_ds = load_dataset(read_data, data_path=args.train_set, lazy=False)
|
||||
dev_ds = load_dataset(read_data, data_path=args.test_file, lazy=False)
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
model = AutoModelForSequenceClassification.from_pretrained(
|
||||
args.model_name_or_path, num_classes=2)
|
||||
|
||||
trans_func = partial(convert_example,
|
||||
tokenizer=tokenizer,
|
||||
max_seq_length=args.max_seq_length,
|
||||
is_pair=True)
|
||||
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"), # input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # segment
|
||||
Stack(dtype="int64") # label
|
||||
): [data for data in fn(samples)]
|
||||
|
||||
train_data_loader = create_dataloader(train_ds,
|
||||
mode='train',
|
||||
batch_size=args.batch_size,
|
||||
batchify_fn=batchify_fn,
|
||||
trans_fn=trans_func)
|
||||
dev_data_loader = create_dataloader(dev_ds,
|
||||
mode='dev',
|
||||
batch_size=args.batch_size,
|
||||
batchify_fn=batchify_fn,
|
||||
trans_fn=trans_func)
|
||||
|
||||
if args.init_from_ckpt and os.path.isfile(args.init_from_ckpt):
|
||||
state_dict = paddle.load(args.init_from_ckpt)
|
||||
model.set_dict(state_dict)
|
||||
|
||||
model = paddle.DataParallel(model)
|
||||
|
||||
num_training_examples = len(train_ds)
|
||||
# 4卡 gpu
|
||||
max_train_steps = args.epochs * num_training_examples // args.batch_size // dev_count
|
||||
|
||||
warmup_steps = int(max_train_steps * args.warmup_proportion)
|
||||
|
||||
print("Device count: %d" % dev_count)
|
||||
print("Num train examples: %d" % num_training_examples)
|
||||
print("Max train steps: %d" % max_train_steps)
|
||||
print("Num warmup steps: %d" % warmup_steps)
|
||||
|
||||
# Generate parameter names needed to perform weight decay.
|
||||
# All bias and LayerNorm parameters are excluded.
|
||||
decay_params = [
|
||||
p.name for n, p in model.named_parameters()
|
||||
if not any(nd in n for nd in ["bias", "norm"])
|
||||
]
|
||||
optimizer = paddle.optimizer.AdamW(
|
||||
learning_rate=args.learning_rate,
|
||||
parameters=model.parameters(),
|
||||
weight_decay=args.weight_decay,
|
||||
apply_decay_param_fun=lambda x: x in decay_params,
|
||||
grad_clip=paddle.nn.ClipGradByGlobalNorm(1.0))
|
||||
|
||||
criterion = paddle.nn.loss.CrossEntropyLoss()
|
||||
metric = paddle.metric.Auc()
|
||||
if args.use_amp:
|
||||
scaler = paddle.amp.GradScaler(init_loss_scaling=args.scale_loss)
|
||||
global_step = 0
|
||||
tic_train = time.time()
|
||||
for epoch in range(1, args.epochs + 1):
|
||||
for step, batch in enumerate(train_data_loader, start=1):
|
||||
input_ids, token_type_ids, labels = batch
|
||||
logits = model(input_ids, token_type_ids)
|
||||
loss = criterion(logits, labels)
|
||||
probs = F.softmax(logits, axis=1)
|
||||
acc = paddle.metric.accuracy(input=probs, label=labels)
|
||||
loss.backward()
|
||||
|
||||
optimizer.step()
|
||||
optimizer.clear_grad()
|
||||
|
||||
global_step += 1
|
||||
if global_step % args.logging_steps == 0 and rank == 0:
|
||||
time_diff = time.time() - tic_train
|
||||
print(
|
||||
"global step %d, epoch: %d, batch: %d, loss: %.5f, accuracy: %.5f, speed: %.2f step/s"
|
||||
% (global_step, epoch, step, loss, acc,
|
||||
args.logging_steps / time_diff))
|
||||
tic_train = time.time()
|
||||
if global_step % args.eval_step == 0 and rank == 0:
|
||||
evaluate(model, metric, dev_data_loader, "dev")
|
||||
if global_step % args.save_steps == 0 and rank == 0:
|
||||
save_dir = os.path.join(args.save_dir, "model_%d" % global_step)
|
||||
model_to_save = model._layers if isinstance(
|
||||
model, paddle.DataParallel) else model
|
||||
model_to_save.save_pretrained(save_dir)
|
||||
tokenizer.save_pretrained(save_dir)
|
||||
tic_train = time.time()
|
||||
|
||||
# save final checkpoint
|
||||
save_dir = os.path.join(args.save_dir, "model_%d" % global_step)
|
||||
model_to_save = model._layers if isinstance(model,
|
||||
paddle.DataParallel) else model
|
||||
model_to_save.save_pretrained(save_dir)
|
||||
tokenizer.save_pretrained(save_dir)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
do_train()
|
||||
409
applications/neural_search/ranking/ernie_matching/README.md
Normal file
409
applications/neural_search/ranking/ernie_matching/README.md
Normal file
@@ -0,0 +1,409 @@
|
||||
|
||||
**目录**
|
||||
|
||||
* [背景介绍](#背景介绍)
|
||||
* [ERNIE-Gram](#ERNIE-Gram)
|
||||
* [1. 技术方案和评估指标](#技术方案)
|
||||
* [2. 环境依赖](#环境依赖)
|
||||
* [3. 代码结构](#代码结构)
|
||||
* [4. 数据准备](#数据准备)
|
||||
* [5. 模型训练](#模型训练)
|
||||
* [6. 评估](#开始评估)
|
||||
* [7. 预测](#预测)
|
||||
* [8. 部署](#部署)
|
||||
|
||||
<a name="背景介绍"></a>
|
||||
|
||||
# 背景介绍
|
||||
|
||||
基于ERNIE-Gram训练Pair-wise模型。Pair-wise 匹配模型适合将文本对相似度作为特征之一输入到上层排序模块进行排序的应用场景。
|
||||
|
||||
|
||||
<a name="ERNIE-Gram"></a>
|
||||
|
||||
# ERNIE-Gram
|
||||
|
||||
<a name="技术方案"></a>
|
||||
|
||||
## 1. 技术方案和评估指标
|
||||
|
||||
### 技术方案
|
||||
|
||||
双塔模型,使用ERNIE-Gram预训练模型,使用margin_ranking_loss训练模型。
|
||||
|
||||
|
||||
### 评估指标
|
||||
|
||||
(1)采用 AUC 指标来评估排序模型的排序效果。
|
||||
|
||||
**效果评估**
|
||||
|
||||
| 模型 | AUC |
|
||||
| ------------ | ------------ |
|
||||
| ERNIE-Gram | 0.801 |
|
||||
|
||||
<a name="环境依赖"></a>
|
||||
|
||||
## 2. 环境依赖和安装说明
|
||||
|
||||
**环境依赖**
|
||||
|
||||
* python >= 3.x
|
||||
* paddlepaddle >= 2.1.3
|
||||
* paddlenlp >= 2.2
|
||||
* pandas >= 0.25.1
|
||||
* scipy >= 1.3.1
|
||||
|
||||
<a name="代码结构"></a>
|
||||
|
||||
## 3. 代码结构
|
||||
|
||||
以下是本项目主要代码结构及说明:
|
||||
|
||||
```
|
||||
ernie_matching/
|
||||
├── deply # 部署
|
||||
├── cpp
|
||||
├── rpc_client.py # RPC 客户端的bash脚本
|
||||
├── http_client.py # http 客户端的bash文件
|
||||
└── start_server.sh # 启动C++服务的脚本
|
||||
└── python
|
||||
├── deploy.sh # 预测部署bash脚本
|
||||
├── config_nlp.yml # Pipeline 的配置文件
|
||||
├── web_service.py # Pipeline 服务端的脚本
|
||||
├── rpc_client.py # Pipeline RPC客户端的脚本
|
||||
└── predict.py # python 预测部署示例
|
||||
|—— scripts
|
||||
├── export_model.sh # 动态图参数导出静态图参数的bash文件
|
||||
├── export_to_serving.sh # 导出 Paddle Serving 模型格式的bash文件
|
||||
├── train_pairwise.sh # Pair-wise 单塔匹配模型训练的bash文件
|
||||
├── evaluate.sh # 评估验证文件bash脚本
|
||||
├── predict_pairwise.sh # Pair-wise 单塔匹配模型预测脚本的bash文件
|
||||
├── export_model.py # 动态图参数导出静态图参数脚本
|
||||
├── export_to_serving.py # 导出 Paddle Serving 模型格式的脚本
|
||||
├── model.py # Pair-wise 匹配模型组网
|
||||
├── data.py # Pair-wise 训练样本的转换逻辑 、Pair-wise 生成随机负例的逻辑
|
||||
├── train_pairwise.py # Pair-wise 单塔匹配模型训练脚本
|
||||
├── evaluate.py # 评估验证文件
|
||||
├── predict_pairwise.py # Pair-wise 单塔匹配模型预测脚本,输出文本对是相似度
|
||||
|
||||
```
|
||||
|
||||
<a name="数据准备"></a>
|
||||
|
||||
## 4. 数据准备
|
||||
|
||||
### 数据集说明
|
||||
|
||||
样例数据如下:
|
||||
```
|
||||
个人所得税税务筹划 基于新个税视角下的个人所得税纳税筹划分析新个税;个人所得税;纳税筹划 个人所得税工资薪金税务筹划研究个人所得税,工资薪金,税务筹划
|
||||
液压支架底座受力分析 ZY4000/09/19D型液压支架的有限元分析液压支架,有限元分析,两端加载,偏载,扭转 基于ANSYS的液压支架多工况受力分析液压支架,四种工况,仿真分析,ANSYS,应力集中,优化
|
||||
迟发性血管痉挛 西洛他唑治疗动脉瘤性蛛网膜下腔出血后脑血管痉挛的Meta分析西洛他唑,蛛网膜下腔出血,脑血管痉挛,Meta分析 西洛他唑治疗动脉瘤性蛛网膜下腔出血后脑血管痉挛的Meta分析西洛他唑,蛛网膜下腔出血,脑血管痉挛,Meta分析
|
||||
氧化亚硅 复合溶胶-凝胶一锅法制备锂离子电池氧化亚硅/碳复合负极材料氧化亚硅,溶胶-凝胶法,纳米颗粒,负极,锂离子电池 负载型聚酰亚胺-二氧化硅-银杂化膜的制备和表征聚酰亚胺,二氧化硅,银,杂化膜,促进传输
|
||||
```
|
||||
|
||||
|
||||
### 数据集下载
|
||||
|
||||
|
||||
- [literature_search_data](https://bj.bcebos.com/v1/paddlenlp/data/literature_search_data.zip)
|
||||
|
||||
```
|
||||
├── milvus # milvus建库数据集
|
||||
├── milvus_data.csv. # 构建召回库的数据
|
||||
├── recall # 召回(语义索引)数据集
|
||||
├── corpus.csv # 用于测试的召回库
|
||||
├── dev.csv # 召回验证集
|
||||
├── test.csv # 召回测试集
|
||||
├── train.csv # 召回训练集
|
||||
├── train_unsupervised.csv # 无监督训练集
|
||||
├── sort # 排序数据集
|
||||
├── test_pairwise.csv # 排序测试集
|
||||
├── dev_pairwise.csv # 排序验证集
|
||||
└── train_pairwise.csv # 排序训练集
|
||||
|
||||
```
|
||||
|
||||
<a name="模型训练"></a>
|
||||
|
||||
## 5. 模型训练
|
||||
|
||||
**排序模型下载链接:**
|
||||
|
||||
|
||||
|Model|训练参数配置|硬件|MD5|
|
||||
| ------------ | ------------ | ------------ |-----------|
|
||||
|[ERNIE-Gram-Sort](https://bj.bcebos.com/v1/paddlenlp/models/ernie_gram_sort.zip)|<div style="width: 150pt">epoch:3 lr:5E-5 bs:64 max_len:64 </div>|<div style="width: 100pt">4卡 v100-16g</div>|d24ece68b7c3626ce6a24baa58dd297d|
|
||||
|
||||
|
||||
### 训练环境说明
|
||||
|
||||
|
||||
- NVIDIA Driver Version: 440.64.00
|
||||
- Ubuntu 16.04.6 LTS (Docker)
|
||||
- Intel(R) Xeon(R) Gold 6148 CPU @ 2.40GHz
|
||||
|
||||
|
||||
### 单机单卡训练/单机多卡训练
|
||||
|
||||
这里采用单机多卡方式进行训练,通过如下命令,指定 GPU 0,1,2,3 卡, 基于ERNIE-Gram训练模型,数据量比较大,需要20小时10分钟左右。如果采用单机单卡训练,只需要把`--gpu`参数设置成单卡的卡号即可
|
||||
|
||||
训练的命令如下:
|
||||
|
||||
```
|
||||
python -u -m paddle.distributed.launch --gpus "0,1,2,3" train_pairwise.py \
|
||||
--device gpu \
|
||||
--save_dir ./checkpoints \
|
||||
--batch_size 32 \
|
||||
--learning_rate 2E-5 \
|
||||
--margin 0.1 \
|
||||
--eval_step 100 \
|
||||
--train_file data/train_pairwise.csv \
|
||||
--test_file data/dev_pairwise.csv
|
||||
```
|
||||
也可以运行bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/train_pairwise.sh
|
||||
```
|
||||
|
||||
<a name="评估"></a>
|
||||
|
||||
## 6. 评估
|
||||
|
||||
|
||||
```
|
||||
unset CUDA_VISIBLE_DEVICES
|
||||
python -u -m paddle.distributed.launch --gpus "0" evaluate.py \
|
||||
--device gpu \
|
||||
--batch_size 32 \
|
||||
--learning_rate 2E-5 \
|
||||
--init_from_ckpt "./checkpoints/model_30000/model_state.pdparams" \
|
||||
--test_file data/dev_pairwise.csv
|
||||
```
|
||||
也可以运行bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/evaluate.sh
|
||||
```
|
||||
|
||||
|
||||
成功运行后会输出下面的指标:
|
||||
|
||||
```
|
||||
eval_dev auc:0.796
|
||||
```
|
||||
|
||||
<a name="预测"></a>
|
||||
|
||||
## 7. 预测
|
||||
|
||||
### 准备预测数据
|
||||
|
||||
待预测数据为 tab 分隔的 tsv 文件,每一行为 1 个文本 Pair,和文本pair的语义索引相似度,部分示例如下:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异 第二语言习得的一大障碍就是文化差异。 0.5160342454910278
|
||||
中西方语言与文化的差异 跨文化视角下中国文化对外传播路径琐谈跨文化,中国文化,传播,翻译 0.5145505666732788
|
||||
中西方语言与文化的差异 从中西方民族文化心理的差异看英汉翻译语言,文化,民族文化心理,思维方式,翻译 0.5141439437866211
|
||||
中西方语言与文化的差异 中英文化差异对翻译的影响中英文化,差异,翻译的影响 0.5138794183731079
|
||||
中西方语言与文化的差异 浅谈文化与语言习得文化,语言,文化与语言的关系,文化与语言习得意识,跨文化交际 0.5131710171699524
|
||||
```
|
||||
|
||||
|
||||
|
||||
### 开始预测
|
||||
|
||||
以上述 demo 数据为例,运行如下命令基于我们开源的 ERNIE-Gram模型开始计算文本 Pair 的语义相似度:
|
||||
|
||||
```shell
|
||||
python -u -m paddle.distributed.launch --gpus "0" \
|
||||
predict_pairwise.py \
|
||||
--device gpu \
|
||||
--params_path "./checkpoints/model_30000/model_state.pdparams"\
|
||||
--batch_size 128 \
|
||||
--max_seq_length 64 \
|
||||
--input_file 'sort/test_pairwise.csv'
|
||||
```
|
||||
也可以直接执行下面的命令:
|
||||
|
||||
```
|
||||
sh scripts/predict_pairwise.sh
|
||||
```
|
||||
得到下面的输出,分别是query,title和对应的预测概率:
|
||||
|
||||
```
|
||||
{'query': '中西方语言与文化的差异', 'title': '第二语言习得的一大障碍就是文化差异。', 'pred_prob': 0.85112214}
|
||||
{'query': '中西方语言与文化的差异', 'title': '跨文化视角下中国文化对外传播路径琐谈跨文化,中国文化,传播,翻译', 'pred_prob': 0.78629625}
|
||||
{'query': '中西方语言与文化的差异', 'title': '从中西方民族文化心理的差异看英汉翻译语言,文化,民族文化心理,思维方式,翻译', 'pred_prob': 0.91767526}
|
||||
{'query': '中西方语言与文化的差异', 'title': '中英文化差异对翻译的影响中英文化,差异,翻译的影响', 'pred_prob': 0.8601749}
|
||||
{'query': '中西方语言与文化的差异', 'title': '浅谈文化与语言习得文化,语言,文化与语言的关系,文化与语言习得意识,跨文化交际', 'pred_prob': 0.8944413}
|
||||
```
|
||||
|
||||
<a name="部署"></a>
|
||||
|
||||
## 8. 部署
|
||||
|
||||
### 动转静导出
|
||||
|
||||
首先把动态图模型转换为静态图:
|
||||
|
||||
```
|
||||
python export_model.py --params_path checkpoints/model_30000/model_state.pdparams \
|
||||
--output_path=./output \
|
||||
--model_name_or_path ernie-3.0-medium-zh
|
||||
```
|
||||
也可以运行下面的bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/export_model.sh
|
||||
```
|
||||
|
||||
### Paddle Inference
|
||||
|
||||
使用PaddleInference:
|
||||
|
||||
```
|
||||
python deploy/python/predict.py --model_dir ./output \
|
||||
--input_file sort/test_pairwise.csv \
|
||||
--model_name_or_path ernie-3.0-medium-zh
|
||||
```
|
||||
也可以运行下面的bash脚本:
|
||||
|
||||
```
|
||||
sh deploy/python/deploy.sh
|
||||
```
|
||||
得到下面的输出,输出的是样本的query,title以及对应的概率:
|
||||
|
||||
```
|
||||
Data: {'query': '中西方语言与文化的差异', 'title': '第二语言习得的一大障碍就是文化差异。'} prob: [0.8511221]
|
||||
Data: {'query': '中西方语言与文化的差异', 'title': '跨文化视角下中国文化对外传播路径琐谈跨文化,中国文化,传播,翻译'} prob: [0.7862964]
|
||||
Data: {'query': '中西方语言与文化的差异', 'title': '从中西方民族文化心理的差异看英汉翻译语言,文化,民族文化心理,思维方式,翻译'} prob: [0.91767514]
|
||||
Data: {'query': '中西方语言与文化的差异', 'title': '中英文化差异对翻译的影响中英文化,差异,翻译的影响'} prob: [0.8601747]
|
||||
Data: {'query': '中西方语言与文化的差异', 'title': '浅谈文化与语言习得文化,语言,文化与语言的关系,文化与语言习得意识,跨文化交际'} prob: [0.8944413]
|
||||
```
|
||||
|
||||
### Paddle Serving部署
|
||||
|
||||
Paddle Serving 的详细文档请参考 [Pipeline_Design](https://github.com/PaddlePaddle/Serving/blob/v0.7.0/doc/Python_Pipeline/Pipeline_Design_CN.md)和[Serving_Design](https://github.com/PaddlePaddle/Serving/blob/v0.7.0/doc/Serving_Design_CN.md),首先把静态图模型转换成Serving的格式:
|
||||
|
||||
```
|
||||
python export_to_serving.py \
|
||||
--dirname "output" \
|
||||
--model_filename "inference.predict.pdmodel" \
|
||||
--params_filename "inference.predict.pdiparams" \
|
||||
--server_path "serving_server" \
|
||||
--client_path "serving_client" \
|
||||
--fetch_alias_names "predict"
|
||||
|
||||
```
|
||||
|
||||
参数含义说明
|
||||
* `dirname`: 需要转换的模型文件存储路径,Program 结构文件和参数文件均保存在此目录。
|
||||
* `model_filename`: 存储需要转换的模型 Inference Program 结构的文件名称。如果设置为 None ,则使用 `__model__` 作为默认的文件名
|
||||
* `params_filename`: 存储需要转换的模型所有参数的文件名称。当且仅当所有模型参数被保>存在一个单独的二进制文件中,它才需要被指定。如果模型参数是存储在各自分离的文件中,设置它的值为 None
|
||||
* `server_path`: 转换后的模型文件和配置文件的存储路径。默认值为 serving_server
|
||||
* `client_path`: 转换后的客户端配置文件存储路径。默认值为 serving_client
|
||||
* `fetch_alias_names`: 模型输出的别名设置,比如输入的 input_ids 等,都可以指定成其他名字,默认不指定
|
||||
* `feed_alias_names`: 模型输入的别名设置,比如输出 pooled_out 等,都可以重新指定成其他模型,默认不指定
|
||||
|
||||
也可以运行下面的 bash 脚本:
|
||||
```
|
||||
sh scripts/export_to_serving.sh
|
||||
```
|
||||
Paddle Serving的部署有两种方式,第一种方式是Pipeline的方式,第二种是C++的方式,下面分别介绍这两种方式的用法:
|
||||
|
||||
#### Pipeline方式
|
||||
|
||||
修改`Tokenizer`
|
||||
|
||||
```
|
||||
self.tokenizer = AutoTokenizer.from_pretrained('ernie-3.0-medium-zh')
|
||||
```
|
||||
|
||||
启动 Pipeline Server:
|
||||
|
||||
```
|
||||
python web_service.py
|
||||
```
|
||||
|
||||
启动客户端调用 Server。
|
||||
|
||||
首先修改rpc_client.py中需要预测的样本:
|
||||
|
||||
```
|
||||
list_data = [{"query":"中西方语言与文化的差异","title":"第二语言习得的一大障碍就是文化差异。"}]`
|
||||
```
|
||||
然后运行:
|
||||
```
|
||||
python rpc_client.py
|
||||
```
|
||||
模型的输出为:
|
||||
|
||||
```
|
||||
PipelineClient::predict pack_data time:1656912047.5986433
|
||||
PipelineClient::predict before time:1656912047.599081
|
||||
time to cost :0.012039899826049805 seconds
|
||||
(1, 1)
|
||||
[[0.85112208]]
|
||||
```
|
||||
可以看到客户端发送了1条文本,这条文本的相似的概率值。
|
||||
|
||||
#### C++的方式
|
||||
|
||||
启动C++的Serving:
|
||||
|
||||
```
|
||||
python -m paddle_serving_server.serve --model serving_server --port 8600 --gpu_id 0 --thread 5 --ir_optim True
|
||||
```
|
||||
也可以使用脚本:
|
||||
|
||||
```
|
||||
sh deploy/cpp/start_server.sh
|
||||
```
|
||||
Client 可以使用 http 或者 rpc 两种方式,rpc 的方式为:
|
||||
|
||||
```
|
||||
python deploy/cpp/rpc_client.py
|
||||
```
|
||||
运行的输出为:
|
||||
|
||||
```
|
||||
I0704 05:19:00.443437 1987 general_model.cpp:490] [client]logid=0,client_cost=8.477ms,server_cost=6.458ms.
|
||||
time to cost :0.008707761764526367 seconds
|
||||
{'predict': array([[0.8511221]], dtype=float32)}
|
||||
```
|
||||
可以看到服务端返回了相似度结果
|
||||
|
||||
或者使用 http 的客户端访问模式:
|
||||
|
||||
```
|
||||
python deploy/cpp/http_client.py
|
||||
```
|
||||
运行的输出为:
|
||||
```
|
||||
time to cost :0.006819009780883789 seconds
|
||||
[0.8511220812797546]
|
||||
```
|
||||
可以看到服务端返回了相似度结果
|
||||
|
||||
也可以使用curl方式发送Http请求:
|
||||
|
||||
```
|
||||
curl -XPOST http://0.0.0.0:8600/GeneralModelService/inference -d ' {"tensor":[{"int64_data":[ 1, 12, 213, 58, 405, 545, 54, 68, 73,
|
||||
5, 859, 712, 2, 131, 177, 405, 545, 489,
|
||||
116, 5, 7, 19, 843, 1767, 113, 10, 68,
|
||||
73, 859, 712, 12043, 2],"elem_type":0,"name":"input_ids","alias_name":"input_ids","shape":[1,32]},
|
||||
{"int64_data":[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1,
|
||||
1, 1, 1, 1, 1, 1, 1, 1, 1, 1],"elem_type":0,"name":"token_type_ids","alias_name":"token_type_ids","shape":[1,32]}
|
||||
],
|
||||
"fetch_var_names":["sigmoid_2.tmp_0"],
|
||||
"log_id":0
|
||||
}'
|
||||
```
|
||||
|
||||
|
||||
## Reference
|
||||
|
||||
[1] Xiao, Dongling, Yu-Kun Li, Han Zhang, Yu Sun, Hao Tian, Hua Wu, and Haifeng Wang. “ERNIE-Gram: Pre-Training with Explicitly N-Gram Masked Language Modeling for Natural Language Understanding.” ArXiv:2010.12148 [Cs].
|
||||
157
applications/neural_search/ranking/ernie_matching/data.py
Normal file
157
applications/neural_search/ranking/ernie_matching/data.py
Normal file
@@ -0,0 +1,157 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import paddle
|
||||
import numpy as np
|
||||
|
||||
from paddlenlp.datasets import MapDataset
|
||||
|
||||
|
||||
def create_dataloader(dataset,
|
||||
mode='train',
|
||||
batch_size=1,
|
||||
batchify_fn=None,
|
||||
trans_fn=None):
|
||||
if trans_fn:
|
||||
dataset = dataset.map(trans_fn)
|
||||
|
||||
shuffle = True if mode == 'train' else False
|
||||
if mode == 'train':
|
||||
batch_sampler = paddle.io.DistributedBatchSampler(dataset,
|
||||
batch_size=batch_size,
|
||||
shuffle=shuffle)
|
||||
else:
|
||||
batch_sampler = paddle.io.BatchSampler(dataset,
|
||||
batch_size=batch_size,
|
||||
shuffle=shuffle)
|
||||
|
||||
return paddle.io.DataLoader(dataset=dataset,
|
||||
batch_sampler=batch_sampler,
|
||||
collate_fn=batchify_fn,
|
||||
return_list=True)
|
||||
|
||||
|
||||
def read_text_pair(data_path):
|
||||
"""Reads data."""
|
||||
with open(data_path, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
data = line.rstrip().split("\t")
|
||||
if len(data) != 3:
|
||||
continue
|
||||
yield {'query': data[0], 'title': data[1]}
|
||||
|
||||
|
||||
def convert_pointwise_example(example,
|
||||
tokenizer,
|
||||
max_seq_length=512,
|
||||
is_test=False):
|
||||
|
||||
query, title = example["query"], example["title"]
|
||||
|
||||
encoded_inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
if not is_test:
|
||||
label = np.array([example["label"]], dtype="int64")
|
||||
return input_ids, token_type_ids, label
|
||||
else:
|
||||
return input_ids, token_type_ids
|
||||
|
||||
|
||||
def convert_pairwise_example(example,
|
||||
tokenizer,
|
||||
max_seq_length=512,
|
||||
phase="train"):
|
||||
|
||||
if phase == "train":
|
||||
query, pos_title, neg_title = example["query"], example[
|
||||
"title"], example["neg_title"]
|
||||
|
||||
pos_inputs = tokenizer(text=query,
|
||||
text_pair=pos_title,
|
||||
max_seq_len=max_seq_length)
|
||||
neg_inputs = tokenizer(text=query,
|
||||
text_pair=neg_title,
|
||||
max_seq_len=max_seq_length)
|
||||
|
||||
pos_input_ids = pos_inputs["input_ids"]
|
||||
pos_token_type_ids = pos_inputs["token_type_ids"]
|
||||
neg_input_ids = neg_inputs["input_ids"]
|
||||
neg_token_type_ids = neg_inputs["token_type_ids"]
|
||||
|
||||
return (pos_input_ids, pos_token_type_ids, neg_input_ids,
|
||||
neg_token_type_ids)
|
||||
|
||||
else:
|
||||
query, title = example["query"], example["title"]
|
||||
|
||||
inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
|
||||
input_ids = inputs["input_ids"]
|
||||
token_type_ids = inputs["token_type_ids"]
|
||||
if phase == "eval":
|
||||
return input_ids, token_type_ids, example["label"]
|
||||
elif phase == "predict":
|
||||
return input_ids, token_type_ids
|
||||
else:
|
||||
raise ValueError("not supported phase:{}".format(phase))
|
||||
|
||||
|
||||
def gen_pair(dataset, pool_size=100):
|
||||
"""
|
||||
Generate triplet randomly based on dataset
|
||||
|
||||
Args:
|
||||
dataset: A `MapDataset` or `IterDataset` or a tuple of those.
|
||||
Each example is composed of 2 texts: exampe["query"], example["title"]
|
||||
pool_size: the number of example to sample negative example randomly
|
||||
|
||||
Return:
|
||||
dataset: A `MapDataset` or `IterDataset` or a tuple of those.
|
||||
Each example is composed of 2 texts: exampe["query"], example["pos_title"]、example["neg_title"]
|
||||
"""
|
||||
|
||||
if len(dataset) < pool_size:
|
||||
pool_size = len(dataset)
|
||||
|
||||
new_examples = []
|
||||
pool = []
|
||||
tmp_exmaples = []
|
||||
|
||||
for example in dataset:
|
||||
label = example["label"]
|
||||
|
||||
# Filter negative example
|
||||
if label == 0:
|
||||
continue
|
||||
|
||||
tmp_exmaples.append(example)
|
||||
pool.append(example["title"])
|
||||
|
||||
if len(pool) >= pool_size:
|
||||
np.random.shuffle(pool)
|
||||
for idx, example in enumerate(tmp_exmaples):
|
||||
example["neg_title"] = pool[idx]
|
||||
new_examples.append(example)
|
||||
tmp_exmaples = []
|
||||
pool = []
|
||||
else:
|
||||
continue
|
||||
return MapDataset(new_examples)
|
||||
@@ -0,0 +1,71 @@
|
||||
# coding:utf-8
|
||||
# pylint: disable=doc-string-missing
|
||||
# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import time
|
||||
import numpy as np
|
||||
import requests
|
||||
import json
|
||||
|
||||
from paddle_serving_client.httpclient import HttpClient
|
||||
import paddlenlp as ppnlp
|
||||
|
||||
|
||||
def convert_example(example, tokenizer, max_seq_length=512):
|
||||
|
||||
query, title = example["query"], example["title"]
|
||||
encoded_inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
return input_ids, token_type_ids
|
||||
|
||||
|
||||
# 启动python客户端
|
||||
endpoint_list = ['127.0.0.1:8600']
|
||||
client = HttpClient()
|
||||
client.load_client_config('serving_client')
|
||||
client.connect(endpoint_list)
|
||||
feed_names = client.feed_names_
|
||||
fetch_names = client.fetch_names_
|
||||
|
||||
# 创建tokenizer
|
||||
tokenizer = ppnlp.transformers.ErnieTokenizer.from_pretrained('ernie-gram-zh')
|
||||
max_seq_len = 64
|
||||
|
||||
# 数据预处理
|
||||
list_data = [{"query": "中西方语言与文化的差异", "title": "第二语言习得的一大障碍就是文化差异。"}]
|
||||
|
||||
input_ids, token_type_ids = [], []
|
||||
for example in list_data:
|
||||
input_id, token_type_id = convert_example(example,
|
||||
tokenizer,
|
||||
max_seq_length=max_seq_len)
|
||||
input_ids.append(input_id)
|
||||
token_type_ids.append(token_type_id)
|
||||
|
||||
feed_dict = {}
|
||||
feed_dict['input_ids'] = np.array(input_ids)
|
||||
feed_dict['token_type_ids'] = np.array(token_type_ids)
|
||||
# batch设置为True表示的是批量预测
|
||||
b_start = time.time()
|
||||
result = client.predict(feed=feed_dict, fetch=fetch_names, batch=True)
|
||||
b_end = time.time()
|
||||
print(result)
|
||||
print("time to cost :{} seconds".format(b_end - b_start))
|
||||
print(result.outputs[0].tensor[0].float_data)
|
||||
@@ -0,0 +1,69 @@
|
||||
# coding:utf-8
|
||||
# pylint: disable=doc-string-missing
|
||||
# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import time
|
||||
import numpy as np
|
||||
|
||||
from paddle_serving_client import Client
|
||||
import paddlenlp as ppnlp
|
||||
|
||||
|
||||
def convert_example(example, tokenizer, max_seq_length=512):
|
||||
|
||||
query, title = example["query"], example["title"]
|
||||
encoded_inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
return input_ids, token_type_ids
|
||||
|
||||
|
||||
# 启动python客户端
|
||||
endpoint_list = ['127.0.0.1:8600']
|
||||
client = Client()
|
||||
client.load_client_config('serving_client')
|
||||
client.connect(endpoint_list)
|
||||
feed_names = client.feed_names_
|
||||
fetch_names = client.fetch_names_
|
||||
|
||||
# 创建tokenizer
|
||||
tokenizer = ppnlp.transformers.ErnieTokenizer.from_pretrained('ernie-gram-zh')
|
||||
max_seq_len = 64
|
||||
|
||||
# 数据预处理
|
||||
list_data = [{"query": "中西方语言与文化的差异", "title": "第二语言习得的一大障碍就是文化差异。"}]
|
||||
|
||||
input_ids, token_type_ids = [], []
|
||||
for example in list_data:
|
||||
input_id, token_type_id = convert_example(example,
|
||||
tokenizer,
|
||||
max_seq_length=max_seq_len)
|
||||
input_ids.append(input_id)
|
||||
token_type_ids.append(token_type_id)
|
||||
|
||||
feed_dict = {}
|
||||
feed_dict['input_ids'] = np.array(input_ids)
|
||||
feed_dict['token_type_ids'] = np.array(token_type_ids)
|
||||
# batch设置为True表示的是批量预测
|
||||
b_start = time.time()
|
||||
result = client.predict(feed=feed_dict, fetch=fetch_names, batch=True)
|
||||
b_end = time.time()
|
||||
print("time to cost :{} seconds".format(b_end - b_start))
|
||||
print(result)
|
||||
@@ -0,0 +1 @@
|
||||
python -m paddle_serving_server.serve --model serving_server --port 8600 --gpu_id 0 --thread 5 --ir_optim True
|
||||
@@ -0,0 +1,34 @@
|
||||
# worker_num, 最大并发数。当build_dag_each_worker=True时, 框架会创建worker_num个进程,每个进程内构建grpcSever和DAG
|
||||
# 当build_dag_each_worker=False时,框架会设置主线程grpc线程池的max_workers=worker_num
|
||||
worker_num: 20
|
||||
# build_dag_each_worker, False,框架在进程内创建一条DAG;True,框架会每个进程内创建多个独立的DAG
|
||||
build_dag_each_worker: false
|
||||
|
||||
dag:
|
||||
# op资源类型, True, 为线程模型;False,为进程模型
|
||||
is_thread_op: False
|
||||
# 使用性能分析, True,生成Timeline性能数据,对性能有一定影响;False为不使用
|
||||
tracer:
|
||||
interval_s: 10
|
||||
# http端口, rpc_port和http_port不允许同时为空。当rpc_port可用且http_port为空时,不自动生成http_port
|
||||
http_port: 8088
|
||||
# rpc端口, rpc_port和http_port不允许同时为空。当rpc_port为空且http_port不为空时,会自动将rpc_port设置为http_port+1
|
||||
rpc_port: 8089
|
||||
op:
|
||||
ernie:
|
||||
# 并发数,is_thread_op=True时,为线程并发;否则为进程并发
|
||||
concurrency: 1
|
||||
# 当op配置没有server_endpoints时,从local_service_conf读取本地服务配置
|
||||
local_service_conf:
|
||||
# client类型,包括brpc, grpc和local_predictor.local_predictor不启动Serving服务,进程内预测
|
||||
client_type: local_predictor
|
||||
# ir_optim
|
||||
ir_optim: True
|
||||
# device_type, 0=cpu, 1=gpu, 2=tensorRT, 3=arm cpu, 4=kunlun xpu
|
||||
device_type: 1
|
||||
# 计算硬件ID,当devices为""或不写时为CPU预测;当devices为"0", "0,1,2"时为GPU预测,表示使用的GPU卡
|
||||
devices: "0"
|
||||
# Fetch结果列表,以client_config中fetch_var的alias_name为准, 如果没有设置则全部返回
|
||||
fetch_list: ['predict']
|
||||
# 模型路径
|
||||
model_config: ../../serving_server/
|
||||
@@ -0,0 +1,3 @@
|
||||
python deploy/python/predict.py --model_dir ./output \
|
||||
--input_file sort/test_pairwise.csv \
|
||||
--model_name_or_path ernie-3.0-medium-zh
|
||||
@@ -0,0 +1,249 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import argparse
|
||||
import os
|
||||
import sys
|
||||
|
||||
from scipy.special import softmax
|
||||
from scipy.special import expit
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
|
||||
import paddle
|
||||
from paddle import inference
|
||||
import paddle.nn.functional as F
|
||||
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from paddlenlp.datasets import load_dataset
|
||||
from paddlenlp.utils.log import logger
|
||||
from paddlenlp.transformers import AutoTokenizer, AutoModel
|
||||
|
||||
sys.path.append('.')
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--model_dir", type=str, required=True,
|
||||
help="The directory to static model.")
|
||||
|
||||
parser.add_argument("--max_seq_length", default=128, type=int,
|
||||
help="The maximum total input sequence length after tokenization. Sequences "
|
||||
"longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--batch_size", default=32, type=int,
|
||||
help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument('--device', choices=['cpu', 'gpu', 'xpu'], default="gpu",
|
||||
help="Select which device to train model, defaults to gpu.")
|
||||
parser.add_argument("--input_file", type=str, required=True,
|
||||
help="The test set file.")
|
||||
parser.add_argument('--use_tensorrt', default=False, type=eval, choices=[True, False],
|
||||
help='Enable to use tensorrt to speed up.')
|
||||
parser.add_argument("--precision", default="fp32", type=str, choices=["fp32", "fp16", "int8"],
|
||||
help='The tensorrt precision.')
|
||||
|
||||
parser.add_argument('--cpu_threads', default=10, type=int,
|
||||
help='Number of threads to predict when using cpu.')
|
||||
parser.add_argument('--enable_mkldnn', default=False, type=eval, choices=[True, False],
|
||||
help='Enable to use mkldnn to speed up when using cpu.')
|
||||
|
||||
parser.add_argument("--benchmark", type=eval, default=False,
|
||||
help="To log some information about environment and running.")
|
||||
parser.add_argument("--save_log_path", type=str, default="./log_output/",
|
||||
help="The file path to save log.")
|
||||
parser.add_argument('--model_name_or_path', default="ernie-3.0-medium-zh", help="The pretrained model used for training")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
def read_text_pair(data_path):
|
||||
"""Reads data."""
|
||||
with open(data_path, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
data = line.rstrip().split("\t")
|
||||
if len(data) != 3:
|
||||
continue
|
||||
yield {'query': data[0], 'title': data[1]}
|
||||
|
||||
|
||||
def convert_example(example, tokenizer, max_seq_length=512, is_test=False):
|
||||
|
||||
query, title = example["query"], example["title"]
|
||||
|
||||
encoded_inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
if not is_test:
|
||||
label = np.array([example["label"]], dtype="int64")
|
||||
return input_ids, token_type_ids, label
|
||||
else:
|
||||
return input_ids, token_type_ids
|
||||
|
||||
|
||||
class Predictor(object):
|
||||
|
||||
def __init__(self,
|
||||
model_dir,
|
||||
device="gpu",
|
||||
max_seq_length=128,
|
||||
batch_size=32,
|
||||
use_tensorrt=False,
|
||||
precision="fp32",
|
||||
cpu_threads=10,
|
||||
enable_mkldnn=False):
|
||||
self.max_seq_length = max_seq_length
|
||||
self.batch_size = batch_size
|
||||
|
||||
model_file = model_dir + "/inference.predict.pdmodel"
|
||||
params_file = model_dir + "/inference.predict.pdiparams"
|
||||
if not os.path.exists(model_file):
|
||||
raise ValueError("not find model file path {}".format(model_file))
|
||||
if not os.path.exists(params_file):
|
||||
raise ValueError("not find params file path {}".format(params_file))
|
||||
config = paddle.inference.Config(model_file, params_file)
|
||||
|
||||
if device == "gpu":
|
||||
# set GPU configs accordingly
|
||||
# such as intialize the gpu memory, enable tensorrt
|
||||
config.enable_use_gpu(100, 0)
|
||||
precision_map = {
|
||||
"fp16": inference.PrecisionType.Half,
|
||||
"fp32": inference.PrecisionType.Float32,
|
||||
"int8": inference.PrecisionType.Int8
|
||||
}
|
||||
precision_mode = precision_map[precision]
|
||||
|
||||
if args.use_tensorrt:
|
||||
config.enable_tensorrt_engine(max_batch_size=batch_size,
|
||||
min_subgraph_size=30,
|
||||
precision_mode=precision_mode)
|
||||
elif device == "cpu":
|
||||
# set CPU configs accordingly,
|
||||
# such as enable_mkldnn, set_cpu_math_library_num_threads
|
||||
config.disable_gpu()
|
||||
if args.enable_mkldnn:
|
||||
# cache 10 different shapes for mkldnn to avoid memory leak
|
||||
config.set_mkldnn_cache_capacity(10)
|
||||
config.enable_mkldnn()
|
||||
config.set_cpu_math_library_num_threads(args.cpu_threads)
|
||||
elif device == "xpu":
|
||||
# set XPU configs accordingly
|
||||
config.enable_xpu(100)
|
||||
|
||||
config.switch_use_feed_fetch_ops(False)
|
||||
self.predictor = paddle.inference.create_predictor(config)
|
||||
self.input_handles = [
|
||||
self.predictor.get_input_handle(name)
|
||||
for name in self.predictor.get_input_names()
|
||||
]
|
||||
self.output_handle = self.predictor.get_output_handle(
|
||||
self.predictor.get_output_names()[0])
|
||||
|
||||
if args.benchmark:
|
||||
import auto_log
|
||||
pid = os.getpid()
|
||||
self.autolog = auto_log.AutoLogger(model_name="ernie-tiny",
|
||||
model_precision=precision,
|
||||
batch_size=self.batch_size,
|
||||
data_shape="dynamic",
|
||||
save_path=args.save_log_path,
|
||||
inference_config=config,
|
||||
pids=pid,
|
||||
process_name=None,
|
||||
gpu_ids=0,
|
||||
time_keys=[
|
||||
'preprocess_time',
|
||||
'inference_time',
|
||||
'postprocess_time'
|
||||
],
|
||||
warmup=0,
|
||||
logger=logger)
|
||||
|
||||
def predict(self, data, tokenizer):
|
||||
"""
|
||||
Predicts the data labels.
|
||||
|
||||
Args:
|
||||
data (obj:`List(str)`): The batch data whose each element is a raw text.
|
||||
tokenizer(obj:`PretrainedTokenizer`): This tokenizer inherits from :class:`~paddlenlp.transformers.PretrainedTokenizer`
|
||||
which contains most of the methods. Users should refer to the superclass for more information regarding methods.
|
||||
label_map(obj:`dict`): The label id (key) to label str (value) map.
|
||||
|
||||
Returns:
|
||||
results(obj:`dict`): All the predictions labels.
|
||||
"""
|
||||
if args.benchmark:
|
||||
self.autolog.times.start()
|
||||
|
||||
examples = []
|
||||
for text in data:
|
||||
input_ids, segment_ids = convert_example(
|
||||
text,
|
||||
tokenizer,
|
||||
max_seq_length=self.max_seq_length,
|
||||
is_test=True)
|
||||
examples.append((input_ids, segment_ids))
|
||||
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"), # input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"
|
||||
), # segment
|
||||
): fn(samples)
|
||||
|
||||
if args.benchmark:
|
||||
self.autolog.times.stamp()
|
||||
|
||||
input_ids, segment_ids = batchify_fn(examples)
|
||||
self.input_handles[0].copy_from_cpu(input_ids)
|
||||
self.input_handles[1].copy_from_cpu(segment_ids)
|
||||
self.predictor.run()
|
||||
sim_score = self.output_handle.copy_to_cpu()
|
||||
if args.benchmark:
|
||||
self.autolog.times.stamp()
|
||||
sim_score = expit(sim_score)
|
||||
|
||||
if args.benchmark:
|
||||
self.autolog.times.end(stamp=True)
|
||||
|
||||
return sim_score
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
# Define predictor to do prediction.
|
||||
predictor = Predictor(args.model_dir, args.device, args.max_seq_length,
|
||||
args.batch_size, args.use_tensorrt, args.precision,
|
||||
args.cpu_threads, args.enable_mkldnn)
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
test_ds = load_dataset(read_text_pair,
|
||||
data_path=args.input_file,
|
||||
lazy=False)
|
||||
|
||||
data = [{'query': d['query'], 'title': d['title']} for d in test_ds]
|
||||
|
||||
batches = [
|
||||
data[idx:idx + args.batch_size]
|
||||
for idx in range(0, len(data), args.batch_size)
|
||||
]
|
||||
|
||||
results = []
|
||||
for batch_data in batches:
|
||||
results.extend(predictor.predict(batch_data, tokenizer))
|
||||
for idx, text in enumerate(data):
|
||||
print('Data: {} \t prob: {}'.format(text, results[idx]))
|
||||
if args.benchmark:
|
||||
predictor.autolog.report()
|
||||
@@ -0,0 +1,34 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
import time
|
||||
import numpy as np
|
||||
|
||||
from paddle_serving_server.pipeline import PipelineClient
|
||||
|
||||
client = PipelineClient()
|
||||
client.connect(['127.0.0.1:8089'])
|
||||
|
||||
list_data = [{"query": "中西方语言与文化的差异", "title": "第二语言习得的一大障碍就是文化差异。"}]
|
||||
feed = {}
|
||||
for i, item in enumerate(list_data):
|
||||
feed[str(i)] = str(item)
|
||||
|
||||
print(feed)
|
||||
start_time = time.time()
|
||||
ret = client.predict(feed_dict=feed)
|
||||
end_time = time.time()
|
||||
print("time to cost :{} seconds".format(end_time - start_time))
|
||||
result = np.array(eval(ret.value[0]))
|
||||
print(result.shape)
|
||||
print(result)
|
||||
@@ -0,0 +1,79 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import numpy as np
|
||||
import sys
|
||||
import json
|
||||
|
||||
from paddle_serving_server.web_service import WebService, Op
|
||||
|
||||
|
||||
def convert_example(example, tokenizer, max_seq_length=512):
|
||||
|
||||
query, title = example["query"], example["title"]
|
||||
encoded_inputs = tokenizer(text=query,
|
||||
text_pair=title,
|
||||
max_seq_len=max_seq_length)
|
||||
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
|
||||
return input_ids, token_type_ids
|
||||
|
||||
|
||||
class ErnieOp(Op):
|
||||
|
||||
def init_op(self):
|
||||
from paddlenlp.transformers import AutoTokenizer
|
||||
self.tokenizer = AutoTokenizer.from_pretrained('ernie-3.0-medium-zh')
|
||||
|
||||
def preprocess(self, input_dicts, data_id, log_id):
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
|
||||
(_, input_dict), = input_dicts.items()
|
||||
print("input dict", input_dict)
|
||||
batch_size = len(input_dict.keys())
|
||||
examples = []
|
||||
for i in range(batch_size):
|
||||
example = json.loads(input_dict[str(i)].replace("\'", "\""))
|
||||
input_ids, segment_ids = convert_example(example, self.tokenizer)
|
||||
examples.append((input_ids, segment_ids))
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=self.tokenizer.pad_token_id, dtype="int64"
|
||||
), # input
|
||||
Pad(axis=0, pad_val=self.tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # segment
|
||||
): fn(samples)
|
||||
input_ids, segment_ids = batchify_fn(examples)
|
||||
feed_dict = {}
|
||||
feed_dict['input_ids'] = input_ids
|
||||
feed_dict['token_type_ids'] = segment_ids
|
||||
return feed_dict, False, None, ""
|
||||
|
||||
def postprocess(self, input_dicts, fetch_dict, data_id, log_id):
|
||||
new_dict = {}
|
||||
new_dict["predict"] = str(fetch_dict["predict"].tolist())
|
||||
return new_dict, None, ""
|
||||
|
||||
|
||||
class ErnieService(WebService):
|
||||
|
||||
def get_pipeline_response(self, read_op):
|
||||
ernie_op = ErnieOp(name="ernie", input_ops=[read_op])
|
||||
return ernie_op
|
||||
|
||||
|
||||
ernie_service = ErnieService(name="ernie")
|
||||
ernie_service.prepare_pipeline_config("config_nlp.yml")
|
||||
ernie_service.run_service()
|
||||
150
applications/neural_search/ranking/ernie_matching/evaluate.py
Normal file
150
applications/neural_search/ranking/ernie_matching/evaluate.py
Normal file
@@ -0,0 +1,150 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import os
|
||||
import random
|
||||
import time
|
||||
|
||||
import numpy as np
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from paddlenlp.datasets import load_dataset
|
||||
from paddlenlp.transformers import LinearDecayWithWarmup, AutoModel, AutoTokenizer
|
||||
|
||||
from data import create_dataloader, gen_pair
|
||||
from data import convert_pairwise_example as convert_example
|
||||
from model import PairwiseMatching
|
||||
import pandas as pd
|
||||
from tqdm import tqdm
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--margin", default=0.1, type=float, help="Margin for pos_score and neg_score.")
|
||||
parser.add_argument("--test_file", type=str, required=True, help="The full path of test file")
|
||||
|
||||
parser.add_argument("--max_seq_length", default=128, type=int, help="The maximum total input sequence length after tokenization. "
|
||||
"Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--batch_size", default=32, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument('--model_name_or_path', default="ernie-3.0-medium-zh", help="The pretrained model used for training")
|
||||
parser.add_argument("--init_from_ckpt", type=str, default=None, help="The path of checkpoint to be loaded.")
|
||||
parser.add_argument("--seed", type=int, default=1000, help="Random seed for initialization.")
|
||||
parser.add_argument('--device', choices=['cpu', 'gpu'], default="gpu", help="Select which device to train model, defaults to gpu.")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
def set_seed(seed):
|
||||
"""sets random seed"""
|
||||
random.seed(seed)
|
||||
np.random.seed(seed)
|
||||
paddle.seed(seed)
|
||||
|
||||
|
||||
@paddle.no_grad()
|
||||
def evaluate(model, metric, data_loader, phase="dev"):
|
||||
"""
|
||||
Given a dataset, it evals model and computes the metric.
|
||||
|
||||
Args:
|
||||
model(obj:`paddle.nn.Layer`): A model to classify texts.
|
||||
data_loader(obj:`paddle.io.DataLoader`): The dataset loader which generates batches.
|
||||
metric(obj:`paddle.metric.Metric`): The evaluation metric.
|
||||
"""
|
||||
model.eval()
|
||||
metric.reset()
|
||||
|
||||
for idx, batch in enumerate(data_loader):
|
||||
input_ids, token_type_ids, labels = batch
|
||||
|
||||
pos_probs = model.predict(input_ids=input_ids,
|
||||
token_type_ids=token_type_ids)
|
||||
|
||||
neg_probs = 1.0 - pos_probs
|
||||
|
||||
preds = np.concatenate((neg_probs, pos_probs), axis=1)
|
||||
metric.update(preds=preds, labels=labels)
|
||||
|
||||
print("eval_{} auc:{:.3}".format(phase, metric.accumulate()))
|
||||
metric.reset()
|
||||
model.train()
|
||||
|
||||
|
||||
# 构建读取函数,读取原始数据
|
||||
def read(src_path, is_predict=False):
|
||||
data = pd.read_csv(src_path, sep='\t')
|
||||
for index, row in tqdm(data.iterrows()):
|
||||
query = row['query']
|
||||
title = row['title']
|
||||
neg_title = row['neg_title']
|
||||
yield {'query': query, 'title': title, 'neg_title': neg_title}
|
||||
|
||||
|
||||
def read_test(src_path, is_predict=False):
|
||||
data = pd.read_csv(src_path, sep='\t')
|
||||
for index, row in tqdm(data.iterrows()):
|
||||
query = row['query']
|
||||
title = row['title']
|
||||
label = row['label']
|
||||
yield {'query': query, 'title': title, 'label': label}
|
||||
|
||||
|
||||
def main():
|
||||
paddle.set_device(args.device)
|
||||
rank = paddle.distributed.get_rank()
|
||||
if paddle.distributed.get_world_size() > 1:
|
||||
paddle.distributed.init_parallel_env()
|
||||
|
||||
set_seed(args.seed)
|
||||
|
||||
dev_ds = load_dataset(read_test, src_path=args.test_file, lazy=False)
|
||||
print(dev_ds[0])
|
||||
|
||||
pretrained_model = AutoModel.from_pretrained(args.model_name_or_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
trans_func_eval = partial(convert_example,
|
||||
tokenizer=tokenizer,
|
||||
max_seq_length=args.max_seq_length,
|
||||
phase="eval")
|
||||
|
||||
batchify_fn_eval = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"
|
||||
), # pair_input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # pair_segment
|
||||
Stack(dtype="int64") # label
|
||||
): [data for data in fn(samples)]
|
||||
|
||||
dev_data_loader = create_dataloader(dev_ds,
|
||||
mode='dev',
|
||||
batch_size=args.batch_size,
|
||||
batchify_fn=batchify_fn_eval,
|
||||
trans_fn=trans_func_eval)
|
||||
|
||||
model = PairwiseMatching(pretrained_model, margin=args.margin)
|
||||
|
||||
if args.init_from_ckpt and os.path.isfile(args.init_from_ckpt):
|
||||
state_dict = paddle.load(args.init_from_ckpt)
|
||||
model.set_dict(state_dict)
|
||||
|
||||
metric = paddle.metric.Auc()
|
||||
evaluate(model, metric, dev_data_loader, "dev")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,58 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import argparse
|
||||
import os
|
||||
|
||||
import numpy as np
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from paddlenlp.transformers import AutoModel, AutoTokenizer
|
||||
from model import PairwiseMatching
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--params_path", type=str, required=True, default='./checkpoint/model_900/model_state.pdparams', help="The path to model parameters to be loaded.")
|
||||
parser.add_argument("--output_path", type=str, default='./output', help="The path of model parameter in static graph to be saved.")
|
||||
parser.add_argument('--model_name_or_path', default="ernie-3.0-medium-zh", help="The pretrained model used for training")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
if __name__ == "__main__":
|
||||
pretrained_model = AutoModel.from_pretrained(args.model_name_or_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
model = PairwiseMatching(pretrained_model)
|
||||
|
||||
if args.params_path and os.path.isfile(args.params_path):
|
||||
state_dict = paddle.load(args.params_path)
|
||||
model.set_dict(state_dict)
|
||||
print("Loaded parameters from %s" % args.params_path)
|
||||
else:
|
||||
raise ValueError(
|
||||
"Please set --params_path with correct pretrained model file")
|
||||
model.eval()
|
||||
|
||||
# Convert to static graph with specific input description
|
||||
model = paddle.jit.to_static(
|
||||
model,
|
||||
input_spec=[
|
||||
paddle.static.InputSpec(shape=[None, None],
|
||||
dtype="int64"), # input_ids
|
||||
paddle.static.InputSpec(shape=[None, None],
|
||||
dtype="int64") # segment_ids
|
||||
])
|
||||
# Save in static graph model.
|
||||
save_path = os.path.join(args.output_path, "inference")
|
||||
paddle.jit.save(model, save_path)
|
||||
@@ -0,0 +1,47 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import argparse
|
||||
import paddle_serving_client.io as serving_io
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--dirname", type=str, required=True,
|
||||
default='./output', help="Path of saved model files. Program file and parameter files are saved in this directory.")
|
||||
parser.add_argument("--model_filename", type=str, required=True,
|
||||
default='inference.get_pooled_embedding.pdmodel', help="The name of file to load the inference program. If it is None, the default filename __model__ will be used.")
|
||||
parser.add_argument("--params_filename", type=str, required=True,
|
||||
default='inference.get_pooled_embedding.pdiparams', help="The name of file to load all parameters. It is only used for the case that all parameters were saved in a single binary file. If parameters were saved in separate files, set it as None. Default: None.")
|
||||
parser.add_argument("--server_path", type=str, default='./serving_server',
|
||||
help="The path of server parameter in static graph to be saved.")
|
||||
parser.add_argument("--client_path", type=str, default='./serving_client',
|
||||
help="The path of client parameter in static graph to be saved.")
|
||||
parser.add_argument("--feed_alias_names", type=str, default=None,
|
||||
help='set alias names for feed vars, split by comma \',\', you should run --show_proto to check the number of feed vars')
|
||||
parser.add_argument("--fetch_alias_names", type=str, default=None,
|
||||
help='set alias names for feed vars, split by comma \',\', you should run --show_proto to check the number of fetch vars')
|
||||
parser.add_argument("--show_proto", type=bool, default=False,
|
||||
help='If yes, you can preview the proto and then determine your feed var alias name and fetch var alias name.')
|
||||
# yapf: enable
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parser.parse_args()
|
||||
serving_io.inference_model_to_serving(
|
||||
dirname=args.dirname,
|
||||
serving_server=args.server_path,
|
||||
serving_client=args.client_path,
|
||||
model_filename=args.model_filename,
|
||||
params_filename=args.params_filename,
|
||||
show_proto=args.show_proto,
|
||||
feed_alias_names=args.feed_alias_names,
|
||||
fetch_alias_names=args.fetch_alias_names)
|
||||
84
applications/neural_search/ranking/ernie_matching/model.py
Normal file
84
applications/neural_search/ranking/ernie_matching/model.py
Normal file
@@ -0,0 +1,84 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License"
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import paddle
|
||||
import paddle.nn as nn
|
||||
import paddle.nn.functional as F
|
||||
|
||||
|
||||
class PairwiseMatching(nn.Layer):
|
||||
|
||||
def __init__(self, pretrained_model, dropout=None, margin=0.1):
|
||||
super().__init__()
|
||||
self.ptm = pretrained_model
|
||||
self.dropout = nn.Dropout(dropout if dropout is not None else 0.1)
|
||||
self.margin = margin
|
||||
|
||||
# hidden_size -> 1, calculate similarity
|
||||
self.similarity = nn.Linear(self.ptm.config["hidden_size"], 1)
|
||||
|
||||
@paddle.jit.to_static(input_spec=[
|
||||
paddle.static.InputSpec(shape=[None, None], dtype='int64'),
|
||||
paddle.static.InputSpec(shape=[None, None], dtype='int64')
|
||||
])
|
||||
def predict(self,
|
||||
input_ids,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
attention_mask=None):
|
||||
|
||||
_, cls_embedding = self.ptm(input_ids, token_type_ids, position_ids,
|
||||
attention_mask)
|
||||
|
||||
cls_embedding = self.dropout(cls_embedding)
|
||||
sim_score = self.similarity(cls_embedding)
|
||||
sim_score = F.sigmoid(sim_score)
|
||||
|
||||
return sim_score
|
||||
|
||||
def forward(self,
|
||||
pos_input_ids,
|
||||
neg_input_ids,
|
||||
pos_token_type_ids=None,
|
||||
neg_token_type_ids=None,
|
||||
pos_position_ids=None,
|
||||
neg_position_ids=None,
|
||||
pos_attention_mask=None,
|
||||
neg_attention_mask=None):
|
||||
|
||||
_, pos_cls_embedding = self.ptm(pos_input_ids, pos_token_type_ids,
|
||||
pos_position_ids, pos_attention_mask)
|
||||
|
||||
_, neg_cls_embedding = self.ptm(neg_input_ids, neg_token_type_ids,
|
||||
neg_position_ids, neg_attention_mask)
|
||||
|
||||
pos_embedding = self.dropout(pos_cls_embedding)
|
||||
neg_embedding = self.dropout(neg_cls_embedding)
|
||||
|
||||
pos_sim = self.similarity(pos_embedding)
|
||||
neg_sim = self.similarity(neg_embedding)
|
||||
|
||||
pos_sim = F.sigmoid(pos_sim)
|
||||
neg_sim = F.sigmoid(neg_sim)
|
||||
|
||||
labels = paddle.full(shape=[pos_cls_embedding.shape[0]],
|
||||
fill_value=1.0,
|
||||
dtype='float32')
|
||||
|
||||
loss = F.margin_ranking_loss(pos_sim,
|
||||
neg_sim,
|
||||
labels,
|
||||
margin=self.margin)
|
||||
|
||||
return loss
|
||||
@@ -0,0 +1,122 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import sys
|
||||
import os
|
||||
import random
|
||||
import time
|
||||
|
||||
import numpy as np
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
from paddlenlp.datasets import load_dataset
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from paddlenlp.transformers import AutoModel, AutoTokenizer
|
||||
|
||||
from data import create_dataloader, read_text_pair
|
||||
from data import convert_pairwise_example as convert_example
|
||||
from model import PairwiseMatching
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--input_file", type=str, required=True, help="The full path of input file")
|
||||
parser.add_argument("--params_path", type=str, required=True, help="The path to model parameters to be loaded.")
|
||||
parser.add_argument("--max_seq_length", default=64, type=int, help="The maximum total input sequence length after tokenization. "
|
||||
"Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument('--model_name_or_path', default="ernie-3.0-medium-zh", help="The pretrained model used for training")
|
||||
parser.add_argument("--batch_size", default=32, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument('--device', choices=['cpu', 'gpu'], default="gpu", help="Select which device to train model, defaults to gpu.")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
def predict(model, data_loader):
|
||||
"""
|
||||
Predicts the data labels.
|
||||
|
||||
Args:
|
||||
model (obj:`SemanticIndexBase`): A model to extract text embedding or calculate similarity of text pair.
|
||||
data_loaer (obj:`List(Example)`): The processed data ids of text pair: [query_input_ids, query_token_type_ids, title_input_ids, title_token_type_ids]
|
||||
Returns:
|
||||
results(obj:`List`): cosine similarity of text pairs.
|
||||
"""
|
||||
batch_probs = []
|
||||
|
||||
model.eval()
|
||||
|
||||
with paddle.no_grad():
|
||||
for batch_data in data_loader:
|
||||
input_ids, token_type_ids = batch_data
|
||||
|
||||
batch_prob = model.predict(input_ids=input_ids,
|
||||
token_type_ids=token_type_ids).numpy()
|
||||
|
||||
batch_probs.append(batch_prob)
|
||||
if (len(batch_prob) == 1):
|
||||
batch_probs = np.array(batch_probs)
|
||||
else:
|
||||
batch_probs = np.concatenate(batch_probs, axis=0)
|
||||
|
||||
return batch_probs
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
paddle.set_device(args.device)
|
||||
|
||||
pretrained_model = AutoModel.from_pretrained(args.model_name_or_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
trans_func = partial(convert_example,
|
||||
tokenizer=tokenizer,
|
||||
max_seq_length=args.max_seq_length,
|
||||
phase="predict")
|
||||
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"), # input_ids
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # segment_ids
|
||||
): [data for data in fn(samples)]
|
||||
|
||||
valid_ds = load_dataset(read_text_pair,
|
||||
data_path=args.input_file,
|
||||
lazy=False)
|
||||
|
||||
valid_data_loader = create_dataloader(valid_ds,
|
||||
mode='predict',
|
||||
batch_size=args.batch_size,
|
||||
batchify_fn=batchify_fn,
|
||||
trans_fn=trans_func)
|
||||
|
||||
model = PairwiseMatching(pretrained_model)
|
||||
|
||||
if args.params_path and os.path.isfile(args.params_path):
|
||||
state_dict = paddle.load(args.params_path)
|
||||
model.set_dict(state_dict)
|
||||
print("Loaded parameters from %s" % args.params_path)
|
||||
else:
|
||||
raise ValueError(
|
||||
"Please set --params_path with correct pretrained model file")
|
||||
|
||||
y_probs = predict(model, valid_data_loader)
|
||||
|
||||
valid_ds = load_dataset(read_text_pair,
|
||||
data_path=args.input_file,
|
||||
lazy=False)
|
||||
|
||||
for idx, prob in enumerate(y_probs):
|
||||
text_pair = valid_ds[idx]
|
||||
text_pair["pred_prob"] = prob[0]
|
||||
print(text_pair)
|
||||
@@ -0,0 +1,16 @@
|
||||
unset CUDA_VISIBLE_DEVICES
|
||||
# gpu
|
||||
python -u -m paddle.distributed.launch --gpus "0" evaluate.py \
|
||||
--device gpu \
|
||||
--batch_size 32 \
|
||||
--learning_rate 2E-5 \
|
||||
--init_from_ckpt "./checkpoints/model_30000/model_state.pdparams" \
|
||||
--test_file sort/dev_pairwise.csv
|
||||
|
||||
# cpu
|
||||
# python evaluate.py \
|
||||
# --device cpu \
|
||||
# --batch_size 32 \
|
||||
# --learning_rate 2E-5 \
|
||||
# --init_from_ckpt "./checkpoints/model_30000/model_state.pdparams" \
|
||||
# --test_file sort/dev_pairwise.csv
|
||||
@@ -0,0 +1,3 @@
|
||||
python export_model.py --params_path checkpoints/model_30000/model_state.pdparams \
|
||||
--output_path=./output \
|
||||
--model_name_or_path ernie-3.0-medium-zh
|
||||
@@ -0,0 +1,7 @@
|
||||
python export_to_serving.py \
|
||||
--dirname "output" \
|
||||
--model_filename "inference.predict.pdmodel" \
|
||||
--params_filename "inference.predict.pdiparams" \
|
||||
--server_path "serving_server" \
|
||||
--client_path "serving_client" \
|
||||
--fetch_alias_names "predict"
|
||||
@@ -0,0 +1,15 @@
|
||||
# gpu
|
||||
python -u -m paddle.distributed.launch --gpus "0" \
|
||||
predict_pairwise.py \
|
||||
--device gpu \
|
||||
--params_path "./checkpoints/model_30000/model_state.pdparams"\
|
||||
--batch_size 128 \
|
||||
--max_seq_length 64 \
|
||||
--input_file 'sort/test_pairwise.csv'
|
||||
# cpu
|
||||
# python predict_pairwise.py \
|
||||
# --device gpu \
|
||||
# --params_path "./checkpoints/model_30000/model_state.pdparams"\
|
||||
# --batch_size 128 \
|
||||
# --max_seq_length 64 \
|
||||
# --input_file 'sort/test_pairwise.csv'
|
||||
@@ -0,0 +1,21 @@
|
||||
# gpu
|
||||
python -u -m paddle.distributed.launch --gpus="0,1,2,3" train_pairwise.py \
|
||||
--device gpu \
|
||||
--save_dir ./checkpoints \
|
||||
--batch_size 32 \
|
||||
--learning_rate 2E-5 \
|
||||
--margin 0.1 \
|
||||
--eval_step 100 \
|
||||
--train_file sort/train_pairwise.csv \
|
||||
--test_file sort/dev_pairwise.csv
|
||||
|
||||
# cpu
|
||||
# python train_pairwise.py \
|
||||
# --device cpu \
|
||||
# --save_dir ./checkpoints \
|
||||
# --batch_size 32 \
|
||||
# --learning_rate 2E-5 \
|
||||
# --margin 0.1 \
|
||||
# --eval_step 100 \
|
||||
# --train_file sort/train_pairwise.csv \
|
||||
# --test_file sort/dev_pairwise.csv
|
||||
@@ -0,0 +1,230 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import os
|
||||
import random
|
||||
import time
|
||||
|
||||
import numpy as np
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
from paddlenlp.datasets import load_dataset
|
||||
from paddlenlp.transformers import LinearDecayWithWarmup, AutoModel, AutoTokenizer
|
||||
|
||||
from data import create_dataloader, gen_pair
|
||||
from data import convert_pairwise_example as convert_example
|
||||
from model import PairwiseMatching
|
||||
import pandas as pd
|
||||
from tqdm import tqdm
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--margin", default=0.2, type=float, help="Margin for pos_score and neg_score.")
|
||||
parser.add_argument("--train_file", type=str, required=True, help="The full path of train file")
|
||||
parser.add_argument("--test_file", type=str, required=True, help="The full path of test file")
|
||||
|
||||
parser.add_argument("--save_dir", default='./checkpoint', type=str, help="The output directory where the model checkpoints will be written.")
|
||||
parser.add_argument("--max_seq_length", default=128, type=int, help="The maximum total input sequence length after tokenization. "
|
||||
"Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--batch_size", default=32, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument("--learning_rate", default=5e-5, type=float, help="The initial learning rate for Adam.")
|
||||
parser.add_argument("--weight_decay", default=0.0, type=float, help="Weight decay if we apply some.")
|
||||
parser.add_argument("--epochs", default=3, type=int, help="Total number of training epochs to perform.")
|
||||
parser.add_argument("--eval_step", default=200, type=int, help="Step interval for evaluation.")
|
||||
parser.add_argument('--save_step', default=10000, type=int, help="Step interval for saving checkpoint.")
|
||||
parser.add_argument("--warmup_proportion", default=0.0, type=float, help="Linear warmup proption over the training process.")
|
||||
parser.add_argument("--init_from_ckpt", type=str, default=None, help="The path of checkpoint to be loaded.")
|
||||
parser.add_argument('--model_name_or_path', default="ernie-3.0-medium-zh", help="The pretrained model used for training")
|
||||
parser.add_argument("--seed", type=int, default=1000, help="Random seed for initialization.")
|
||||
parser.add_argument('--device', choices=['cpu', 'gpu'], default="gpu", help="Select which device to train model, defaults to gpu.")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
def set_seed(seed):
|
||||
"""sets random seed"""
|
||||
random.seed(seed)
|
||||
np.random.seed(seed)
|
||||
paddle.seed(seed)
|
||||
|
||||
|
||||
@paddle.no_grad()
|
||||
def evaluate(model, metric, data_loader, phase="dev"):
|
||||
"""
|
||||
Given a dataset, it evals model and computes the metric.
|
||||
|
||||
Args:
|
||||
model(obj:`paddle.nn.Layer`): A model to classify texts.
|
||||
data_loader(obj:`paddle.io.DataLoader`): The dataset loader which generates batches.
|
||||
metric(obj:`paddle.metric.Metric`): The evaluation metric.
|
||||
"""
|
||||
model.eval()
|
||||
metric.reset()
|
||||
|
||||
for idx, batch in enumerate(data_loader):
|
||||
input_ids, token_type_ids, labels = batch
|
||||
|
||||
pos_probs = model.predict(input_ids=input_ids,
|
||||
token_type_ids=token_type_ids)
|
||||
|
||||
neg_probs = 1.0 - pos_probs
|
||||
|
||||
preds = np.concatenate((neg_probs, pos_probs), axis=1)
|
||||
metric.update(preds=preds, labels=labels)
|
||||
|
||||
print("eval_{} auc:{:.3}".format(phase, metric.accumulate()))
|
||||
metric.reset()
|
||||
model.train()
|
||||
|
||||
|
||||
# 构建读取函数,读取原始数据
|
||||
def read(src_path, is_predict=False):
|
||||
data = pd.read_csv(src_path, sep='\t')
|
||||
for index, row in tqdm(data.iterrows()):
|
||||
query = row['query']
|
||||
title = row['title']
|
||||
neg_title = row['neg_title']
|
||||
yield {'query': query, 'title': title, 'neg_title': neg_title}
|
||||
|
||||
|
||||
def read_test(src_path, is_predict=False):
|
||||
data = pd.read_csv(src_path, sep='\t')
|
||||
for index, row in tqdm(data.iterrows()):
|
||||
query = row['query']
|
||||
title = row['title']
|
||||
label = row['label']
|
||||
yield {'query': query, 'title': title, 'label': label}
|
||||
|
||||
|
||||
def do_train():
|
||||
paddle.set_device(args.device)
|
||||
rank = paddle.distributed.get_rank()
|
||||
if paddle.distributed.get_world_size() > 1:
|
||||
paddle.distributed.init_parallel_env()
|
||||
|
||||
set_seed(args.seed)
|
||||
|
||||
train_ds = load_dataset(read, src_path=args.train_file, lazy=False)
|
||||
dev_ds = load_dataset(read_test, src_path=args.test_file, lazy=False)
|
||||
|
||||
pretrained_model = AutoModel.from_pretrained(args.model_name_or_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
trans_func_train = partial(convert_example,
|
||||
tokenizer=tokenizer,
|
||||
max_seq_length=args.max_seq_length)
|
||||
|
||||
trans_func_eval = partial(convert_example,
|
||||
tokenizer=tokenizer,
|
||||
max_seq_length=args.max_seq_length,
|
||||
phase="eval")
|
||||
|
||||
batchify_fn_train = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"
|
||||
), # pos_pair_input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # pos_pair_segment
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"
|
||||
), # neg_pair_input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id, dtype="int64"
|
||||
) # neg_pair_segment
|
||||
): [data for data in fn(samples)]
|
||||
|
||||
batchify_fn_eval = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"
|
||||
), # pair_input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # pair_segment
|
||||
Stack(dtype="int64") # label
|
||||
): [data for data in fn(samples)]
|
||||
|
||||
train_data_loader = create_dataloader(train_ds,
|
||||
mode='train',
|
||||
batch_size=args.batch_size,
|
||||
batchify_fn=batchify_fn_train,
|
||||
trans_fn=trans_func_train)
|
||||
|
||||
dev_data_loader = create_dataloader(dev_ds,
|
||||
mode='dev',
|
||||
batch_size=args.batch_size,
|
||||
batchify_fn=batchify_fn_eval,
|
||||
trans_fn=trans_func_eval)
|
||||
|
||||
model = PairwiseMatching(pretrained_model, margin=args.margin)
|
||||
|
||||
if args.init_from_ckpt and os.path.isfile(args.init_from_ckpt):
|
||||
state_dict = paddle.load(args.init_from_ckpt)
|
||||
model.set_dict(state_dict)
|
||||
|
||||
num_training_steps = len(train_data_loader) * args.epochs
|
||||
|
||||
lr_scheduler = LinearDecayWithWarmup(args.learning_rate, num_training_steps,
|
||||
args.warmup_proportion)
|
||||
|
||||
# Generate parameter names needed to perform weight decay.
|
||||
# All bias and LayerNorm parameters are excluded.
|
||||
decay_params = [
|
||||
p.name for n, p in model.named_parameters()
|
||||
if not any(nd in n for nd in ["bias", "norm"])
|
||||
]
|
||||
optimizer = paddle.optimizer.AdamW(
|
||||
learning_rate=lr_scheduler,
|
||||
parameters=model.parameters(),
|
||||
weight_decay=args.weight_decay,
|
||||
apply_decay_param_fun=lambda x: x in decay_params)
|
||||
|
||||
metric = paddle.metric.Auc()
|
||||
|
||||
global_step = 0
|
||||
tic_train = time.time()
|
||||
for epoch in range(1, args.epochs + 1):
|
||||
for step, batch in enumerate(train_data_loader, start=1):
|
||||
pos_input_ids, pos_token_type_ids, neg_input_ids, neg_token_type_ids = batch
|
||||
|
||||
loss = model(pos_input_ids=pos_input_ids,
|
||||
neg_input_ids=neg_input_ids,
|
||||
pos_token_type_ids=pos_token_type_ids,
|
||||
neg_token_type_ids=neg_token_type_ids)
|
||||
|
||||
global_step += 1
|
||||
if global_step % 10 == 0 and rank == 0:
|
||||
print(
|
||||
"global step %d, epoch: %d, batch: %d, loss: %.5f, speed: %.2f step/s"
|
||||
% (global_step, epoch, step, loss, 10 /
|
||||
(time.time() - tic_train)))
|
||||
tic_train = time.time()
|
||||
|
||||
loss.backward()
|
||||
optimizer.step()
|
||||
lr_scheduler.step()
|
||||
optimizer.clear_grad()
|
||||
|
||||
if global_step % args.eval_step == 0 and rank == 0:
|
||||
evaluate(model, metric, dev_data_loader, "dev")
|
||||
|
||||
if global_step % args.save_step == 0 and rank == 0:
|
||||
save_dir = os.path.join(args.save_dir, "model_%d" % global_step)
|
||||
if not os.path.exists(save_dir):
|
||||
os.makedirs(save_dir)
|
||||
save_param_path = os.path.join(save_dir, 'model_state.pdparams')
|
||||
paddle.save(model.state_dict(), save_param_path)
|
||||
tokenizer.save_pretrained(save_dir)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
do_train()
|
||||
632
applications/neural_search/recall/in_batch_negative/README.md
Normal file
632
applications/neural_search/recall/in_batch_negative/README.md
Normal file
@@ -0,0 +1,632 @@
|
||||
# In-batch Negatives
|
||||
|
||||
**目录**
|
||||
|
||||
* [背景介绍](#背景介绍)
|
||||
* [In-batch Negatives](#In-batchNegatives)
|
||||
* [1. 技术方案和评估指标](#技术方案)
|
||||
* [2. 环境依赖](#环境依赖)
|
||||
* [3. 代码结构](#代码结构)
|
||||
* [4. 数据准备](#数据准备)
|
||||
* [5. 模型训练](#模型训练)
|
||||
* [6. 评估](#开始评估)
|
||||
* [7. 预测](#预测)
|
||||
* [8. 部署](#部署)
|
||||
|
||||
<a name="背景介绍"></a>
|
||||
|
||||
# 背景介绍
|
||||
|
||||
语义索引(可通俗理解为向量索引)技术是搜索引擎、推荐系统、广告系统在召回阶段的核心技术之一。语义索引模型的目标是:给定输入文本,模型可以从海量候选召回库中**快速、准确**地召回一批语义相关文本。语义索引模型的效果直接决定了语义相关的物料能否被成功召回进入系统参与上层排序,从基础层面影响整个系统的效果。
|
||||
|
||||
在召回阶段,最常见的方式是通过双塔模型,学习Document(简写为Doc)的向量表示,对Doc端建立索引,用ANN召回。我们在这种方式的基础上,引入语义索引策略 [In-batch Negatives](https://arxiv.org/abs/2004.04906),以如下Batch size=4的训练数据为例:
|
||||
|
||||
|
||||
```
|
||||
我手机丢了,我想换个手机 我想买个新手机,求推荐
|
||||
求秋色之空漫画全集 求秋色之空全集漫画
|
||||
学日语软件手机上的 手机学日语的软件
|
||||
侠盗飞车罪恶都市怎样改车 侠盗飞车罪恶都市怎么改车
|
||||
```
|
||||
|
||||
In-batch Negatives 策略的训练数据为语义相似的 Pair 对,策略核心是在 1 个 Batch 内同时基于 N 个负例进行梯度更新,将Batch 内除自身之外其它所有 Source Text 的相似文本 Target Text 作为负例,例如: 上例中“我手机丢了,我想换个手机” 有 1 个正例(”我想买个新手机,求推荐“),3 个负例(1.求秋色之空全集漫画,2.手机学日语的软件,3.侠盗飞车罪恶都市怎么改车)。
|
||||
|
||||
|
||||
<a name="In-batch Negatives"></a>
|
||||
|
||||
# In-batch Negatives
|
||||
|
||||
<a name="技术方案"></a>
|
||||
|
||||
## 1. 技术方案和评估指标
|
||||
|
||||
### 技术方案
|
||||
|
||||
双塔模型,在召回训练阶段引入In-batch Negatives 策略,使用hnswlib建立索引库,进行召回测试。
|
||||
|
||||
|
||||
### 评估指标
|
||||
|
||||
采用 Recall@1,Recall@5 ,Recall@10 ,Recall@20 和 Recall@50 指标来评估语义索引模型的召回效果。
|
||||
|
||||
Recall@K召回率是指预测的前topK(top-k是指从最后的按得分排序的召回列表中返回前k个结果)结果中检索出的相关结果数和库中所有的相关结果数的比率,衡量的是检索系统的查全率。
|
||||
|
||||
**效果评估**
|
||||
|
||||
| 策略 | 模型 | Recall@1 | Recall@5 |Recall@10 |Recall@20 |Recall@50 |
|
||||
| ------------ | ------------ | ------------ |--------- |--------- |--------- |--------- |
|
||||
| In-batch Negatives | ernie 1.0 | 51.301 | 65.309| 69.878| 73.996|78.881|
|
||||
| In-batch Negatives | rocketqa-zh-base-query-encoder | **59.622** | **75.089**| **79.668**| **83.404**|**87.773**|
|
||||
|
||||
|
||||
<a name="环境依赖"></a>
|
||||
|
||||
## 2. 环境依赖
|
||||
|
||||
推荐使用GPU进行训练,在预测阶段使用CPU或者GPU均可。
|
||||
|
||||
**环境依赖**
|
||||
* python >= 3.6.2
|
||||
* paddlepaddle >= 2.2.3
|
||||
* paddlenlp >= 2.2
|
||||
* [hnswlib](https://github.com/nmslib/hnswlib) >= 0.5.2
|
||||
* visualdl >= 2.2.2
|
||||
|
||||
<a name="代码结构"></a>
|
||||
|
||||
## 3. 代码结构
|
||||
|
||||
```
|
||||
|—— data.py # 数据读取、数据转换等预处理逻辑
|
||||
|—— base_model.py # 语义索引模型基类
|
||||
|—— train_batch_neg.py # In-batch Negatives 策略的训练主脚本
|
||||
|—— batch_negative
|
||||
|—— model.py # In-batch Negatives 策略核心网络结构
|
||||
|—— ann_util.py # Ann 建索引库相关函数
|
||||
|
||||
|
||||
|—— recall.py # 基于训练好的语义索引模型,从召回库中召回给定文本的相似文本
|
||||
|—— evaluate.py # 根据召回结果和评估集计算评估指标
|
||||
|—— predict.py # 给定输入文件,计算文本 pair 的相似度
|
||||
|—— export_model.py # 动态图转换成静态图
|
||||
|—— scripts
|
||||
|—— export_model.sh # 动态图转换成静态图脚本
|
||||
|—— predict.sh # 预测 bash 版本
|
||||
|—— evaluate.sh # 评估 bash 版本
|
||||
|—— run_build_index.sh # 构建索引 bash 版本
|
||||
|—— train_batch_neg.sh # 训练 bash 版本
|
||||
|—— export_to_serving.sh # Paddle Inference 转 Serving 的 bash 脚本
|
||||
|—— deploy
|
||||
|—— python
|
||||
|—— predict.py # PaddleInference
|
||||
|—— deploy.sh # Paddle Inference 部署脚本
|
||||
|—— rpc_client.py # Paddle Serving 的 Client 端
|
||||
|—— web_service.py # Paddle Serving 的 Serving 端
|
||||
|—— config_nlp.yml # Paddle Serving 的配置文件
|
||||
|—— inference.py # 动态图抽取向量
|
||||
|—— export_to_serving.py # 静态图转 Serving
|
||||
|
||||
```
|
||||
|
||||
<a name="数据准备"></a>
|
||||
|
||||
## 4. 数据准备
|
||||
|
||||
### 数据集说明
|
||||
|
||||
我们基于某文献检索平台数据,构造面向语义索引的训练集、测试集、召回库。
|
||||
|
||||
**训练集** 和 **验证集** 格式一致,训练集4k条,测试集2w条,每行由一对语义相似的文本Pair构成,以tab符分割,第一列是检索query,第二列由相关文献标题(+关键词)构成。样例数据如下:
|
||||
|
||||
```
|
||||
宁夏社区图书馆服务体系布局现状分析 宁夏社区图书馆服务体系布局现状分析社区图书馆,社区图书馆服务,社区图书馆服务体系
|
||||
人口老龄化对京津冀经济 京津冀人口老龄化对区域经济增长的影响京津冀,人口老龄化,区域经济增长,固定效应模型
|
||||
英语广告中的模糊语 模糊语在英语广告中的应用及其功能模糊语,英语广告,表现形式,语用功能
|
||||
甘氨酸二肽的合成 甘氨酸二肽合成中缩合剂的选择甘氨酸,缩合剂,二肽
|
||||
```
|
||||
|
||||
**召回库** 用于模拟业务线上的全量语料库,评估模型的召回效果,计算相应的Recall指标。召回库总共30万条样本,每行由一列构成,文献标题(+关键词),样例数据如下:
|
||||
```
|
||||
陕西省贫困地区城乡青春期少女生长发育调查青春期,生长发育,贫困地区
|
||||
五丈岩水库溢洪道加固工程中的新材料应用碳纤维布,粘钢加固技术,超细水泥,灌浆技术
|
||||
木塑复合材料在儿童卫浴家具中的应用探索木塑复合材料,儿童,卫浴家具
|
||||
泡沫铝准静态轴向压缩有限元仿真泡沫铝,准静态,轴向压缩,力学特性
|
||||
```
|
||||
|
||||
|
||||
### 数据集下载
|
||||
|
||||
|
||||
- [literature_search_data](https://bj.bcebos.com/v1/paddlenlp/data/literature_search_data.zip)
|
||||
|
||||
```
|
||||
├── milvus # milvus建库数据集
|
||||
├── milvus_data.csv. # 构建召回库的数据
|
||||
├── recall # 召回(语义索引)数据集
|
||||
├── corpus.csv # 用于测试的召回库
|
||||
├── dev.csv # 召回验证集
|
||||
├── test.csv # 召回测试集
|
||||
├── train.csv # 召回训练集
|
||||
├── train_unsupervised.csv # 无监督训练集
|
||||
├── sort # 排序数据集
|
||||
├── test_pairwise.csv # 排序测试集
|
||||
├── dev_pairwise.csv # 排序验证集
|
||||
└── train_pairwise.csv # 排序训练集
|
||||
|
||||
```
|
||||
|
||||
<a name="模型训练"></a>
|
||||
|
||||
|
||||
## 5. 模型训练
|
||||
|
||||
**语义索引训练模型下载链接:**
|
||||
|
||||
以下模型结构参数为: `TrasformerLayer:12, Hidden:768, Heads:12, OutputEmbSize: 256`
|
||||
|
||||
|Model|训练参数配置|硬件|MD5|
|
||||
| ------------ | ------------ | ------------ |-----------|
|
||||
|[batch_neg](https://bj.bcebos.com/v1/paddlenlp/models/inbatch_model.zip)|<div style="width: 150pt">ernie 1.0 margin:0.2 scale:30 epoch:3 lr:5E-5 bs:64 max_len:64 </div>|<div style="width: 100pt">4卡 v100-16g</div>|f3e5c7d7b0b718c2530c5e1b136b2d74|
|
||||
|
||||
|
||||
### 训练环境说明
|
||||
|
||||
- NVIDIA Driver Version: 440.64.00
|
||||
- Ubuntu 16.04.6 LTS (Docker)
|
||||
- Intel(R) Xeon(R) Gold 6148 CPU @ 2.40GHz
|
||||
|
||||
|
||||
### 单机单卡训练/单机多卡训练
|
||||
|
||||
这里采用单机多卡方式进行训练,通过如下命令,指定 GPU 0,1,2,3 卡, 基于 In-batch Negatives 策略训练模型,数据量比较小,几分钟就可以完成。如果采用单机单卡训练,只需要把`--gpus`参数设置成单卡的卡号即可。
|
||||
|
||||
如果使用CPU进行训练,则需要吧`--gpus`参数去除,然后吧`device`设置成cpu即可,详细请参考train_batch_neg.sh文件的训练设置
|
||||
|
||||
然后运行下面的命令使用GPU训练,得到语义索引模型:
|
||||
|
||||
```
|
||||
root_path=inbatch
|
||||
python -u -m paddle.distributed.launch --gpus "0,1,2,3" \
|
||||
train_batch_neg.py \
|
||||
--device gpu \
|
||||
--save_dir ./checkpoints/${root_path} \
|
||||
--batch_size 64 \
|
||||
--learning_rate 5E-5 \
|
||||
--epochs 3 \
|
||||
--output_emb_size 256 \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--save_steps 10 \
|
||||
--max_seq_length 64 \
|
||||
--margin 0.2 \
|
||||
--train_set_file recall/train.csv \
|
||||
--recall_result_dir "recall_result_dir" \
|
||||
--recall_result_file "recall_result.txt" \
|
||||
--hnsw_m 100 \
|
||||
--hnsw_ef 100 \
|
||||
--recall_num 50 \
|
||||
--similar_text_pair_file "recall/dev.csv" \
|
||||
--corpus_file "recall/corpus.csv"
|
||||
```
|
||||
|
||||
参数含义说明
|
||||
|
||||
* `device`: 使用 cpu/gpu 进行训练
|
||||
* `save_dir`: 模型存储路径
|
||||
* `batch_size`: 训练的batch size的大小
|
||||
* `learning_rate`: 训练的学习率的大小
|
||||
* `epochs`: 训练的epoch数
|
||||
* `output_emb_size`: Transformer 顶层输出的文本向量维度
|
||||
* `model_name_or_path`: 预训练模型,用于模型和`Tokenizer`的参数初始化
|
||||
* `save_steps`: 模型存储 checkpoint 的间隔 steps 个数
|
||||
* `max_seq_length`: 输入序列的最大长度
|
||||
* `margin`: 正样本相似度与负样本之间的目标 Gap
|
||||
* `train_set_file`: 训练集文件
|
||||
* `evaluate`: 是否开启边训练边评估模型训练效果,默认开启
|
||||
* `recall_result_dir`: 召回结果存储目录
|
||||
* `recall_result_file`: 召回结果的文件名
|
||||
* `hnsw_m`: hnsw 算法相关参数,保持默认即可
|
||||
* `hnsw_ef`: hnsw 算法相关参数,保持默认即可
|
||||
* `recall_num`: 对 1 个文本召回的相似文本数量
|
||||
* `similar_text_pair_file`: 由相似文本对构成的评估集
|
||||
* `corpus_file`: 召回库数据 corpus_file
|
||||
|
||||
也可以使用bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/train.sh
|
||||
```
|
||||
|
||||
|
||||
<a name="评估"></a>
|
||||
|
||||
## 6. 评估
|
||||
|
||||
效果评估分为 4 个步骤:
|
||||
|
||||
a. 获取Doc端Embedding
|
||||
|
||||
基于语义索引模型抽取出Doc样本库的文本向量。
|
||||
|
||||
b. 采用hnswlib对Doc端Embedding建库
|
||||
|
||||
使用 ANN 引擎构建索引库(这里基于 [hnswlib](https://github.com/nmslib/hnswlib) 进行 ANN 索引)
|
||||
|
||||
c. 获取Query的Embedding并查询相似结果
|
||||
|
||||
基于语义索引模型抽取出评估集 *Source Text* 的文本向量,在第 2 步中建立的索引库中进行 ANN 查询,召回 Top50 最相似的 *Target Text*, 产出评估集中 *Source Text* 的召回结果 `recall_result` 文件。
|
||||
|
||||
d. 评估
|
||||
|
||||
基于评估集 `dev.csv` 和召回结果 `recall_result` 计算评估指标 Recall@k,其中k取值1,5,10,20,50。
|
||||
|
||||
运行如下命令进行 ANN 建库、召回,产出召回结果数据 `recall_result`
|
||||
|
||||
```
|
||||
root_dir="checkpoints/inbatch"
|
||||
python -u -m paddle.distributed.launch --gpus "3" --log_dir "recall_log/" \
|
||||
recall.py \
|
||||
--device gpu \
|
||||
--recall_result_dir "recall_result_dir" \
|
||||
--recall_result_file "recall_result.txt" \
|
||||
--params_path "${root_dir}/model_40/model_state.pdparams" \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--hnsw_m 100 \
|
||||
--hnsw_ef 100 \
|
||||
--batch_size 64 \
|
||||
--output_emb_size 256\
|
||||
--max_seq_length 60 \
|
||||
--recall_num 50 \
|
||||
--similar_text_pair "recall/dev.csv" \
|
||||
--corpus_file "recall/corpus.csv"
|
||||
```
|
||||
参数含义说明
|
||||
* `device`: 使用 cpu/gpu 进行训练
|
||||
* `recall_result_dir`: 召回结果存储目录
|
||||
* `recall_result_file`: 召回结果的文件名
|
||||
* `params_path`: 待评估模型的参数文件名
|
||||
* `model_name_or_path`: 预训练模型,用于模型和`Tokenizer`的参数初始化
|
||||
* `hnsw_m`: hnsw 算法相关参数,保持默认即可
|
||||
* `hnsw_ef`: hnsw 算法相关参数,保持默认即可
|
||||
* `output_emb_size`: Transformer 顶层输出的文本向量维度
|
||||
* `recall_num`: 对 1 个文本召回的相似文本数量
|
||||
* `similar_text_pair`: 由相似文本对构成的评估集
|
||||
* `corpus_file`: 召回库数据 corpus_file
|
||||
|
||||
也可以使用下面的bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/run_build_index.sh
|
||||
```
|
||||
|
||||
run_build_index.sh还包含cpu和gpu运行的脚本,默认是gpu的脚本
|
||||
|
||||
成功运行结束后,会在 `./recall_result_dir/` 目录下产出 `recall_result.txt` 文件
|
||||
|
||||
```
|
||||
热处理对尼龙6 及其与聚酰胺嵌段共聚物共混体系晶体熔融行为和结晶结构的影响 热处理对尼龙6及其与聚酰胺嵌段共聚物共混体系晶体熔融行为和结晶结构的影响尼龙6,聚酰胺嵌段共聚物,芳香聚酰胺,热处理 0.9831992387771606
|
||||
热处理对尼龙6 及其与聚酰胺嵌段共聚物共混体系晶体熔融行为和结晶结构的影响 热处理方法对高强高模聚乙烯醇纤维性能的影响聚乙烯醇纤维,热处理,性能,热拉伸,热定型 0.8438636660575867
|
||||
热处理对尼龙6 及其与聚酰胺嵌段共聚物共混体系晶体熔融行为和结晶结构的影响 制备工艺对PVC/ABS合金力学性能和维卡软化温度的影响PVC,ABS,正交试验,力学性能,维卡软化温度 0.8130228519439697
|
||||
.....
|
||||
```
|
||||
|
||||
|
||||
接下来,运行如下命令进行效果评估,产出Recall@1, Recall@5, Recall@10, Recall@20 和 Recall@50 指标:
|
||||
```
|
||||
python -u evaluate.py \
|
||||
--similar_text_pair "recall/dev.csv" \
|
||||
--recall_result_file "./recall_result_dir/recall_result.txt" \
|
||||
--recall_num 50
|
||||
```
|
||||
也可以使用下面的bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/evaluate.sh
|
||||
```
|
||||
|
||||
参数含义说明
|
||||
* `similar_text_pair`: 由相似文本对构成的评估集 semantic_similar_pair.tsv
|
||||
* `recall_result_file`: 针对评估集中第一列文本 *Source Text* 的召回结果
|
||||
* `recall_num`: 对 1 个文本召回的相似文本数量
|
||||
|
||||
成功运行结束后,会输出如下评估指标:
|
||||
|
||||
```
|
||||
recall@1=51.261
|
||||
recall@5=65.279
|
||||
recall@10=69.848
|
||||
recall@20=73.971
|
||||
recall@50=78.84
|
||||
```
|
||||
|
||||
<a name="预测"></a>
|
||||
|
||||
## 7. 预测
|
||||
|
||||
我们可以基于语义索引模型预测文本的语义向量或者计算文本 Pair 的语义相似度。
|
||||
|
||||
### 7.1 功能一:抽取文本的语义向量
|
||||
|
||||
修改 inference.py 文件里面输入文本 id2corpus 和模型路径 params_path :
|
||||
|
||||
```
|
||||
params_path='checkpoints/inbatch/model_40/model_state.pdparams'
|
||||
id2corpus={0:'国有企业引入非国有资本对创新绩效的影响——基于制造业国有上市公司的经验证据'}
|
||||
```
|
||||
然后运行:
|
||||
```
|
||||
python inference.py
|
||||
```
|
||||
预测结果为256维的向量:
|
||||
|
||||
```
|
||||
[1, 256]
|
||||
[[ 0.07766181 -0.13780491 0.03388524 -0.14910668 -0.0334941 0.06780092
|
||||
0.0104043 0.03168401 0.02605671 0.02088691 0.05520441 -0.0852212
|
||||
.....
|
||||
```
|
||||
|
||||
### 7.2 功能二:计算文本 Pair 的语义相似度
|
||||
|
||||
|
||||
### 准备预测数据
|
||||
|
||||
待预测数据为 tab 分隔的 csv 文件,每一行为 1 个文本 Pair,部分示例如下:
|
||||
```
|
||||
试论我国海岸带经济开发的问题与前景 试论我国海岸带经济开发的问题与前景海岸带,经济开发,问题,前景
|
||||
外语阅读焦虑与英语成绩及性别的关系 外语阅读焦虑与英语成绩及性别的关系外语阅读焦虑,外语课堂焦虑,英语成绩,性别
|
||||
数字图书馆 智能化图书馆
|
||||
网络健康可信性研究 网络成瘾少年
|
||||
```
|
||||
|
||||
### 开始预测
|
||||
|
||||
以上述 demo 数据为例,运行如下命令基于我们开源的 [In-batch Negatives](https://arxiv.org/abs/2004.04906) 策略语义索引模型开始计算文本 Pair 的语义相似度:
|
||||
```
|
||||
root_dir="checkpoints/inbatch"
|
||||
|
||||
python -u -m paddle.distributed.launch --gpus "0" \
|
||||
predict.py \
|
||||
--device gpu \
|
||||
--params_path "${root_dir}/model_40/model_state.pdparams" \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--output_emb_size 256 \
|
||||
--batch_size 128 \
|
||||
--max_seq_length 64 \
|
||||
--text_pair_file "recall/test.csv"
|
||||
```
|
||||
|
||||
参数含义说明
|
||||
* `device`: 使用 cpu/gpu 进行训练
|
||||
* `params_path`: 预训练模型的参数文件名
|
||||
* `model_name_or_path`: 预训练模型,用于模型和`Tokenizer`的参数初始化
|
||||
* `output_emb_size`: Transformer 顶层输出的文本向量维度
|
||||
* `text_pair_file`: 由文本 Pair 构成的待预测数据集
|
||||
|
||||
也可以运行下面的bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/predict.sh
|
||||
```
|
||||
predict.sh文件包含了cpu和gpu运行的脚本,默认是gpu运行的脚本
|
||||
|
||||
产出如下结果
|
||||
```
|
||||
0.9717282652854919
|
||||
0.9371012449264526
|
||||
0.7968897223472595
|
||||
0.30377304553985596
|
||||
```
|
||||
|
||||
<a name="部署"></a>
|
||||
|
||||
## 8. 部署
|
||||
|
||||
### 动转静导出
|
||||
|
||||
首先把动态图模型转换为静态图:
|
||||
|
||||
```
|
||||
python export_model.py --params_path checkpoints/inbatch/model_40/model_state.pdparams \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--output_path=./output
|
||||
```
|
||||
也可以运行下面的bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/export_model.sh
|
||||
```
|
||||
|
||||
### Paddle Inference预测
|
||||
|
||||
预测既可以抽取向量也可以计算两个文本的相似度。
|
||||
|
||||
修改id2corpus的样本:
|
||||
|
||||
```
|
||||
# 抽取向量
|
||||
id2corpus={0:'国有企业引入非国有资本对创新绩效的影响——基于制造业国有上市公司的经验证据'}
|
||||
# 计算相似度
|
||||
corpus_list=[['中西方语言与文化的差异','中西方文化差异以及语言体现中西方文化,差异,语言体现'],
|
||||
['中西方语言与文化的差异','飞桨致力于让深度学习技术的创新与应用更简单']]
|
||||
|
||||
```
|
||||
|
||||
然后使用PaddleInference
|
||||
|
||||
```
|
||||
python deploy/python/predict.py \
|
||||
--model_dir=./output \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder
|
||||
```
|
||||
也可以运行下面的bash脚本:
|
||||
|
||||
```
|
||||
sh deploy.sh
|
||||
```
|
||||
最终输出的是256维度的特征向量和句子对的预测概率:
|
||||
|
||||
```
|
||||
(1, 256)
|
||||
[[-0.0394925 -0.04474756 -0.065534 0.00939134 0.04359895 0.14659195
|
||||
-0.0091779 -0.07303623 0.09413272 -0.01255222 -0.08685658 0.02762237
|
||||
0.10138468 0.00962821 0.10888419 0.04553023 0.05898942 0.00694253
|
||||
....
|
||||
|
||||
[0.959269642829895, 0.04725276678800583]
|
||||
```
|
||||
|
||||
### Paddle Serving部署
|
||||
|
||||
Paddle Serving 的详细文档请参考 [Pipeline_Design](https://github.com/PaddlePaddle/Serving/blob/v0.7.0/doc/Python_Pipeline/Pipeline_Design_CN.md)和[Serving_Design](https://github.com/PaddlePaddle/Serving/blob/v0.7.0/doc/Serving_Design_CN.md),首先把静态图模型转换成Serving的格式:
|
||||
|
||||
```
|
||||
python export_to_serving.py \
|
||||
--dirname "output" \
|
||||
--model_filename "inference.get_pooled_embedding.pdmodel" \
|
||||
--params_filename "inference.get_pooled_embedding.pdiparams" \
|
||||
--server_path "./serving_server" \
|
||||
--client_path "./serving_client" \
|
||||
--fetch_alias_names "output_embedding"
|
||||
|
||||
```
|
||||
|
||||
参数含义说明
|
||||
* `dirname`: 需要转换的模型文件存储路径,Program 结构文件和参数文件均保存在此目录。
|
||||
* `model_filename`: 存储需要转换的模型 Inference Program 结构的文件名称。如果设置为 None ,则使用 `__model__` 作为默认的文件名
|
||||
* `params_filename`: 存储需要转换的模型所有参数的文件名称。当且仅当所有模型参数被保>存在一个单独的二进制文件中,它才需要被指定。如果模型参数是存储在各自分离的文件中,设置它的值为 None
|
||||
* `server_path`: 转换后的模型文件和配置文件的存储路径。默认值为 serving_server
|
||||
* `client_path`: 转换后的客户端配置文件存储路径。默认值为 serving_client
|
||||
* `fetch_alias_names`: 模型输出的别名设置,比如输入的 input_ids 等,都可以指定成其他名字,默认不指定
|
||||
* `feed_alias_names`: 模型输入的别名设置,比如输出 pooled_out 等,都可以重新指定成其他模型,默认不指定
|
||||
|
||||
也可以运行下面的 bash 脚本:
|
||||
```
|
||||
sh scripts/export_to_serving.sh
|
||||
```
|
||||
|
||||
Paddle Serving的部署有两种方式,第一种方式是Pipeline的方式,第二种是C++的方式,下面分别介绍这两种方式的用法:
|
||||
|
||||
#### Pipeline方式
|
||||
|
||||
修改模型需要用到的`Tokenizer`
|
||||
|
||||
```
|
||||
self.tokenizer = AutoTokenizer.from_pretrained("rocketqa-zh-base-query-encoder")
|
||||
```
|
||||
|
||||
然后启动 Pipeline Server:
|
||||
|
||||
```
|
||||
cd deploy/python
|
||||
python web_service.py
|
||||
```
|
||||
|
||||
启动客户端调用 Server。
|
||||
|
||||
首先修改rpc_client.py中需要预测的样本:
|
||||
|
||||
```
|
||||
list_data = [
|
||||
"国有企业引入非国有资本对创新绩效的影响——基于制造业国有上市公司的经验证据",
|
||||
"试论翻译过程中的文化差异与语言空缺翻译过程,文化差异,语言空缺,文化对比"
|
||||
]
|
||||
```
|
||||
然后运行:
|
||||
|
||||
```
|
||||
python deploy/python/rpc_client.py
|
||||
```
|
||||
模型的输出为:
|
||||
|
||||
```
|
||||
{'0': '国有企业引入非国有资本对创新绩效的影响——基于制造业国有上市公司的经验证据', '1': '试论翻译过程中的文化差异与语言空缺翻译过程,文化差异,语言空缺,文化对比'}
|
||||
PipelineClient::predict pack_data time:1641450851.3752182
|
||||
PipelineClient::predict before time:1641450851.375738
|
||||
['output_embedding']
|
||||
(2, 256)
|
||||
[[ 0.07830612 -0.14036864 0.03433796 -0.14967982 -0.03386067 0.06630666
|
||||
0.01357943 0.03531194 0.02411093 0.02000859 0.05724002 -0.08119463
|
||||
......
|
||||
```
|
||||
|
||||
可以看到客户端发送了2条文本,返回了2个 embedding 向量
|
||||
|
||||
#### C++的方式
|
||||
|
||||
启动C++的Serving:
|
||||
|
||||
```
|
||||
python -m paddle_serving_server.serve --model serving_server --port 9393 --gpu_id 2 --thread 5 --ir_optim True --use_trt --precision FP16
|
||||
```
|
||||
也可以使用脚本:
|
||||
|
||||
```
|
||||
sh deploy/cpp/start_server.sh
|
||||
```
|
||||
Client 可以使用 http 或者 rpc 两种方式,rpc 的方式为:
|
||||
|
||||
```
|
||||
python deploy/cpp/rpc_client.py
|
||||
```
|
||||
运行的输出为:
|
||||
```
|
||||
I0209 20:40:07.978225 20896 general_model.cpp:490] [client]logid=0,client_cost=395.695ms,server_cost=392.559ms.
|
||||
time to cost :0.3960278034210205 seconds
|
||||
{'output_embedding': array([[ 9.01343748e-02, -1.21870913e-01, 1.32834800e-02,
|
||||
-1.57673359e-01, -2.60387752e-02, 6.98455423e-02,
|
||||
1.58108603e-02, 3.89952064e-02, 3.22783105e-02,
|
||||
3.49135026e-02, 7.66086206e-02, -9.12970975e-02,
|
||||
6.25643134e-02, 7.21886680e-02, 7.03565404e-02,
|
||||
5.44054210e-02, 3.25332815e-03, 5.01751155e-02,
|
||||
......
|
||||
```
|
||||
可以看到服务端返回了向量
|
||||
|
||||
或者使用 http 的客户端访问模式:
|
||||
|
||||
```
|
||||
python deploy/cpp/http_client.py
|
||||
```
|
||||
运行的输出为:
|
||||
|
||||
```
|
||||
(2, 64)
|
||||
(2, 64)
|
||||
outputs {
|
||||
tensor {
|
||||
float_data: 0.09013437479734421
|
||||
float_data: -0.12187091261148453
|
||||
float_data: 0.01328347995877266
|
||||
float_data: -0.15767335891723633
|
||||
......
|
||||
```
|
||||
可以看到服务端返回了向量
|
||||
|
||||
## FAQ
|
||||
|
||||
#### 如何基于无监督SimCSE训练出的模型参数作为参数初始化继续做有监督 In-Batch Negative 训练?
|
||||
|
||||
+ 使用 `--init_from_ckpt` 参数加载即可,下面是使用示例:
|
||||
|
||||
```
|
||||
python -u -m paddle.distributed.launch --gpus "0,1,2,3" \
|
||||
train_batch_neg.py \
|
||||
--device gpu \
|
||||
--save_dir ./checkpoints/simcse_inbatch_negative \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--batch_size 64 \
|
||||
--learning_rate 5E-5 \
|
||||
--epochs 3 \
|
||||
--output_emb_size 256 \
|
||||
--save_steps 10 \
|
||||
--max_seq_length 64 \
|
||||
--margin 0.2 \
|
||||
--train_set_file recall/train.csv \
|
||||
--init_from_ckpt simcse/model_20000/model_state.pdparams
|
||||
```
|
||||
|
||||
|
||||
|
||||
## Reference
|
||||
|
||||
[1] Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, Wen-tau Yih, Dense Passage Retrieval for Open-Domain Question Answering, Preprint 2020.
|
||||
@@ -0,0 +1,61 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
# coding=UTF-8
|
||||
|
||||
import numpy as np
|
||||
import hnswlib
|
||||
from paddlenlp.utils.log import logger
|
||||
|
||||
|
||||
def build_index(args, data_loader, model):
|
||||
|
||||
index = hnswlib.Index(
|
||||
space='ip',
|
||||
dim=args.output_emb_size if args.output_emb_size > 0 else 768)
|
||||
|
||||
# Initializing index
|
||||
# max_elements - the maximum number of elements (capacity). Will throw an exception if exceeded
|
||||
# during insertion of an element.
|
||||
# The capacity can be increased by saving/loading the index, see below.
|
||||
#
|
||||
# ef_construction - controls index search speed/build speed tradeoff
|
||||
#
|
||||
# M - is tightly connected with internal dimensionality of the data. Strongly affects memory consumption (~M)
|
||||
# Higher M leads to higher accuracy/run_time at fixed ef/efConstruction
|
||||
index.init_index(max_elements=args.hnsw_max_elements,
|
||||
ef_construction=args.hnsw_ef,
|
||||
M=args.hnsw_m)
|
||||
|
||||
# Controlling the recall by setting ef:
|
||||
# higher ef leads to better accuracy, but slower search
|
||||
index.set_ef(args.hnsw_ef)
|
||||
|
||||
# Set number of threads used during batch search/construction
|
||||
# By default using all available cores
|
||||
index.set_num_threads(16)
|
||||
|
||||
logger.info("start build index..........")
|
||||
|
||||
all_embeddings = []
|
||||
|
||||
for text_embeddings in model.get_semantic_embedding(data_loader):
|
||||
all_embeddings.append(text_embeddings.numpy())
|
||||
|
||||
all_embeddings = np.concatenate(all_embeddings, axis=0)
|
||||
index.add_items(all_embeddings)
|
||||
|
||||
logger.info("Total index number:{}".format(index.get_current_count()))
|
||||
|
||||
return index
|
||||
@@ -0,0 +1,185 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License"
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import abc
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
|
||||
import paddle
|
||||
import paddle.nn as nn
|
||||
import paddle.nn.functional as F
|
||||
|
||||
|
||||
class SemanticIndexBase(nn.Layer):
|
||||
|
||||
def __init__(self, pretrained_model, dropout=None, output_emb_size=None):
|
||||
super().__init__()
|
||||
self.ptm = pretrained_model
|
||||
self.dropout = nn.Dropout(dropout if dropout is not None else 0.1)
|
||||
|
||||
# if output_emb_size is not None, then add Linear layer to reduce embedding_size,
|
||||
# we recommend set output_emb_size = 256 considering the trade-off beteween
|
||||
# recall performance and efficiency
|
||||
|
||||
self.output_emb_size = output_emb_size
|
||||
if output_emb_size > 0:
|
||||
weight_attr = paddle.ParamAttr(
|
||||
initializer=paddle.nn.initializer.TruncatedNormal(std=0.02))
|
||||
self.emb_reduce_linear = paddle.nn.Linear(768,
|
||||
output_emb_size,
|
||||
weight_attr=weight_attr)
|
||||
|
||||
def get_pooled_embedding(self,
|
||||
input_ids,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
attention_mask=None):
|
||||
_, cls_embedding = self.ptm(input_ids, token_type_ids, position_ids,
|
||||
attention_mask)
|
||||
|
||||
if self.output_emb_size > 0:
|
||||
cls_embedding = self.emb_reduce_linear(cls_embedding)
|
||||
cls_embedding = self.dropout(cls_embedding)
|
||||
cls_embedding = F.normalize(cls_embedding, p=2, axis=-1)
|
||||
|
||||
return cls_embedding
|
||||
|
||||
def get_semantic_embedding(self, data_loader):
|
||||
self.eval()
|
||||
with paddle.no_grad():
|
||||
for batch_data in data_loader:
|
||||
input_ids, token_type_ids = batch_data
|
||||
|
||||
text_embeddings = self.get_pooled_embedding(
|
||||
input_ids, token_type_ids=token_type_ids)
|
||||
|
||||
yield text_embeddings
|
||||
|
||||
def cosine_sim(self,
|
||||
query_input_ids,
|
||||
title_input_ids,
|
||||
query_token_type_ids=None,
|
||||
query_position_ids=None,
|
||||
query_attention_mask=None,
|
||||
title_token_type_ids=None,
|
||||
title_position_ids=None,
|
||||
title_attention_mask=None):
|
||||
|
||||
query_cls_embedding = self.get_pooled_embedding(query_input_ids,
|
||||
query_token_type_ids,
|
||||
query_position_ids,
|
||||
query_attention_mask)
|
||||
|
||||
title_cls_embedding = self.get_pooled_embedding(title_input_ids,
|
||||
title_token_type_ids,
|
||||
title_position_ids,
|
||||
title_attention_mask)
|
||||
|
||||
cosine_sim = paddle.sum(query_cls_embedding * title_cls_embedding,
|
||||
axis=-1)
|
||||
return cosine_sim
|
||||
|
||||
@abc.abstractmethod
|
||||
def forward(self):
|
||||
pass
|
||||
|
||||
|
||||
class SemanticIndexBaseStatic(nn.Layer):
|
||||
|
||||
def __init__(self, pretrained_model, dropout=None, output_emb_size=None):
|
||||
super().__init__()
|
||||
self.ptm = pretrained_model
|
||||
self.dropout = nn.Dropout(dropout if dropout is not None else 0.1)
|
||||
|
||||
# if output_emb_size is not None, then add Linear layer to reduce embedding_size,
|
||||
# we recommend set output_emb_size = 256 considering the trade-off beteween
|
||||
# recall performance and efficiency
|
||||
|
||||
self.output_emb_size = output_emb_size
|
||||
if output_emb_size > 0:
|
||||
weight_attr = paddle.ParamAttr(
|
||||
initializer=paddle.nn.initializer.TruncatedNormal(std=0.02))
|
||||
self.emb_reduce_linear = paddle.nn.Linear(768,
|
||||
output_emb_size,
|
||||
weight_attr=weight_attr)
|
||||
|
||||
@paddle.jit.to_static(input_spec=[
|
||||
paddle.static.InputSpec(shape=[None, None], dtype='int64'),
|
||||
paddle.static.InputSpec(shape=[None, None], dtype='int64')
|
||||
])
|
||||
def get_pooled_embedding(self,
|
||||
input_ids,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
attention_mask=None):
|
||||
_, cls_embedding = self.ptm(input_ids, token_type_ids, position_ids,
|
||||
attention_mask)
|
||||
|
||||
if self.output_emb_size > 0:
|
||||
cls_embedding = self.emb_reduce_linear(cls_embedding)
|
||||
cls_embedding = self.dropout(cls_embedding)
|
||||
cls_embedding = F.normalize(cls_embedding, p=2, axis=-1)
|
||||
|
||||
return cls_embedding
|
||||
|
||||
def get_semantic_embedding(self, data_loader):
|
||||
self.eval()
|
||||
with paddle.no_grad():
|
||||
for batch_data in data_loader:
|
||||
input_ids, token_type_ids = batch_data
|
||||
|
||||
text_embeddings = self.get_pooled_embedding(
|
||||
input_ids, token_type_ids=token_type_ids)
|
||||
|
||||
yield text_embeddings
|
||||
|
||||
def cosine_sim(self,
|
||||
query_input_ids,
|
||||
title_input_ids,
|
||||
query_token_type_ids=None,
|
||||
query_position_ids=None,
|
||||
query_attention_mask=None,
|
||||
title_token_type_ids=None,
|
||||
title_position_ids=None,
|
||||
title_attention_mask=None):
|
||||
|
||||
query_cls_embedding = self.get_pooled_embedding(query_input_ids,
|
||||
query_token_type_ids,
|
||||
query_position_ids,
|
||||
query_attention_mask)
|
||||
|
||||
title_cls_embedding = self.get_pooled_embedding(title_input_ids,
|
||||
title_token_type_ids,
|
||||
title_position_ids,
|
||||
title_attention_mask)
|
||||
|
||||
cosine_sim = paddle.sum(query_cls_embedding * title_cls_embedding,
|
||||
axis=-1)
|
||||
return cosine_sim
|
||||
|
||||
def forward(self,
|
||||
input_ids,
|
||||
token_type_ids=None,
|
||||
position_ids=None,
|
||||
attention_mask=None):
|
||||
_, cls_embedding = self.ptm(input_ids, token_type_ids, position_ids,
|
||||
attention_mask)
|
||||
|
||||
if self.output_emb_size > 0:
|
||||
cls_embedding = self.emb_reduce_linear(cls_embedding)
|
||||
cls_embedding = self.dropout(cls_embedding)
|
||||
cls_embedding = F.normalize(cls_embedding, p=2, axis=-1)
|
||||
|
||||
return cls_embedding
|
||||
@@ -0,0 +1,78 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License"
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import paddle
|
||||
import paddle.nn as nn
|
||||
import paddle.nn.functional as F
|
||||
|
||||
from base_model import SemanticIndexBase
|
||||
|
||||
|
||||
class SemanticIndexBatchNeg(SemanticIndexBase):
|
||||
|
||||
def __init__(self,
|
||||
pretrained_model,
|
||||
dropout=None,
|
||||
margin=0.3,
|
||||
scale=30,
|
||||
output_emb_size=None):
|
||||
super().__init__(pretrained_model, dropout, output_emb_size)
|
||||
|
||||
self.margin = margin
|
||||
# Used scaling cosine similarity to ease converge
|
||||
self.sacle = scale
|
||||
|
||||
def forward(self,
|
||||
query_input_ids,
|
||||
title_input_ids,
|
||||
query_token_type_ids=None,
|
||||
query_position_ids=None,
|
||||
query_attention_mask=None,
|
||||
title_token_type_ids=None,
|
||||
title_position_ids=None,
|
||||
title_attention_mask=None):
|
||||
|
||||
query_cls_embedding = self.get_pooled_embedding(query_input_ids,
|
||||
query_token_type_ids,
|
||||
query_position_ids,
|
||||
query_attention_mask)
|
||||
|
||||
title_cls_embedding = self.get_pooled_embedding(title_input_ids,
|
||||
title_token_type_ids,
|
||||
title_position_ids,
|
||||
title_attention_mask)
|
||||
|
||||
cosine_sim = paddle.matmul(query_cls_embedding,
|
||||
title_cls_embedding,
|
||||
transpose_y=True)
|
||||
|
||||
# substract margin from all positive samples cosine_sim()
|
||||
margin_diag = paddle.full(shape=[query_cls_embedding.shape[0]],
|
||||
fill_value=self.margin,
|
||||
dtype=paddle.get_default_dtype())
|
||||
|
||||
cosine_sim = cosine_sim - paddle.diag(margin_diag)
|
||||
|
||||
# scale cosine to ease training converge
|
||||
cosine_sim *= self.sacle
|
||||
|
||||
labels = paddle.arange(0, query_cls_embedding.shape[0], dtype='int64')
|
||||
labels = paddle.reshape(labels, shape=[-1, 1])
|
||||
|
||||
loss = F.cross_entropy(input=cosine_sim, label=labels)
|
||||
|
||||
return loss
|
||||
181
applications/neural_search/recall/in_batch_negative/data.py
Normal file
181
applications/neural_search/recall/in_batch_negative/data.py
Normal file
@@ -0,0 +1,181 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import os
|
||||
import paddle
|
||||
from paddlenlp.utils.log import logger
|
||||
|
||||
|
||||
def create_dataloader(dataset,
|
||||
mode='train',
|
||||
batch_size=1,
|
||||
batchify_fn=None,
|
||||
trans_fn=None):
|
||||
if trans_fn:
|
||||
dataset = dataset.map(trans_fn)
|
||||
shuffle = True if mode == 'train' else False
|
||||
if mode == 'train':
|
||||
batch_sampler = paddle.io.DistributedBatchSampler(dataset,
|
||||
batch_size=batch_size,
|
||||
shuffle=shuffle)
|
||||
else:
|
||||
batch_sampler = paddle.io.BatchSampler(dataset,
|
||||
batch_size=batch_size,
|
||||
shuffle=shuffle)
|
||||
|
||||
return paddle.io.DataLoader(dataset=dataset,
|
||||
batch_sampler=batch_sampler,
|
||||
collate_fn=batchify_fn,
|
||||
return_list=True)
|
||||
|
||||
|
||||
def convert_example(example,
|
||||
tokenizer,
|
||||
max_seq_length=512,
|
||||
pad_to_max_seq_len=False):
|
||||
"""
|
||||
Builds model inputs from a sequence.
|
||||
|
||||
A BERT sequence has the following format:
|
||||
|
||||
- single sequence: ``[CLS] X [SEP]``
|
||||
|
||||
Args:
|
||||
example(obj:`list(str)`): The list of text to be converted to ids.
|
||||
tokenizer(obj:`PretrainedTokenizer`): This tokenizer inherits from :class:`~paddlenlp.transformers.PretrainedTokenizer`
|
||||
which contains most of the methods. Users should refer to the superclass for more information regarding methods.
|
||||
max_seq_len(obj:`int`): The maximum total input sequence length after tokenization.
|
||||
Sequences longer than this will be truncated, sequences shorter will be padded.
|
||||
is_test(obj:`False`, defaults to `False`): Whether the example contains label or not.
|
||||
|
||||
Returns:
|
||||
input_ids(obj:`list[int]`): The list of query token ids.
|
||||
token_type_ids(obj: `list[int]`): List of query sequence pair mask.
|
||||
"""
|
||||
|
||||
result = []
|
||||
for key, text in example.items():
|
||||
encoded_inputs = tokenizer(text=text,
|
||||
max_seq_len=max_seq_length,
|
||||
pad_to_max_seq_len=pad_to_max_seq_len)
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
result += [input_ids, token_type_ids]
|
||||
return result
|
||||
|
||||
|
||||
def read_text_pair(data_path):
|
||||
"""Reads data."""
|
||||
with open(data_path, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
data = line.rstrip().split("\t")
|
||||
if len(data) != 2:
|
||||
continue
|
||||
yield {'text_a': data[0], 'text_b': data[1]}
|
||||
|
||||
|
||||
def read_text_triplet(data_path):
|
||||
"""Reads data."""
|
||||
with open(data_path, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
data = line.rstrip().split("\t")
|
||||
if len(data) != 3:
|
||||
continue
|
||||
yield {
|
||||
'text': data[0],
|
||||
'pos_sample': data[1],
|
||||
'neg_sample': data[2]
|
||||
}
|
||||
|
||||
|
||||
# ANN - active learning ------------------------------------------------------
|
||||
def get_latest_checkpoint(args):
|
||||
"""
|
||||
Return: (latest_checkpint_path, global_step)
|
||||
"""
|
||||
if not os.path.exists(args.save_dir):
|
||||
return args.init_from_ckpt, 0
|
||||
|
||||
subdirectories = list(next(os.walk(args.save_dir))[1])
|
||||
|
||||
def valid_checkpoint(checkpoint):
|
||||
chk_path = os.path.join(args.save_dir, checkpoint)
|
||||
scheduler_path = os.path.join(chk_path, "model_state.pdparams")
|
||||
succeed_flag_file = os.path.join(chk_path, "succeed_flag_file")
|
||||
return os.path.exists(scheduler_path) and os.path.exists(
|
||||
succeed_flag_file)
|
||||
|
||||
trained_steps = [int(s) for s in subdirectories if valid_checkpoint(s)]
|
||||
|
||||
if len(trained_steps) > 0:
|
||||
return os.path.join(args.save_dir, str(max(trained_steps)),
|
||||
"model_state.pdparams"), max(trained_steps)
|
||||
|
||||
return args.init_from_ckpt, 0
|
||||
|
||||
|
||||
# ANN - active learning ------------------------------------------------------
|
||||
def get_latest_ann_data(ann_data_dir):
|
||||
if not os.path.exists(ann_data_dir):
|
||||
return None, -1
|
||||
|
||||
subdirectories = list(next(os.walk(ann_data_dir))[1])
|
||||
|
||||
def valid_checkpoint(step):
|
||||
ann_data_file = os.path.join(ann_data_dir, step, "new_ann_data")
|
||||
# succed_flag_file is an empty file that indicates ann data has been generated
|
||||
succeed_flag_file = os.path.join(ann_data_dir, step,
|
||||
"succeed_flag_file")
|
||||
return os.path.exists(succeed_flag_file) and os.path.exists(
|
||||
ann_data_file)
|
||||
|
||||
ann_data_steps = [int(s) for s in subdirectories if valid_checkpoint(s)]
|
||||
|
||||
if len(ann_data_steps) > 0:
|
||||
latest_ann_data_file = os.path.join(ann_data_dir,
|
||||
str(max(ann_data_steps)),
|
||||
"new_ann_data")
|
||||
logger.info(
|
||||
"Using lateset ann_data_file:{}".format(latest_ann_data_file))
|
||||
return latest_ann_data_file, max(ann_data_steps)
|
||||
|
||||
logger.info("no new ann_data, return (None, -1)")
|
||||
return None, -1
|
||||
|
||||
|
||||
def gen_id2corpus(corpus_file):
|
||||
id2corpus = {}
|
||||
with open(corpus_file, 'r', encoding='utf-8') as f:
|
||||
for idx, line in enumerate(f):
|
||||
id2corpus[idx] = line.rstrip()
|
||||
return id2corpus
|
||||
|
||||
|
||||
def gen_text_file(similar_text_pair_file):
|
||||
text2similar_text = {}
|
||||
texts = []
|
||||
with open(similar_text_pair_file, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
splited_line = line.rstrip().split("\t")
|
||||
if len(splited_line) != 2:
|
||||
continue
|
||||
|
||||
text, similar_text = line.rstrip().split("\t")
|
||||
|
||||
if not text or not similar_text:
|
||||
continue
|
||||
|
||||
text2similar_text[text] = similar_text
|
||||
texts.append({"text": text})
|
||||
return texts, text2similar_text
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user