Compare commits
293 Commits
v2.4.0
...
ppdiffuser
| Author | SHA1 | Date | |
|---|---|---|---|

|
2c92c543f2 | ||
|
|
a85212ed00 | ||
|
|
6f71c7cf5e | ||
|
|
767d3552e3 | ||
|
|
feb9d8296b | ||
|
|
00ae25bf35 | ||
|
|
e97f670440 | ||
|
|
6289d9c0d3 | ||
|
|
7b4cf36b90 | ||
|
|
a50fbbcc30 | ||
|
|
9e2a0a8a9f | ||
|
|
f74de55082 | ||
|
|
e785bb1163 | ||
|
|
ce31a77f90 | ||
|
|
58a5a9dcfd | ||
|
|
6387410b5a | ||
|
|
1a53c35887 | ||
|
|
fd6ef4058e | ||
|
|
1f2b2c5d58 | ||
|
|
7b6454908a | ||
|
|
02b4383b7e | ||
|
|
6471ce331a | ||
|
|
61acf19460 | ||
|
|
c38902e3a8 | ||
|
|
1fc23a8888 | ||
|
|
afeb623588 | ||
|
|
ff546f6d9a | ||
|
|
81bb7d1433 | ||
|
|
6eb6937b69 | ||
|
|
228c58a494 | ||
|
|
e94af7978a | ||
|
|
83a9c3893a | ||
|
|
bdd659d266 | ||
|
|
b52c2ea5d2 | ||
|
|
2483d4fb85 | ||
|
|
7bc85cdfb2 | ||
|
|
513a8328d9 | ||
|
|
3e2ddd182c | ||
|
|
b90ed42dff | ||
|
|
b705fa481d | ||
|
|
cf478ba6ee | ||
|
|
9eda9a46c4 | ||
|
|
1f88c41d14 | ||
|
|
7f650ac0ca | ||
|
|
b6c3589ea6 | ||
|
|
c2e1dc4852 | ||
|
|
1c5e127866 | ||
|
|
c8bc4405fc | ||
|
|
05e7432ef7 | ||
|
|
d390dc95e8 | ||
|
|
b262611f37 | ||
|
|
78c8615791 | ||
|
|
16aa2ba5b1 | ||
|
|
21345f8d2e | ||
|
|
c9c5c15a66 | ||
|
|
d57e350f9e | ||
|
|
295d68e940 | ||
|
|
947007f552 | ||
|
|
14c934c1a1 | ||
|
|
e98231f911 | ||
|
|
d1506f8a38 | ||
|
|
94864bc48e | ||
|
|
b0f7650ecf | ||
|
|
cd5a2e35a6 | ||
|
|
91d5c527dd | ||
|
|
fca7ca25da | ||
|
|
b0ba2e1e79 | ||
|
|
553ba12211 | ||
|
|
122824885c | ||
|
|
211e8204dd | ||
|
|
47f7c36e1e | ||
|
|
7eac0586bc | ||
|
|
a0f5a8ebcd | ||
|
|
636e3430fc | ||
|
|
d52d8e5ea1 | ||
|
|
97fe71d000 | ||
|
|
1bad94989f | ||
|
|
04a742106e | ||
|
|
1076b890de | ||
|
|
219b6abd15 | ||
|
|
fb0cb9b35b | ||
|
|
293c8308af | ||
|
|
e14487780b | ||
|
|
39b49c928f | ||
|
|
38fcccbd86 | ||
|
|
31dc47aed5 | ||
|
|
8f3e4e51e3 | ||
|
|
7476962a6c | ||
|
|
b1ac71b2f5 | ||
|
|
1ac55f0325 | ||
|
|
0497ce7984 | ||
|
|
0a402ca287 | ||
|
|
a12481fc30 | ||
|
|
3e7d4d8140 | ||
|
|
ce67b4fc41 | ||
|
|
839b2d09bb | ||
|
|
db915e756a | ||
|
|
217a25cf01 | ||
|
|
c00d28fcd8 | ||
|
|
90c6f1da59 | ||
|
|
f43cfd0d79 | ||
|
|
caa37ce8d8 | ||
|
|
988204dfbf | ||
|
|
a6b46912d2 | ||
|
|
a3e92bbb04 | ||
|
|
426b75778f | ||
|
|
6011ed8573 | ||
|
|
b1e373c6db | ||
|
|
e83abbb47f | ||
|
|
361d826fbd | ||
|
|
63b3c312ec | ||
|
|
c65dbb42f8 | ||
|
|
4c4f961b89 | ||
|
|
db1f9919c3 | ||
|
|
7fbd726ccf | ||
|
|
50cd2197f1 | ||
|
|
e544a04f8a | ||
|
|
ddb59bfb56 | ||
|
|
ee696c397d | ||
|
|
0b4985dda2 | ||
|
|
907144f8ee | ||
|
|
aa1bef4890 | ||
|
|
01be7792c8 | ||
|
|
70b6e5043a | ||
|
|
031e2bf8f6 | ||
|
|
eee364e7f8 | ||
|
|
289d8214b1 | ||
|
|
a8f08c8ed5 | ||
|
|
9182f34818 | ||
|
|
1e81d90f1f | ||
|
|
3f9ea47d15 | ||
|
|
b6a718bc87 | ||
|
|
0cb7fe99f7 | ||
|
|
3109311e58 | ||
|
|
507084013c | ||
|
|
c987531a2a | ||
|
|
6b54c4e523 | ||
|
|
9c6300d6a5 | ||
|
|
fcb477de4f | ||
|
|
c5c06ce0bb | ||
|
|
c92632bfe0 | ||
|
|
4f70f7297b | ||
|
|
2dfdfa04a2 | ||
|
|
c297ab07b1 | ||
|
|
fdc9a1b1f2 | ||
|
|
116790b58f | ||
|
|
e08cd026d6 | ||
|
|
afcfb6712d | ||
|
|
3db00167e8 | ||
|
|
e5189e973b | ||
|
|
d6f460e54a | ||
|
|
6a0be69064 | ||
|
|
0eb379261a | ||
|
|
d6f1c61fb6 | ||
|
|
985a9a41c0 | ||
|
|
bc23b8b0c2 | ||
|
|
2cfeadf114 | ||
|
|
3abb3589a8 | ||
|
|
be4b6c2a0e | ||
|
|
3b6b183503 | ||
|
|
131750a5bc | ||
|
|
fe2543d981 | ||
|
|
18e2e1188b | ||
|
|
759ec97e70 | ||
|
|
829f445169 | ||
|
|
521fd43191 | ||
|
|
abf217e9f3 | ||
|
|
252a9c0133 | ||
|
|
adf6fcad61 | ||
|
|
0e159ad0c5 | ||
|
|
07e5c553e6 | ||
|
|
b4b1bdc3ed | ||
|
|
0711a60584 | ||
|
|
fb69d1500f | ||
|
|
3d83e742fd | ||
|
|
24fb15e4ef | ||
|
|
90491a00a5 | ||
|
|
62f55d0e25 | ||
|
|
85d7ac6afe | ||
|
|
07994a19cf | ||
|
|
b525401826 | ||
|
|
ad6fe2403f | ||
|
|
2f57f9b036 | ||
|
|
675bfa14a4 | ||
|
|
c64ed99efd | ||
|
|
68d7946293 | ||
|
|
8dc205c918 | ||
|
|
7708822b76 | ||
|
|
17ca23a15e | ||
|
|
a4065c9917 | ||
|
|
e9d24e5e4e | ||
|
|
2080001221 | ||
|
|
aae81be26d | ||
|
|
31a8dc5c24 | ||
|
|
df9e6473ec | ||
|
|
d5587376de | ||
|
|
929e019712 | ||
|
|
8a3a1aa8ae | ||
|
|
77b65d3999 | ||
|
|
611b7c543d | ||
|
|
0befe965af | ||
|
|
938edda04f | ||
|
|
f6e0068a45 | ||
|
|
b8e12c5a33 | ||
|
|
e893a6304e | ||
|
|
2baa92a84a | ||
|
|
a4749e1f50 | ||
|
|
9a25764763 | ||
|
|
1e919ba45d | ||
|
|
338fe2afec | ||
|
|
eb05f409b1 | ||
|
|
7fdfbf2b2b | ||
|
|
7ce1b5cf35 | ||
|
|
20ab09baa0 | ||
|
|
0bdb7b5141 | ||
|
|
46f395ae1d | ||
|
|
0f464e8303 | ||
|
|
fb4eec74d0 | ||
|
|
8ca5cd8256 | ||
|
|
b1ad85171e | ||
|
|
37a68609f0 | ||
|
|
8fc38d6201 | ||
|
|
87613d4c25 | ||
|
|
135e9fa753 | ||
|
|
28f0b9195b | ||
|
|
e1f700a0a2 | ||
|
|
815ddfb72b | ||
|
|
8f5f965fa8 | ||
|
|
64c695aec1 | ||
|
|
2173cf358b | ||
|
|
363269affb | ||
|
|
4ce8fd9a9b | ||
|
|
3e66b0cd02 | ||
|
|
94dd90ae88 | ||
|
|
6b59ba2ef2 | ||
|
|
8b827f410e | ||
|
|
f4e1b67d62 | ||
|
|
2f84f9791e | ||
|
|
93d9c67ec4 | ||
|
|
51fa58f11c | ||
|
|
b50fa0dd22 | ||
|
|
f32a6cab0d | ||
|
|
0ea3cc4b5e | ||
|
|
332da6ba34 | ||
|
|
f0c64b8666 | ||
|
|
848268d284 | ||
|
|
fbd155d602 | ||
|
|
635eb8cabd | ||
|
|
3dfadff339 | ||
|
|
f05794c4b0 | ||
|
|
23979e704b | ||
|
|
6fa2df53d2 | ||
|
|
88435c2701 | ||
|
|
a837aeead6 | ||
|
|
9570637275 | ||
|
|
63ad917675 | ||
|
|
447c0146f5 | ||
|
|
cbc07032f9 | ||
|
|
9f858e6bf5 | ||
|
|
824982dade | ||
|
|
ead43829e3 | ||
|
|
98f6df61ae | ||
|
|
9ab5a91df6 | ||
|
|
12c605af45 | ||
|
|
bd8fa1a972 | ||
|
|
9b51a64069 | ||
|
|
60a475e157 | ||
|
|
a6ab9c896b | ||
|
|
0ed8de72bc | ||
|
|
c6abe76ab9 | ||
|
|
c7287ce9dc | ||
|
|
4f10afa914 | ||
|
|
b7437055f0 | ||
|
|
19e03c4e71 | ||
|
|
b88fc4ea5b | ||
|
|
58e5e7e4bb | ||
|
|
da23449878 | ||
|
|
2ed52ed88b | ||
|
|
13a13aff17 | ||
|
|
3a90faa916 | ||
|
|
c19efe5f34 | ||
|
|
58e785a7e7 | ||
|
|
0861160e57 | ||
|
|
26daca4cf1 | ||
|
|
200af6de8d | ||
|
|
d4b41227bb | ||
|
|
0f133c04ac | ||
|
|
522becff95 | ||
|
|
d6f58c836f | ||
|
|
b1629c0cdf | ||
|
|
75c29031c2 | ||
|
|
7b50b5450a | ||
|
|
52a18de38f |
134
.copyright.hook
Normal file
134
.copyright.hook
Normal file
@@ -0,0 +1,134 @@
|
||||
# Copyright (c) 2020 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import print_function
|
||||
from __future__ import unicode_literals
|
||||
|
||||
import argparse
|
||||
import io
|
||||
import re
|
||||
import sys
|
||||
import os
|
||||
import datetime
|
||||
|
||||
COPYRIGHT = '''Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.'''
|
||||
|
||||
def _generate_copyright(comment_mark):
|
||||
copyright=COPYRIGHT.split(os.linesep)
|
||||
header = copyright[0].rstrip()
|
||||
|
||||
p = re.search('(\d{4})', header).group(0)
|
||||
now = datetime.datetime.now()
|
||||
|
||||
header = header.replace(p,str(now.year))
|
||||
|
||||
ans=[comment_mark + " " + header + os.linesep]
|
||||
for idx, line in enumerate(copyright[1:]):
|
||||
ans.append(comment_mark + " " + line.rstrip() + os.linesep)
|
||||
|
||||
return ans
|
||||
|
||||
def _get_comment_mark(path):
|
||||
lang_type=re.compile(r"\.(py|sh)$")
|
||||
if lang_type.search(path) is not None:
|
||||
return "#"
|
||||
|
||||
lang_type=re.compile(r"\.(h|c|hpp|cc|cpp|cu|go|cuh|proto)$")
|
||||
if lang_type.search(path) is not None:
|
||||
return "//"
|
||||
|
||||
return None
|
||||
|
||||
|
||||
RE_ENCODE = re.compile(r"^[ \t\v]*#.*?coding[:=]", re.IGNORECASE)
|
||||
RE_COPYRIGHT = re.compile(r".*Copyright( \(c\))* \d{4}", re.IGNORECASE)
|
||||
RE_SHEBANG = re.compile(r"^[ \t\v]*#[ \t]?\!")
|
||||
|
||||
def _check_copyright(path):
|
||||
head=[]
|
||||
try:
|
||||
with open(path) as f:
|
||||
head = [next(f) for x in range(4)]
|
||||
except StopIteration:
|
||||
pass
|
||||
|
||||
for idx, line in enumerate(head):
|
||||
if RE_COPYRIGHT.search(line) is not None:
|
||||
return True
|
||||
|
||||
return False
|
||||
|
||||
def generate_copyright(path, comment_mark):
|
||||
original_contents = io.open(path, encoding="utf-8").readlines()
|
||||
head = original_contents[0:4]
|
||||
|
||||
insert_line_no=0
|
||||
for i, line in enumerate(head):
|
||||
if RE_ENCODE.search(line) or RE_SHEBANG.search(line):
|
||||
insert_line_no=i+1
|
||||
|
||||
copyright = _generate_copyright(comment_mark)
|
||||
if insert_line_no == 0:
|
||||
new_contents = copyright
|
||||
if len(original_contents) > 0 and len(original_contents[0].strip()) != 0:
|
||||
new_contents.append(os.linesep)
|
||||
new_contents.extend(original_contents)
|
||||
else:
|
||||
new_contents=original_contents[0:insert_line_no]
|
||||
new_contents.append(os.linesep)
|
||||
new_contents.extend(copyright)
|
||||
if len(original_contents) > insert_line_no and len(original_contents[insert_line_no].strip()) != 0:
|
||||
new_contents.append(os.linesep)
|
||||
new_contents.extend(original_contents[insert_line_no:])
|
||||
new_contents="".join(new_contents)
|
||||
|
||||
with io.open(path, 'w') as output_file:
|
||||
output_file.write(new_contents)
|
||||
|
||||
|
||||
|
||||
def main(argv=None):
|
||||
parser = argparse.ArgumentParser(
|
||||
description='Checker for copyright declaration.')
|
||||
parser.add_argument('filenames', nargs='*', help='Filenames to check')
|
||||
args = parser.parse_args(argv)
|
||||
|
||||
retv = 0
|
||||
for path in args.filenames:
|
||||
comment_mark = _get_comment_mark(path)
|
||||
if comment_mark is None:
|
||||
print("warning:Unsupported file", path, file=sys.stderr)
|
||||
continue
|
||||
|
||||
if _check_copyright(path):
|
||||
continue
|
||||
|
||||
generate_copyright(path, comment_mark)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
exit(main())
|
||||
17
.github/ISSUE_TEMPLATE/----.md
vendored
17
.github/ISSUE_TEMPLATE/----.md
vendored
@@ -1,17 +0,0 @@
|
||||
---
|
||||
name: 问题反馈
|
||||
about: PaddleNLP问题反馈
|
||||
title: ''
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
欢迎您反馈PaddleNLP使用问题,非常感谢您对PaddleNLP的贡献!
|
||||
在留下您的问题时,辛苦您同步提供如下信息:
|
||||
- 版本、环境信息
|
||||
1)PaddleNLP和PaddlePaddle版本:请提供您的PaddleNLP和PaddlePaddle版本号,例如PaddleNLP 2.0.4,PaddlePaddle2.1.1
|
||||
2)系统环境:请您描述系统类型,例如Linux/Windows/MacOS/,python版本
|
||||
- 复现信息:如为报错,请给出复现环境、复现步骤
|
||||
|
||||
如还有问题可以到 PaddleNLP github 主页面的**[社区交流](https://github.com/PaddlePaddle/PaddleNLP#%E7%A4%BE%E5%8C%BA%E4%BA%A4%E6%B5%81)**扫描加入微信群,相关值班同学将会为您解答!
|
||||
26
.github/ISSUE_TEMPLATE/---general-issues---.md
vendored
26
.github/ISSUE_TEMPLATE/---general-issues---.md
vendored
@@ -1,26 +0,0 @@
|
||||
---
|
||||
name: "\U0001F4DD General issue / 一般问题"
|
||||
about: Report any issue about PaddleNLP / 提出任何一个与PaddleNLP相关的问题
|
||||
title: "[General Issue]"
|
||||
labels: question
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
Thanks for your issue. To help us solve the issue better, please provide following information:
|
||||
1. PaddleNLP version: (please specify the branch as well,e.g. PaddleNLP v2.2.1)
|
||||
2. PaddlePaddle version: (e.g. PaddlePaddle 2.1.0)
|
||||
3. Operation system: (e.g. Linux/Windows/MacOS)
|
||||
4. Python version: (e.g. Python3.6/3.7/3.8)
|
||||
5. CUDA/cuDNN version: (e.g. CUDA 10.2/cuDNN 7.6.5)
|
||||
6. Additional context: (Add any other context about the problem)
|
||||
|
||||
---
|
||||
|
||||
欢迎您反馈PaddleNLP使用问题,辛苦您提供以下信息,方便我们快速定位和解决问题:
|
||||
1. PaddleNLP版本:(请提供版本号和分支信息,如PaddleNLP v2.2.1)
|
||||
2. PaddlePaddle版本:(如PaddlePaddle 2.1.0)
|
||||
3. 操作系统信息:(如Linux/Windows/MacOS)
|
||||
4. Python版本号:(如Python3.6/3.7/3.8)
|
||||
5. CUDA/cuDNN版本:( 如CUDA 10.2/cuDNN 7.6.5等)
|
||||
6. 其他内容: (增加其他与问题相关的内容)
|
||||
23
.github/ISSUE_TEMPLATE/ask-question.yml
vendored
Normal file
23
.github/ISSUE_TEMPLATE/ask-question.yml
vendored
Normal file
@@ -0,0 +1,23 @@
|
||||
name: 🐛 Ask Question
|
||||
description: 请描述您使用PaddleNLP时遇到的问题
|
||||
title: "[Question]: "
|
||||
labels:
|
||||
- question
|
||||
body:
|
||||
- type: markdown
|
||||
attributes:
|
||||
value: >
|
||||
#### 你可以在这里提出一个使用/咨询问题,提问之前请确保:
|
||||
|
||||
- 1)已经百度/谷歌搜索过你的问题,但是没有找到解答;
|
||||
|
||||
- 2)已经在官网查询过[API文档](https://www.paddlepaddle.org.cn/documentation/docs/zh/api/index_cn.html)与[FAQ](https://www.paddlepaddle.org.cn/documentation/docs/zh/faq/index_cn.html),但是没有找到解答;
|
||||
|
||||
- 3)已经在[历史issue](https://github.com/PaddlePaddle/Paddle/issues)中搜索过,没有找到同类issue或issue未被解答。
|
||||
|
||||
- type: textarea
|
||||
id: question
|
||||
attributes:
|
||||
label: 请提出你的问题
|
||||
validations:
|
||||
required: true
|
||||
45
.github/ISSUE_TEMPLATE/bug-report.yml
vendored
Normal file
45
.github/ISSUE_TEMPLATE/bug-report.yml
vendored
Normal file
@@ -0,0 +1,45 @@
|
||||
name: 🐛 Bug Report
|
||||
description: PaddleNLP问题反馈
|
||||
title: "[Bug]: "
|
||||
labels: bug
|
||||
body:
|
||||
- type: textarea
|
||||
id: environment
|
||||
attributes:
|
||||
label: 软件环境
|
||||
description: |
|
||||
请使用以下命令给出您本地Paddle相关包信息
|
||||
```sh
|
||||
pip list | grep paddle
|
||||
|
||||
```
|
||||
value: |
|
||||
- paddlepaddle:
|
||||
- paddlepaddle-gpu:
|
||||
- paddlenlp:
|
||||
render: Markdown
|
||||
validations:
|
||||
required: true
|
||||
- type: checkboxes
|
||||
id: dumplicated-problem
|
||||
attributes:
|
||||
label: 重复问题
|
||||
description: 是否已在issues中搜索相关问题
|
||||
options:
|
||||
- label: I have searched the existing issues
|
||||
required: true
|
||||
- type: textarea
|
||||
id: descripton
|
||||
attributes:
|
||||
label: 错误描述
|
||||
description: 给出错误详细描述,以便能够更好的追踪相关问题
|
||||
render: Markdown
|
||||
validations:
|
||||
required: true
|
||||
- type: textarea
|
||||
id: mvp-code
|
||||
attributes:
|
||||
label: 稳定复现步骤 & 代码
|
||||
description: 请给出稳定复现该问题的步骤 & 代码,以便相关人员能够快速定位到具体问题。
|
||||
validations:
|
||||
required: true
|
||||
32
.github/ISSUE_TEMPLATE/docs-report.yml
vendored
Normal file
32
.github/ISSUE_TEMPLATE/docs-report.yml
vendored
Normal file
@@ -0,0 +1,32 @@
|
||||
name: 🐛 Docs Report
|
||||
description: PaddleNLP文档反馈
|
||||
title: "[Docs]: "
|
||||
labels:
|
||||
- documentation
|
||||
|
||||
body:
|
||||
- type: textarea
|
||||
id: environment
|
||||
attributes:
|
||||
label: 软件环境
|
||||
description: |
|
||||
请使用以下命令给出您本地Paddle相关包信息
|
||||
```sh
|
||||
pip list | grep paddle
|
||||
|
||||
```
|
||||
value: |
|
||||
- paddlepaddle:
|
||||
- paddlepaddle-gpu:
|
||||
- paddlenlp:
|
||||
render: Markdown
|
||||
validations:
|
||||
required: true
|
||||
- type: textarea
|
||||
id: description
|
||||
attributes:
|
||||
label: 详细描述
|
||||
description: 请详细描述您想要反馈的具体问题
|
||||
render: Markdown
|
||||
validations:
|
||||
required: true
|
||||
30
.github/ISSUE_TEMPLATE/feature-request.yml
vendored
Normal file
30
.github/ISSUE_TEMPLATE/feature-request.yml
vendored
Normal file
@@ -0,0 +1,30 @@
|
||||
name: "\U0001F680 Feature request"
|
||||
description: 请详细描述您所需功能
|
||||
labels: [ "feature" ]
|
||||
body:
|
||||
- type: textarea
|
||||
id: feature-request
|
||||
validations:
|
||||
required: true
|
||||
attributes:
|
||||
label: Feature request
|
||||
description: |
|
||||
对特性提案的清晰而简明的描述。如果论文和代码存在,请提供链接。
|
||||
|
||||
- type: textarea
|
||||
id: motivation
|
||||
validations:
|
||||
required: true
|
||||
attributes:
|
||||
label: Motivation
|
||||
description: |
|
||||
请概述这项建议的动机。您的特性要求与问题有关吗?
|
||||
|
||||
- type: textarea
|
||||
id: contribution
|
||||
validations:
|
||||
required: true
|
||||
attributes:
|
||||
label: Your contribution
|
||||
description: |
|
||||
Is there any way that you could help, e.g. by submitting a PR? Make sure to read the CONTRIBUTING.MD [readme](https://github.com/huggingface/transformers/blob/main/CONTRIBUTING.md)
|
||||
28
.github/ISSUE_TEMPLATE/new-model.yaml
vendored
Normal file
28
.github/ISSUE_TEMPLATE/new-model.yaml
vendored
Normal file
@@ -0,0 +1,28 @@
|
||||
name: "\U0001F31F 添加新模型"
|
||||
description: 请为新模型提交一份说明
|
||||
labels: [ "New model" ]
|
||||
|
||||
body:
|
||||
- type: textarea
|
||||
id: description-request
|
||||
validations:
|
||||
required: true
|
||||
attributes:
|
||||
label: 简要描述
|
||||
description: |
|
||||
请简要描述模型的类型、解决的问题等。
|
||||
|
||||
- type: checkboxes
|
||||
id: information-tasks
|
||||
attributes:
|
||||
label: 是否已开源
|
||||
options:
|
||||
- label: 已开源
|
||||
- label: 未开源
|
||||
|
||||
- type: textarea
|
||||
id: additional-info
|
||||
attributes:
|
||||
label: 模型详细信息
|
||||
description: |
|
||||
请给出新模型相关信息,如论文地址、现存代码地址等。
|
||||
23
.github/ISSUE_TEMPLATE/others.yml
vendored
Normal file
23
.github/ISSUE_TEMPLATE/others.yml
vendored
Normal file
@@ -0,0 +1,23 @@
|
||||
name: 🧩 其他 Others
|
||||
description: 提出其他问题。
|
||||
labels: [others]
|
||||
|
||||
body:
|
||||
- type: markdown
|
||||
attributes:
|
||||
value: >
|
||||
#### 你可以在这里提出任何前面几类模板不适用的问题,包括但不限于:优化性建议、框架使用体验反馈、版本兼容性问题、报错信息不清楚等。
|
||||
|
||||
- type: textarea
|
||||
id: others
|
||||
attributes:
|
||||
label: 问题描述
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: markdown
|
||||
attributes:
|
||||
value: >
|
||||
感谢你的贡献 🎉!
|
||||
|
||||
|
||||
60
.github/workflows/pypi.yml
vendored
Normal file
60
.github/workflows/pypi.yml
vendored
Normal file
@@ -0,0 +1,60 @@
|
||||
name: PyPI
|
||||
|
||||
on: [push, pull_request]
|
||||
|
||||
jobs:
|
||||
build:
|
||||
name: Build
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- uses: actions/setup-python@v1
|
||||
with:
|
||||
python-version: 3.8
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install -r requirements.txt
|
||||
pip install -r docs/requirements.txt
|
||||
pip install -r ppdiffusers/requirements.txt
|
||||
|
||||
ppdiffusers:
|
||||
name: Pack
|
||||
needs: build
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v2
|
||||
- uses: actions/setup-python@v1
|
||||
with:
|
||||
python-version: 3.8
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
pip install setuptools wheel twine
|
||||
make install-ppdiffusers
|
||||
|
||||
- name: Should Deploy to Pypi Server
|
||||
id: should-deploy
|
||||
run: python scripts/should_deploy.py --name ppdiffusers >> $GITHUB_OUTPUT
|
||||
- name: Check Branch
|
||||
id: check-branch
|
||||
run: |
|
||||
if [[ ${{ github.ref }} =~ ^refs/heads/(develop)$ ]]; then
|
||||
echo "match=true" >> $GITHUB_OUTPUT
|
||||
fi # See: https://stackoverflow.com/a/58869470/1123955
|
||||
|
||||
- name: Is A Publish Branch
|
||||
if: steps.check-branch.outputs.match == 'true' && steps.should-deploy.outputs.should_deploy == 'true'
|
||||
env:
|
||||
TWINE_USERNAME: paddle-dev
|
||||
TWINE_PASSWORD: ${{ secrets.paddlenlp }}
|
||||
run: |
|
||||
make deploy-ppdiffusers
|
||||
|
||||
- name: Should Not Deploy To Pypi Server
|
||||
if: steps.should-deploy.outputs.should_deploy != 'true'
|
||||
run: echo 'should not deploy pypi server'
|
||||
|
||||
- name: Is Not A Publish Branch
|
||||
if: steps.check-branch.outputs.match != 'true'
|
||||
run: echo 'Not A Publish Branch'
|
||||
1
.gitignore
vendored
1
.gitignore
vendored
@@ -123,3 +123,4 @@ FETCH_HEAD
|
||||
|
||||
# vscode
|
||||
.vscode
|
||||
./ppdiffusers/ppdiffusers/version.py
|
||||
@@ -26,3 +26,10 @@ repos:
|
||||
files: \.md$
|
||||
- id: remove-tabs
|
||||
files: \.md$
|
||||
- repo: local
|
||||
hooks:
|
||||
- id: copyright_checker
|
||||
name: copyright_checker
|
||||
entry: python .copyright.hook
|
||||
language: system
|
||||
files: \.(c|cc|cxx|cpp|cu|h|hpp|hxx|proto|xpu|kps|py|sh)$
|
||||
|
||||
88
CODE_OF_CONDUCT.md
Normal file
88
CODE_OF_CONDUCT.md
Normal file
@@ -0,0 +1,88 @@
|
||||
|
||||
# 贡献者公约
|
||||
|
||||
## 我们的承诺
|
||||
|
||||
身为社区成员、贡献者和领袖,我们承诺使社区参与者不受骚扰,无论其年龄、体型、可见或不可见的缺陷、族裔、性征、性别认同和表达、经验水平、教育程度、社会与经济地位、国籍、相貌、种族、种姓、肤色、宗教信仰、性倾向或性取向如何。
|
||||
|
||||
我们承诺以有助于建立开放、友善、多样化、包容、健康社区的方式行事和互动。
|
||||
|
||||
## 我们的准则
|
||||
|
||||
有助于为我们的社区创造积极环境的行为例子包括但不限于:
|
||||
|
||||
* 表现出对他人的同情和善意
|
||||
* 尊重不同的主张、观点和感受
|
||||
* 提出和大方接受建设性意见
|
||||
* 承担责任并向受我们错误影响的人道歉
|
||||
* 注重社区共同诉求,而非个人得失
|
||||
|
||||
不当行为例子包括:
|
||||
|
||||
* 使用情色化的语言或图像,及性引诱或挑逗
|
||||
* 嘲弄、侮辱或诋毁性评论,以及人身或政治攻击
|
||||
* 公开或私下的骚扰行为
|
||||
* 未经他人明确许可,公布他人的私人信息,如物理或电子邮件地址
|
||||
* 其他有理由认定为违反职业操守的不当行为
|
||||
|
||||
## 责任和权力
|
||||
|
||||
社区领袖有责任解释和落实我们所认可的行为准则,并妥善公正地对他们认为不当、威胁、冒犯或有害的任何行为采取纠正措施。
|
||||
|
||||
社区领导有权力和责任删除、编辑或拒绝或拒绝与本行为准则不相符的评论(comment)、提交(commits)、代码、维基(wiki)编辑、议题(issues)或其他贡献,并在适当时机知采取措施的理由。
|
||||
|
||||
## 适用范围
|
||||
|
||||
本行为准则适用于所有社区场合,也适用于在公共场所代表社区时的个人。
|
||||
|
||||
代表社区的情形包括使用官方电子邮件地址、通过官方社交媒体帐户发帖或在线上或线下活动中担任指定代表。
|
||||
|
||||
## 监督
|
||||
|
||||
辱骂、骚扰或其他不可接受的行为可通过 paddlenlp@baidu.com 向负责监督的社区领袖报告。
|
||||
所有投诉都将得到及时和公平的审查和调查。
|
||||
|
||||
所有社区领袖都有义务尊重任何事件报告者的隐私和安全。
|
||||
|
||||
## 处理方针
|
||||
|
||||
社区领袖将遵循下列社区处理方针来明确他们所认定违反本行为准则的行为的处理方式:
|
||||
|
||||
### 1. 纠正
|
||||
|
||||
**社区影响**:使用不恰当的语言或其他在社区中被认定为不符合职业道德或不受欢迎的行为。
|
||||
|
||||
**处理意见**:由社区领袖发出非公开的书面警告,明确说明违规行为的性质,并解释举止如何不妥。或将要求公开道歉。
|
||||
|
||||
### 2. 警告
|
||||
|
||||
**社区影响**:单个或一系列违规行为。
|
||||
|
||||
**处理意见**:警告并对连续性行为进行处理。在指定时间内,不得与相关人员互动,包括主动与行为准则执行者互动。这包括避免在社区场所和外部渠道中的互动。违反这些条款可能会导致临时或永久封禁。
|
||||
|
||||
### 3. 临时封禁
|
||||
|
||||
**社区影响**: 严重违反社区准则,包括持续的不当行为。
|
||||
|
||||
**处理意见**: 在指定时间内,暂时禁止与社区进行任何形式的互动或公开交流。在此期间,不得与相关人员进行公开或私下互动,包括主动与行为准则执行者互动。违反这些条款可能会导致永久封禁。
|
||||
|
||||
### 4. 永久封禁
|
||||
|
||||
**社区影响**:行为模式表现出违反社区准则,包括持续的不当行为、骚扰个人或攻击或贬低某个类别的个体。
|
||||
|
||||
**处理意见**:永久禁止在社区内进行任何形式的公开互动。
|
||||
|
||||
## 参见
|
||||
|
||||
本行为准则改编自 [Contributor Covenant][homepage] 2.1 版, 参见 [https://www.contributor-covenant.org/version/2/1/code_of_conduct.html][v2.1]。
|
||||
|
||||
社区处理方针灵感来源于 [Mozilla's code of conduct enforcement ladder][Mozilla CoC]。
|
||||
|
||||
有关本行为准则的常见问题的答案,参见 [https://www.contributor-covenant.org/faq][FAQ]。
|
||||
其他语言翻译参见 [https://www.contributor-covenant.org/translations][translations]。
|
||||
|
||||
[homepage]: https://www.contributor-covenant.org
|
||||
[v2.1]: https://www.contributor-covenant.org/version/2/1/code_of_conduct.html
|
||||
[Mozilla CoC]: https://github.com/mozilla/diversity
|
||||
[FAQ]: https://www.contributor-covenant.org/faq
|
||||
[translations]: https://www.contributor-covenant.org/translations
|
||||
133
CODE_OF_CONDUCT_en.md
Normal file
133
CODE_OF_CONDUCT_en.md
Normal file
@@ -0,0 +1,133 @@
|
||||
|
||||
# Contributor Covenant Code of Conduct
|
||||
|
||||
## Our Pledge
|
||||
|
||||
We as members, contributors, and leaders pledge to make participation in our
|
||||
community a harassment-free experience for everyone, regardless of age, body
|
||||
size, visible or invisible disability, ethnicity, sex characteristics, gender
|
||||
identity and expression, level of experience, education, socio-economic status,
|
||||
nationality, personal appearance, race, caste, color, religion, or sexual
|
||||
identity and orientation.
|
||||
|
||||
We pledge to act and interact in ways that contribute to an open, welcoming,
|
||||
diverse, inclusive, and healthy community.
|
||||
|
||||
## Our Standards
|
||||
|
||||
Examples of behavior that contributes to a positive environment for our
|
||||
community include:
|
||||
|
||||
* Demonstrating empathy and kindness toward other people
|
||||
* Being respectful of differing opinions, viewpoints, and experiences
|
||||
* Giving and gracefully accepting constructive feedback
|
||||
* Accepting responsibility and apologizing to those affected by our mistakes,
|
||||
and learning from the experience
|
||||
* Focusing on what is best not just for us as individuals, but for the overall
|
||||
community
|
||||
|
||||
Examples of unacceptable behavior include:
|
||||
|
||||
* The use of sexualized language or imagery, and sexual attention or advances of
|
||||
any kind
|
||||
* Trolling, insulting or derogatory comments, and personal or political attacks
|
||||
* Public or private harassment
|
||||
* Publishing others' private information, such as a physical or email address,
|
||||
without their explicit permission
|
||||
* Other conduct which could reasonably be considered inappropriate in a
|
||||
professional setting
|
||||
|
||||
## Enforcement Responsibilities
|
||||
|
||||
Community leaders are responsible for clarifying and enforcing our standards of
|
||||
acceptable behavior and will take appropriate and fair corrective action in
|
||||
response to any behavior that they deem inappropriate, threatening, offensive,
|
||||
or harmful.
|
||||
|
||||
Community leaders have the right and responsibility to remove, edit, or reject
|
||||
comments, commits, code, wiki edits, issues, and other contributions that are
|
||||
not aligned to this Code of Conduct, and will communicate reasons for moderation
|
||||
decisions when appropriate.
|
||||
|
||||
## Scope
|
||||
|
||||
This Code of Conduct applies within all community spaces, and also applies when
|
||||
an individual is officially representing the community in public spaces.
|
||||
Examples of representing our community include using an official e-mail address,
|
||||
posting via an official social media account, or acting as an appointed
|
||||
representative at an online or offline event.
|
||||
|
||||
## Enforcement
|
||||
|
||||
Instances of abusive, harassing, or otherwise unacceptable behavior may be
|
||||
reported to the community leaders responsible for enforcement at
|
||||
paddlenlp@baidu.com.
|
||||
All complaints will be reviewed and investigated promptly and fairly.
|
||||
|
||||
All community leaders are obligated to respect the privacy and security of the
|
||||
reporter of any incident.
|
||||
|
||||
## Enforcement Guidelines
|
||||
|
||||
Community leaders will follow these Community Impact Guidelines in determining
|
||||
the consequences for any action they deem in violation of this Code of Conduct:
|
||||
|
||||
### 1. Correction
|
||||
|
||||
**Community Impact**: Use of inappropriate language or other behavior deemed
|
||||
unprofessional or unwelcome in the community.
|
||||
|
||||
**Consequence**: A private, written warning from community leaders, providing
|
||||
clarity around the nature of the violation and an explanation of why the
|
||||
behavior was inappropriate. A public apology may be requested.
|
||||
|
||||
### 2. Warning
|
||||
|
||||
**Community Impact**: A violation through a single incident or series of
|
||||
actions.
|
||||
|
||||
**Consequence**: A warning with consequences for continued behavior. No
|
||||
interaction with the people involved, including unsolicited interaction with
|
||||
those enforcing the Code of Conduct, for a specified period of time. This
|
||||
includes avoiding interactions in community spaces as well as external channels
|
||||
like social media. Violating these terms may lead to a temporary or permanent
|
||||
ban.
|
||||
|
||||
### 3. Temporary Ban
|
||||
|
||||
**Community Impact**: A serious violation of community standards, including
|
||||
sustained inappropriate behavior.
|
||||
|
||||
**Consequence**: A temporary ban from any sort of interaction or public
|
||||
communication with the community for a specified period of time. No public or
|
||||
private interaction with the people involved, including unsolicited interaction
|
||||
with those enforcing the Code of Conduct, is allowed during this period.
|
||||
Violating these terms may lead to a permanent ban.
|
||||
|
||||
### 4. Permanent Ban
|
||||
|
||||
**Community Impact**: Demonstrating a pattern of violation of community
|
||||
standards, including sustained inappropriate behavior, harassment of an
|
||||
individual, or aggression toward or disparagement of classes of individuals.
|
||||
|
||||
**Consequence**: A permanent ban from any sort of public interaction within the
|
||||
community.
|
||||
|
||||
## Attribution
|
||||
|
||||
This Code of Conduct is adapted from the [Contributor Covenant][homepage],
|
||||
version 2.1, available at
|
||||
[https://www.contributor-covenant.org/version/2/1/code_of_conduct.html][v2.1].
|
||||
|
||||
Community Impact Guidelines were inspired by
|
||||
[Mozilla's code of conduct enforcement ladder][Mozilla CoC].
|
||||
|
||||
For answers to common questions about this code of conduct, see the FAQ at
|
||||
[https://www.contributor-covenant.org/faq][FAQ]. Translations are available at
|
||||
[https://www.contributor-covenant.org/translations][translations].
|
||||
|
||||
[homepage]: https://www.contributor-covenant.org
|
||||
[v2.1]: https://www.contributor-covenant.org/version/2/1/code_of_conduct.html
|
||||
[Mozilla CoC]: https://github.com/mozilla/diversity
|
||||
[FAQ]: https://www.contributor-covenant.org/faq
|
||||
[translations]: https://www.contributor-covenant.org/translations
|
||||
10
Makefile
Normal file
10
Makefile
Normal file
@@ -0,0 +1,10 @@
|
||||
|
||||
|
||||
.PHONY: deploy-ppdiffusers
|
||||
deploy-ppdiffusers:
|
||||
cd ppdiffusers && make
|
||||
|
||||
.PHONY: install-ppdiffusers
|
||||
install-ppdiffusers:
|
||||
cd ppdiffusers && make install
|
||||
|
||||
38
README_cn.md
38
README_cn.md
@@ -30,24 +30,30 @@
|
||||
**PaddleNLP**是一款**简单易用**且**功能强大**的自然语言处理开发库。聚合业界**优质预训练模型**并提供**开箱即用**的开发体验,覆盖NLP多场景的模型库搭配**产业实践范例**可满足开发者**灵活定制**的需求。
|
||||
|
||||
## News 📢
|
||||
* 📝 2022.8.1 **PaddleNLP v2.3.5**发布!新增[**CodeGen**](./examples/code_generation/codegen) 对话式程序生成大模型,支持Taskflow一键调用;通用信息抽取技术英文模型[**UIE-en**](./model_zoo/uie)正式发布,支持英文各项信息抽取工作; [**RGL**](./examples/few_shot/RGL)是百度自研的 Prompt-based tuning 小样本学习算法,论文被 Findings of NAACL 2022 接收,欢迎大家使用!
|
||||
* 🍭 2022.6.29 **PaddleNLP v2.3.4**发布 全系列中文预训练小模型发布,快速提升预训练模型部署效率,通用信息抽取技术[**UIE Tiny**](./model_zoo/uie) 系列模型全新升级,支持速度更快效果更好的UIE小模型。
|
||||
* 🔥 2022.5.16 [**PaddleNLP v2.3**](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.3.0)全新发布!🎉
|
||||
* 💎 发布通用信息抽取技术[**UIE**](./model_zoo/uie),单模型支持实体识别、关系和事件抽取、情感分析等多种开放域信息抽取任务,不限领域和抽取目标,支持**一键抽取**与全流程**小样本**高效定制开发。
|
||||
* 😊 发布文心大模型[**ERNIE 3.0**](./model_zoo/ernie-3.0)轻量级模型,在[CLUE](https://www.cluebenchmarks.com/)上实现同规模结构效果最佳,并提供**🗜️无损压缩**和**⚙️全场景部署**方案。
|
||||
* 🏥 发布中文医疗领域预训练模型[**ERNIE-Health**](./model_zoo/ernie-health),[CBLUE](https://github.com/CBLUEbenchmark/CBLUE)中文医疗信息处理评测冠军模型。
|
||||
* 💬 发布大规模百亿开放域对话预训练模型[**PLATO-XL**](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/model_zoo/plato-xl) ,配合⚡**FasterGeneration**⚡快速实现高性能GPU并行推理加速。
|
||||
* 🔥 **2022.10.27 发布 [PaddleNLP v2.4.2](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.2)**
|
||||
* NLG能力扩充:新增📄[**基于Pegasus的中文文本摘要方案**](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_summarization/pegasus),效果领先;新增❓[**问题生成解决方案**](./examples/question_generation),提供基于业界领先模型UNIMO-Text和大规模多领域问题生成数据集训练的通用问题生成预训练模型。均支持Taskflow一键调用,支持FasterGeneration高性能推理,训练推理部署全流程打通。
|
||||
* 发布 🖼[**PPDiffusers**](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/ppdiffusers):支持跨模态(如图像与语音)训练和推理的扩散模型(Diffusion Model)工具箱,可快速体验、二次开发 **Stable Diffusion**,持续支持更多模型。
|
||||
|
||||
* 🔥 **2022.10.14 发布 [PaddleNLP v2.4.1](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.1)**
|
||||
* 🧾 发布多语言跨模态布局增强文档智能大模型 [**ERNIE-Layout**](./model_zoo/ernie-layout/),刷新11项任务SOTA。同步发布基于ERNIE-Layout的**文档抽取问答模型DocPrompt** 🔖,精准理解文档图片布局与语义信息,轻松应对各类业务场景。
|
||||
|
||||
* 🔥 **2022.9.6 发布 [PaddleNLP v2.4](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.0)**
|
||||
* 💎 NLP工具:**[NLP 流水线系统 Pipelines](./pipelines)** 发布,支持快速搭建搜索引擎、问答系统,可扩展支持各类NLP系统,让解决 NLP 任务像搭积木一样便捷、灵活、高效!
|
||||
* 💢 产业应用:新增 **[文本分类全流程应用方案](./applications/text_classification)** ,覆盖多分类、多标签、层次分类各类场景,支持 **小样本学习** 和 **TrustAI** 可信计算模型训练与调优;[**通用信息抽取 UIE 能力升级**](./model_zoo/uie),发布 **UIE-M**,支持中英文混合抽取,新增**UIE 数据蒸馏**方案,打破 UIE 推理瓶颈,推理速度提升 100 倍以上;
|
||||
* 🍭 AIGC 内容生成:新增代码生成 SOTA 模型[**CodeGen**](./examples/code_generation/codegen),支持多种编程语言代码生成;集成[**文图生成潮流模型**](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/model_zoo/taskflow.md#%E6%96%87%E5%9B%BE%E7%94%9F%E6%88%90) DALL·E Mini、Disco Diffusion、Stable Diffusion,更多趣玩模型等你来玩;新增[**中文文本摘要应用**](./applications/text_summarization),基于大规模语料的中文摘要模型首次发布,可支持 Taskflow 一键调用和定制训练;
|
||||
* 💪 框架升级:[**模型自动压缩 API**](./docs/compression.md) 发布,自动对模型进行裁减和量化,大幅降低模型压缩技术使用门槛;[**小样本 Prompt**](./applications/text_classification/multi_class/few-shot)能力发布,集成 PET、P-Tuning、RGL 等经典算法。
|
||||
|
||||
|
||||
## 社区交流
|
||||
|
||||
- 微信扫描二维码并填写问卷之后,加入交流群领取福利
|
||||
- 微信扫描二维码并填写问卷,回复小助手关键词(NLP)之后,即可加入交流群领取福利
|
||||
|
||||
- 与众多社区开发者以及官方团队深度交流。
|
||||
- 10G重磅NLP学习大礼包!
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/184784832-bb97930f-a738-4480-99be-517aeb65afac.png" width="150" height="150" />
|
||||
</div>
|
||||
|
||||
<img src="https://user-images.githubusercontent.com/11793384/200770385-a2c02093-0e1d-4189-b324-8b0251cba316.jpg" width="150" height="150" />
|
||||
</div>
|
||||
## 特性
|
||||
|
||||
#### <a href=#开箱即用的nlp工具集> 📦 开箱即用的NLP工具集 </a>
|
||||
@@ -65,6 +71,14 @@ Taskflow提供丰富的**📦开箱即用**的产业级NLP预置模型,覆盖
|
||||
|
||||
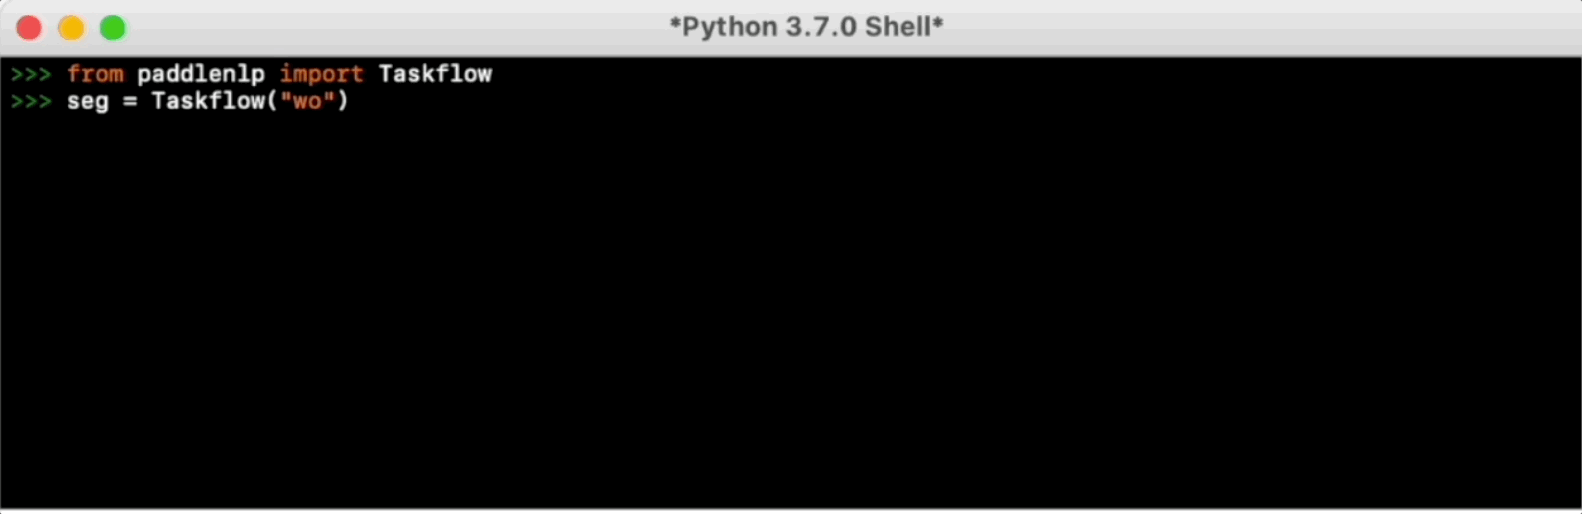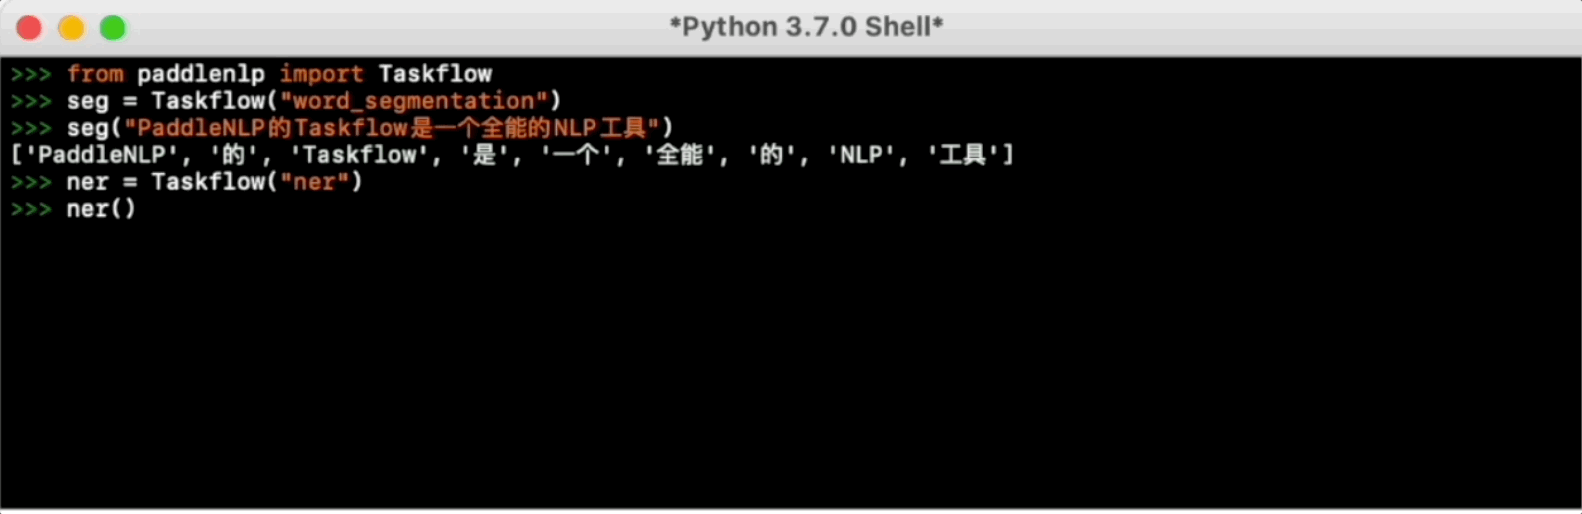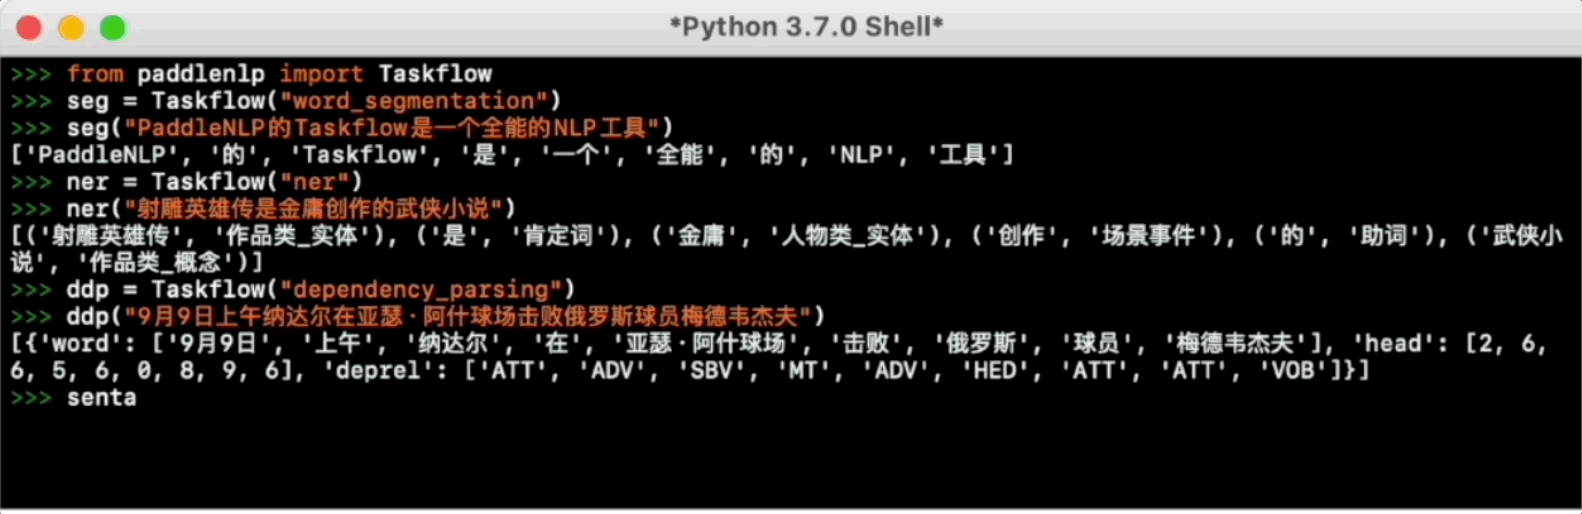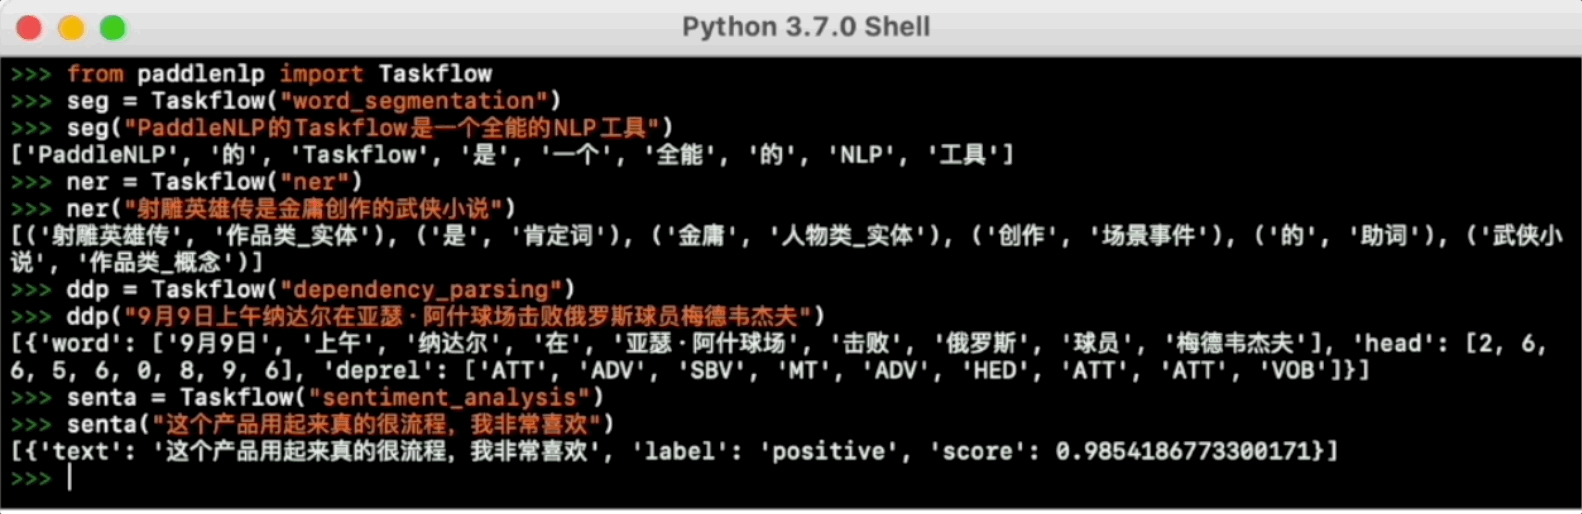
|
||||
|
||||
Taskflow最新集成了文生图的趣玩应用,三行代码体验 **Stable Diffusion**
|
||||
```python
|
||||
from paddlenlp import Taskflow
|
||||
text_to_image = Taskflow("text_to_image", model="CompVis/stable-diffusion-v1-4")
|
||||
image_list = text_to_image('"In the morning light,Chinese ancient buildings in the mountains,Magnificent and fantastic John Howe landscape,lake,clouds,farm,Fairy tale,light effect,Dream,Greg Rutkowski,James Gurney,artstation"')
|
||||
```
|
||||
<img width="300" alt="image" src="https://user-images.githubusercontent.com/16698950/194882669-f7cc7c98-d63a-45f4-99c1-0514c6712368.png">
|
||||
|
||||
更多使用方法可参考[Taskflow文档](./docs/model_zoo/taskflow.md)。
|
||||
|
||||
### 丰富完备的中文模型库
|
||||
@@ -196,7 +210,7 @@ PaddleNLP针对信息抽取、语义检索、智能问答、情感分析等高
|
||||
</div>
|
||||
|
||||
|
||||
更多使用说明请参考[智能问答系统](./applications/question_answering)与[文档智能问答](./applications/doc_vqa)
|
||||
更多使用说明请参考[智能问答系统](./applications/question_answering)与[文档智能问答](./applications/document_intelligence/doc_vqa)
|
||||
|
||||
#### 💌 评论观点抽取与情感分析
|
||||
|
||||
|
||||
42
README_en.md
42
README_en.md
@@ -29,16 +29,23 @@
|
||||
**PaddleNLP** is an *easy-to-use* and *powerful* NLP library with **Awesome** pre-trained model zoo, supporting wide-range of NLP tasks from research to industrial applications.
|
||||
|
||||
## News 📢
|
||||
* 📝 2022.8.1 **PaddleNLP v2.3.5** Released!
|
||||
* Release the dialogic code generation model [**CodeGen**](./examples/code_generation/codegen), which can be easily used via [Taskflow](./docs/model_zoo/taskflow.md).
|
||||
* Release [**UIE en**](./model_zoo/uie), supports for multiple tasks in **open-domain** information extraction.
|
||||
* Release [**RGL**](./examples/few_shot/RGL), an independent research prompt-base tuning approach for few-shot learning, the paper is accepted by NAACL 2022.
|
||||
* 🍭 2022.6.29 **PaddleNLP v2.3.4** Released! Whole series of Chinese pretrained models [**ERNIE Tiny**](./model_zoo/ernie-3.0) are released to quickly improve deployment efficiency. We also provides smaller and faster models [**UIE Tiny**](./model_zoo/uie) for universal information extraction.
|
||||
* 🔥 2022.5.16 PaddleNLP [v2.3](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.3.0) Released!🎉
|
||||
* 💎 Release [**UIE** (Universal Information Extraction)](./model_zoo/uie) technique, single model supports multiple **open-domain** IE tasks. Super easy to use and finetune with few examples via [Taskflow](./docs/model_zoo/taskflow.md).
|
||||
* 😊 Release [**ERNIE 3.0**](./model_zoo/ernie-3.0) light-weight model achieved better results compared to ERNIE 2.0 on [CLUE](https://www.cluebenchmarks.com/), also including **🗜️lossless model compression** and **⚙️end-to-end deployment**.
|
||||
* 🏥 Release [**ERNIE-Health**](./model_zoo/ernie-health), a **SOTA** biomedical pretrained model on [CBLUE](https://github.com/CBLUEbenchmark/CBLUE).
|
||||
* 💬 Release [**PLATO-XL**](./model_zoo/plato-xl) with ⚡**FasterGeneration**⚡, the *11B open-domain SOTA chatbot model* can be deployed on multi-GPU and do parallel inference easily.
|
||||
|
||||
* 🔥 **2022.10.27 [PaddleNLP v2.4.2](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.2) Released!**
|
||||
* NLG Upgrade: 📄 Release [**Solution of Text Summarization**](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_summarization/pegasus) based on Pegasus;❓ Release [**Solution of Problem Generation**](./examples/question_generation), providing **general problem generation pre-trained model** based on Baidu's UNIMO Text and large-scale multi domain problem generation dataset。Supporting high-performance inference ability based on FasterGeneration , and covering the whole process of training , inference and deployment.
|
||||
* 🔥 **2022.10.14 [PaddleNLP v2.4.1](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.1) Released!**
|
||||
* 🧾 Release multilingual/cross-lingual pre-trained models [**ERNIE-Layout**](./model_zoo/ernie-layout/) which achieves new SOTA results in 11 downstream tasks. **DocPrompt** 🔖 based on ERNIE-Layout is also released which has the ability for multilingual document information extraction and question ansering.
|
||||
* 🔥 **2022.9.6 [PaddleNLPv2.4](https://github.com/PaddlePaddle/PaddleNLP/releases/tag/v2.4.0) Released!**
|
||||
|
||||
* 💎 NLP Tool:**[Pipelines](./pipelines)** released. Supports for fast construction of search engine and question answering systems, and it is expandable to all kinds of NLP systems. Building end-to-end pipelines for NLP tasks like playing Lego!
|
||||
|
||||
* 💢 Industrial application:Release **[Complete Solution of Text Classification](./applications/text_classification)** covering various scenarios of text classification: multi-class, multi-label and hierarchical, it also supports for **few-shot learning** and the training and optimization of **TrustAI**. Upgrade for [**Universal Information Extraction**](./model_zoo/uie) and release **UIE-M**, support both Chinese and English information extraction in a single model; release the data distillation solution for UIE to break the bottleneck of time-consuming of inference.
|
||||
|
||||
* 🍭 AIGC: Release code generation SOTA model [**CodeGen**](./examples/code_generation/codegen), supports for multiple programming languages code generation. Integrate [**Text to Image Model**](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/model_zoo/taskflow.md#%E6%96%87%E5%9B%BE%E7%94%9F%E6%88%90) DALL·E Mini, Disco Diffusion, Stable Diffusion, let's play and have some fun! Release [**Chinese Text Summarization Application**](./applications/text_summarization), first release of chinese text summarization model pretrained on a large scale of corpus, it can be use via Taskflow API and support for finetuning on your own data.
|
||||
|
||||
* 💪 Framework upgrade: Release [**Auto Model Compression API**](./docs/compression.md), supports for pruning and quantization automatically, lower the barriers of model compression; Release [**Few-shot Prompt**](./applications/text_classification/multi_class/few-shot), includes the algorithms such as PET, P-Tuning and RGL.
|
||||
|
||||
|
||||
|
||||
|
||||
## Features
|
||||
|
||||
@@ -63,7 +70,7 @@ For more usage please refer to [Taskflow Docs](./docs/model_zoo/taskflow.md).
|
||||
|
||||
#### 🀄 Comprehensive Chinese Transformer Models
|
||||
|
||||
We provide **45+** network architectures and over **500+** pretrained models. Not only includes all the SOTA model like ERNIE, PLATO and SKEP released by Baidu, but also integrates most of the high-quality Chinese pretrained model developed by other organizations. Use `AutoModel` API to **⚡SUPER FAST⚡** download pretrained mdoels of different architecture. We welcome all developers to contribute your Transformer models to PaddleNLP!
|
||||
We provide **45+** network architectures and over **500+** pretrained models. Not only includes all the SOTA model like ERNIE, PLATO and SKEP released by Baidu, but also integrates most of the high-quality Chinese pretrained model developed by other organizations. Use `AutoModel` API to **⚡SUPER FAST⚡** download pretrained models of different architecture. We welcome all developers to contribute your Transformer models to PaddleNLP!
|
||||
|
||||
```python
|
||||
from paddlenlp.transformers import *
|
||||
@@ -187,7 +194,7 @@ We provide question answering pipeline which can support FAQ system, Document-le
|
||||
</div>
|
||||
|
||||
|
||||
For more details please refer to [Question Answering](./applications/question_answering) and [Document VQA](./applications/doc_vqa).
|
||||
For more details please refer to [Question Answering](./applications/question_answering) and [Document VQA](./applications/document_intelligence/doc_vqa).
|
||||
|
||||
|
||||
#### 💌 Opinion Extraction and Sentiment Analysis
|
||||
@@ -310,10 +317,6 @@ Please find all PaddleNLP API Reference from our [readthedocs](https://paddlenlp
|
||||
|
||||
## Community
|
||||
|
||||
### Special Interest Group (SIG)
|
||||
|
||||
Welcome to join [PaddleNLP SIG](https://iwenjuan.baidu.com/?code=bkypg8) for contribution, eg. Dataset, Models and Toolkit.
|
||||
|
||||
### Slack
|
||||
|
||||
To connect with other users and contributors, welcome to join our [Slack channel](https://paddlenlp.slack.com/).
|
||||
@@ -322,9 +325,10 @@ To connect with other users and contributors, welcome to join our [Slack channel
|
||||
|
||||
Scan the QR code below with your Wechat⬇️. You can access to official technical exchange group. Look forward to your participation.
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/184784832-bb97930f-a738-4480-99be-517aeb65afac.png" width="150" height="150" />
|
||||
</div>
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/11793384/200770385-a2c02093-0e1d-4189-b324-8b0251cba316.jpg" width="150" height="150" />
|
||||
</div>
|
||||
|
||||
|
||||
|
||||
## Citation
|
||||
|
||||
@@ -1,24 +0,0 @@
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
QUESTION=$1
|
||||
|
||||
python3 change_to_mrc.py ${QUESTION}
|
||||
|
||||
python3 ./run_docvqa.py \
|
||||
--model_name_or_path "layoutxlm-base-uncased" \
|
||||
--max_seq_len 512 \
|
||||
--do_test true \
|
||||
--test_file "data/demo_test.json" \
|
||||
--num_train_epochs 100 \
|
||||
--eval_steps 6000 \
|
||||
--save_steps 6000 \
|
||||
--output_dir "output/" \
|
||||
--save_path "data/decode_res.json" \
|
||||
--init_checkpoint "./checkpoints/layoutxlm/" \
|
||||
--learning_rate 3e-5 \
|
||||
--warmup_steps 12000 \
|
||||
--per_gpu_train_batch_size 4 \
|
||||
--per_gpu_eval_batch_size 1 \
|
||||
--seed 2048
|
||||
|
||||
python3 view.py
|
||||
@@ -1,18 +0,0 @@
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
python3 ./run_docvqa.py \
|
||||
--model_name_or_path "layoutxlm-base-uncased" \
|
||||
--max_seq_len 512 \
|
||||
--train_file "data/train.json" \
|
||||
--init_checkpoint "checkpoints/base_model" \
|
||||
--do_train true \
|
||||
--num_train_epochs 50 \
|
||||
--eval_steps 24000 \
|
||||
--save_steps 40 \
|
||||
--output_dir "output" \
|
||||
--save_path "data/decode_res.json" \
|
||||
--learning_rate 3e-5 \
|
||||
--warmup_steps 40 \
|
||||
--per_gpu_train_batch_size 4 \
|
||||
--per_gpu_eval_batch_size 4 \
|
||||
--seed 2048
|
||||
@@ -1,19 +0,0 @@
|
||||
import sys
|
||||
import json
|
||||
|
||||
question = sys.argv[1]
|
||||
|
||||
with open('../OCR_process/demo_ocr_res.json', 'r', encoding='utf8') as f:
|
||||
paras = []
|
||||
for line in f:
|
||||
line = json.loads(line.strip())
|
||||
document = line['document']
|
||||
para = []
|
||||
for token in document:
|
||||
token = token.replace('▁', '')
|
||||
para.append(token)
|
||||
paras.append(''.join(para))
|
||||
|
||||
with open('./data/demo.tsv', 'w', encoding='utf8') as f:
|
||||
for para in paras:
|
||||
f.write('{}\t\t{}\t0\n'.format(question, para))
|
||||
@@ -1,20 +0,0 @@
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
QUESTION=$1
|
||||
|
||||
# Question: NFC咋开门
|
||||
|
||||
if [ $# != 1 ];then
|
||||
echo "USAGE: sh script/run_cross_encoder_test.sh \$QUESTION"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# compute scores for QUESTION and OCR parsing results with Rerank module
|
||||
cd Rerank
|
||||
bash run_test.sh ${QUESTION}
|
||||
cd ..
|
||||
|
||||
# extraction answer for QUESTION from the top1 of rank
|
||||
cd Extraction
|
||||
bash run_test.sh ${QUESTION}
|
||||
cd ..
|
||||
188
applications/document_intelligence/README.md
Normal file
188
applications/document_intelligence/README.md
Normal file
@@ -0,0 +1,188 @@
|
||||
# 文档智能应用
|
||||
|
||||
**目录**
|
||||
- [1. 文档智能应用简介](#文档智能应用简介)
|
||||
- [2. 技术特色介绍](#技术特色介绍)
|
||||
- [2.1 多语言跨模态训练基座](#多语言跨模态训练基座)
|
||||
- [2.2 多场景覆盖](#多场景覆盖)
|
||||
- [3. 快速开始](#快速开始)
|
||||
- [3.1 开箱即用](#开箱即用)
|
||||
- [3.2 产业级流程方案](#产业级流程方案)
|
||||
|
||||
## 1. 文档智能应用简介
|
||||
|
||||
文档智能(DI, Document Intelligence)主要指**对于网页、数字文档或扫描文档所包含的文本以及丰富的排版格式等信息,通过人工智能技术进行理解、分类、提取以及信息归纳**的过程。文档智能技术广泛应用于金融、保险、能源、物流、医疗等行业,常见的应用场景包括财务报销单、招聘简历、企业财报、合同文书、动产登记证、法律判决书、物流单据等多模态文档的关键信息抽取、文档解析、文档比对等。
|
||||
|
||||
在实际应用中,需要解决文档格式繁杂、布局多样、信息模态多样、需求开放、业务数据少等多重难题。针对文档智能领域的痛点和难点,PaddleNLP将持续开源一系列产业实践范例,解决开发者们实际应用难题。
|
||||
|
||||
<div align="center">
|
||||
<img width="1000" height="270" alt="文档智能技术一般流程" src="https://user-images.githubusercontent.com/40840292/196361583-6b1c66d1-6a9b-4193-949a-71e2d420a82a.png">
|
||||
</div>
|
||||
|
||||
<a name="技术特色介绍"></a>
|
||||
|
||||
## 2. 技术特色介绍
|
||||
|
||||
<a name="多语言跨模态训练基座"></a>
|
||||
|
||||
### 2.1 多语言跨模态训练基座
|
||||
|
||||
近期,百度文心文档智能,基于多语言跨模态布局增强的文档智能大模型[ERNIE-Layout](http://arxiv.org/abs/2210.06155),刷新了五类11项文档智能任务效果。依托文心ERNIE大模型,基于布局知识增强技术,融合文本、图像、布局等信息进行联合建模,能够对多模态文档(如文档图片、PDF 文件、扫描件等)进行深度理解与分析,为各类上层应用提供SOTA模型底座。
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/196373896-597f6178-4c78-41a1-bb12-796546644b32.png width="600"/>
|
||||
</div>
|
||||
|
||||
<a name="多场景覆盖"></a>
|
||||
|
||||
### 2.2 多场景覆盖
|
||||
|
||||
以下是文档智能技术的一些应用场景展示:
|
||||
|
||||
- 发票抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/196118171-fd3e49a0-b9f1-4536-a904-c48f709a2dec.png height=350 width=1000 hspace='10'/>
|
||||
</div>
|
||||
|
||||
- 海报抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195610368-04230855-62de-439e-b708-2c195b70461f.png height=600 width=1000 hspace='15'/>
|
||||
</div>
|
||||
|
||||
- 网页抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195611613-bdbe692e-d7f2-4a2b-b548-1a933463b0b9.png height=350 width=1000 hspace='10'/>
|
||||
</div>
|
||||
|
||||
|
||||
- 表格抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195610692-8367f1c8-32c2-4b5d-9514-a149795cf609.png height=350 width=1000 hspace='10'/>
|
||||
</div>
|
||||
|
||||
|
||||
- 试卷抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195823294-d891d95a-2ef8-4519-be59-0fedb96c00de.png height=700 width=1000 hspace='10'/>
|
||||
</div>
|
||||
|
||||
|
||||
- 英文票据多语种(中、英、日、泰、西班牙、俄语)抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195610820-7fb88608-b317-45fc-a6ab-97bf3b20a4ac.png height=400 width=1000 hspace='15'/>
|
||||
</div>
|
||||
|
||||
- 中文票据多语种(中简、中繁、英、日、法语)抽取问答
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195611075-9323ce9f-134b-4657-ab1c-f4892075d909.png height=350 width=1000 hspace='15'/>
|
||||
</div>
|
||||
|
||||
- Demo图片可在此[下载](https://bj.bcebos.com/paddlenlp/taskflow/document_intelligence/demo.zip)
|
||||
|
||||
<a name="快速开始"></a>
|
||||
|
||||
## 3. 快速开始
|
||||
|
||||
<a name="开箱即用"></a>
|
||||
|
||||
### 3.1 开箱即用
|
||||
|
||||
开源DocPrompt开放文档抽取问答模型,以ERNIE-Layout为底座,可精准理解图文信息,推理学习附加知识,准备捕捉图片、PDF等多模态文档中的每个细节。
|
||||
|
||||
🧾 通过[Huggingface网页](https://huggingface.co/spaces/PaddlePaddle/ERNIE-Layout)体验DocPrompt功能:
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/195749427-864d7744-1fd1-455e-99c6-53a260776483.jpg height=700 width=1100 hspace='10'/>
|
||||
</div>
|
||||
|
||||
#### Taskflow
|
||||
|
||||
通过``paddlenlp.Taskflow``三行代码调用DocPrompt功能,具备多语言文档抽取问答能力,部分应用场景展示如下:
|
||||
|
||||
- 输入格式
|
||||
|
||||
```
|
||||
[
|
||||
{"doc": "./invoice.jpg", "prompt": ["发票号码是多少?", "校验码是多少?"]},
|
||||
{"doc": "./resume.png", "prompt": ["五百丁本次想要担任的是什么职位?", "五百丁是在哪里上的大学?", "大学学的是什么专业?"]}
|
||||
]
|
||||
```
|
||||
|
||||
默认使用PaddleOCR进行OCR识别,同时支持用户通过``word_boxes``传入自己的OCR结果,格式为``List[str, List[float, float, float, float]]``。
|
||||
|
||||
```
|
||||
[
|
||||
{"doc": doc_path, "prompt": prompt, "word_boxes": word_boxes}
|
||||
]
|
||||
```
|
||||
|
||||
- 支持单条、批量预测
|
||||
|
||||
- 支持本地图片路径输入
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/194748579-f9e8aa86-7f65-4827-bfae-824c037228b3.png height=800 hspace='20'/>
|
||||
</div>
|
||||
|
||||
```python
|
||||
>>> from pprint import pprint
|
||||
>>> from paddlenlp import Taskflow
|
||||
|
||||
>>> docprompt = Taskflow("document_intelligence")
|
||||
>>> pprint(docprompt([{"doc": "./resume.png", "prompt": ["五百丁本次想要担任的是什么职位?", "五百丁是在哪里上的大学?", "大学学的是什么专业?"]}]))
|
||||
[{'prompt': '五百丁本次想要担任的是什么职位?',
|
||||
'result': [{'end': 7, 'prob': 1.0, 'start': 4, 'value': '客户经理'}]},
|
||||
{'prompt': '五百丁是在哪里上的大学?',
|
||||
'result': [{'end': 37, 'prob': 1.0, 'start': 31, 'value': '广州五百丁学院'}]},
|
||||
{'prompt': '大学学的是什么专业?',
|
||||
'result': [{'end': 44, 'prob': 0.82, 'start': 38, 'value': '金融学(本科)'}]}]
|
||||
```
|
||||
|
||||
- http图片链接输入
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/40840292/194748592-e20b2a5f-d36b-46fb-8057-86755d188af0.jpg height=400 hspace='10'/>
|
||||
</div>
|
||||
|
||||
```python
|
||||
>>> from pprint import pprint
|
||||
>>> from paddlenlp import Taskflow
|
||||
|
||||
>>> docprompt = Taskflow("document_intelligence")
|
||||
>>> pprint(docprompt([{"doc": "https://bj.bcebos.com/paddlenlp/taskflow/document_intelligence/images/invoice.jpg", "prompt": ["发票号码是多少?", "校验码是多少?"]}]))
|
||||
[{'prompt': '发票号码是多少?',
|
||||
'result': [{'end': 2, 'prob': 0.74, 'start': 2, 'value': 'No44527206'}]},
|
||||
{'prompt': '校验码是多少?',
|
||||
'result': [{'end': 233,
|
||||
'prob': 1.0,
|
||||
'start': 231,
|
||||
'value': '01107 555427109891646'}]}]
|
||||
```
|
||||
|
||||
- 可配置参数说明
|
||||
* `batch_size`:批处理大小,请结合机器情况进行调整,默认为1。
|
||||
* `lang`:选择PaddleOCR的语言,`ch`可在中英混合的图片中使用,`en`在英文图片上的效果更好,默认为`ch`。
|
||||
* `topn`: 如果模型识别出多个结果,将返回前n个概率值最高的结果,默认为1。
|
||||
|
||||
<a name="产业级流程方案"></a>
|
||||
|
||||
### 3.2 产业级流程方案
|
||||
|
||||
针对文档智能领域的痛点和难点,PaddleNLP将持续开源一系列文档智能产业实践范例,解决开发者们实际应用难题。
|
||||
|
||||
- 👉 [汽车说明书跨模态智能问答](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/document_intelligence/doc_vqa#readme)
|
||||
|
||||
更多:百度TextMind智能文档分析平台可提供包括文档信息抽取、文本内容审查、企业文档管理、文档格式解析、文档内容比对等全方位一站式的文档智能服务,已形成一套完整的企业文档场景化解决方案,满足银行、券商、法律、能源、传媒、通信、物流等不同行业和场景的文档处理需求,以AI助力企业的办公智能化升级和数字化转型。欢迎深度交流与商业合作,了解详情:https://ai.baidu.com/tech/nlp/Textanalysis
|
||||
|
||||
## References
|
||||
|
||||
- [文档智能:数据集、模型和应用](http://jcip.cipsc.org.cn/CN/abstract/abstract3331.shtml)
|
||||
|
||||
- [ERNIE-Layout: Layout-Knowledge Enhanced Multi-modal Pre-training for Document Understanding](http://arxiv.org/abs/2210.06155)
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import json
|
||||
import numpy as np
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import os
|
||||
import cv2
|
||||
import sys
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import numpy as np
|
||||
|
||||
import paddle
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import os
|
||||
import sys
|
||||
import copy
|
||||
38
applications/document_intelligence/doc_vqa/Extraction/run_test.sh
Executable file
38
applications/document_intelligence/doc_vqa/Extraction/run_test.sh
Executable file
@@ -0,0 +1,38 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
QUESTION=$1
|
||||
|
||||
python3 change_to_mrc.py ${QUESTION}
|
||||
|
||||
python3 ./run_docvqa.py \
|
||||
--model_name_or_path "layoutxlm-base-uncased" \
|
||||
--max_seq_len 512 \
|
||||
--do_test true \
|
||||
--test_file "data/demo_test.json" \
|
||||
--num_train_epochs 100 \
|
||||
--eval_steps 6000 \
|
||||
--save_steps 6000 \
|
||||
--output_dir "output/" \
|
||||
--save_path "data/decode_res.json" \
|
||||
--init_checkpoint "./checkpoints/layoutxlm/" \
|
||||
--learning_rate 3e-5 \
|
||||
--warmup_steps 12000 \
|
||||
--per_gpu_train_batch_size 4 \
|
||||
--per_gpu_eval_batch_size 1 \
|
||||
--seed 2048
|
||||
|
||||
python3 view.py
|
||||
32
applications/document_intelligence/doc_vqa/Extraction/run_train.sh
Executable file
32
applications/document_intelligence/doc_vqa/Extraction/run_train.sh
Executable file
@@ -0,0 +1,32 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
python3 ./run_docvqa.py \
|
||||
--model_name_or_path "layoutxlm-base-uncased" \
|
||||
--max_seq_len 512 \
|
||||
--train_file "data/train.json" \
|
||||
--init_checkpoint "checkpoints/base_model" \
|
||||
--do_train true \
|
||||
--num_train_epochs 50 \
|
||||
--eval_steps 24000 \
|
||||
--save_steps 40 \
|
||||
--output_dir "output" \
|
||||
--save_path "data/decode_res.json" \
|
||||
--learning_rate 3e-5 \
|
||||
--warmup_steps 40 \
|
||||
--per_gpu_train_batch_size 4 \
|
||||
--per_gpu_eval_batch_size 4 \
|
||||
--seed 2048
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import cv2
|
||||
import json
|
||||
import numpy as np
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import os
|
||||
import json
|
||||
from paddleocr import PaddleOCR
|
||||
@@ -0,0 +1,33 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import json
|
||||
|
||||
question = sys.argv[1]
|
||||
|
||||
with open('../OCR_process/demo_ocr_res.json', 'r', encoding='utf8') as f:
|
||||
paras = []
|
||||
for line in f:
|
||||
line = json.loads(line.strip())
|
||||
document = line['document']
|
||||
para = []
|
||||
for token in document:
|
||||
token = token.replace('▁', '')
|
||||
para.append(token)
|
||||
paras.append(''.join(para))
|
||||
|
||||
with open('./data/demo.tsv', 'w', encoding='utf8') as f:
|
||||
for para in paras:
|
||||
f.write('{}\t\t{}\t0\n'.format(question, para))
|
||||
@@ -1,5 +1,19 @@
|
||||
#!/bin/bash
|
||||
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
QUESTION=$1
|
||||
@@ -1,4 +1,19 @@
|
||||
#!/bin/bash
|
||||
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
if [ $# != 4 ];then
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
import time
|
||||
import faiss
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import sys
|
||||
|
||||
shift = int(sys.argv[1])
|
||||
34
applications/document_intelligence/doc_vqa/run_test.sh
Normal file
34
applications/document_intelligence/doc_vqa/run_test.sh
Normal file
@@ -0,0 +1,34 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
export CUDA_VISIBLE_DEVICES=0
|
||||
|
||||
QUESTION=$1
|
||||
|
||||
# Question: NFC咋开门
|
||||
|
||||
if [ $# != 1 ];then
|
||||
echo "USAGE: sh script/run_cross_encoder_test.sh \$QUESTION"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# compute scores for QUESTION and OCR parsing results with Rerank module
|
||||
cd Rerank
|
||||
bash run_test.sh ${QUESTION}
|
||||
cd ..
|
||||
|
||||
# extraction answer for QUESTION from the top1 of rank
|
||||
cd Extraction
|
||||
bash run_test.sh ${QUESTION}
|
||||
cd ..
|
||||
1
applications/document_intelligence/docprompt
Symbolic link
1
applications/document_intelligence/docprompt
Symbolic link
@@ -0,0 +1 @@
|
||||
../../model_zoo/ernie-layout
|
||||
@@ -3,8 +3,11 @@
|
||||
## 1. 场景概述
|
||||
|
||||
检索系统存在于我们日常使用的很多产品中,比如商品搜索系统、学术文献检索系等等,本方案提供了检索系统完整实现。限定场景是用户通过输入检索词 Query,快速在海量数据中查找相似文档。
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/12107462/191490721-90a8f526-ad64-4f2b-b9b4-34ab06c6749b.png" width="500px">
|
||||
</div>
|
||||
|
||||
所谓语义检索(也称基于向量的检索),是指检索系统不再拘泥于用户 Query 字面本身,而是能精准捕捉到用户 Query 后面的真正意图并以此来搜索,从而更准确地向用户返回最符合的结果。通过使用最先进的语义索引模型找到文本的向量表示,在高维向量空间中对它们进行索引,并度量查询向量与索引文档的相似程度,从而解决了关键词索引带来的缺陷。
|
||||
所谓语义检索(也称基于向量的检索,如上图所示),是指检索系统不再拘泥于用户 Query 字面本身,而是能精准捕捉到用户 Query 后面的真正意图并以此来搜索,从而更准确地向用户返回最符合的结果。通过使用最先进的语义索引模型找到文本的向量表示,在高维向量空间中对它们进行索引,并度量查询向量与索引文档的相似程度,从而解决了关键词索引带来的缺陷。
|
||||
|
||||
例如下面两组文本 Pair,如果基于关键词去计算相似度,两组的相似度是相同的。而从实际语义上看,第一组相似度高于第二组。
|
||||
|
||||
@@ -13,7 +16,7 @@
|
||||
车头如何放置车牌 后牌照怎么装
|
||||
```
|
||||
|
||||
语义检索系统的关键就在于,采用语义而非关键词方式进行召回,达到更精准、更广泛得召回相似结果的目的。
|
||||
语义检索系统的关键就在于,采用语义而非关键词方式进行召回,达到更精准、更广泛得召回相似结果的目的。想快速体验搜索的效果,请参考[Pipelines的实现](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/pipelines)
|
||||
|
||||
## 2. 产品功能介绍
|
||||
|
||||
@@ -33,8 +36,9 @@
|
||||
+ 兼具无监督数据 和 有监督数据:融合模型
|
||||
+ 进一步优化方案: 面向领域的预训练 Domain-adaptive Pretraining
|
||||
+ 性能快
|
||||
+ 基于 Paddle Inference 快速抽取向量
|
||||
+ 基于 Milvus 快速查询和高性能建库
|
||||
+ Paddle Inference 快速抽取向量
|
||||
+ Milvus 快速查询和高性能建库
|
||||
+ Paddle Serving服务化部署
|
||||
|
||||
### 2.2 功能架构
|
||||
|
||||
@@ -43,9 +47,11 @@
|
||||
#### 2.2.1 整体介绍
|
||||
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/12107462/191469309-42a54a67-a3a3-4e43-b6b1-b12be81ddf3d.png" width="800px">
|
||||
</div>
|
||||
|
||||

|
||||
以上是nerual_search的系统流程图,其中左侧为召回环节,核心是语义向量抽取模块;右侧是排序环节,核心是排序模型。图中红色虚线框表示在线计算,黑色虚线框表示离线批量处理。下面我们分别介绍召回中的语义向量抽取模块,以及排序模型。
|
||||
以上是nerual_search的系统流程图,其中左侧为召回环节,核心是语义向量抽取模块;右侧是排序环节,核心是排序模型。召回环节需要用户通过自己的语料构建向量索引库,用户发起query了之后,就可以检索出相似度最高的向量,然后找出该向量对应的文本;排序环节主要是对召回的文本进行重新排序。下面我们分别介绍召回中的语义向量抽取模块,以及排序模型。
|
||||
|
||||
|
||||
#### 2.2.2 召回模块
|
||||
@@ -68,7 +74,9 @@
|
||||
|
||||
#### 2.2.3 排序模块
|
||||
|
||||
排序模块基于前沿的预训练模型 ERNIE-Gram,训练 Pair-wise 语义匹配模型。召回模型负责从海量(千万级)候选文本中快速(毫秒级)筛选出与 Query 相关性较高的 TopK Doc,排序模型会在召回模型筛选出的 TopK Doc 结果基础之上针对每一个 (Query, Doc) Pair 对进行两两匹配计算相关性,排序效果更精准。
|
||||
召回模型负责从海量(千万级)候选文本中快速(毫秒级)筛选出与 Query 相关性较高的 TopK Doc,排序模型会在召回模型筛选出的 TopK Doc 结果基础之上针对每一个 (Query, Doc) Pair 对进行两两匹配计算相关性,排序效果更精准。
|
||||
|
||||
排序模块有2种选择,第一种基于前沿的预训练模型 ERNIE,训练 Pair-wise 语义匹配模型;第二种是基于RocketQA模型训练的Cross Encoder模形。第一种是Pair-wise的排序算法,基本思路是对样本构建偏序文档对,两两比较,从比较中学习顺序,第二种是Poinet-Wise的算法,只考虑当前Query和每个文档的绝对相关度,并没有考虑其他文档与Query的相关度,但是建模方式比较简单。第一种Pair-wise模型可以说是第二种point-wise模型的改进版本,但对于噪声数据更为敏感,即一个错误的标注会导致多个pair对的错误,用户可以先使用基于Point-wise的Cross Encoder构建一个基础模型,需要进一步优化可以使用Pair-wise的方法优化。
|
||||
|
||||
## 3. 文献检索实践
|
||||
|
||||
@@ -78,9 +86,9 @@
|
||||
|
||||
**语义索引**:由于我们既有无监督数据,又有有监督数据,所以结合 SimCSE 和 In-batch Negatives 方案,并采取 Domain-adaptive Pretraining 优化模型效果。
|
||||
|
||||
首先是利用 ERNIE 1.0 模型进行 Domain-adaptive Pretraining,在得到的预训练模型基础上,进行无监督的 SimCSE 训练,最后利用 In-batch Negatives 方法进行微调,得到最终的语义索引模型,把建库的文本放入模型中抽取特征向量,然后把抽取后的向量放到语义索引引擎 milvus 中,利用 milvus 就可以很方便得实现召回了。
|
||||
首先是利用 ERNIE模型进行 Domain-adaptive Pretraining,在得到的预训练模型基础上,进行无监督的 SimCSE 训练,最后利用 In-batch Negatives 方法进行微调,得到最终的语义索引模型,把建库的文本放入模型中抽取特征向量,然后把抽取后的向量放到语义索引引擎 milvus 中,利用 milvus 就可以很方便得实现召回了。
|
||||
|
||||
**排序**:使用 ERNIE-Gram 的单塔结构对召回后的数据精排序。
|
||||
**排序**:使用 ERNIE-Gram 的单塔结构/RocketQA的Cross Encoder对召回后的数据精排序。
|
||||
|
||||
#### 3.1.2 评估指标
|
||||
|
||||
@@ -94,7 +102,7 @@
|
||||
|
||||
* 建库性能和 ANN 查询性能快
|
||||
|
||||
### 3.2 数据说明
|
||||
### 3.2 预置数据说明
|
||||
|
||||
数据集来源于某文献检索系统,既有大量无监督数据,又有有监督数据。
|
||||
|
||||
@@ -104,18 +112,19 @@
|
||||
|
||||
(3)使用文献的的query, title, keywords,构造带正标签的数据集,不包含负标签样本,基于 In-batch Negatives 策略进行训练;
|
||||
|
||||
(4)在排序阶段,使用点击(作为正样本)和展现未点击(作为负样本)数据构造排序阶段的训练集,使用ERNIE-Gram模型进行精排训练。
|
||||
(4)在排序阶段,使用点击(作为正样本)和展现未点击(作为负样本)数据构造排序阶段的训练集,进行精排训练。
|
||||
|
||||
| 阶段 |模型 | 训练集 | 评估集(用于评估模型效果) | 召回库 |测试集 |
|
||||
| ------------ | ------------ |------------ | ------------ | ------------ | ------------ |
|
||||
| 召回 | Domain-adaptive Pretraining | 2kw | - | - | - |
|
||||
| 召回 | 无监督预训练 - SimCSE | 798w | 20000 | 300000| 1000 |
|
||||
| 召回 | 有监督训练 - In-batch Negatives | 3998 | 20000 |300000 | 1000 |
|
||||
| 排序 | 有监督训练 - ERNIE-Gram单塔 Pairwise| 1973538 | 57811 | - | 1000 |
|
||||
| 排序 | 有监督训练 - ERNIE-Gram单塔 Pairwise/RocketQA Cross Encoder| 1973538 | 57811 | - | 1000 |
|
||||
|
||||
我们将除 Domain-adaptive Pretraining 之外的其他数据集全部开源,下载地址:
|
||||
|
||||
- [literature_search_data](https://bj.bcebos.com/v1/paddlenlp/data/literature_search_data.zip)
|
||||
- [literature_search_rank](https://paddlenlp.bj.bcebos.com/applications/literature_search_rank.zip)
|
||||
|
||||
```
|
||||
├── milvus # milvus建库数据集
|
||||
@@ -126,13 +135,147 @@
|
||||
├── dev.csv # 召回阶段验证集,用于评估召回模型的效果,SimCSE 和 In-batch Negative 共用
|
||||
├── corpus.csv # 构建召回库的数据(模拟实际业务线上的语料库,实际语料库远大于这里的规模),用于评估召回阶段模型效果,SimCSE 和 In-batch Negative 共用
|
||||
├── test.csv # 召回阶段测试数据,预测文本之间的相似度,SimCSE 和 In-batch Negative 共用
|
||||
├── data # RocketQA排序数据集
|
||||
├── test.csv # 测试集
|
||||
├── dev_pairwise.csv # 验证集
|
||||
└── train.csv # 训练集
|
||||
├── sort # 排序阶段数据集
|
||||
├── train_pairwise.csv # 排序训练集
|
||||
├── dev_pairwise.csv # 排序验证集
|
||||
└── test_pairwise.csv # 排序测试集
|
||||
```
|
||||
|
||||
### 3.3 运行环境和安装说明
|
||||
|
||||
### 3.3 数据格式
|
||||
|
||||
1. 对于无监督SimCSE的训练方法,格式参考`train_unsupervised.csv`,即一行条文本即可,无需任何标注。对于召回模型训练需要规定格式的本地数据集,需要准备训练集文件`train.csv`,验证集`dev.csv`,召回集文件`corpus.csv`。
|
||||
|
||||
|
||||
训练数据集`train.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t 用户点击的title1
|
||||
query2 \t 用户点击的title2
|
||||
```
|
||||
训练集合`train.csv`的文件样例:
|
||||
```
|
||||
从《唐律疏义》看唐代封爵贵族的法律特权 从《唐律疏义》看唐代封爵贵族的法律特权《唐律疏义》,封爵贵族,法律特权
|
||||
宁夏社区图书馆服务体系布局现状分析 宁夏社区图书馆服务体系布局现状分析社区图书馆,社区图书馆服务,社区图书馆服务体系
|
||||
人口老龄化对京津冀经济 京津冀人口老龄化对区域经济增长的影响京津冀,人口老龄化,区域经济增长,固定效应模型
|
||||
英语广告中的模糊语 模糊语在英语广告中的应用及其功能模糊语,英语广告,表现形式,语用功能
|
||||
甘氨酸二肽的合成 甘氨酸二肽合成中缩合剂的选择甘氨酸,缩合剂,二肽
|
||||
......
|
||||
```
|
||||
|
||||
验证集`dev.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t 用户点击的title1
|
||||
query2 \t 用户点击的title2
|
||||
```
|
||||
|
||||
验证集合`train.csv`的文件样例:
|
||||
```
|
||||
试论我国海岸带经济开发的问题与前景 试论我国海岸带经济开发的问题与前景海岸带,经济开发,问题,前景
|
||||
外语阅读焦虑与英语成绩及性别的关系 外语阅读焦虑与英语成绩及性别的关系外语阅读焦虑,外语课堂焦虑,英语成绩,性别
|
||||
加油站风险分级管控 加油站工作危害风险分级研究加油站,工作危害分析(JHA),风险分级管控
|
||||
```
|
||||
召回集合`corpus.csv`主要作用是检验测试集合的句子对能否被正确召回,它的构造主要是提取验证集的第二列的句子,然后加入很多无关的句子,用来检验模型能够正确的从这些文本中找出测试集合对应的第二列的句子,格式如下:
|
||||
|
||||
```
|
||||
2002-2017年我国法定传染病发病率和死亡率时间变化趋势传染病,发病率,死亡率,病死率
|
||||
陕西省贫困地区城乡青春期少女生长发育调查青春期,生长发育,贫困地区
|
||||
五丈岩水库溢洪道加固工程中的新材料应用碳纤维布,粘钢加固技术,超细水泥,灌浆技术
|
||||
......
|
||||
```
|
||||
|
||||
2. 对于排序模型的训练,排序模型目前提供了2种,第一种是Pairwise训练的方式,第二种是RocketQA的排序模型,对于第一种排序模型,需要准备训练集`train_pairwise.csv`,验证集`dev_pairwise.csv`两个文件,除此之外还可以准备测试集文件`test.csv`或者`test_pairwise.csv`。
|
||||
|
||||
训练数据集`train_pairwise.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t 用户点击的title1 \t 用户未点击的title2
|
||||
query2 \t 用户点击的title3 \t 用户未点击的title4
|
||||
```
|
||||
|
||||
训练数据集`train_pairwise.csv`的示例如下:
|
||||
|
||||
```
|
||||
英语委婉语引起的跨文化交际障碍 英语委婉语引起的跨文化交际障碍及其翻译策略研究英语委婉语,跨文化交际障碍,翻译策略 委婉语在英语和汉语中的文化差异委婉语,文化,跨文化交际
|
||||
范迪慧 嘉兴市中医院 滋阴疏肝汤联合八穴隔姜灸治疗肾虚肝郁型卵巢功能低下的临床疗效滋阴疏肝汤,八穴隔姜灸,肾虚肝郁型卵巢功能低下,性脉甾类激素,妊娠 温针灸、中药薰蒸在半月板损伤术后康复中的疗效分析膝损伤,半月板,胫骨,中医康复,温针疗法,薰洗
|
||||
......
|
||||
```
|
||||
|
||||
验证数据集`dev_pairwise.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t title1 \t label
|
||||
query2 \t title2 \t label
|
||||
```
|
||||
验证数据集`dev_pairwise.csv`的示例如下:
|
||||
|
||||
```
|
||||
作者单位:南州中学 浅谈初中教学管理如何体现人文关怀初中教育,教学管理,人文关怀 1
|
||||
作者单位:南州中学 高中美术课堂教学中藏区本土民间艺术的融入路径藏区,传统民间艺术,美术课堂 0
|
||||
作者单位:南州中学 列宁关于资产阶级民主革命向 社会主义革命过渡的理论列宁,直接过渡,间接过渡,资产阶级民主革命,社会主义革命 0
|
||||
DAA髋关节置换 DAA前侧入路和后外侧入路髋关节置换疗效对比髋关节置换术;直接前侧入路;后外侧入路;髋关节功能;疼痛;并发症 1
|
||||
DAA髋关节置换 DAA全髋关节置换术治疗髋关节病变对患者髋关节运动功能的影响直接前侧入路全髋关节置换术,髋关节病变,髋关节运动功能 0
|
||||
DAA髋关节置换 护患沟通技巧在急诊输液护理中的应用分析急诊科,输液护理,护理沟通技巧,应用 0
|
||||
.......
|
||||
```
|
||||
训练数据集`test_pairwise.csv`的格式如下,其中这个score得分是召回算出来的相似度或者距离,仅供参考,可以忽略:
|
||||
|
||||
```
|
||||
query1 \t title1 \t score
|
||||
query2 \t title2 \t score
|
||||
```
|
||||
训练数据集`test_pairwise.csv`的示例如下:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异 中西方文化差异以及语言体现中西方文化,差异,语言体现 0.43203747272491455
|
||||
中西方语言与文化的差异 论中西方文化差异在非言语交际中的体现中西方文化,差异,非言语交际 0.4644506871700287
|
||||
中西方语言与文化的差异 中西方体态语文化差异跨文化,体态语,非语言交际,差异 0.4917311668395996
|
||||
中西方语言与文化的差异 由此便可以发现两种语言以及两种文化的差异。 0.5039259195327759
|
||||
.......
|
||||
```
|
||||
|
||||
对于第二种基于RocketQA的排序模型。
|
||||
|
||||
训练数据集`train.csv`,验证集`dev_pairwise.csv`的格式如下:
|
||||
|
||||
```
|
||||
query1 \t title1 \t label
|
||||
query2 \t title2 \t label
|
||||
```
|
||||
训练数据集`train.csv`,验证集`dev_pairwise.csv`的示例如下:
|
||||
|
||||
```
|
||||
(小学数学教材比较) 关键词:新加坡 新加坡与中国数学教材的特色比较数学教材,教材比较,问题解决 0
|
||||
徐慧新疆肿瘤医院 头颈部非霍奇金淋巴瘤扩散加权成像ADC值与Ki-67表达相关性分析淋巴瘤,非霍奇金,头颈部肿瘤,磁共振成像 1
|
||||
抗生素关性腹泻 鼠李糖乳杆菌GG防治消化系统疾病的研究进展鼠李糖乳杆菌,腹泻,功能性胃肠病,肝脏疾病,幽门螺杆菌 0
|
||||
德州市图书馆 图书馆智慧化建设与融合创新服务研究图书馆;智慧化;阅读服务;融合创新 1
|
||||
维生素c 综述 维生素C防治2型糖尿病研究进展维生素C;2型糖尿病;氧化应激;自由基;抗氧化剂 0
|
||||
.......
|
||||
```
|
||||
|
||||
训练数据集`test.csv`的格式如下,其中这个score得分是召回算出来的相似度或者距离,仅供参考,可以忽略:
|
||||
|
||||
```
|
||||
query1 \t title1 \t score
|
||||
query2 \t title2 \t score
|
||||
```
|
||||
训练数据集`test.csv`的示例如下:
|
||||
|
||||
```
|
||||
加强科研项目管理有效促进医学科研工作 科研项目管理策略科研项目,项目管理,实施,必要性,策略 0.32163668
|
||||
加强科研项目管理有效促进医学科研工作 关于推进我院科研发展进程的相关问题研究医院科研,主体,环境,信息化 0.32922596
|
||||
加强科研项目管理有效促进医学科研工作 深圳科技计划对高校科研项目资助现状分析与思考基础研究,高校,科技计划,科技创新 0.36869502
|
||||
加强科研项目管理有效促进医学科研工作 普通高校科研管理模式的优化与创新普通高校,科研,科研管理 0.3688045
|
||||
.......
|
||||
```
|
||||
|
||||
|
||||
### 3.4 运行环境和安装说明
|
||||
|
||||
|
||||
(1)运行环境
|
||||
@@ -163,14 +306,91 @@ c. 依赖安装:
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 4. 动手实践——搭建自己的检索系统
|
||||
## 4. Neural Search 快速体验实践
|
||||
|
||||
PaddleNLP已经基于ERNIE 1.0训练了一个基线模型,如果想快速搭建Neural Search的完整系统。
|
||||
|
||||
### 4.1. 召回
|
||||
|
||||
- 召回向量抽取服务的搭建请参考:[In-batch Negatives](./recall/in_batch_negative/), 只需要下载基于ERNIE 1.0的预训练模型,导出成Paddle Serving的格式,然后启动Pipeline Server服务即可
|
||||
|
||||
- 召回向量检索服务的搭建请参考:[Milvus](./recall/milvus/), 需要搭建Milvus并且插入检索数据的向量
|
||||
|
||||
【注意】如果使用Neural Search训练好的模型,由于该模型是基于ERNIE 1.0训练的,所以需要把 `model_name_or_path`指定为`ernie 1.0`,向量抽取结果才能正常。
|
||||
|
||||
|
||||
### 4.2. 排序
|
||||
|
||||
排序服务的搭建请参考 [ernie_matching](./ranking/ernie_matching/),只需要下载基于ERNIE Gram的预训练模型,导出成Paddle Serving的格式,最后需要启动 Pipeline Serving服务
|
||||
|
||||
【注意】如果使用Neural Search训练好的模型,由于该模型是基于ERNIE Gram训练的,所以需要把 `model_name_or_path`指定为`ernie-gram-zh`,向量抽取结果才能正常。
|
||||
|
||||
### 4.3. 系统运行
|
||||
|
||||
以上召回和排序模型都经过Paddle Serving服务化以后,就可以直接使用下面的命令运行体验:
|
||||
|
||||
```
|
||||
python3 run_system.py
|
||||
```
|
||||
输出的结果为:
|
||||
|
||||
```
|
||||
PipelineClient::predict pack_data time:1656991375.5521955
|
||||
PipelineClient::predict before time:1656991375.5529568
|
||||
Extract feature time to cost :0.0161135196685791 seconds
|
||||
Search milvus time cost is 0.8139839172363281 seconds
|
||||
PipelineClient::predict pack_data time:1656991376.3981335
|
||||
PipelineClient::predict before time:1656991376.3983877
|
||||
time to cost :0.05616641044616699 seconds
|
||||
```
|
||||
会输出2个文件 `recall_result.csv` 是召回检索的结果,`rank_result.csv` 是排序的结果。csv的示例输出下。
|
||||
|
||||
召回的结果:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异,港台文化对内地中小学生的负面影响,0.055068351328372955
|
||||
中西方语言与文化的差异,外来文化在越南的传播与融合,0.05621318891644478
|
||||
中西方语言与文化的差异,临终关怀中的“仪式”,0.05705389380455017
|
||||
中西方语言与文化的差异,历史的真实与艺术加工,0.05745899677276611
|
||||
......
|
||||
```
|
||||
|
||||
排序的结果:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异,论中西方教育差异,0.870943009853363
|
||||
中西方语言与文化的差异,浅析中西方问候语的差异,0.8468159437179565
|
||||
中西方语言与文化的差异,文化认同及其根源,0.8288694620132446
|
||||
中西方语言与文化的差异,从历史文化角度分析中西方学校教育的差异,0.8209370970726013
|
||||
中西方语言与文化的差异,中西医思维方式的差异,0.8150948882102966
|
||||
中西方语言与文化的差异,浅析中韩餐桌文化差异,0.7751647233963013
|
||||
......
|
||||
```
|
||||
|
||||
|
||||
|
||||
## 5. 从头开始搭建自己的检索系统
|
||||
|
||||
这里展示了能够从头至尾跑通的完整代码,您使用自己的业务数据,照着跑,能搭建出一个给定 Query,返回 topK 相关文档的小型检索系统。您可以参照我们给出的效果和性能数据来检查自己的运行过程是否正确。
|
||||
|
||||
### 4.1 召回阶段
|
||||
### 5.1 召回阶段
|
||||
|
||||
**召回模型训练**
|
||||
|
||||
我们进行了多组实践,用来对比说明召回阶段各方案的效果:
|
||||
|
||||
| 模型 | Recall@1 | Recall@5 |Recall@10 |Recall@20 |Recall@50 |策略简要说明|
|
||||
| ------------ | ------------ | ------------ |--------- |--------- |--------- |--------- |
|
||||
| 有监督训练 Baseline | 30.077| 43.513| 48.633 | 53.448 |59.632| 标准 pair-wise 训练范式,通过随机采样产生负样本|
|
||||
| 有监督训练 In-batch Negatives | 51.301 | 65.309| 69.878| 73.996|78.881| In-batch Negatives 有监督训练|
|
||||
| 无监督训练 SimCSE | 42.374 | 57.505| 62.641| 67.09|72.331| SimCSE 无监督训练|
|
||||
| 无监督 + 有监督训练 SimCSE + In-batch Negatives | 55.976 | 71.849| 76.363| 80.49|84.809| SimCSE无监督训练,In-batch Negatives 有监督训练|
|
||||
| Domain-adaptive Pretraining + SimCSE | 51.031 | 66.648| 71.338 | 75.676 |80.144| ERNIE 预训练,SimCSE 无监督训练|
|
||||
| Domain-adaptive Pretraining + SimCSE + In-batch Negatives| **58.248** | **75.099**| **79.813**| **83.801**|**87.733**| ERNIE 预训练,SimCSE 无监督训训练,In-batch Negatives 有监督训练|
|
||||
|
||||
从上述表格可以看出,首先利用 ERNIE 3.0 做 Domain-adaptive Pretraining ,然后把训练好的模型加载到 SimCSE 上进行无监督训练,最后利用 In-batch Negatives 在有监督数据上进行训练能够获得最佳的性能。[模型下载](https://paddlenlp.bj.bcebos.com/models/inbatch_model_best.zip),模型的使用方式参考[In-batch Negatives](./recall/in_batch_negative/) 。
|
||||
|
||||
|
||||
这里采用 Domain-adaptive Pretraining + SimCSE + In-batch Negatives 方案:
|
||||
|
||||
第一步:无监督训练 Domain-adaptive Pretraining
|
||||
@@ -186,19 +406,6 @@ pip install -r requirements.txt
|
||||
几分钟内训练完成,可参考 [In-batch Negatives](./recall/in_batch_negative/)
|
||||
|
||||
|
||||
此外,我们进行了多组实践,用来对比说明召回阶段各方案的效果:
|
||||
|
||||
| 模型 | Recall@1 | Recall@5 |Recall@10 |Recall@20 |Recall@50 |策略简要说明|
|
||||
| ------------ | ------------ | ------------ |--------- |--------- |--------- |--------- |
|
||||
| 有监督训练 Baseline | 30.077| 43.513| 48.633 | 53.448 |59.632| 标准 pair-wise 训练范式,通过随机采样产生负样本|
|
||||
| 有监督训练 In-batch Negatives | 51.301 | 65.309| 69.878| 73.996|78.881| In-batch Negatives 有监督训练|
|
||||
| 无监督训练 SimCSE | 42.374 | 57.505| 62.641| 67.09|72.331| SimCSE 无监督训练|
|
||||
| 无监督 + 有监督训练 SimCSE + In-batch Negatives | 55.976 | 71.849| 76.363| 80.49|84.809| SimCSE无监督训练,In-batch Negatives 有监督训练|
|
||||
| Domain-adaptive Pretraining + SimCSE | 51.031 | 66.648| 71.338 | 75.676 |80.144| ERNIE 预训练,SimCSE 无监督训练|
|
||||
| Domain-adaptive Pretraining + SimCSE + In-batch Negatives| **58.248** | **75.099**| **79.813**| **83.801**|**87.733**| ERNIE 预训练,SimCSE 无监督训训练,In-batch Negatives 有监督训练|
|
||||
|
||||
从上述表格可以看出,首先利用 ERNIE 3.0 做 Domain-adaptive Pretraining ,然后把训练好的模型加载到 SimCSE 上进行无监督训练,最后利用 In-batch Negatives 在有监督数据上进行训练能够获得最佳的性能。[模型下载](https://paddlenlp.bj.bcebos.com/models/inbatch_model_best.zip),模型的使用方式参考[In-batch Negatives](./recall/in_batch_negative/) 。
|
||||
|
||||
**召回系统搭建**
|
||||
|
||||
召回系统使用索引引擎 Milvus,可参考 [milvus_system](./recall/milvus/)。
|
||||
@@ -233,18 +440,19 @@ pip install -r requirements.txt
|
||||
```
|
||||
|
||||
|
||||
### 4.2 排序阶段
|
||||
### 5.2 排序阶段
|
||||
|
||||
排序阶段使用的模型是 ERNIE-3.0-Medium-zh,用时 20h,可参考:
|
||||
排序阶段有2种方案,第一种是[ernie_matching](./ranking/ernie_matching/)使用的模型是 ERNIE-3.0-Medium-zh,用时 20h;第二种是基于RocketQA的排序模型[cross_encoder](./ranking/cross_encoder/),训练用时也是20h左右。
|
||||
|
||||
[ernie_matching](./ranking/ernie_matching/)
|
||||
|
||||
排序阶段的效果评估:
|
||||
|
||||
| 模型 | AUC |
|
||||
| ------------ | ------------ |
|
||||
| Baseline: In-batch Negatives | 0.582 |
|
||||
| ERNIE-Gram | 0.801 |
|
||||
| pairwise ERNIE-Gram |0.801 |
|
||||
| CrossEncoder:rocketqa-base-cross-encoder |**0.835** |
|
||||
|
||||
|
||||
同样输入文本:
|
||||
|
||||
|
||||
@@ -24,7 +24,6 @@ from tqdm import tqdm
|
||||
from paddlenlp.transformers import AutoTokenizer, AutoModel, AutoModelForSequenceClassification
|
||||
|
||||
from data import convert_example, read_text_pair, create_dataloader
|
||||
from model import CrossEncoder
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
|
||||
@@ -204,9 +204,8 @@ python -u -m paddle.distributed.launch --gpus "0,1,2,3" \
|
||||
--hnsw_m 100 \
|
||||
--hnsw_ef 100 \
|
||||
--recall_num 50 \
|
||||
--similar_text_pair "recall/dev.csv" \
|
||||
--corpus_file "recall/corpus.csv" \
|
||||
--similar_text_pair "recall/dev.csv"
|
||||
--similar_text_pair_file "recall/dev.csv" \
|
||||
--corpus_file "recall/corpus.csv"
|
||||
```
|
||||
|
||||
参数含义说明
|
||||
@@ -228,9 +227,8 @@ python -u -m paddle.distributed.launch --gpus "0,1,2,3" \
|
||||
* `hnsw_m`: hnsw 算法相关参数,保持默认即可
|
||||
* `hnsw_ef`: hnsw 算法相关参数,保持默认即可
|
||||
* `recall_num`: 对 1 个文本召回的相似文本数量
|
||||
* `similar_text_pair`: 由相似文本对构成的评估集
|
||||
* `similar_text_pair_file`: 由相似文本对构成的评估集
|
||||
* `corpus_file`: 召回库数据 corpus_file
|
||||
* `similar_text_pair`: 由相似文本对构成的评估集 semantic_similar_pair.tsv
|
||||
|
||||
也可以使用bash脚本:
|
||||
|
||||
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import os
|
||||
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import os
|
||||
@@ -66,8 +80,10 @@ if __name__ == "__main__":
|
||||
max_seq_length=max_seq_length)
|
||||
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id), # text_input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id), # text_segment
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_id, dtype="int64"
|
||||
), # text_input
|
||||
Pad(axis=0, pad_val=tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # text_segment
|
||||
): [data for data in fn(samples)]
|
||||
|
||||
pretrained_model = AutoModel.from_pretrained(model_name_or_path)
|
||||
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import os
|
||||
@@ -5,7 +19,7 @@ import sys
|
||||
import random
|
||||
import time
|
||||
|
||||
sys.path.append('../recall/milvus')
|
||||
sys.path.append('./recall/milvus')
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
from tqdm import tqdm
|
||||
@@ -1,74 +0,0 @@
|
||||
**目录**
|
||||
|
||||
* [介绍](#背景介绍)
|
||||
* [检索系统](#检索系统)
|
||||
* [1. 召回](#召回服务)
|
||||
* [2. 排序](#排序服务)
|
||||
* [3. 系统运行](#系统运行)
|
||||
|
||||
|
||||
<a name="背景介绍"></a>
|
||||
|
||||
# 介绍
|
||||
|
||||
使用召回模型和排序模型搭建一个完整的搜索流程
|
||||
|
||||
|
||||
# 检索系统
|
||||
|
||||
<a name="召回服务"></a>
|
||||
|
||||
## 1. 召回
|
||||
|
||||
- 召回向量抽取服务的搭建请参考:[In-batch Negatives](../recall/in_batch_negative/), 需要启动Pipeline Server服务
|
||||
|
||||
- 召回向量检索服务的搭建请参考:[Milvus](../recall/milvus/), 需要搭建Milvus并且插入检索数据的向量
|
||||
|
||||
<a name="排序服务"></a>
|
||||
|
||||
## 2. 排序
|
||||
|
||||
排序服务的搭建请参考 [ernie_matching](../ranking/ernie_matching/),同样的需要启动 Pipeline Serving服务
|
||||
|
||||
|
||||
<a name="系统运行"></a>
|
||||
|
||||
## 3. 系统运行
|
||||
|
||||
```
|
||||
python3 run_system.py
|
||||
```
|
||||
输出的结果为:
|
||||
|
||||
```
|
||||
PipelineClient::predict pack_data time:1656991375.5521955
|
||||
PipelineClient::predict before time:1656991375.5529568
|
||||
Extract feature time to cost :0.0161135196685791 seconds
|
||||
Search milvus time cost is 0.8139839172363281 seconds
|
||||
PipelineClient::predict pack_data time:1656991376.3981335
|
||||
PipelineClient::predict before time:1656991376.3983877
|
||||
time to cost :0.05616641044616699 seconds
|
||||
```
|
||||
会输出2个文件 `recall_result.csv` 是召回检索的结果,`rank_result.csv` 是排序的结果。csv的示例输出下。
|
||||
|
||||
召回的结果:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异,港台文化对内地中小学生的负面影响,0.055068351328372955
|
||||
中西方语言与文化的差异,外来文化在越南的传播与融合,0.05621318891644478
|
||||
中西方语言与文化的差异,临终关怀中的“仪式”,0.05705389380455017
|
||||
中西方语言与文化的差异,历史的真实与艺术加工,0.05745899677276611
|
||||
......
|
||||
```
|
||||
|
||||
排序的结果:
|
||||
|
||||
```
|
||||
中西方语言与文化的差异,论中西方教育差异,0.870943009853363
|
||||
中西方语言与文化的差异,浅析中西方问候语的差异,0.8468159437179565
|
||||
中西方语言与文化的差异,文化认同及其根源,0.8288694620132446
|
||||
中西方语言与文化的差异,从历史文化角度分析中西方学校教育的差异,0.8209370970726013
|
||||
中西方语言与文化的差异,中西医思维方式的差异,0.8150948882102966
|
||||
中西方语言与文化的差异,浅析中韩餐桌文化差异,0.7751647233963013
|
||||
......
|
||||
```
|
||||
@@ -2,18 +2,23 @@
|
||||
|
||||
**目录**
|
||||
|
||||
* [1. 场景概述](#场景概述)
|
||||
* [1. 项目介绍](#项目介绍)
|
||||
* [2. 系统特色](#系统特色)
|
||||
* [3. 保险智能问答系统方案](#保险问答系统方案)
|
||||
* [4. 动手实践——搭建自己的端到端检索式问答系统](#动手实践——搭建自己的端到端检索式问答系统)
|
||||
* [5. 模型优化](#模型优化)
|
||||
* [6. 参考文献](#参考文献)
|
||||
|
||||
<a name="项目介绍"></a>
|
||||
|
||||
<a name="场景概述"></a>
|
||||
|
||||
## 1. 场景概述
|
||||
## 1. 项目介绍
|
||||
|
||||
智能问答是获取信息和知识的更直接、更高效的方式之一,传统的信息检索方法智能找到相关的文档,而智能问答能够直接找到精准的答案,极大的节省了人们查询信息的时间。问答按照技术分为基于阅读理解的问答和检索式的问答,阅读理解的问答是在正文中找到对应的答案片段,检索式问答则是匹配高频的问题,然后把答案返回给用户。本项目属于检索式的问答,问答的领域用途很广,比如搜索引擎,小度音响等智能硬件,政府,金融,银行,电信,电商领域的智能客服,聊天机器人等。
|
||||
|
||||
- 本方案是场景的定制化的方案,用户可以使用自己的数据训练一个特定场景的方案。另外,想快速体验FAQ智能问答系统请参考Pipelines的实现[FAQ智能问答](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/pipelines/examples/FAQ)
|
||||
|
||||
- 本项目的详细教程请参考(包括数据和代码实现)[aistudio教程](https://aistudio.baidu.com/aistudio/projectdetail/3882519)
|
||||
|
||||
<a name="系统特色"></a>
|
||||
|
||||
## 2. 系统特色
|
||||
@@ -44,9 +49,10 @@
|
||||
|
||||
* 该保险智能问答系统使用的指标是 Recall@K,表示的是预测的前topK(从最后的按得分排序的召回列表中返回前K个结果)结果和语料库中真实的前 K 个相关结果的重叠率,衡量的是检索系统的查全率。
|
||||
|
||||
|
||||
### 3.2 数据说明
|
||||
|
||||
#### 3.2.1 预置数据介绍
|
||||
|
||||
数据集来源于Github开源的保险的问答数据,包括源用户的问题和相应的回复。
|
||||
|
||||
| 阶段 |模型 | 训练集 | 评估集(用于评估模型效果) | 召回库 |
|
||||
@@ -57,6 +63,7 @@
|
||||
|
||||
评估集的问题对的构造使用了中英文回译的方法,数据使用的是百度翻译的API,详情请参考[百度翻译](https://fanyi-api.baidu.com/?fr=simultaneous)
|
||||
|
||||
【注意】:数据集是基于Github开源数据进行了处理得到的,如果有任何侵权问题,请及时联系,我们会第一时间进行删除。
|
||||
|
||||
```
|
||||
├── data # 数据集
|
||||
@@ -68,6 +75,89 @@
|
||||
```
|
||||
数据集的下载链接为: [faq_finance](https://github.com/SophonPlus/ChineseNlpCorpus/blob/master/datasets/baoxianzhidao/intro.ipynb)
|
||||
|
||||
#### 3.2.2 数据格式
|
||||
|
||||
训练需要规定格式的本地数据集,需要准备训练集文件`train.csv`或者`train_aug.csv`,测试集`test_pair.csv`,召回集文件`corpus.csv`,问答对 `qa_pair.csv`。
|
||||
|
||||
用于无监督训练的训练集的格式如下:
|
||||
|
||||
```
|
||||
文本1
|
||||
文本2
|
||||
...
|
||||
```
|
||||
训练集合`train.csv`的文件样例:
|
||||
|
||||
```
|
||||
家里有社保,还有必要买重疾险吗?
|
||||
工地买了建工险,出了事故多长时间上报保险公司有效
|
||||
请问下哆啦a保值不值得买呢?不晓得保障多不多
|
||||
自由职业办理养老保险是否划算
|
||||
工伤七级如果公司不干了,怎么赔我
|
||||
普通意外险的保障范围都有哪些?
|
||||
......
|
||||
```
|
||||
除此之外,也可以使用数据增强的格式,训练方式是类似有监督的构造句子对。数据增强的文件格式如下:
|
||||
|
||||
```
|
||||
文本1 \t 增强文本1
|
||||
文本2 \t 增强文本2
|
||||
```
|
||||
增强数据集`train_aug.csv`的格式如下:
|
||||
|
||||
```
|
||||
工伤七级如果公司不干了,怎么赔我 工伤七级如果企业不干了,怎生赔我
|
||||
普通意外险的保障范围都有哪些? 一般性意外险的保障范围都有哪些?
|
||||
重疾险赔付三次和赔付一次的区别 重疾险赔偿三次和赔偿一次的区别
|
||||
。。。。。
|
||||
```
|
||||
|
||||
测试集合`test_pair.csv`是问句对,具体格式如下:
|
||||
|
||||
```
|
||||
句子1 \t 句子2
|
||||
句子3 \t 句子4
|
||||
```
|
||||
其中句子1和句子2是相似的句子,只是表达方式不同,或者进行了一定程度的变形,但实际表达的语义是一样的。
|
||||
|
||||
测试集的文件样例:
|
||||
|
||||
```
|
||||
车险如何计算 如何计算汽车保险
|
||||
农民买养老保险怎么买 农民如何购买养老保险
|
||||
车险必买哪几项 你必须购买哪些汽车保险
|
||||
...
|
||||
```
|
||||
召回集合`corpus.csv`主要作用是检验测试集合的句子对能否被正确召回,它的构造主要是提取测试集的第二列的句子,然后加入很多无关的句子,用来检验模型能够正确的从这些文本中找出测试集合对应的第二列的句子,格式如下:
|
||||
|
||||
```
|
||||
如何办理企业养老保险
|
||||
如何为西班牙购买签证保险?
|
||||
康慧宝需要买多少?
|
||||
如果另一方对车辆事故负有全部责任,并且拒绝提前支付维修费,该怎么办
|
||||
准备清明节去新兴坡旅游,什么样的旅游保险好?
|
||||
你能从国外账户购买互助基金吗?
|
||||
什么是海上保险?有哪些海上保险?
|
||||
....
|
||||
```
|
||||
|
||||
问答对集合`qa_pair.csv`包含的是整个项目的问题和对应的答案,,具体格式如下:
|
||||
|
||||
```
|
||||
问题1 \t 答案1
|
||||
问题2 \t 答案2
|
||||
......
|
||||
```
|
||||
问答对集合示例:
|
||||
|
||||
```
|
||||
既然强制运输保险有浮动费率制度,有商业保险吗? 商业车险也有的。关于汽车商业险的费率在全国每个省都是不一样的,在同一地区,费率也会变化。一般1年、2-4年、4-6年、费率都不同。新车第一年的费率会比较高,2-4是相对比较优惠,4-6会再上涨,不同类型的汽车费率也不同。商业车险保费浮动比例与其他公司相比都是差不多的,一般销售保费浮动比例是这样的:上年赔款1次,保费打7折;上年赔款2次,保费打8折;上年赔款3次,保费上浮15%;上年赔款4次,保费上浮51%;上年赔款5次以上,保费上浮69%。该公司的有关人士表示,如果上年赔款次数超过了7次,续保时可能会遭拒。目前的研究意见规定中加大了车险保费与赔款记录相关系数的浮动区间,并与交通违章情况挂钩,若车主少违章少出险则保费最多可打5折,反之则保费最高可上浮至现行标准的4.5倍。
|
||||
汇鑫安儿童保险的保费是否也与性别有关 有关系,女宝宝会比男宝宝要多一点。如0岁男宝宝趸交是130.4元,3年期交是43.7元,5年期交是27元;而0岁女宝宝趸交是131.6元,3年期交是44.1元,5年期交是27.2元。
|
||||
在中国,哪个品牌的餐饮照明比较好? 一般来说美尔家比较可靠吧,有保障
|
||||
......
|
||||
```
|
||||
|
||||
|
||||
### 3.3 代码说明
|
||||
|
||||
```
|
||||
@@ -82,7 +172,7 @@
|
||||
|—— export_to_serving.py # 静态图转 Serving
|
||||
|—— feature_extract.py # 批量提取文本的特征向量
|
||||
|—— milvus_util.py # Milvus的插入和召回类
|
||||
|—— vector_insert.py # 向 Milvus 引擎插入向量的函数
|
||||
|—— milvus_ann_search.py # 向 Milvus 引擎插入向量的函数
|
||||
|—— run_system.py # Client Server 模式客户端,向 server 发送文本,得到向量后,利用milvus引擎进行检索
|
||||
|—— scripts
|
||||
|—— export_model.sh # 动态图转换成静态图脚本
|
||||
@@ -100,6 +190,8 @@
|
||||
|
||||
### 3.3 效果评估
|
||||
|
||||
以下实验结果使用的是模型是`rocketqa-zh-dureader-query-encoder`:
|
||||
|
||||
| 模型 | Recall@1 |Recall@5 |Recall@10 |
|
||||
| ------------ | ------------ |--------- |--------- |
|
||||
| RocketQA + SimCSE | 82.827 | 93.791| 96.169|
|
||||
@@ -111,12 +203,27 @@
|
||||
|
||||
## 4. 动手实践——搭建自己的端到端检索式问答系统
|
||||
|
||||
### 4.1 无监督训练
|
||||
### 4.1 环境安装
|
||||
|
||||
在运行下面的代码之前,安装相关的依赖,运行下面的命令:
|
||||
|
||||
```
|
||||
python -u -m paddle.distributed.launch --gpus '0' \
|
||||
pip install -r requirements.txt -i https://pypi.tuna.tsinghua.edu.cn/simple
|
||||
```
|
||||
|
||||
### 4.2 模型训练
|
||||
|
||||
SimCSE可以使用2种方式进行训练,即有监督训练和无监督训练,区别在于无监督训练不需要标注数据集,有监督训练需要标注好问句对,下面是无监督的执行方式。
|
||||
|
||||
#### 无监督训练
|
||||
|
||||
无监督训练执行下面的方式,可以选择`train.csv`,纯无监督文本,或者数据增强的数据`train_aug.csv`,然后执行下面的命令:
|
||||
|
||||
```
|
||||
python -u -m paddle.distributed.launch --gpus='0' \
|
||||
train.py \
|
||||
--device gpu \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--save_dir ./checkpoints/ \
|
||||
--batch_size 64 \
|
||||
--learning_rate 5E-5 \
|
||||
@@ -125,9 +232,9 @@ python -u -m paddle.distributed.launch --gpus '0' \
|
||||
--eval_steps 50 \
|
||||
--max_seq_length 64 \
|
||||
--dropout 0.2 \
|
||||
--output_emb_size 256 \
|
||||
--dup_rate 0.1 \
|
||||
--rdrop_coef 0.1 \
|
||||
--output_emb_size 256 \
|
||||
--train_set_file "./data/train_aug.csv"
|
||||
```
|
||||
|
||||
@@ -135,9 +242,11 @@ python -u -m paddle.distributed.launch --gpus '0' \
|
||||
|
||||
* `device`: 使用 cpu/gpu 进行训练
|
||||
* `save_dir`: 模型存储路径
|
||||
* `model_name_or_path`: 预训练语言模型名,用于模型的初始化
|
||||
* `batch_size`: 训练的batch size的大小
|
||||
* `learning_rate`: 训练的学习率的大小
|
||||
* `epochs`: 训练的epoch数
|
||||
* `is_unsupervised`:是否使用无监督的训练方式
|
||||
* `save_steps`: 模型存储 checkpoint 的间隔 steps 个数
|
||||
* `max_seq_length`: 输入序列的最大长度
|
||||
* `dropout`: SimCSE的dropout参数
|
||||
@@ -152,7 +261,7 @@ python -u -m paddle.distributed.launch --gpus '0' \
|
||||
sh scripts/train.sh
|
||||
```
|
||||
|
||||
### 4.2 评估
|
||||
### 4.3 评估
|
||||
|
||||
效果评估分为 4 个步骤:
|
||||
|
||||
@@ -194,6 +303,7 @@ python -u -m paddle.distributed.launch --gpus "0" --log_dir "recall_log/" \
|
||||
* `device`: 使用 cpu/gpu 进行训练
|
||||
* `recall_result_dir`: 召回结果存储目录
|
||||
* `recall_result_file`: 召回结果的文件名
|
||||
* `model_name_or_path`: 预训练语言模型名,用于模型的初始化
|
||||
* `params_path`: 待评估模型的参数文件名
|
||||
* `hnsw_m`: hnsw 算法相关参数,保持默认即可
|
||||
* `hnsw_ef`: hnsw 算法相关参数,保持默认即可
|
||||
@@ -235,16 +345,18 @@ recall@10=96.433
|
||||
* `recall_result_file`: 针对评估集中第一列文本 *Source Text* 的召回结果
|
||||
* `recall_num`: 对 1 个文本召回的相似文本数量
|
||||
|
||||
## 4.3 模型部署
|
||||
### 4.4 模型部署
|
||||
|
||||
模型部署模块首先要把动态图转换成静态图,然后转换成serving的格式。
|
||||
|
||||
### 动转静导出
|
||||
#### 动转静导出
|
||||
|
||||
首先把动态图模型转换为静态图:
|
||||
|
||||
```
|
||||
python export_model.py --params_path checkpoints/model_100/model_state.pdparams --output_path=./output
|
||||
python export_model.py --params_path checkpoints/model_100/model_state.pdparams \
|
||||
--output_path=./output \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder
|
||||
```
|
||||
也可以运行下面的bash脚本:
|
||||
|
||||
@@ -252,9 +364,9 @@ python export_model.py --params_path checkpoints/model_100/model_state.pdparams
|
||||
sh scripts/export_model.sh
|
||||
```
|
||||
|
||||
### 问答检索引擎
|
||||
#### 问答检索引擎
|
||||
|
||||
模型准备结束以后,开始搭建 Milvus 的语义检索引擎,用于语义向量的快速检索,本项目使用[Milvus](https://milvus.io/)开源工具进行向量检索,Milvus 的搭建教程请参考官方教程 [Milvus官方安装教程](https://milvus.io/cn/docs/v1.1.1/milvus_docker-cpu.md)本案例使用的是 Milvus 的1.1.1 CPU版本,建议使用官方的 Docker 安装方式,简单快捷。
|
||||
模型准备结束以后,开始搭建 Milvus 的语义检索引擎,用于语义向量的快速检索,本项目使用[Milvus](https://milvus.io/)开源工具进行向量检索,Milvus 的搭建教程请参考官方教程 [Milvus官方安装教程](https://milvus.io/docs/v2.1.x/install_standalone-docker.md)本案例使用的是 Milvus 的2.1 版本,建议使用官方的 Docker-Compose 安装方式,简单快捷。
|
||||
|
||||
|
||||
Milvus 搭建完系统以后就可以插入和检索向量了,首先生成 embedding 向量,每个样本生成256维度的向量:
|
||||
@@ -262,22 +374,49 @@ Milvus 搭建完系统以后就可以插入和检索向量了,首先生成 emb
|
||||
```
|
||||
python feature_extract.py \
|
||||
--model_dir=./output \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--corpus_file "data/corpus.csv"
|
||||
```
|
||||
其中 output 目录下存放的是召回的 Paddle Inference 静态图模型。
|
||||
|
||||
也可以运行下面的bash脚本:
|
||||
|
||||
```
|
||||
sh scripts/feature_extract.sh
|
||||
```
|
||||
|
||||
然后向搭建好的 Milvus 系统插入向量:
|
||||
|
||||
```
|
||||
python vector_insert.py
|
||||
python milvus_ann_search.py --data_path data/qa_pair.csv \
|
||||
--embedding_path corpus_embedding.npy \
|
||||
--batch_size 100000 \
|
||||
--insert
|
||||
```
|
||||
|
||||
### Paddle Serving 部署
|
||||
|
||||
Paddle Serving 的安装可以参考[Paddle Serving 安装文档](https://github.com/PaddlePaddle/Serving#installation)。需要在服务端和客户端安装相关的依赖,安装完依赖后就可以执行下面的步骤。
|
||||
另外,Milvus提供了可视化的管理界面,可以很方便的查看数据,安装地址为[Attu](https://github.com/zilliztech/attu).
|
||||
|
||||
|
||||
首先把生成的静态图模型导出为 Paddle Serving的格式,命令如下:
|
||||
#### Paddle Serving 部署
|
||||
|
||||
Paddle Serving 的安装可以参考[Paddle Serving 安装文档](https://github.com/PaddlePaddle/Serving#installation)。需要在服务端和客户端安装相关的依赖,用pip安装Paddle Serving的依赖如下:
|
||||
|
||||
```
|
||||
pip install paddle-serving-client==0.8.3 -i https://pypi.tuna.tsinghua.edu.cn/simple
|
||||
pip install paddle-serving-app==0.8.3 -i https://pypi.tuna.tsinghua.edu.cn/simple
|
||||
|
||||
# 如果是CPU部署,只需要安装CPU Server
|
||||
pip install paddle-serving-server==0.8.3 -i https://pypi.tuna.tsinghua.edu.cn/simple
|
||||
|
||||
# 如果是GPU Server,需要确认环境再选择执行哪一条,推荐使用CUDA 10.2的包
|
||||
# CUDA10.2 + Cudnn7 + TensorRT6(推荐)
|
||||
pip install paddle-serving-server-gpu==0.8.3.post102 -i https://pypi.tuna.tsinghua.edu.cn/simple
|
||||
# CUDA10.1 + TensorRT6
|
||||
pip install paddle-serving-server-gpu==0.8.3.post101 -i https://pypi.tuna.tsinghua.edu.cn/simple
|
||||
# CUDA11.2 + TensorRT8
|
||||
pip install paddle-serving-server-gpu==0.8.3.post112 -i https://pypi.tuna.tsinghua.edu.cn/simple
|
||||
```
|
||||
更详细的安装信息请参考[链接](https://github.com/PaddlePaddle/Serving/blob/v0.9.0/doc/Install_Linux_Env_CN.md),安装完依赖后就可以执行下面的步骤。首先把生成的静态图模型导出为 Paddle Serving的格式,命令如下:
|
||||
|
||||
```
|
||||
python export_to_serving.py \
|
||||
@@ -307,7 +446,7 @@ sh scripts/export_to_serving.sh
|
||||
|
||||
```
|
||||
cd deploy/python/
|
||||
python web_service.py
|
||||
python web_service.py --model_name_or_path rocketqa-zh-base-query-encoder
|
||||
```
|
||||
|
||||
启动客户端调用 Server, 使用 POST的方式:
|
||||
@@ -333,7 +472,23 @@ list_data = [
|
||||
python rpc_client.py
|
||||
```
|
||||
|
||||
## 4.4 问答系统整个流程
|
||||
对于Windows用户,启动下面的Pipeline Server:
|
||||
|
||||
```
|
||||
python web_service_windows.py --model_name_or_path rocketqa-zh-base-query-encoder
|
||||
```
|
||||
|
||||
启动客户端调用 Server, 使用 POST的方式(Windows不支持RPC的调用方式),首先修改http_client.py中需要预测的样本:
|
||||
|
||||
```
|
||||
data = {"feed": ["买了社保,是不是就不用买商业保险了?"], "fetch": ["output_embedding"]}
|
||||
```
|
||||
然后运行:
|
||||
```
|
||||
python http_client.py
|
||||
```
|
||||
|
||||
### 4.5 问答系统整个流程
|
||||
|
||||
问答系统使用了Client Server的模式,即抽取向量的模型部署在服务端,然后启动客户端(Client)端去访问。
|
||||
|
||||
@@ -351,12 +506,50 @@ list_data = ["买了社保,是不是就不用买商业保险了?"]
|
||||
|
||||
```
|
||||
......
|
||||
PipelineClient::predict pack_data time:1650712793.4998188
|
||||
PipelineClient::predict before time:1650712793.5002873
|
||||
Extract feature time to cost :0.012665271759033203 seconds
|
||||
Search milvus time cost is 0.007043361663818359 seconds
|
||||
如果你买社会保险,你不需要买商业保险吗? 社保是基础的,就是我们通常说的“五险”包括:基本养老保险、基本医疗保险、失业保险、工伤保险和生育保险。而商业保险则是保障。 0.4609384536743164
|
||||
社保跟商业保险的区别在哪?有了社保还需要买商业保险不? 社会保险是指国家为了预防和分担年老、失业、疾病以及死亡等社会风险,实现社会安全,而强制社会多数成员参加的,具有所得重分配功能的非营利性的社会安全制度。而商业保险是指通过订立保险合同运营,以营利为目的的保险形式,由专门的保险企业经营。这两种保险是不同的,一般在有社会保险基础上,添加商业保险,是一种补充。社保和商业保险的区别在于:1、性质不同社保是属于社会福利保障的范畴,所以最终的赔偿是由国家来承担的,但是商业保险是由商业机构承担的,最终的保险赔偿和风险都是有商业机构所承担的,这就是社保和商业保险的区别最明显的表现之处。2、自愿原则社保是一种国家福利,是强制性缴纳的;商业保险是一种个人行为,可自愿购买。3、期限可选社保必须交满一定年限才可动用或领取;商业保险缴费期限灵活,3年、5年、10年、20年...时间长短由投保人决定。4、交费多少社保的交费,只要参与,每个人都基本一样,由单位交纳20%(或12%)左右,个人交8%,月交方式,金额会随着时间变化而增加;而商保是个人行为,根据自己的实际情况,多少自由,多交多得,少交少得。5、保障水平不同。社会保险为被保险人提供的保障是最基本的,其水平高于社会贫困线,低于社会平均工资的50%,保障程度较低;商业保险提供的保障水平完全取决于保险双方当事人的约定和投保人所缴保费的多少,只要符合投保条件并有一定的缴费能力,被保险人可以获得高水平的保障。 0.5826151371002197
|
||||
PipelineClient::predict pack_data time:1663127450.1656108
|
||||
PipelineClient::predict before time:1663127450.166227
|
||||
Extract feature time to cost :0.017495155334472656 seconds
|
||||
|
||||
=== start connecting to Milvus ===
|
||||
=== Connect collection faq_finance ===
|
||||
Search milvus time cost is 0.18691015243530273 seconds
|
||||
如果你买社会保险,你不需要买商业保险吗? 社保是基础的,就是我们通常说的“五险”包括:基本养老保险、基本医疗保险、失业保险、工伤保险和生育保险。而商业保险则是保障。 0.32494643330574036
|
||||
已有社会保险还需要买商业保险吗 社保是社会保险的简称社会保险是指国家为了预防和分担年老失业疾病以及死亡等社会风险实现社会安全而强制社会多数成员参加的具有所得重分配功能的非营利性的社会安全制度主要包括基本医疗保险基本养老保险工伤保险失业保险生育保险五大类险种,商业保险是社保的一个补充,如果有足够的经济条件可以进行购买。1、社保覆盖面广,不存在拒保问题,但是保障较低,只能满足基本的保障需求。社保中的医疗保险,住院一般可报70%。而且这70%的医疗费,限于扣除起付线标准后。而且,在社保规定用药和规定项目内。许多检查费、专家诊疗、高新尖诊疗技术,社保都是不报的。这就需配合必要的商业保险了。2、另外,社保医疗是出院后报的,商业医保中的重疾险是确诊后就可以给钱,可以弥补很多家庭没钱治的困境;3、商业保险可以选择购买更高的保额,社保则很有限;社保医疗只是补偿医药费,而没有住院期间的收入损失补偿,商业医疗就有住院补贴。总之,建议在有了社保后,再购买适合自己的寿险,加上意外险、住院医疗、重疾医疗保险,就是非常的完善的保障了。 0.38041722774505615
|
||||
.....
|
||||
```
|
||||
输出的结果包括特征提取和检索的时间,还包含检索出来的问答对。
|
||||
|
||||
|
||||
<a name="模型优化"></a>
|
||||
|
||||
## 5. 模型优化
|
||||
|
||||
### 5.1 有监督训练[优化步骤,可选]
|
||||
|
||||
无监督的方式对模型的提升有限,如果需要继续提升模型,则需要标注数据。构造类似`train_aug.csv`中的句子对,只需要构造相似句子对即可,不需要构造不相似的句子对。
|
||||
|
||||
```
|
||||
python -u -m paddle.distributed.launch --gpus='0' \
|
||||
train.py \
|
||||
--device gpu \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--save_dir ./checkpoints/ \
|
||||
--batch_size 64 \
|
||||
--learning_rate 5E-5 \
|
||||
--epochs 3 \
|
||||
--save_steps 50 \
|
||||
--eval_steps 50 \
|
||||
--max_seq_length 64 \
|
||||
--dropout 0.2 \
|
||||
--output_emb_size 256 \
|
||||
--dup_rate 0.1 \
|
||||
--rdrop_coef 0.1 \
|
||||
--train_set_file "./data/train_aug.csv"
|
||||
```
|
||||
|
||||
其他步骤同上,只是使用的数据集是有监督数据。
|
||||
|
||||
|
||||
## 6.参考文献
|
||||
|
||||
[1] Tianyu Gao, Xingcheng Yao, Danqi Chen: [SimCSE: Simple Contrastive Learning of Sentence Embeddings](https://arxiv.org/abs/2104.08821). EMNLP (1) 2021: 6894-6910
|
||||
|
||||
@@ -12,20 +12,27 @@
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import os
|
||||
from milvus import MetricType, IndexType
|
||||
search_param = {'nprobe': 20}
|
||||
collection_name = 'faq_finance'
|
||||
partition_tag = 'partition_1'
|
||||
|
||||
MILVUS_HOST = '10.21.226.173'
|
||||
MILVUS_HOST = '10.21.226.175'
|
||||
MILVUS_PORT = 8530
|
||||
data_dim = 256
|
||||
top_k = 10
|
||||
embedding_name = 'embeddings'
|
||||
|
||||
collection_param = {
|
||||
'dimension': 256,
|
||||
'index_file_size': 256,
|
||||
'metric_type': MetricType.L2
|
||||
index_config = {
|
||||
"index_type": "IVF_FLAT",
|
||||
"metric_type": "L2",
|
||||
"params": {
|
||||
"nlist": 1000
|
||||
},
|
||||
}
|
||||
|
||||
index_type = IndexType.IVF_FLAT
|
||||
index_param = {'nlist': 1000}
|
||||
|
||||
top_k = 10
|
||||
search_param = {'nprobe': 20}
|
||||
search_params = {
|
||||
"metric_type": "L2",
|
||||
"params": {
|
||||
"nprobe": top_k
|
||||
},
|
||||
}
|
||||
|
||||
@@ -0,0 +1,31 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import json
|
||||
import base64
|
||||
import time
|
||||
import numpy as np
|
||||
import requests
|
||||
|
||||
headers = {"Content-type": "application/json"}
|
||||
url = "http://10.21.226.175:8080/ernie/prediction" # XXX取决于服务端YourService的初始化name参数
|
||||
|
||||
data = {"feed": ["买了社保,是不是就不用买商业保险了?"], "fetch": ["output_embedding"]}
|
||||
data = json.dumps(data)
|
||||
print(data)
|
||||
r = requests.post(url=url, headers=headers, data=data)
|
||||
print(r.json())
|
||||
json_data = r.json()
|
||||
data = np.array(json_data['result']['output_embedding'])
|
||||
print(data.shape)
|
||||
@@ -14,9 +14,16 @@
|
||||
|
||||
import numpy as np
|
||||
import sys
|
||||
import argparse
|
||||
|
||||
from paddle_serving_server.web_service import WebService, Op
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-zh-base-query-encoder", help="Select tokenizer name to for model")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
def convert_example(example,
|
||||
tokenizer,
|
||||
@@ -37,7 +44,7 @@ class ErnieOp(Op):
|
||||
|
||||
def init_op(self):
|
||||
from paddlenlp.transformers import AutoTokenizer
|
||||
self.tokenizer = AutoTokenizer.from_pretrained('ernie-3.0-medium-zh')
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
def preprocess(self, input_dicts, data_id, log_id):
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
@@ -53,7 +60,7 @@ class ErnieOp(Op):
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=self.tokenizer.pad_token_id, dtype="int64"
|
||||
), # input
|
||||
Pad(axis=0, pad_val=self.tokenizer.pad_token_id, dtype="int64"
|
||||
Pad(axis=0, pad_val=self.tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # segment
|
||||
): fn(samples)
|
||||
input_ids, segment_ids = batchify_fn(examples)
|
||||
@@ -76,6 +83,7 @@ class ErnieService(WebService):
|
||||
return ernie_op
|
||||
|
||||
|
||||
ernie_service = ErnieService(name="ernie")
|
||||
ernie_service.prepare_pipeline_config("config_nlp.yml")
|
||||
ernie_service.run_service()
|
||||
if __name__ == "__main__":
|
||||
ernie_service = ErnieService(name="ernie")
|
||||
ernie_service.prepare_pipeline_config("config_nlp.yml")
|
||||
ernie_service.run_service()
|
||||
|
||||
@@ -0,0 +1,82 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import numpy as np
|
||||
import sys
|
||||
import argparse
|
||||
|
||||
from paddle_serving_server.web_service import WebService, Op
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-zh-base-query-encoder", help="Select tokenizer name to for model")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
def convert_example(example,
|
||||
tokenizer,
|
||||
max_seq_length=512,
|
||||
pad_to_max_seq_len=False):
|
||||
result = []
|
||||
for text in example:
|
||||
encoded_inputs = tokenizer(text=text,
|
||||
max_seq_len=max_seq_length,
|
||||
pad_to_max_seq_len=pad_to_max_seq_len)
|
||||
input_ids = encoded_inputs["input_ids"]
|
||||
token_type_ids = encoded_inputs["token_type_ids"]
|
||||
result += [input_ids, token_type_ids]
|
||||
return result
|
||||
|
||||
|
||||
class ErnieService(WebService):
|
||||
|
||||
def init_service(self):
|
||||
from paddlenlp.transformers import AutoTokenizer
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
def preprocess(self, feed=[], fetch=[]):
|
||||
from paddlenlp.data import Stack, Tuple, Pad
|
||||
print("input dict", feed)
|
||||
batch_size = len(feed)
|
||||
is_batch = True
|
||||
examples = []
|
||||
for i in range(batch_size):
|
||||
input_ids, segment_ids = convert_example([feed[i]], self.tokenizer)
|
||||
examples.append((input_ids, segment_ids))
|
||||
batchify_fn = lambda samples, fn=Tuple(
|
||||
Pad(axis=0, pad_val=self.tokenizer.pad_token_id, dtype="int64"
|
||||
), # input
|
||||
Pad(axis=0, pad_val=self.tokenizer.pad_token_type_id, dtype="int64"
|
||||
), # segment
|
||||
): fn(samples)
|
||||
input_ids, segment_ids = batchify_fn(examples)
|
||||
feed_dict = {}
|
||||
feed_dict['input_ids'] = input_ids
|
||||
feed_dict['token_type_ids'] = segment_ids
|
||||
return feed_dict, fetch, is_batch
|
||||
|
||||
def postprocess(self, feed=[], fetch=[], fetch_map=None):
|
||||
for key in fetch_map:
|
||||
fetch_map[key] = fetch_map[key].tolist()
|
||||
return fetch_map
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
ernie_service = ErnieService(name="ernie")
|
||||
ernie_service.load_model_config("../../serving_server")
|
||||
ernie_service.prepare_server(workdir="workdir", port=8080)
|
||||
ernie_service.init_service()
|
||||
ernie_service.run_debugger_service()
|
||||
ernie_service.run_web_service()
|
||||
@@ -30,22 +30,25 @@ parser.add_argument("--params_path", type=str, required=True,
|
||||
default='./checkpoint/model_50/model_state.pdparams', help="The path to model parameters to be loaded.")
|
||||
parser.add_argument("--output_path", type=str, default='./output',
|
||||
help="The path of model parameter in static graph to be saved.")
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-zh-base-query-encoder", help="The pretrained model used for training")
|
||||
parser.add_argument("--output_emb_size", default=256, type=int, help="Output_embedding_size, 0 means use hidden_size as output embedding size.")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
if __name__ == "__main__":
|
||||
output_emb_size = 256
|
||||
|
||||
pretrained_model = AutoModel.from_pretrained("ernie-3.0-medium-zh")
|
||||
pretrained_model = AutoModel.from_pretrained(args.model_name_or_path)
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('ernie-3.0-medium-zh')
|
||||
model = SimCSE(pretrained_model, output_emb_size=output_emb_size)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
model = SimCSE(pretrained_model, output_emb_size=args.output_emb_size)
|
||||
|
||||
if args.params_path and os.path.isfile(args.params_path):
|
||||
state_dict = paddle.load(args.params_path)
|
||||
model.set_dict(state_dict)
|
||||
print("Loaded parameters from %s" % args.params_path)
|
||||
|
||||
else:
|
||||
raise ValueError(
|
||||
"Please set --params_path with correct pretrained model file")
|
||||
model.eval()
|
||||
# Convert to static graph with specific input description
|
||||
model = paddle.jit.to_static(
|
||||
|
||||
@@ -35,7 +35,7 @@ parser.add_argument("--model_dir", type=str, required=True,
|
||||
|
||||
parser.add_argument("--corpus_file", type=str, required=True,
|
||||
help="The corpus_file path.")
|
||||
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-zh-base-query-encoder", help="The pretrained model used for training")
|
||||
parser.add_argument("--max_seq_length", default=64, type=int,
|
||||
help="The maximum total input sequence length after tokenization. Sequences "
|
||||
"longer than this will be truncated, sequences shorter will be padded.")
|
||||
@@ -214,7 +214,7 @@ if __name__ == "__main__":
|
||||
args.batch_size, args.use_tensorrt, args.precision,
|
||||
args.cpu_threads, args.enable_mkldnn)
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained('ernie-3.0-medium-zh')
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
id2corpus = read_text(args.corpus_file)
|
||||
|
||||
corpus_list = [{idx: text} for idx, text in id2corpus.items()]
|
||||
|
||||
117
applications/question_answering/faq_finance/milvus_ann_search.py
Normal file
117
applications/question_answering/faq_finance/milvus_ann_search.py
Normal file
@@ -0,0 +1,117 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import random
|
||||
from tqdm import tqdm
|
||||
import time
|
||||
import argparse
|
||||
|
||||
import numpy as np
|
||||
from milvus_util import VecToMilvus, RecallByMilvus, text_max_len
|
||||
from config import collection_name, partition_tag, embedding_name
|
||||
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--data_path",
|
||||
default='data/corpus.csv',
|
||||
type=str,
|
||||
required=True,
|
||||
help="The data for vector extraction.")
|
||||
parser.add_argument("--embedding_path",
|
||||
default='corpus_embedding.npy',
|
||||
type=str,
|
||||
required=True,
|
||||
help="The vector path for data.")
|
||||
parser.add_argument('--index',
|
||||
default=0,
|
||||
type=int,
|
||||
help='index of the vector for search')
|
||||
parser.add_argument('--insert',
|
||||
action='store_true',
|
||||
help='whether to insert data')
|
||||
parser.add_argument('--search',
|
||||
action='store_true',
|
||||
help='whether to search data')
|
||||
parser.add_argument('--batch_size',
|
||||
default=100000,
|
||||
type=int,
|
||||
help='number of examples to insert each time')
|
||||
args = parser.parse_args()
|
||||
|
||||
|
||||
def read_text(file_path):
|
||||
file = open(file_path)
|
||||
id2corpus = []
|
||||
for idx, data in enumerate(file.readlines()):
|
||||
question, answer = data.strip().split('\t')
|
||||
id2corpus.append({'question': question, 'answer': answer})
|
||||
return id2corpus
|
||||
|
||||
|
||||
def milvus_data_insert(data_path, embedding_path, batch_size):
|
||||
corpus_list = read_text(data_path)
|
||||
embeddings = np.load(embedding_path)
|
||||
embedding_ids = [i for i in range(embeddings.shape[0])]
|
||||
client = VecToMilvus()
|
||||
client.drop_collection(collection_name)
|
||||
data_size = len(embedding_ids)
|
||||
for i in tqdm(range(0, data_size, batch_size)):
|
||||
cur_end = i + batch_size
|
||||
if (cur_end > data_size):
|
||||
cur_end = data_size
|
||||
batch_emb = embeddings[np.arange(i, cur_end)]
|
||||
entities = [
|
||||
[j for j in range(i, cur_end, 1)],
|
||||
[
|
||||
corpus_list[j]['question'][:text_max_len - 1]
|
||||
for j in range(i, cur_end, 1)
|
||||
],
|
||||
[
|
||||
corpus_list[j]['answer'][:text_max_len - 1]
|
||||
for j in range(i, cur_end, 1)
|
||||
],
|
||||
batch_emb # field embeddings, supports numpy.ndarray and list
|
||||
]
|
||||
client.insert(collection_name=collection_name,
|
||||
entities=entities,
|
||||
index_name=embedding_name,
|
||||
partition_tag=partition_tag)
|
||||
|
||||
|
||||
def milvus_data_recall(embedding_path, index):
|
||||
embeddings = np.load(embedding_path)
|
||||
embedding_ids = [i for i in range(embeddings.shape[0])]
|
||||
recall_client = RecallByMilvus()
|
||||
if (index > len(embedding_ids)):
|
||||
print('Index should not be larger than embedding szie')
|
||||
return
|
||||
embeddings = embeddings[np.arange(index, index + 1)]
|
||||
time_start = time.time()
|
||||
result = recall_client.search(embeddings,
|
||||
embedding_name,
|
||||
collection_name,
|
||||
partition_names=[partition_tag],
|
||||
output_fields=['pk', 'text'])
|
||||
time_end = time.time()
|
||||
sum_t = time_end - time_start
|
||||
print('time cost', sum_t, 's')
|
||||
for hits in result:
|
||||
for hit in hits:
|
||||
print(f"hit: {hit}, text field: {hit.entity.get('text')}")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
if (args.insert):
|
||||
milvus_data_insert(args.data_path, args.embedding_path, args.batch_size)
|
||||
if (args.search):
|
||||
milvus_data_recall(args.embedding_path, args.index)
|
||||
@@ -1,4 +1,4 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
@@ -12,78 +12,105 @@
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from milvus import *
|
||||
from config import MILVUS_HOST, MILVUS_PORT, collection_param, index_type, index_param
|
||||
from config import top_k, search_param
|
||||
import time
|
||||
|
||||
import numpy as np
|
||||
from pymilvus import (
|
||||
connections,
|
||||
utility,
|
||||
FieldSchema,
|
||||
CollectionSchema,
|
||||
DataType,
|
||||
Collection,
|
||||
)
|
||||
|
||||
from config import MILVUS_HOST, MILVUS_PORT, data_dim, index_config, top_k, search_params
|
||||
|
||||
fmt = "\n=== {:30} ===\n"
|
||||
text_max_len = 1000
|
||||
fields = [
|
||||
FieldSchema(name="pk",
|
||||
dtype=DataType.INT64,
|
||||
is_primary=True,
|
||||
auto_id=False,
|
||||
max_length=100),
|
||||
FieldSchema(name="question",
|
||||
dtype=DataType.VARCHAR,
|
||||
max_length=text_max_len),
|
||||
FieldSchema(name="answer", dtype=DataType.VARCHAR, max_length=text_max_len),
|
||||
FieldSchema(name="embeddings", dtype=DataType.FLOAT_VECTOR, dim=data_dim)
|
||||
]
|
||||
schema = CollectionSchema(fields, "Neural Search Index")
|
||||
|
||||
|
||||
class VecToMilvus():
|
||||
|
||||
def __init__(self):
|
||||
self.client = Milvus(host=MILVUS_HOST, port=MILVUS_PORT)
|
||||
print(fmt.format("start connecting to Milvus"))
|
||||
connections.connect("default", host=MILVUS_HOST, port=MILVUS_PORT)
|
||||
self.collection = None
|
||||
|
||||
def has_collection(self, collection_name):
|
||||
try:
|
||||
status, ok = self.client.has_collection(collection_name)
|
||||
return ok
|
||||
has = utility.has_collection(collection_name)
|
||||
print(f"Does collection {collection_name} exist in Milvus: {has}")
|
||||
return has
|
||||
except Exception as e:
|
||||
print("Milvus has_table error:", e)
|
||||
|
||||
def creat_collection(self, collection_name):
|
||||
try:
|
||||
collection_param['collection_name'] = collection_name
|
||||
status = self.client.create_collection(collection_param)
|
||||
print(status)
|
||||
return status
|
||||
print(fmt.format("Create collection {}".format(collection_name)))
|
||||
self.collection = Collection(collection_name,
|
||||
schema,
|
||||
consistency_level="Strong")
|
||||
except Exception as e:
|
||||
print("Milvus create collection error:", e)
|
||||
|
||||
def create_index(self, collection_name):
|
||||
def drop_collection(self, collection_name):
|
||||
try:
|
||||
status = self.client.create_index(collection_name, index_type,
|
||||
index_param)
|
||||
print(status)
|
||||
return status
|
||||
utility.drop_collection(collection_name)
|
||||
except Exception as e:
|
||||
print("Milvus delete collection error:", e)
|
||||
|
||||
def create_index(self, index_name):
|
||||
try:
|
||||
print(fmt.format("Start Creating index"))
|
||||
self.collection.create_index(index_name, index_config)
|
||||
print(fmt.format("Start loading"))
|
||||
self.collection.load()
|
||||
except Exception as e:
|
||||
print("Milvus create index error:", e)
|
||||
|
||||
def has_partition(self, collection_name, partition_tag):
|
||||
def has_partition(self, partition_tag):
|
||||
try:
|
||||
status, ok = self.client.has_partition(collection_name,
|
||||
partition_tag)
|
||||
return ok
|
||||
result = self.collection.has_partition(partition_tag)
|
||||
return result
|
||||
except Exception as e:
|
||||
print("Milvus has partition error: ", e)
|
||||
|
||||
def create_partition(self, collection_name, partition_tag):
|
||||
def create_partition(self, partition_tag):
|
||||
try:
|
||||
status = self.client.create_partition(collection_name,
|
||||
partition_tag)
|
||||
self.collection.create_partition(partition_tag)
|
||||
print('create partition {} successfully'.format(partition_tag))
|
||||
return status
|
||||
except Exception as e:
|
||||
print('Milvus create partition error: ', e)
|
||||
|
||||
def insert(self, vectors, collection_name, ids=None, partition_tag=None):
|
||||
def insert(self, entities, collection_name, index_name, partition_tag=None):
|
||||
try:
|
||||
if not self.has_collection(collection_name):
|
||||
self.creat_collection(collection_name)
|
||||
self.create_index(collection_name)
|
||||
print('collection info: {}'.format(
|
||||
self.client.get_collection_info(collection_name)[1]))
|
||||
if (partition_tag is not None) and (not self.has_partition(
|
||||
collection_name, partition_tag)):
|
||||
self.create_partition(collection_name, partition_tag)
|
||||
status, ids = self.client.insert(collection_name=collection_name,
|
||||
records=vectors,
|
||||
ids=ids,
|
||||
partition_tag=partition_tag)
|
||||
self.client.flush([collection_name])
|
||||
self.create_index(index_name)
|
||||
else:
|
||||
self.collection = Collection(collection_name)
|
||||
if (partition_tag
|
||||
is not None) and (not self.has_partition(partition_tag)):
|
||||
self.create_partition(partition_tag)
|
||||
|
||||
self.collection.insert(entities, partition_name=partition_tag)
|
||||
print(
|
||||
'Insert {} entities, there are {} entities after insert data.'.
|
||||
format(len(ids),
|
||||
self.client.count_entities(collection_name)[1]))
|
||||
return status, ids
|
||||
f"Number of entities in Milvus: {self.collection.num_entities}"
|
||||
) # check the num_entites
|
||||
except Exception as e:
|
||||
print("Milvus insert error:", e)
|
||||
|
||||
@@ -91,16 +118,66 @@ class VecToMilvus():
|
||||
class RecallByMilvus():
|
||||
|
||||
def __init__(self):
|
||||
self.client = Milvus(host=MILVUS_HOST, port=MILVUS_PORT)
|
||||
print(fmt.format("start connecting to Milvus"))
|
||||
connections.connect("default", host=MILVUS_HOST, port=MILVUS_PORT)
|
||||
self.collection = None
|
||||
|
||||
def search(self, vectors, collection_name, partition_tag=None):
|
||||
def get_collection(self, collection_name):
|
||||
try:
|
||||
status, results = self.client.search(
|
||||
collection_name=collection_name,
|
||||
query_records=vectors,
|
||||
top_k=top_k,
|
||||
params=search_param,
|
||||
partition_tag=partition_tag)
|
||||
return status, results
|
||||
print(fmt.format("Connect collection {}".format(collection_name)))
|
||||
self.collection = Collection(collection_name)
|
||||
except Exception as e:
|
||||
print("Milvus create collection error:", e)
|
||||
|
||||
def search(self,
|
||||
vectors,
|
||||
embedding_name,
|
||||
collection_name,
|
||||
partition_names=[],
|
||||
output_fields=[]):
|
||||
try:
|
||||
self.get_collection(collection_name)
|
||||
result = self.collection.search(vectors,
|
||||
embedding_name,
|
||||
search_params,
|
||||
limit=top_k,
|
||||
partition_names=partition_names,
|
||||
output_fields=output_fields)
|
||||
return result
|
||||
except Exception as e:
|
||||
print('Milvus recall error: ', e)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
print(fmt.format("Start inserting entities"))
|
||||
rng = np.random.default_rng(seed=19530)
|
||||
num_entities = 3000
|
||||
entities = [
|
||||
# provide the pk field because `auto_id` is set to False
|
||||
[i for i in range(num_entities)],
|
||||
['第{}个样本'.format(i)
|
||||
for i in range(num_entities)], # field text, only supports list
|
||||
rng.random(
|
||||
(num_entities,
|
||||
data_dim)), # field embeddings, supports numpy.ndarray and list
|
||||
]
|
||||
print(entities[-1].shape)
|
||||
collection_name = 'test1'
|
||||
partition_tag = 'partition_1'
|
||||
embedding_name = 'embeddings'
|
||||
client = VecToMilvus()
|
||||
client.insert(collection_name=collection_name,
|
||||
entities=entities,
|
||||
index_name=embedding_name,
|
||||
partition_tag=partition_tag)
|
||||
print(fmt.format("Start searching entities"))
|
||||
vectors_to_search = entities[-1][-2:]
|
||||
recall_client = RecallByMilvus()
|
||||
result = recall_client.search(vectors_to_search,
|
||||
embedding_name,
|
||||
collection_name,
|
||||
partition_names=[partition_tag],
|
||||
output_fields=['pk', 'text'])
|
||||
for hits in result:
|
||||
for hit in hits:
|
||||
print(f"hit: {hit}, random field: {hit.entity.get('text')}")
|
||||
|
||||
@@ -45,7 +45,7 @@ parser.add_argument("--max_seq_length", default=64, type=int, help="The maximum
|
||||
parser.add_argument("--batch_size", default=32, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument("--output_emb_size", default=None, type=int, help="output_embedding_size")
|
||||
parser.add_argument("--recall_num", default=10, type=int, help="Recall number for each query from Ann index.")
|
||||
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-zh-base-query-encoder", help="The pretrained model used for training")
|
||||
parser.add_argument("--hnsw_m", default=100, type=int, help="Recall number for each query from Ann index.")
|
||||
parser.add_argument("--hnsw_ef", default=100, type=int, help="Recall number for each query from Ann index.")
|
||||
parser.add_argument("--hnsw_max_elements", default=1000000, type=int, help="Recall number for each query from Ann index.")
|
||||
@@ -59,8 +59,7 @@ if __name__ == "__main__":
|
||||
rank = paddle.distributed.get_rank()
|
||||
if paddle.distributed.get_world_size() > 1:
|
||||
paddle.distributed.init_parallel_env()
|
||||
model_name_or_path = 'rocketqa-zh-dureader-query-encoder'
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name_or_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
trans_func = partial(convert_example_test,
|
||||
tokenizer=tokenizer,
|
||||
@@ -73,7 +72,7 @@ if __name__ == "__main__":
|
||||
), # text_segment
|
||||
): [data for data in fn(samples)]
|
||||
|
||||
pretrained_model = AutoModel.from_pretrained(model_name_or_path)
|
||||
pretrained_model = AutoModel.from_pretrained(args.model_name_or_path)
|
||||
|
||||
model = SimCSE(pretrained_model, output_emb_size=args.output_emb_size)
|
||||
model = paddle.DataParallel(model)
|
||||
@@ -105,7 +104,6 @@ if __name__ == "__main__":
|
||||
final_index = build_index(args, corpus_data_loader, inner_model)
|
||||
|
||||
text_list, text2similar_text = gen_text_file(args.similar_text_pair_file)
|
||||
# print(text_list[:5])
|
||||
|
||||
query_ds = MapDataset(text_list)
|
||||
|
||||
|
||||
@@ -0,0 +1,8 @@
|
||||
pymilvus>=2.1.0
|
||||
pandas==0.25.1
|
||||
paddlenlp>=2.3.7
|
||||
paddlepaddle-gpu>=2.2.3
|
||||
hnswlib>=0.5.2
|
||||
numpy>=1.17.2
|
||||
visualdl>=2.2.2
|
||||
pybind11
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import os
|
||||
@@ -9,45 +23,13 @@ import numpy as np
|
||||
import pandas as pd
|
||||
from tqdm import tqdm
|
||||
from paddle_serving_server.pipeline import PipelineClient
|
||||
from data import gen_id2corpus
|
||||
from milvus_util import RecallByMilvus
|
||||
from config import collection_name, partition_tag, embedding_name
|
||||
|
||||
|
||||
def search_in_milvus(text_embedding, query_text):
|
||||
collection_name = 'faq_finance'
|
||||
partition_tag = 'partition_1'
|
||||
client = RecallByMilvus()
|
||||
start_time = time.time()
|
||||
status, results = client.search(collection_name=collection_name,
|
||||
vectors=text_embedding,
|
||||
partition_tag=partition_tag)
|
||||
end_time = time.time()
|
||||
print('Search milvus time cost is {} seconds '.format(end_time -
|
||||
start_time))
|
||||
|
||||
corpus_file = "data/qa_pair.csv"
|
||||
id2corpus = gen_id2corpus(corpus_file)
|
||||
list_data = []
|
||||
for line in results:
|
||||
for item in line:
|
||||
idx = item.id
|
||||
distance = item.distance
|
||||
text = id2corpus[idx]
|
||||
print(text, distance)
|
||||
list_data.append([query_text, text, distance])
|
||||
df = pd.DataFrame(list_data, columns=['query_text', 'text', 'distance'])
|
||||
df = df.sort_values(by="distance", ascending=True)
|
||||
df.to_csv('data/recall_predict.csv',
|
||||
columns=['text', 'distance'],
|
||||
sep='\t',
|
||||
header=None,
|
||||
index=False)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
def recall_result(list_data):
|
||||
client = PipelineClient()
|
||||
client.connect(['127.0.0.1:8080'])
|
||||
list_data = ["买了社保,是不是就不用买商业保险了?"]
|
||||
feed = {}
|
||||
for i, item in enumerate(list_data):
|
||||
feed[str(i)] = item
|
||||
@@ -57,4 +39,35 @@ if __name__ == "__main__":
|
||||
print("Extract feature time to cost :{} seconds".format(end_time -
|
||||
start_time))
|
||||
result = np.array(eval(ret.value[0]))
|
||||
search_in_milvus(result, list_data[0])
|
||||
return result
|
||||
|
||||
|
||||
def search_in_milvus(embeddings, query_text):
|
||||
recall_client = RecallByMilvus()
|
||||
start_time = time.time()
|
||||
results = recall_client.search(embeddings,
|
||||
embedding_name,
|
||||
collection_name,
|
||||
partition_names=[partition_tag],
|
||||
output_fields=['pk', 'question', 'answer'])
|
||||
end_time = time.time()
|
||||
print('Search milvus time cost is {} seconds '.format(end_time -
|
||||
start_time))
|
||||
list_data = []
|
||||
for line in results:
|
||||
for item in line:
|
||||
idx = item.id
|
||||
distance = item.distance
|
||||
question = item.entity.get('question')
|
||||
answer = item.entity.get('answer')
|
||||
print(question, answer, distance)
|
||||
list_data.append([query_text, question, answer, distance])
|
||||
df = pd.DataFrame(list_data,
|
||||
columns=['query_text', 'question', 'answer', 'distance'])
|
||||
df.to_csv('faq_result.csv', index=False)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
list_data = ["买了社保,是不是就不用买商业保险了?"]
|
||||
result = recall_result(list_data)
|
||||
df = search_in_milvus(result, list_data[0])
|
||||
|
||||
@@ -1 +1,17 @@
|
||||
python export_model.py --params_path checkpoints/model_100/model_state.pdparams --output_path=./output
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
python export_model.py --params_path checkpoints/model_100/model_state.pdparams \
|
||||
--output_path=./output \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder
|
||||
@@ -1,3 +1,18 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
python feature_extract.py \
|
||||
--model_dir=./output \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--corpus_file "data/corpus.csv"
|
||||
@@ -1,9 +1,24 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
# gpu
|
||||
python -u -m paddle.distributed.launch --gpus "0" --log_dir "recall_log/" \
|
||||
recall.py \
|
||||
--device gpu \
|
||||
--recall_result_dir "recall_result_dir" \
|
||||
--recall_result_file "recall_result.txt" \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--params_path "checkpoints/model_100/model_state.pdparams" \
|
||||
--hnsw_m 100 \
|
||||
--hnsw_ef 100 \
|
||||
|
||||
@@ -1,6 +1,21 @@
|
||||
python -u -m paddle.distributed.launch --gpus '0' \
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
python -u -m paddle.distributed.launch --gpus='1' \
|
||||
train.py \
|
||||
--device gpu \
|
||||
--model_name_or_path rocketqa-zh-base-query-encoder \
|
||||
--save_dir ./checkpoints/ \
|
||||
--batch_size 64 \
|
||||
--learning_rate 5E-5 \
|
||||
|
||||
@@ -53,9 +53,11 @@ parser.add_argument('--eval_steps', type=int, default=10000, help="Step interval
|
||||
parser.add_argument("--train_set_file", type=str, required=True, help="The full path of train_set_file.")
|
||||
parser.add_argument("--margin", default=0.0, type=float, help="Margin beteween pos_sample and neg_samples.")
|
||||
parser.add_argument("--scale", default=20, type=int, help="Scale for pair-wise margin_rank_loss.")
|
||||
parser.add_argument("--is_unsupervised", action='store_true', help="Whether to use unsupervised training")
|
||||
parser.add_argument("--dropout", default=0.1, type=float, help="Dropout for pretrained model encoder.")
|
||||
parser.add_argument("--dup_rate", default=0.32, type=float, help="duplicate rate for word reptition.")
|
||||
parser.add_argument("--infer_with_fc_pooler", action='store_true', help="Whether use fc layer after cls embedding or not for when infer.")
|
||||
parser.add_argument('--model_name_or_path', default="rocketqa-zh-base-query-encoder", help="The pretrained model used for training")
|
||||
parser.add_argument("--rdrop_coef", default=0.0, type=float, help="The coefficient of KL-Divergence loss in R-Drop paper, for more detail please refer to https://arxiv.org/abs/2106.14448), if rdrop_coef > 0 then R-Drop works")
|
||||
args = parser.parse_args()
|
||||
|
||||
@@ -101,15 +103,19 @@ def do_train():
|
||||
paddle.distributed.init_parallel_env()
|
||||
|
||||
set_seed(args.seed)
|
||||
train_ds = load_dataset(
|
||||
if(args.is_unsupervised):
|
||||
train_ds = load_dataset(
|
||||
read_simcse_text, data_path=args.train_set_file,is_test=False, lazy=False)
|
||||
else:
|
||||
train_ds = load_dataset(
|
||||
read_text_pair, data_path=args.train_set_file,is_test=False, lazy=False)
|
||||
model_name_or_path='rocketqa-zh-dureader-query-encoder'
|
||||
|
||||
pretrained_model = AutoModel.from_pretrained(
|
||||
model_name_or_path,
|
||||
args.model_name_or_path,
|
||||
hidden_dropout_prob=args.dropout,
|
||||
attention_probs_dropout_prob=args.dropout)
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_name_or_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name_or_path)
|
||||
|
||||
trans_func = partial(
|
||||
convert_example,
|
||||
|
||||
@@ -1,46 +0,0 @@
|
||||
# Copyright (c) 2021 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import random
|
||||
|
||||
from tqdm import tqdm
|
||||
import numpy as np
|
||||
|
||||
from milvus_util import VecToMilvus
|
||||
|
||||
|
||||
def vector_insert(file_path):
|
||||
embeddings = np.load(file_path)
|
||||
print(embeddings.shape)
|
||||
embedding_ids = [i for i in range(embeddings.shape[0])]
|
||||
print(len(embedding_ids))
|
||||
client = VecToMilvus()
|
||||
collection_name = 'faq_finance'
|
||||
partition_tag = 'partition_1'
|
||||
data_size = len(embedding_ids)
|
||||
batch_size = 100000
|
||||
for i in tqdm(range(0, data_size, batch_size)):
|
||||
cur_end = i + batch_size
|
||||
if (cur_end > data_size):
|
||||
cur_end = data_size
|
||||
batch_emb = embeddings[np.arange(i, cur_end)]
|
||||
status, ids = client.insert(collection_name=collection_name,
|
||||
vectors=batch_emb.tolist(),
|
||||
ids=embedding_ids[i:i + batch_size],
|
||||
partition_tag=partition_tag)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
file_path = 'corpus_embedding.npy'
|
||||
vector_insert(file_path)
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from functools import partial
|
||||
import argparse
|
||||
import os
|
||||
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
# ## Task: Speech Command Analysis for Audio Expense Claim
|
||||
#
|
||||
# Structured information entry is a common application scenario of speech
|
||||
|
||||
@@ -8,6 +8,7 @@
|
||||
- [2.3 高效模型调优方案](#高效模型调优方案)
|
||||
- [2.4 产业级全流程方案](#产业级全流程方案)
|
||||
- [3. 快速开始](#快速开始)
|
||||
- [4. 常用中文分类数据集](#常用中文分类数据集)
|
||||
|
||||
<a name="文本分类应用简介"></a>
|
||||
|
||||
@@ -17,7 +18,7 @@
|
||||
文本分类简单来说就是对给定的一个句子或一段文本使用分类模型分类。虽然文本分类在金融、医疗、法律、工业等领域都有广泛的成功实践应用,但如何选择合适的方案和预训练模型、数据标注质量差、效果调优困难、AI入门成本高、如何高效训练部署等问题使部分开发者望而却步。针对文本分类领域的痛点和难点,PaddleNLP文本分类应用提出了多种前沿解决方案,助力开发者简单高效实现文本分类数据标注、训练、调优、上线,降低文本分类落地技术门槛。
|
||||
|
||||
<div align="center">
|
||||
<img width="700" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/187667617-81567ba3-7f1f-4d72-9e89-cf6e8d68b906.png">
|
||||
<img width="700" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/189114119-4a1b0bd5-a604-4a34-a63b-7b27519eaf09.png">
|
||||
</div>
|
||||
|
||||
**文本分类应用技术特色:**
|
||||
@@ -36,7 +37,7 @@
|
||||
### 2.1 文本分类方案全覆盖
|
||||
|
||||
<div align="center">
|
||||
<img width="900" alt="image" src="https://user-images.githubusercontent.com/63761690/187871917-9cabcd20-8059-4df0-8a1d-0bf875d80549.png">
|
||||
<img width="900" alt="image" src="https://user-images.githubusercontent.com/63761690/189114232-bb706af4-45a9-4e63-8857-76945a63d081.png">
|
||||
</div>
|
||||
|
||||
#### 2.1.1 分类场景齐全
|
||||
@@ -66,7 +67,7 @@
|
||||
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/63761690/187669557-20893b74-8ff6-43bf-9768-9b431be23895.png width=800 height=300 />
|
||||
<img src=https://user-images.githubusercontent.com/63761690/189115968-c1d14ed3-dbdd-4a84-ac11-e9eaa447d40f.png width=800 height=300 />
|
||||
</div>
|
||||
|
||||
|
||||
@@ -79,18 +80,18 @@
|
||||
|
||||
【方案选择】提示学习(Prompt Learning)适用于**标注成本高、标注样本较少的文本分类场景**。在小样本场景中,相比于预训练模型微调学习,提示学习能取得更好的效果。对于标注样本充足、标注成本较低的场景,我们仍旧推荐使用充足的标注样本进行文本分类[预训练模型微调](#预训练模型微调)。
|
||||
|
||||
【方案介绍】**提示学习的主要思想是将文本分类任务转换为构造提示中掩码 `[MASK]` 的分类预测任务**,也即在掩码 `[MASK]`向量后接入线性层分类器预测掩码位置可能的字或词。提示学习使用待预测字的预训练向量来初始化分类器参数(如果待预测的是词,则为词中所有字的预训练向量平均值),充分利用预训练语言模型学习到的特征和标签文本,从而降低样本需求。提示学习同时提供[ R-Drop](https://arxiv.org/abs/2106.14448) 和 [RGL](https://aclanthology.org/2022.findings-naacl.81/) 策略,帮助提示模型效果。
|
||||
【方案介绍】**提示学习的主要思想是将文本分类任务转换为构造提示中掩码 `[MASK]` 的分类预测任务**,也即在掩码 `[MASK]`向量后接入线性层分类器预测掩码位置可能的字或词。提示学习使用待预测字的预训练向量来初始化分类器参数(如果待预测的是词,则为词中所有字的预训练向量平均值),充分利用预训练语言模型学习到的特征和标签文本,从而降低样本需求。提示学习同时提供[ R-Drop](https://arxiv.org/abs/2106.14448) 和 [RGL](https://aclanthology.org/2022.findings-naacl.81/) 策略,帮助提升模型效果。
|
||||
|
||||
我们以下图情感二分类任务为例来具体介绍提示学习流程,分类任务标签分为 `0:负向` 和 `1:正向` 。在文本加入构造提示 `我[MASK]喜欢。` ,将情感分类任务转化为预测掩码 `[MASK]` 的待预测字是 `不` 还是 `很`。具体实现方法是在掩码`[MASK]`的输出向量后接入线性分类器(二分类),然后用`不`和`很`的预训练向量来初始化分类器进行训练,分类器预测分类为 `0:不` 或 `1:很` 对应原始标签 `0:负向` 或 `1:正向`。而预训练模型微调则是在预训练模型`[CLS]`向量接入随机初始化线性分类器进行训练,分类器直接预测分类为 `0:负向` 或 `1:正向`。
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/25607475/183909263-6ead8871-699c-4c2d-951f-e33eddcfdd9c.png width=800 height=300 />
|
||||
<img src=https://user-images.githubusercontent.com/63761690/189114324-376025b6-8f4e-4d94-a135-953f53f20636.png width=800 height=300 />
|
||||
</div>
|
||||
|
||||
【方案效果】我们比较预训练模型微调与提示学习在多分类、多标签、层次分类小样本场景的模型表现(多分类精度为准确率,多标签和层次分类精度为Macro F1值),可以看到在样本较少的情况下,提示学习比预训练模型微调有明显优势。
|
||||
|
||||
<div align="center">
|
||||
<img width="600" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/187650189-18dc5d4c-66c6-459e-827e-8a8d67a24d42.jpeg">
|
||||
<img width="600" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/189114445-ee0dd6af-f102-4708-9f46-c630c572dfd3.png">
|
||||
</div>
|
||||
|
||||
|
||||
@@ -108,9 +109,12 @@
|
||||
|
||||
【方案介绍】语义索引目标是从海量候选召回集中快速、准确地召回一批与输入文本语义相关的文本。基于语义索引的文本分类方法具体来说是将标签集作为召回目标集,召回与输入文本语义相似的标签作为文本的标签类别。
|
||||
|
||||
<div align="center">
|
||||
<img src=https://user-images.githubusercontent.com/63761690/189114541-2278b7f7-1af6-470d-a300-28e7e902b6a8.png width=800 height=300 />
|
||||
</div>
|
||||
|
||||
【快速开始】
|
||||
- 快速开启多分类任务参见 👉 [语义索引-多分类指南](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_classification/multi_class/retrieval_based#readme)
|
||||
- 快速开启多标签分类任务参见 👉 [语义索引-多标签分类指南](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_classification/multi_label/retrieval_based#readme)
|
||||
- 快速开启层次分类任务参见 👉 [语义索引-层次分类指南](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_classification/hierarchical/retrieval_based#readme)
|
||||
|
||||
|
||||
@@ -136,24 +140,35 @@
|
||||
有这么一句话在业界广泛流传,"数据决定了机器学习的上限,而模型和算法只是逼近这个上限",可见数据质量的重要性。文本分类应用依托[TrustAI](https://github.com/PaddlePaddle/TrustAI)可信增强能力和[数据增强API](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/dataaug.md)开源了模型分析模块,针对标注数据质量不高、训练数据覆盖不足、样本数量少等文本分类常见数据痛点,提供稀疏数据筛选、脏数据清洗、数据增强三种数据优化方案,解决训练数据缺陷问题,用低成本方式获得大幅度的效果提升。
|
||||
|
||||
|
||||
- **稀疏数据筛选**基于特征相似度的实例级证据分析方法挖掘待预测数据中缺乏证据支持的数据(也即稀疏数据),并进行有选择的训练集数据增强或针对性筛选未标注数据进行标注来解决稀疏数据问题,有效提升模型表现。我们采用在多分类、多标签、层次分类场景中评测稀疏数据-数据增强策略和稀疏数据-数据标注策略,下图表明稀疏数据筛选方案在各场景能够有效提高模型表现(多分类精度为准确率,多标签和层次分类精度为Macro F1值)。
|
||||
- **稀疏数据筛选**基于特征相似度的实例级证据分析方法挖掘待预测数据中缺乏证据支持的数据(也即稀疏数据),并进行有选择的训练集数据增强或针对性筛选未标注数据进行标注来解决稀疏数据问题,有效提升模型表现。
|
||||
<div align="center">
|
||||
<img width="1000" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/189114644-c0d21801-dd6c-4530-b3a3-5f5a568a7a22.png">
|
||||
</div>
|
||||
|
||||
我们采用在多分类、多标签、层次分类场景中评测稀疏数据-数据增强策略和稀疏数据-数据标注策略,下图表明稀疏数据筛选方案在各场景能够有效提高模型表现(多分类精度为准确率,多标签和层次分类精度为Macro F1值)。
|
||||
|
||||
<div align="center">
|
||||
<img width="600" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/187650173-c83afc31-a1f8-478b-a391-b977d5170825.jpeg">
|
||||
<img width="600" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/189114660-820d1471-4907-4c73-a118-c494200afff0.png">
|
||||
</div>
|
||||
|
||||
|
||||
- **脏数据清洗**基于表示点方法的实例级证据分析方法,计算训练数据对模型的影响分数,分数高的训练数据表明对模型影响大,这些数据有较大概率为脏数据(标注错误样本)。脏数据清洗方案通过高效识别训练集中脏数据(也即标注质量差的数据),有效降低人力检查成本。我们采用在多分类、多标签、层次分类场景中评测脏数据清洗方案,实验表明方案能够高效筛选出训练集中脏数据,提高模型表现(多分类精度为准确率,多标签和层次分类精度为Macro F1值)。
|
||||
- **脏数据清洗**基于表示点方法的实例级证据分析方法,计算训练数据对模型的影响分数,分数高的训练数据表明对模型影响大,这些数据有较大概率为脏数据(标注错误样本)。脏数据清洗方案通过高效识别训练集中脏数据(也即标注质量差的数据),有效降低人力检查成本。
|
||||
|
||||
<div align="center">
|
||||
<img width="600" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/187652793-aec6dc9f-a709-431e-9d18-58e39719a1e5.jpeg">
|
||||
<img width="1000" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/189114677-9a2f5232-9551-4e10-a215-54ddb7ca1f33.png">
|
||||
</div>
|
||||
|
||||
我们采用在多分类、多标签、层次分类场景中评测脏数据清洗方案,实验表明方案能够高效筛选出训练集中脏数据,提高模型表现(多分类精度为准确率,多标签和层次分类精度为Macro F1值)。
|
||||
|
||||
<div align="center">
|
||||
<img width="600" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/189114695-90cef2fd-955d-4243-9fc4-78f2dcf7fb6c.png">
|
||||
</div>
|
||||
|
||||
|
||||
- **数据增强**在数据量较少的情况下能够通过增加数据集多样性,提升模型效果。PaddleNLP内置[数据增强API](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/dataaug.md),支持词替换、词删除、词插入、词置换、基于上下文生成词(MLM预测)、TF-IDF等多种数据增强策略。数据增强方案提供一行命令,快速完成数据集增强。以CAIL2019—婚姻家庭要素提取数据子集(500条)为例,我们在数据集应用多种数据增强策略,策略效果如下表。
|
||||
|
||||
<div align="center">
|
||||
<img width="600" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/187666776-53abc345-da7f-4f7e-ada4-8040577c8720.png">
|
||||
<img width="600" alt="文本分类落地难点" src="https://user-images.githubusercontent.com/63761690/189115071-40152f7c-7c90-41b3-a70b-4d4aabc5b715.png">
|
||||
</div>
|
||||
|
||||
|
||||
@@ -163,7 +178,7 @@
|
||||
|
||||
- 体验模型分析模块 👉 [多分类-模型分析模块](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_classification/multi_class/analysis)
|
||||
- 体验模型分析模块 👉 [多标签-模型分析模块](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_classification/multi_label/analysis)
|
||||
- 体验模型分析模块 👉 [层次分类多-模型分析模块](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_classification/hierarchical/analysis)
|
||||
- 体验模型分析模块 👉 [层次分类-模型分析模块](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_classification/hierarchical/analysis)
|
||||
|
||||
<a name="产业级全流程方案"></a>
|
||||
|
||||
@@ -172,7 +187,7 @@
|
||||
文本分类应用提供了简单易用的数据标注-模型训练-模型调优-模型压缩-预测部署全流程方案,我们将以预训练模型微调方案为例介绍文本分类应用的全流程:
|
||||
|
||||
<div align="center">
|
||||
<img width="900" alt="image" src="https://user-images.githubusercontent.com/63761690/187828356-e2f4f627-f5fe-4c83-8879-ed6951f7511e.png">
|
||||
<img width="900" alt="image" src="https://user-images.githubusercontent.com/63761690/189115101-20cbaa00-e549-425b-b047-61bac2a5e39f.png">
|
||||
</div>
|
||||
<div align="center">
|
||||
<font size ="2">
|
||||
@@ -198,7 +213,11 @@
|
||||
|
||||
**3.模型部署**
|
||||
|
||||
- 现实部署场景需要同时考虑模型的精度和性能表现。基于压缩API的模型裁剪能够进一步压缩模型体积,此外模型裁剪去掉了部分冗余参数的扰动,增加了模型的泛化能力,在部分任务预测精度得到提高。
|
||||
- 现实部署场景需要同时考虑模型的精度和性能表现,文本分类应用接入PaddleNLP 模型压缩 API 。采用了DynaBERT 中宽度自适应裁剪策略,对预训练模型多头注意力机制中的头(Head )进行重要性排序,保证更重要的头(Head )不容易被裁掉,然后用原模型作为蒸馏过程中的教师模型,宽度更小的模型作为学生模型,蒸馏得到的学生模型就是我们裁剪得到的模型。实验表明模型裁剪能够有效缩小模型体积、减少内存占用、提升推理速度。模型裁剪去掉了部分冗余参数的扰动,增加了模型的泛化能力,在部分任务中预测精度得到提高。
|
||||
|
||||
<div align="center">
|
||||
<img width="900" alt="image" src="https://user-images.githubusercontent.com/63761690/189115124-2f429043-3145-4bf8-9969-47580a706037.png">
|
||||
</div>
|
||||
|
||||
- 模型部署需要将保存的最佳模型参数(动态图参数)导出成静态图参数,用于后续的推理部署。p.s.模型裁剪之后会默认导出静态图模型
|
||||
|
||||
@@ -214,3 +233,59 @@
|
||||
- 快速开启多标签分类 👉 [多标签指南](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_classification/multi_label#readme)
|
||||
|
||||
- 快速开启层次分类 👉 [层次分类指南](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/applications/text_classification/hierarchical#readme)
|
||||
|
||||
<a name="常用中文分类数据集"></a>
|
||||
|
||||
## 4. 常用中文分类数据集
|
||||
|
||||
**多分类数据集:**
|
||||
|
||||
- [THUCNews新闻分类数据集](http://thuctc.thunlp.org/)
|
||||
|
||||
- [百科问答分类数据集](https://github.com/brightmart/nlp_chinese_corpus#3%E7%99%BE%E7%A7%91%E7%B1%BB%E9%97%AE%E7%AD%94json%E7%89%88baike2018qa)
|
||||
|
||||
- [头条新闻标题数据集TNEWS](https://github.com/aceimnorstuvwxz/toutiao-text-classfication-dataset)
|
||||
|
||||
- [复旦新闻文本数据集](https://www.heywhale.com/mw/dataset/5d3a9c86cf76a600360edd04)
|
||||
|
||||
- [IFLYTEK app应用描述分类数据集](https://storage.googleapis.com/cluebenchmark/tasks/iflytek_public.zip)
|
||||
|
||||
- [CAIL 2022事件检测](https://cloud.tsinghua.edu.cn/d/6e911ff1286d47db8016/)
|
||||
|
||||
**情感分类数据集(多分类):**
|
||||
|
||||
- [亚马逊商品评论情感数据集](https://github.com/SophonPlus/ChineseNlpCorpus/blob/master/datasets/yf_amazon/intro.ipynb)
|
||||
|
||||
- [财经新闻情感分类数据集](https://github.com/wwwxmu/Dataset-of-financial-news-sentiment-classification)
|
||||
|
||||
- [ChnSentiCorp 酒店评论情感分类数据集](https://github.com/SophonPlus/ChineseNlpCorpus/tree/master/datasets/ChnSentiCorp_htl_all)
|
||||
|
||||
- [外卖评论情感分类数据集](https://github.com/SophonPlus/ChineseNlpCorpus/blob/master/datasets/waimai_10k/intro.ipynb)
|
||||
|
||||
- [weibo情感二分类数据集](https://github.com/SophonPlus/ChineseNlpCorpus/blob/master/datasets/weibo_senti_100k/intro.ipynb)
|
||||
|
||||
- [weibo情感四分类数据集](https://github.com/SophonPlus/ChineseNlpCorpus/blob/master/datasets/simplifyweibo_4_moods/intro.ipynb)
|
||||
|
||||
- [商品评论情感分类数据集](https://github.com/SophonPlus/ChineseNlpCorpus/blob/master/datasets/online_shopping_10_cats/intro.ipynb)
|
||||
|
||||
- [电影评论情感分类数据集](https://github.com/SophonPlus/ChineseNlpCorpus/blob/master/datasets/dmsc_v2/intro.ipynb)
|
||||
|
||||
- [大众点评分类数据集](https://github.com/SophonPlus/ChineseNlpCorpus/blob/master/datasets/yf_dianping/intro.ipynb)
|
||||
|
||||
**多标签数据集:**
|
||||
|
||||
- [学生评语分类数据集](https://github.com/FBI1314/textClassification/tree/master/multilabel_text_classfication/data)
|
||||
|
||||
- [CAIL2019婚姻要素识别](https://aistudio.baidu.com/aistudio/projectdetail/3996601)
|
||||
|
||||
- [CAIL2018 刑期预测、法条预测、罪名预测](https://cail.oss-cn-qingdao.aliyuncs.com/CAIL2018_ALL_DATA.zip)
|
||||
|
||||
**层次分类数据集:**
|
||||
|
||||
- [头条新闻标题分类-TNEWS的升级版](https://github.com/aceimnorstuvwxz/toutiao-multilevel-text-classfication-dataset)
|
||||
|
||||
- [网页层次分类数据集](https://csri.scu.edu.cn/info/1012/2827.htm)
|
||||
|
||||
- [医学意图数据集(CMID)](https://github.com/liutongyang/CMID)
|
||||
|
||||
- [2020语言与智能技术竞赛事件分类](https://github.com/percent4/keras_bert_multi_label_cls/tree/master/data)
|
||||
|
||||
@@ -36,7 +36,7 @@
|
||||
|
||||
- 【标注成本高、标注样本较少的小样本场景】 👉 [提示学习层次分类方案](./few-shot#readme)
|
||||
|
||||
- 【标签类别不固定场景】 👉 [语义索引层次分类方案](./retrieval_based#readme)
|
||||
- 【标签类别不固定场景、标签数量众多】 👉 [语义索引层次分类方案](./retrieval_based#readme)
|
||||
|
||||
<a name="快速开始"></a>
|
||||
|
||||
@@ -65,7 +65,7 @@ rm baidu_extract_2020.tar.gz
|
||||
|
||||
- python >= 3.6
|
||||
- paddlepaddle >= 2.3
|
||||
- paddlenlp >= 2.3.4
|
||||
- paddlenlp >= 2.4
|
||||
- scikit-learn >= 1.0.2
|
||||
|
||||
**安装PaddlePaddle:**
|
||||
@@ -77,7 +77,7 @@ rm baidu_extract_2020.tar.gz
|
||||
|
||||
安装PaddleNLP默认开启百度镜像源来加速下载,如果您使用 HTTP 代理可以关闭(删去 -i https://mirror.baidu.com/pypi/simple),更多关于PaddleNLP安装的详细教程请查见[PaddleNLP快速安装](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/get_started/installation.rst)。
|
||||
```shell
|
||||
python3 -m pip install paddlenlp==2.3.4 -i https://mirror.baidu.com/pypi/simple
|
||||
python3 -m pip install --upgrade paddlenlp -i https://mirror.baidu.com/pypi/simple
|
||||
```
|
||||
|
||||
|
||||
@@ -92,20 +92,13 @@ python3 -m pip install scikit-learn==1.0.2
|
||||
|
||||
```text
|
||||
hierarchical/
|
||||
├── few-shot # 小样本学习方案
|
||||
├── retrieval_based # 语义索引方案
|
||||
├── analysis # 分析模块
|
||||
├── deploy # 部署
|
||||
│ └── predictor # 离线部署
|
||||
│ │ ├── infer.py # 测试脚本
|
||||
│ │ ├── predictor.py 离线部署脚本
|
||||
│ │ └── README.md # 离线部署使用说明
|
||||
│ ├── paddle_serving # PaddleServing在线服务化部署
|
||||
│ │ ├──config.yml # 服务端的配置文件
|
||||
│ │ ├──rpc_client.py # 客户端预测脚本
|
||||
│ │ ├──service.py # 服务端的脚本
|
||||
│ │ └── README.md # 在线服务化部署使用说明
|
||||
│ └── triton_serving # Triton在线服务化部署
|
||||
│ ├── README.md # Triton部署使用说明
|
||||
│ ├── seqcls_grpc_client.py # 客户端预测脚本
|
||||
│ └── models
|
||||
├── train.py # 训练评估脚本
|
||||
├── predict.py # 预测脚本
|
||||
├── export_model.py # 静态图模型导出脚本
|
||||
@@ -130,7 +123,7 @@ data/
|
||||
└── data.txt # 待预测数据文件(可选)
|
||||
```
|
||||
|
||||
**训练、开发、测试数据集文件:** 文本与标签类别名用tab符`'\t'`分隔开,标签中多个标签之间用英文逗号`','`分隔开。
|
||||
**训练、开发、测试数据集文件:** 文本与标签类别名用tab符`'\t'`分隔开,标签中多个标签之间用英文逗号`','`分隔开,文本中避免出现tab符`'\t'`。
|
||||
|
||||
- train.txt/dev.txt/test.txt 文件格式:
|
||||
```text
|
||||
@@ -188,8 +181,6 @@ data/
|
||||
|
||||
### 2.4 模型训练
|
||||
|
||||
|
||||
|
||||
#### 2.4.1 预训练模型微调
|
||||
|
||||
使用CPU/GPU训练,默认为GPU训练,使用CPU训练只需将设备参数配置改为`--device "cpu"`:
|
||||
@@ -200,19 +191,20 @@ python train.py \
|
||||
--max_seq_length 128 \
|
||||
--model_name "ernie-3.0-medium-zh" \
|
||||
--batch_size 32 \
|
||||
--early_stop
|
||||
--early_stop \
|
||||
--epochs 100
|
||||
```
|
||||
|
||||
|
||||
如果在CPU环境下训练,可以指定`nproc_per_node`参数进行多核训练:
|
||||
```shell
|
||||
python -m paddle.distributed.launch --nproc_per_node 8 --backend "gloo" train.py \
|
||||
--dataset_dir "data" \
|
||||
--device "gpu" \
|
||||
--device "cpu" \
|
||||
--max_seq_length 128 \
|
||||
--model_name "ernie-3.0-medium-zh" \
|
||||
--batch_size 32 \
|
||||
--early_stop
|
||||
--early_stop \
|
||||
--epochs 100
|
||||
```
|
||||
|
||||
如果在GPU环境中使用,可以指定`gpus`参数进行单卡/多卡训练。使用多卡训练可以指定多个GPU卡号,例如 --gpus "0,1"。如果设备只有一个GPU卡号默认为0,可使用`nvidia-smi`命令查看GPU使用情况。
|
||||
@@ -225,7 +217,8 @@ python -m paddle.distributed.launch --gpus "0" train.py \
|
||||
--max_seq_length 128 \
|
||||
--model_name "ernie-3.0-medium-zh" \
|
||||
--batch_size 32 \
|
||||
--early_stop
|
||||
--early_stop \
|
||||
--epochs 100
|
||||
```
|
||||
|
||||
|
||||
@@ -235,7 +228,7 @@ python -m paddle.distributed.launch --gpus "0" train.py \
|
||||
* `dataset_dir`:必须,本地数据集路径,数据集路径中应包含train.txt,dev.txt和label.txt文件;默认为None。
|
||||
* `save_dir`:保存训练模型的目录;默认保存在当前目录checkpoint文件夹下。
|
||||
* `max_seq_length`:分词器tokenizer使用的最大序列长度,ERNIE模型最大不能超过2048。请根据文本长度选择,通常推荐128、256或512,若出现显存不足,请适当调低这一参数;默认为128。
|
||||
* `model_name`:选择预训练模型,可选"ernie-3.0-xbase-zh", "ernie-3.0-base-zh", "ernie-3.0-medium-zh", "ernie-3.0-micro-zh", "ernie-3.0-mini-zh", "ernie-3.0-nano-zh", "ernie-2.0-base-en", "ernie-2.0-large-en","ernie-1.0-large-zh-cw";默认为"ernie-3.0-medium-zh"。
|
||||
* `model_name`:选择预训练模型,可选"ernie-1.0-large-zh-cw","ernie-3.0-xbase-zh", "ernie-3.0-base-zh", "ernie-3.0-medium-zh", "ernie-3.0-micro-zh", "ernie-3.0-mini-zh", "ernie-3.0-nano-zh", "ernie-2.0-base-en", "ernie-2.0-large-en","ernie-m-base","ernie-m-large";默认为"ernie-3.0-medium-zh",根据任务复杂度和硬件条件进行选择。
|
||||
* `batch_size`:批处理大小,请结合显存情况进行调整,若出现显存不足,请适当调低这一参数;默认为32。
|
||||
* `learning_rate`:训练最大学习率;默认为3e-5。
|
||||
* `epochs`: 训练轮次,使用早停法时可以选择100;默认为10。
|
||||
@@ -263,14 +256,20 @@ checkpoint/
|
||||
|
||||
**NOTE:**
|
||||
* 如需恢复模型训练,则可以设置 `--init_from_ckpt checkpoint/model_state.pdparams` 。
|
||||
* 如需训练英文文本分类任务,只需更换预训练模型参数 `model_name` 。英文训练任务推荐使用"ernie-2.0-base-en",更多可选模型可参考[Transformer预训练模型](https://paddlenlp.readthedocs.io/zh/latest/model_zoo/index.html#transformer)。
|
||||
* 英文和中文以外文本分类任务建议使用多语言预训练模型"ernie-m-base","ernie-m-large", 多语言模型暂不支持文本分类模型部署,相关功能正在加速开发中。
|
||||
* 如需训练英文文本分类任务,只需更换预训练模型参数 `model_name` 。英文训练任务推荐使用"ernie-2.0-base-en"、"ernie-2.0-large-en"。
|
||||
* 英文和中文以外语言的文本分类任务,推荐使用基于96种语言(涵盖法语、日语、韩语、德语、西班牙语等几乎所有常见语言)进行预训练的多语言预训练模型"ernie-m-base"、"ernie-m-large",详情请参见[ERNIE-M论文](https://arxiv.org/pdf/2012.15674.pdf)。
|
||||
#### 2.4.2 训练评估与模型优化
|
||||
|
||||
训练后的模型我们可以使用 [模型分析模块](./analysis) 对每个类别分别进行评估,并输出预测错误样本(bad case),默认在GPU环境下使用,在CPU环境下修改参数配置为`--device "cpu"`:
|
||||
文本分类预测过程中常会遇到诸如"模型为什么会预测出错误的结果","如何提升模型的表现"等问题。[Analysis模块](./analysis) 提供了**模型评估、可解释性分析、数据优化**等功能,旨在帮助开发者更好地分析文本分类模型预测结果和对模型效果进行优化。
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/63761690/195241942-70068989-df17-4f53-9f71-c189d8c5c88d.png" width="600">
|
||||
</div>
|
||||
|
||||
**模型评估:** 训练后的模型我们可以使用 [Analysis模块](./analysis) 对每个类别分别进行评估,并输出预测错误样本(bad case),默认在GPU环境下使用,在CPU环境下修改参数配置为`--device "cpu"`:
|
||||
|
||||
```shell
|
||||
python analysis/evaluate.py --device "gpu" --max_seq_length 128 --batch_size 32 --bad_case_path "./bad_case.txt" --dataset_dir "data" --params_path "./checkpoint"
|
||||
python analysis/evaluate.py --device "gpu" --max_seq_length 128 --batch_size 32 --bad_case_file "bad_case.txt" --dataset_dir "data" --params_path "./checkpoint"
|
||||
```
|
||||
|
||||
输出打印示例:
|
||||
@@ -297,15 +296,38 @@ python analysis/evaluate.py --device "gpu" --max_seq_length 128 --batch_size 32
|
||||
预测错误的样本保存在bad_case.txt文件中:
|
||||
|
||||
```text
|
||||
Prediction Label Text
|
||||
组织关系,组织关系##解雇 组织关系,组织关系##加盟,组织关系##裁员 据猛龙随队记者JoshLewenberg报道,消息人士透露,猛龙已将前锋萨加巴-科纳特裁掉。此前他与猛龙签下了一份Exhibit10合同。在被裁掉后,科纳特下赛季大概率将前往猛龙的发展联盟球队效力。
|
||||
组织关系,组织关系##解雇 组织关系,组织关系##裁员 冠军射手被裁掉,欲加入湖人队,但湖人却无意,冠军射手何去何从
|
||||
组织关系,组织关系##裁员 组织关系,组织关系##退出,组织关系##裁员 有多名魅族员工表示,从6月份开始,魅族开始了新一轮裁员,重点裁员区域是营销和线下。裁员占比超过30%,剩余员工将不过千余人,魅族的知名工程师,爱讲真话的洪汉生已经从钉钉里退出了,外界传言说他去了OPPO。
|
||||
人生,人生##死亡,灾害/意外,灾害/意外##坍/垮塌 灾害/意外,灾害/意外##坍/垮塌 冲刺千亿的美的置业贵阳项目倒塌致8人死亡已责令全面停工
|
||||
Text Label Prediction
|
||||
据猛龙随队记者JoshLewenberg报道,消息人士透露,猛龙已将前锋萨加巴-科纳特裁掉。此前他与猛龙签下了一份Exhibit10合同。在被裁掉后,科纳特下赛季大概率将前往猛龙的发展联盟球队效力。 组织关系,组织关系##加盟,组织关系##裁员 组织关系,组织关系##解雇
|
||||
冠军射手被裁掉,欲加入湖人队,但湖人却无意,冠军射手何去何从 组织关系,组织关系##裁员 组织关系,组织关系##解雇
|
||||
6月7日报道,IBM将裁员超过1000人。IBM周四确认,将裁减一千多人。据知情人士称,此次裁员将影响到约1700名员工,约占IBM全球逾34万员工中的0.5%。IBM股价今年累计上涨16%,但该公司4月发布的财报显示,一季度营收下降5%,低于市场预期。 组织关系,组织关系##裁员 组织关系,组织关系##裁员,财经/交易
|
||||
有多名魅族员工表示,从6月份开始,魅族开始了新一轮裁员,重点裁员区域是营销和线下。裁员占比超过30%,剩余员工将不过千余人,魅族的知名工程师,爱讲真话的洪汉生已经从钉钉里退出了,外界传言说他去了OPPO。 组织关系,组织关系##退出,组织关系##裁员 组织关系,组织关系##裁员
|
||||
...
|
||||
```
|
||||
|
||||
模型表现常常受限于数据质量,在analysis模块中我们提供了基于[TrustAI](https://github.com/PaddlePaddle/TrustAI)的稀疏数据筛选、脏数据清洗、数据增强三种优化方案助力开发者提升模型效果,更多模型评估和优化方案细节详见[训练评估与模型优化指南](analysis/README.md)。
|
||||
**可解释性分析:** 基于[TrustAI](https://github.com/PaddlePaddle/TrustAI)提供单词和句子级别的模型可解释性分析,帮助理解模型预测结果,用于错误样本(bad case)分析,细节详见[训练评估与模型优化指南](analysis/README.md)。
|
||||
|
||||
- 单词级别可解释性分析,也即分析待预测样本中哪一些单词对模型预测结果起重要作用。以下图为例,用颜色深浅表示单词对预测结果的重要性。
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/63761690/195334753-78cc2dc8-a5ba-4460-9fde-3b1bb704c053.png" width="1000">
|
||||
</div>
|
||||
|
||||
- 句子级别可解释性分析 ,也即分析对待预测样本的模型预测结果与训练集中中哪些样本有重要关系。下面的例子表明句子级别可解释性分析可以帮助理解待预测样本的预测结果与训练集中样本之间的关联。
|
||||
```text
|
||||
text: 据猛龙随队记者JoshLewenberg报道,消息人士透露,猛龙已将前锋萨加巴-科纳特裁掉。此前他与猛龙签下了一份Exhibit10合同。在被裁掉后,科纳特下赛季大概率将前往猛龙的发展联盟球队效力。
|
||||
predict label: 组织关系,组织关系##解雇
|
||||
label: 组织关系,组织关系##加盟,组织关系##裁员
|
||||
examples with positive influence
|
||||
support1 text: 尼克斯官方今日宣布,他们已经裁掉了前锋扎克-欧文,后者昨日才与尼克斯签约。 label: 组织关系,组织关系##加盟,组织关系##解雇 score: 0.99357
|
||||
support2 text: 活塞官方今日宣布,他们已经签下了克雷格-斯沃德,并且裁掉了托德-威瑟斯。 label: 组织关系,组织关系##加盟,组织关系##解雇 score: 0.98344
|
||||
support3 text: 孟菲斯灰熊今年宣布,球队已经签下后卫达斯蒂-汉纳斯(DustyHannahs,版头图)并裁掉马特-穆尼。 label: 组织关系,组织关系##加盟,组织关系##解雇 score: 0.98219
|
||||
...
|
||||
```
|
||||
|
||||
**数据优化:** 结合[TrustAI](https://github.com/PaddlePaddle/TrustAI)和[数据增强API](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/dataaug.md)提供了**稀疏数据筛选、脏数据清洗、数据增强**三种优化策略,从多角度优化训练数据提升模型效果,策略细节详见[训练评估与模型优化指南](analysis/README.md)。
|
||||
|
||||
- 稀疏数据筛选主要是解决数据不均衡、训练数据覆盖不足的问题,通过数据增强和数据标注两种方式解决这一问题。
|
||||
- 脏数据清洗可以帮助开发者筛选训练集中错误标注的数据,对这些数据重新进行人工标注,得到标注正确的数据再重新进行训练。
|
||||
- 数据增强策略提供多种数据增强方案,可以快速扩充数据,提高模型泛化性和鲁棒性。
|
||||
|
||||
#### 2.4.3 模型预测
|
||||
训练结束后,输入待预测数据(data.txt)和类别标签对照列表(label.txt),使用训练好的模型进行,默认在GPU环境下使用,在CPU环境下修改参数配置为`--device "cpu"`:
|
||||
@@ -337,8 +359,13 @@ python predict.py --device "gpu" --max_seq_length 128 --batch_size 32 --dataset_
|
||||
python export_model.py --params_path ./checkpoint/ --output_path ./export
|
||||
```
|
||||
|
||||
可支持配置的参数:
|
||||
如果使用多语言模型 ERNIE M作为预训练模型,运行方式:
|
||||
```shell
|
||||
python export_model.py --params_path ./checkpoint/ --output_path ./export --multilingual
|
||||
```
|
||||
|
||||
可支持配置的参数:
|
||||
* `multilingual`:是否为多语言任务(是否使用ERNIE M作为预训练模型);默认为False。
|
||||
* `params_path`:动态图训练保存的参数路径;默认为"./checkpoint/"。
|
||||
* `output_path`:静态图图保存的参数路径;默认为"./export"。
|
||||
|
||||
@@ -397,9 +424,9 @@ python prune.py \
|
||||
```text
|
||||
prune/
|
||||
├── width_mult_0.75
|
||||
│ ├── float32.pdiparams
|
||||
│ ├── float32.pdiparams.info
|
||||
│ ├── float32.pdmodel
|
||||
│ ├── pruned_model.pdiparams
|
||||
│ ├── pruned_model.pdiparams.info
|
||||
│ ├── pruned_model.pdmodel
|
||||
│ ├── model_state.pdparams
|
||||
│ └── model_config.json
|
||||
└── ...
|
||||
@@ -413,7 +440,6 @@ prune/
|
||||
|
||||
3. ERNIE Base、Medium、Mini、Micro、Nano的模型宽度(multi head数量)为12,ERNIE Xbase、Large 模型宽度(multi head数量)为16,保留比例`width_mult`乘以宽度(multi haed数量)应为整数。
|
||||
|
||||
|
||||
#### 2.5.3 部署方案
|
||||
|
||||
- 离线部署搭建请参考[离线部署](deploy/predictor/README.md)。
|
||||
@@ -454,11 +480,13 @@ prune/
|
||||
|
||||
| | 模型结构 |Micro F1(%) | Macro F1(%) | latency(ms) |
|
||||
| -------------------------- | ------------ | ------------ | ------------ |------------ |
|
||||
|ERNIE 3.0 Base |12-layer, 768-hidden, 12-heads|95.68|93.39| 4.63 |
|
||||
|ERNIE 3.0 Medium| 6-layer, 768-hidden, 12-heads|95.26|93.22| 2.42|
|
||||
|ERNIE 3.0 Mini|6-layer, 384-hidden, 12-heads|94.72|93.03| 0.93|
|
||||
|ERNIE 3.0 Micro | 4-layer, 384-hidden, 12-heads|94.24|93.08| 0.70|
|
||||
|ERNIE 3.0 Nano |4-layer, 312-hidden, 12-heads|93.98|91.25|0.54|
|
||||
|ERNIE 1.0 Large Cw |24-layer, 1024-hidden, 20-heads|96.24|94.24 |5.59 |
|
||||
|ERNIE 3.0 Xbase |20-layer, 1024-hidden, 16-heads|96.21|94.13| 5.51 |
|
||||
|ERNIE 3.0 Base |12-layer, 768-hidden, 12-heads|95.68|93.39| 2.01 |
|
||||
|ERNIE 3.0 Medium| 6-layer, 768-hidden, 12-heads|95.26|93.22| 1.01|
|
||||
|ERNIE 3.0 Mini|6-layer, 384-hidden, 12-heads|94.72|93.03| 0.36|
|
||||
|ERNIE 3.0 Micro | 4-layer, 384-hidden, 12-heads|94.24|93.08| 0.24|
|
||||
|ERNIE 3.0 Nano |4-layer, 312-hidden, 12-heads|93.98|91.25|0.19|
|
||||
| ERNIE 3.0 Medium + 裁剪(保留比例3/4)|6-layer, 768-hidden, 9-heads| 95.45|93.40| 0.81 |
|
||||
| ERNIE 3.0 Medium + 裁剪(保留比例2/3)|6-layer, 768-hidden, 8-heads| 95.23|93.27 | 0.74 |
|
||||
| ERNIE 3.0 Medium + 裁剪(保留比例1/2)|6-layer, 768-hidden, 6-heads| 94.92 | 92.70| 0.61 |
|
||||
|
||||
@@ -1,18 +1,29 @@
|
||||
# 层次分类训练评估与模型优化指南
|
||||
# 训练评估与模型优化指南
|
||||
|
||||
**目录**
|
||||
* [analysis模块介绍](#analysis模块介绍)
|
||||
* [Analysis模块介绍](#Analysis模块介绍)
|
||||
* [环境准备](#环境准备)
|
||||
* [模型评估](#模型评估)
|
||||
* [稀疏数据筛选方案](#稀疏数据筛选方案)
|
||||
* [脏数据清洗方案](#脏数据清洗方案)
|
||||
* [数据增强策略方案](#数据增强策略方案)
|
||||
* [可解释性分析](#可解释性分析)
|
||||
* [单词级别可解释性分析](#单词级别可解释性分析)
|
||||
* [句子级别可解释性分析](#句子级别可解释性分析)
|
||||
* [数据优化](#数据优化)
|
||||
* [稀疏数据筛选方案](#稀疏数据筛选方案)
|
||||
* [脏数据清洗方案](#脏数据清洗方案)
|
||||
* [数据增强策略方案](#数据增强策略方案)
|
||||
|
||||
## analysis模块介绍
|
||||
## Analysis模块介绍
|
||||
|
||||
analysis模块提供了**模型评估**脚本对整体分类情况和每个类别分别进行评估,并打印预测错误样本,帮助开发者分析模型表现找到训练和预测数据中存在的问题问题。同时基于[可信AI工具集](https://github.com/PaddlePaddle/TrustAI)和[数据增强API](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/dataaug.md)提供了**稀疏数据筛选、脏数据清洗、数据增强**三种优化方案从多角度帮助开发者提升模型效果。
|
||||
Analysis模块提供了**模型评估、可解释性分析、数据优化**等功能,旨在帮助开发者更好地分析文本分类模型预测结果和对模型效果进行优化。
|
||||
|
||||
- **模型评估:** 对整体分类情况和每个类别分别进行评估,并打印预测错误样本,帮助开发者分析模型表现找到训练和预测数据中存在的问题。
|
||||
|
||||
- **可解释性分析:** 基于[TrustAI](https://github.com/PaddlePaddle/TrustAI)提供单词和句子级别的模型可解释性分析,帮助理解模型预测结果。
|
||||
|
||||
- **数据优化:** 结合[TrustAI](https://github.com/PaddlePaddle/TrustAI)和[数据增强API](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/dataaug.md)提供了**稀疏数据筛选、脏数据清洗、数据增强**三种优化策略,从多角度优化训练数据提升模型效果。
|
||||
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/63761690/184790352-7f91da02-aadd-48fe-9130-8323a89c6a43.jpg" width="600">
|
||||
<img src="https://user-images.githubusercontent.com/63761690/195241942-70068989-df17-4f53-9f71-c189d8c5c88d.png" width="600">
|
||||
</div>
|
||||
|
||||
以下是本项目主要代码结构及说明:
|
||||
@@ -20,10 +31,27 @@ analysis模块提供了**模型评估**脚本对整体分类情况和每个类
|
||||
```text
|
||||
analysis/
|
||||
├── evaluate.py # 评估脚本
|
||||
├── sent_interpret.py # 句子级别可解释性分析脚本
|
||||
├── word_interpret.py # 单词级别可解释性分析notebook
|
||||
├── sparse.py # 稀疏数据筛选脚本
|
||||
├── dirty.py # 脏数据清洗脚本
|
||||
├── aug.py # 数据增强脚本
|
||||
└── README.md # 层次分类训练评估与模型优化指南
|
||||
└── README.md # 训练评估与模型优化指南
|
||||
```
|
||||
|
||||
## 环境准备
|
||||
需要可解释性分析和数据优化需要安装相关环境。
|
||||
- trustai >= 0.1.7
|
||||
- interpretdl >= 0.7.0
|
||||
|
||||
**安装TrustAI**(可选)如果使用可解释性分析和数据优化中稀疏数据筛选和脏数据清洗需要安装TrustAI。
|
||||
```shell
|
||||
pip install trustai==0.1.7
|
||||
```
|
||||
|
||||
**安装InterpretDL**(可选)如果使用词级别可解释性分析GradShap方法,需要安装InterpretDL
|
||||
```shell
|
||||
pip install interpretdl==0.7.0
|
||||
```
|
||||
|
||||
## 模型评估
|
||||
@@ -37,14 +65,14 @@ python evaluate.py \
|
||||
--params_path "../checkpoint" \
|
||||
--max_seq_length 128 \
|
||||
--batch_size 32 \
|
||||
--bad_case_path "./bad_case.txt"
|
||||
--bad_case_file "bad_case.txt"
|
||||
```
|
||||
|
||||
默认在GPU环境下使用,在CPU环境下修改参数配置为`--device "cpu"`
|
||||
|
||||
可支持配置的参数:
|
||||
|
||||
* `device`: 选用什么设备进行训练,选择cpu、gpu、xpu、npu;默认为"gpu"。
|
||||
* `device`: 选用什么设备进行训练,可选择cpu、gpu、xpu、npu;默认为"gpu"。
|
||||
* `dataset_dir`:必须,本地数据集路径,数据集路径中应包含train.txt、dev.txt和label.txt文件;默认为None。
|
||||
* `params_path`:保存训练模型的目录;默认为"../checkpoint/"。
|
||||
* `max_seq_length`:分词器tokenizer使用的最大序列长度,ERNIE模型最大不能超过2048。请根据文本长度选择,通常推荐128、256或512,若出现显存不足,请适当调低这一参数;默认为128。
|
||||
@@ -54,6 +82,7 @@ python evaluate.py \
|
||||
* `label_file`:本地数据集中标签集文件名;默认为"label.txt"。
|
||||
* `bad_case_path`:开发集中预测错误样本保存路径;默认为"/bad_case.txt"。
|
||||
|
||||
|
||||
输出打印示例:
|
||||
|
||||
```text
|
||||
@@ -78,30 +107,109 @@ python evaluate.py \
|
||||
预测错误的样本保存在bad_case.txt文件中:
|
||||
|
||||
```text
|
||||
Prediction Label Text
|
||||
组织关系,组织关系##解雇 组织关系,组织关系##加盟,组织关系##裁员 据猛龙随队记者JoshLewenberg报道,消息人士透露,猛龙已将前锋萨加巴-科纳特裁掉。此前他与猛龙签下了一份Exhibit10合同。在被裁掉后,科纳特下赛季大概率将前往猛龙的发展联盟球队效力。
|
||||
组织关系,组织关系##解雇 组织关系,组织关系##裁员 冠军射手被裁掉,欲加入湖人队,但湖人却无意,冠军射手何去何从
|
||||
组织关系,组织关系##裁员 组织关系,组织关系##退出,组织关系##裁员 有多名魅族员工表示,从6月份开始,魅族开始了新一轮裁员,重点裁员区域是营销和线下。裁员占比超过30%,剩余员工将不过千余人,魅族的知名工程师,爱讲真话的洪汉生已经从钉钉里退出了,外界传言说他去了OPPO。
|
||||
人生,人生##死亡,灾害/意外,灾害/意外##坍/垮塌 灾害/意外,灾害/意外##坍/垮塌 冲刺千亿的美的置业贵阳项目倒塌致8人死亡已责令全面停工
|
||||
Text Label Prediction
|
||||
据猛龙随队记者JoshLewenberg报道,消息人士透露,猛龙已将前锋萨加巴-科纳特裁掉。此前他与猛龙签下了一份Exhibit10合同。在被裁掉后,科纳特下赛季大概率将前往猛龙的发展联盟球队效力。 组织关系,组织关系##加盟,组织关系##裁员 组织关系,组织关系##解雇
|
||||
冠军射手被裁掉,欲加入湖人队,但湖人却无意,冠军射手何去何从 组织关系,组织关系##裁员 组织关系,组织关系##解雇
|
||||
6月7日报道,IBM将裁员超过1000人。IBM周四确认,将裁减一千多人。据知情人士称,此次裁员将影响到约1700名员工,约占IBM全球逾34万员工中的0.5%。IBM股价今年累计上涨16%,但该公司4月发布的财报显示,一季度营收下降5%,低于市场预期。 组织关系,组织关系##裁员 组织关系,组织关系##裁员,财经/交易
|
||||
有多名魅族员工表示,从6月份开始,魅族开始了新一轮裁员,重点裁员区域是营销和线下。裁员占比超过30%,剩余员工将不过千余人,魅族的知名工程师,爱讲真话的洪汉生已经从钉钉里退出了,外界传言说他去了OPPO。 组织关系,组织关系##退出,组织关系##裁员 组织关系,组织关系##裁员
|
||||
...
|
||||
```
|
||||
|
||||
## 稀疏数据筛选方案
|
||||
## 可解释性分析
|
||||
"模型为什么会预测出这个结果?"是文本分类任务开发者时常遇到的问题,如何分析错误样本(bad case)是文本分类任务落地中重要一环,本项目基于TrustAI开源了基于词级别和句子级别的模型可解释性分析方法,帮助开发者更好地理解文本分类模型与数据,有助于后续的模型优化与数据清洗标注。
|
||||
|
||||
稀疏数据指缺乏足够训练数据支持导致低置信度的待预测数据,简单来说,由于模型在训练过程中没有学习到足够与待预测样本相似的数据,模型难以正确预测样本所属类别。本项目中稀疏数据筛选基于TrustAI(可信AI)工具集,利用基于特征相似度的实例级证据分析方法,抽取开发集中样本的支持训练证据,并计算支持证据平均分(通常为得分前三的支持训练证据均分)。分数较低的样本表明其训练证据不足,在训练集中较为稀疏,实验表明模型在这些样本上表现也相对较差。更多细节详见[TrustAI](https://github.com/PaddlePaddle/TrustAI)和[实例级证据分析](https://github.com/PaddlePaddle/TrustAI/blob/main/trustai/interpretation/example_level/README.md)。
|
||||
### 单词级别可解释性分析
|
||||
本项目开源模型的词级别可解释性分析Notebook,提供LIME、Integrated Gradient、GradShap 三种分析方法,支持分析微调后模型的预测结果,开发者可以通过更改**数据目录**和**模型目录**在自己的任务中使用Jupyter Notebook进行数据分析。
|
||||
|
||||
稀疏数据筛选旨在开发集中挖掘缺乏训练证据支持的稀疏数据,通常可以采用**数据增强**或**少量数据标注**的两种低成本方式,提升模型预测效果。
|
||||
运行 [word_interpret.ipynb](./word_interpreter.ipynb) 代码,即可分析影响样本预测结果的关键词以及可视化所有词对预测结果的贡献情况,颜色越深代表这个词对预测结果影响越大:
|
||||
<div align="center">
|
||||
<img src="https://user-images.githubusercontent.com/63761690/195334753-78cc2dc8-a5ba-4460-9fde-3b1bb704c053.png" width="1000">
|
||||
</div>
|
||||
|
||||
**安装TrustAI**
|
||||
```shell
|
||||
pip install trustai==0.1.4
|
||||
### 句子级别可解释性分析
|
||||
本项目基于特征相似度([FeatureSimilarity](https://arxiv.org/abs/2104.04128))算法,计算对样本预测结果正影响的训练数据,帮助理解模型的预测结果与训练集数据的关系。
|
||||
|
||||
待分析数据文件`interpret_input_file`应为以下三种格式中的一种:
|
||||
**格式一:包括文本、标签、预测结果**
|
||||
```text
|
||||
<文本>'\t'<标签>'\t'<预测结果>
|
||||
...
|
||||
```
|
||||
|
||||
### 稀疏数据识别--数据增强
|
||||
**格式二:包括文本、标签**
|
||||
```text
|
||||
<文本>'\t'<标签>
|
||||
...
|
||||
```
|
||||
|
||||
这里我们将介绍稀疏数据识别--数据增强流程,首先使用数据增强脚本挖掘开发集中的稀疏数据,然后筛选训练集中对稀疏数据的支持数据进行数据增强,然后将得到的数据增强后的支持数据加入到训练集中进行训练。
|
||||
**格式三:只包括文本**
|
||||
```text
|
||||
<文本>
|
||||
准予原告胡某甲与被告韩某甲离婚。
|
||||
...
|
||||
```
|
||||
|
||||
现在我们进行稀疏数据识别--数据增强,得到新增训练数据:
|
||||
我们可以运行代码,得到支持样本模型预测结果的训练数据:
|
||||
```shell
|
||||
python sent_interpret.py \
|
||||
--device "gpu" \
|
||||
--dataset_dir "../data" \
|
||||
--params_path "../checkpoint/" \
|
||||
--max_seq_length 128 \
|
||||
--batch_size 16 \
|
||||
--top_k 3 \
|
||||
--train_file "train.txt" \
|
||||
--interpret_input_file "bad_case.txt" \
|
||||
--interpret_result_file "sent_interpret.txt"
|
||||
```
|
||||
|
||||
默认在GPU环境下使用,在CPU环境下修改参数配置为`--device "cpu"`
|
||||
|
||||
可支持配置的参数:
|
||||
|
||||
* `device`: 选用什么设备进行训练,可可选择cpu、gpu、xpu、npu;默认为"gpu"。
|
||||
* `dataset_dir`:必须,本地数据集路径,数据集路径中应包含dev.txt和label.txt文件;默认为None。
|
||||
* `params_path`:保存训练模型的目录;默认为"../checkpoint/"。
|
||||
* `max_seq_length`:分词器tokenizer使用的最大序列长度,ERNIE模型最大不能超过2048。请根据文本长度选择,通常推荐128、256或512,若出现显存不足,请适当调低这一参数;默认为128。
|
||||
* `batch_size`:批处理大小,请结合显存情况进行调整,若出现显存不足,请适当调低这一参数;默认为32。
|
||||
* `seed`:随机种子,默认为3。
|
||||
* `top_k`:筛选支持训练证据数量;默认为3。
|
||||
* `train_file`:本地数据集中训练集文件名;默认为"train.txt"。
|
||||
* `interpret_input_file`:本地数据集中待分析文件名;默认为"bad_case.txt"。
|
||||
* `interpret_result_file`:保存句子级别可解释性结果文件名;默认为"sent_interpret.txt"。
|
||||
|
||||
可解释性结果保存在 `interpret_result_file` 文件中:
|
||||
```text
|
||||
text: 据猛龙随队记者JoshLewenberg报道,消息人士透露,猛龙已将前锋萨加巴-科纳特裁掉。此前他与猛龙签下了一份Exhibit10合同。在被裁掉后,科纳特下赛季大概率将前往猛龙的发展联盟球队效力。
|
||||
predict label: 组织关系,组织关系##解雇
|
||||
label: 组织关系,组织关系##加盟,组织关系##裁员
|
||||
examples with positive influence
|
||||
support1 text: 尼克斯官方今日宣布,他们已经裁掉了前锋扎克-欧文,后者昨日才与尼克斯签约。 label: 组织关系,组织关系##加盟,组织关系##解雇 score: 0.99357
|
||||
support2 text: 活塞官方今日宣布,他们已经签下了克雷格-斯沃德,并且裁掉了托德-威瑟斯。 label: 组织关系,组织关系##加盟,组织关系##解雇 score: 0.98344
|
||||
support3 text: 孟菲斯灰熊今年宣布,球队已经签下后卫达斯蒂-汉纳斯(DustyHannahs,版头图)并裁掉马特-穆尼。 label: 组织关系,组织关系##加盟,组织关系##解雇 score: 0.98219
|
||||
...
|
||||
```
|
||||
|
||||
## 数据优化
|
||||
|
||||
### 稀疏数据筛选方案
|
||||
|
||||
稀疏数据筛选适用于文本分类中**数据不平衡或训练数据覆盖不足**的场景,简单来说,就是由于模型在训练过程中没有学习到足够与待预测样本相似的数据,模型难以正确预测样本所属类别的情况。稀疏数据筛选旨在开发集中挖掘缺乏训练证据支持的数据,通常可以采用**数据增强**或**少量数据标注**的两种低成本方式,提升模型在开发集的预测效果。
|
||||
|
||||
本项目中稀疏数据筛选基于TrustAI,利用基于特征相似度的实例级证据分析方法,抽取开发集中样本的支持训练证据,并计算支持证据平均分(通常为得分前三的支持训练证据均分)。分数较低的样本表明其训练证据不足,在训练集中较为稀疏,实验表明模型在这些样本上表现也相对较差。更多细节详见[TrustAI](https://github.com/PaddlePaddle/TrustAI)和[实例级证据分析](https://github.com/PaddlePaddle/TrustAI/blob/main/trustai/interpretation/example_level/README.md)。
|
||||
|
||||
|
||||
#### 稀疏数据识别—数据增强
|
||||
|
||||
这里我们将介绍稀疏数据识别—数据增强流程:
|
||||
|
||||
- **稀疏数据识别:** 挖掘开发集中的缺乏训练证据支持数据,记为稀疏数据集(Sparse Dataset);
|
||||
|
||||
- **数据增强**:将稀疏数据集在训练集中的支持证据应用数据增强策略,这些数据增强后的训练数据记为支持数据集(Support Dataset);
|
||||
|
||||
- **重新训练模型:** 将支持数据集加入到原有的训练集获得新的训练集,重新训练新的文本分类模型。
|
||||
|
||||
现在我们进行稀疏数据识别-数据增强,得到支持数据集:
|
||||
|
||||
```shell
|
||||
python sparse.py \
|
||||
@@ -119,14 +227,15 @@ python sparse.py \
|
||||
|
||||
可支持配置的参数:
|
||||
|
||||
* `device`: 选用什么设备进行训练,选择cpu、gpu、xpu、npu;默认为"gpu"。
|
||||
* `device`: 选用什么设备进行训练,可选择cpu、gpu、xpu、npu;默认为"gpu"。
|
||||
* `dataset_dir`:必须,本地数据集路径,数据集路径中应包含dev.txt和label.txt文件;默认为None。
|
||||
* `aug_strategy`:数据增强类型,可选"duplicate","substitute", "insert", "delete", "swap";默认为"substitute"。
|
||||
* `params_path`:保存训练模型的目录;默认为"../checkpoint/"。
|
||||
* `max_seq_length`:分词器tokenizer使用的最大序列长度,ERNIE模型最大不能超过2048。请根据文本长度选择,通常推荐128、256或512,若出现显存不足,请适当调低这一参数;默认为128。
|
||||
* `batch_size`:批处理大小,请结合显存情况进行调整,若出现显存不足,请适当调低这一参数;默认为32。
|
||||
* `seed`:随机种子,默认为3。
|
||||
* `rationale_num`:计算样本置信度时支持训练证据数量,默认为3。
|
||||
* `rationale_num_sparse`:筛选稀疏数据时计算样本置信度时支持训练证据数量;认为3。
|
||||
* `rationale_num_support`:筛选支持数据时计算样本置信度时支持训练证据数量,如果筛选的支持数据不够,可以适当增加;默认为6。
|
||||
* `sparse_num`:筛选稀疏数据数量,建议为开发集的10%~20%,默认为100。
|
||||
* `support_num`:用于数据增强的支持数据数量,建议为训练集的10%~20%,默认为100。
|
||||
* `support_threshold`:支持数据的阈值,只选择支持证据分数大于阈值作为支持数据,默认为0.7。
|
||||
@@ -155,9 +264,15 @@ cat ../data/train.txt ../data/support.txt > ../data/train_sparse_aug.txt
|
||||
|训练集+支持增强集(delete) |90.56| 80.26|
|
||||
|训练集+支持增强集(swap) |90.18|80.05|
|
||||
|
||||
### 稀疏数据识别--数据标注
|
||||
#### 稀疏数据识别-数据标注
|
||||
|
||||
这里我们将介绍稀疏数据识别--数据标注流程,首先使用数据增强脚本挖掘开发集中的稀疏数据,然后筛选对稀疏数据支持的未标注数据,然后将得到支持数据进行标注后加入到训练集中进行训练。
|
||||
本方案能够有针对性进行数据标注,相比于随机标注数据更好提高模型预测效果。这里我们将介绍稀疏数据识别-数据标注流程:
|
||||
|
||||
- **稀疏数据识别:** 挖掘开发集中的缺乏训练证据支持数据,记为稀疏数据集(Sparse Dataset);
|
||||
|
||||
- **数据标注**:在未标注数据集中筛选稀疏数据集的支持证据,并进行数据标注,记为支持数据集(Support Dataset);
|
||||
|
||||
- **重新训练模型:** 将支持数据集加入到原有的训练集获得新的训练集,重新训练新的文本分类模型。
|
||||
|
||||
现在我们进行稀疏数据识别--数据标注,得到待标注数据:
|
||||
|
||||
@@ -178,14 +293,15 @@ python sparse.py \
|
||||
|
||||
可支持配置的参数:
|
||||
|
||||
* `device`: 选用什么设备进行训练,选择cpu、gpu、xpu、npu;默认为"gpu"。
|
||||
* `device`: 选用什么设备进行训练,可选择cpu、gpu、xpu、npu;默认为"gpu"。
|
||||
* `dataset_dir`:必须,本地数据集路径,数据集路径中应包含dev.txt和label.txt文件;默认为None。
|
||||
* `annotate`:选择稀疏数据识别--数据标注模式;默认为False。
|
||||
* `params_path`:保存训练模型的目录;默认为"../checkpoint/"。
|
||||
* `max_seq_length`:分词器tokenizer使用的最大序列长度,ERNIE模型最大不能超过2048。请根据文本长度选择,通常推荐128、256或512,若出现显存不足,请适当调低这一参数;默认为128。
|
||||
* `batch_size`:批处理大小,请结合显存情况进行调整,若出现显存不足,请适当调低这一参数;默认为32。
|
||||
* `seed`:随机种子,默认为3。
|
||||
* `rationale_num`:计算样本置信度时支持训练证据数量,默认为3。
|
||||
* `rationale_num_sparse`:筛选稀疏数据时计算样本置信度时支持训练证据数量;认为3。
|
||||
* `rationale_num_support`:筛选支持数据时计算样本置信度时支持训练证据数量,如果筛选的支持数据不够,可以适当增加;默认为6。
|
||||
* `sparse_num`:筛选稀疏数据数量,建议为开发集的10%~20%,默认为100。
|
||||
* `support_num`:用于数据增强的支持数据数量,建议为训练集的10%~20%,默认为100。
|
||||
* `support_threshold`:支持数据的阈值,只选择支持证据分数大于阈值作为支持数据,默认为0.7。
|
||||
@@ -214,14 +330,13 @@ cat ../data/train.txt ../data/support.txt > ../data/train_sparse_annotate.txt
|
||||
|训练集+策略采样集(100) |91.12|**84.13**|
|
||||
|训练集+随机采样集(100) |**91.24**|81.66|
|
||||
|
||||
## 脏数据清洗方案
|
||||
### 脏数据清洗方案
|
||||
|
||||
训练数据标注质量对模型效果有较大影响,但受限于标注人员水平、标注任务难易程度等影响,训练数据中都存在一定比例的标注较差的数据(脏数据)。当标注数据规模较大时,数据标注检查就成为一个难题。本项目中脏数据清洗基于TrustAI(可信AI)工具集,利用基于表示点方法的实例级证据分析方法,计算训练数据对模型的影响分数,分数高的训练数据表明对模型影响大,这些数据有较大概率为脏数据(标注错误样本)。更多细节详见[TrustAI](https://github.com/PaddlePaddle/TrustAI)和[实例级证据分析](https://github.com/PaddlePaddle/TrustAI/blob/main/trustai/interpretation/example_level/README.md)。
|
||||
脏数据清洗方案是基于已训练好的文本分类模型,筛选出训练数据集中标注错误的数据,再由人工检查重新标注,获得标注正确的数据集进行重新训练。我们将介绍脏数据清洗流程:
|
||||
|
||||
**安装TrustAI**
|
||||
```shell
|
||||
pip install trustai==0.1.4
|
||||
```
|
||||
- **脏数据筛选:** 基于TrustAI中表示点方法,计算训练数据对文本分类模型的影响分数,分数高的训练数据表明对模型影响大,这些数据有较大概率为标注错误样本,记为脏数据集(Dirty Dataset)。
|
||||
|
||||
- **数据清洗、训练:** 将筛选出的脏数据由人工重新检查,为数据打上正确的标签。将清洗后的训练数据重新放入文本分类模型进行训练。
|
||||
|
||||
现在我们进行脏数据识别,脏数据保存在`"train_dirty.txt"`,剩余训练数据保存在`"train_dirty_rest.txt"`:
|
||||
|
||||
@@ -244,16 +359,16 @@ python dirty.py \
|
||||
* `dataset_dir`:必须,本地数据集路径,数据集路径中应包含train.txt和label.txt文件;默认为None。
|
||||
* `max_seq_length`:分词器tokenizer使用的最大序列长度,ERNIE模型最大不能超过2048。请根据文本长度选择,通常推荐128、256或512,若出现显存不足,请适当调低这一参数;默认为128。
|
||||
* `params_path`:保存训练模型的目录;默认为"../checkpoint/"。
|
||||
* `device`: 选用什么设备进行训练,选择cpu、gpu、xpu、npu;默认为"gpu"。
|
||||
* `device`: 选用什么设备进行训练,可选择cpu、gpu、xpu、npu;默认为"gpu"。
|
||||
* `batch_size`:批处理大小,请结合显存情况进行调整,若出现显存不足,请适当调低这一参数;默认为32。
|
||||
* `seed`:随机种子,默认为3。
|
||||
* `dirty_file`:保存脏数据文件名,默认为"train_dirty.txt"。
|
||||
* `rest_file`:保存剩余数据(非脏数据)文件名,默认为"train_dirty_rest.txt"。
|
||||
* `train_file`:本地数据集中训练集文件名;默认为"train.txt"。
|
||||
* `dirty_threshold`:筛选脏数据用于重新标注的阈值,只选择影响分数大于阈值作为有效数据,默认为0。
|
||||
* `dirty_threshold`:筛选脏数据用于重新标注的阈值,只选择影响分数大于阈值作为支持数据,默认为0。
|
||||
|
||||
|
||||
我们将筛选出脏数据进行重新标注,可以将`train_dirty.txt`直接导入标注工具doccano帮助更快重新标注,详情请参考[文本分类任务doccano数据标注使用指南](../../doccano.md)进行文本分类数据标注。然后将已重新标注的脏数据`train_dirty.txt`与剩余训练集数据`train_dirty_rest.txt`合并得到新的训练集`train_clean.txt`重新进行训练:
|
||||
我们将筛选出脏数据进行人工检查重新标注,可以将`train_dirty.txt`直接导入标注工具doccano帮助更快重新标注,详情请参考[文本分类任务doccano数据标注使用指南](../../doccano.md)进行文本分类数据标注。然后将已重新标注的脏数据`train_dirty.txt`与剩余训练集数据`train_dirty_rest.txt`合并得到新的训练集`train_clean.txt`重新进行训练:
|
||||
|
||||
```shell
|
||||
cat ../data/train_dirty_rest.txt ../data/train_dirty.txt > ../data/train_clean.txt
|
||||
@@ -271,7 +386,7 @@ cat ../data/train_dirty_rest.txt ../data/train_dirty.txt > ../data/train_clean.t
|
||||
|训练集(2000,含200条脏数据) + 脏数据清洗(100)|92.48|**87.83**|
|
||||
|训练集(2000,含200条脏数据) + 脏数据清洗(150)|**92.55**|83.73|
|
||||
|
||||
## 数据增强策略方案
|
||||
### 数据增强策略方案
|
||||
|
||||
在数据量较少或某些类别样本量较少时,也可以通过数据增强策略的方式,生成更多的训练数据,提升模型效果。
|
||||
|
||||
@@ -287,11 +402,11 @@ python aug.py \
|
||||
|
||||
* `train_path`:待增强训练数据集文件路径;默认为"../data/train.txt"。
|
||||
* `aug_path`:增强生成的训练数据集文件路径;默认为"../data/train_aug.txt"。
|
||||
* `aug_strategy`:数据增强策略,可选"mix", "substitute", "insert", "delete", "swap"为多种数据策略混合使用;默认为"substitute"。
|
||||
* `aug_strategy`:数据增强策略,可选"mix", "substitute", "insert", "delete", "swap","mix"为多种数据策略混合使用;默认为"substitute"。
|
||||
* `aug_type`:词替换/词插入增强类型,可选"synonym", "homonym", "mlm",建议在GPU环境下使用mlm类型;默认为"synonym"。
|
||||
* `create_n`:生成的句子数量,默认为2。
|
||||
* `aug_percent`:生成词替换百分比,默认为0.1。
|
||||
* `device`: 选用什么设备进行增强,选择cpu、gpu、xpu、npu,仅在使用mlm类型有影响;默认为"gpu"。
|
||||
* `device`: 选用什么设备进行增强,可选择cpu、gpu、xpu、npu,仅在使用mlm类型有影响;默认为"gpu"。
|
||||
|
||||
生成的增强数据保存在`"aug.txt"`文件中,与训练集数据`train.txt`合并得到新的训练集`train_aug.txt`重新进行训练:
|
||||
|
||||
|
||||
@@ -37,7 +37,7 @@ parser.add_argument("--batch_size", default=32, type=int, help="Batch size per G
|
||||
parser.add_argument("--train_file", type=str, default="train.txt", help="Train dataset file name")
|
||||
parser.add_argument("--dev_file", type=str, default="dev.txt", help="Dev dataset file name")
|
||||
parser.add_argument("--label_file", type=str, default="label.txt", help="Label file name")
|
||||
parser.add_argument("--bad_case_path", type=str, default="./bad_case.txt", help="Bad case saving file path")
|
||||
parser.add_argument("--bad_case_file", type=str, default="./bad_case.txt", help="Bad case saving file path")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
@@ -65,8 +65,17 @@ def read_local_dataset(path, label_list):
|
||||
"""
|
||||
with open(path, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
sentence, label = line.strip().split('\t')
|
||||
labels = [label_list[l] for l in label.split(',')]
|
||||
items = line.strip().split('\t')
|
||||
if len(items) == 0:
|
||||
continue
|
||||
elif len(items) == 1:
|
||||
sentence = items[0]
|
||||
labels = []
|
||||
label = ''
|
||||
else:
|
||||
sentence = ''.join(items[:-1])
|
||||
label = items[-1]
|
||||
labels = [label_list[l] for l in label.split(',')]
|
||||
yield {"text": sentence, 'label': labels, 'label_n': label}
|
||||
|
||||
|
||||
@@ -227,23 +236,22 @@ def evaluate():
|
||||
report[str(i)]['recall'] * 100,
|
||||
report[str(i)]['f1-score'] * 100))
|
||||
logger.info("----------------------------")
|
||||
|
||||
with open(args.bad_case_path, 'w', encoding="utf-8") as f:
|
||||
f.write("Prediction\tLabel\tText\n")
|
||||
bad_case_path = os.path.join(args.dataset_dir, args.bad_case_file)
|
||||
with open(bad_case_path, 'w', encoding="utf-8") as f:
|
||||
f.write("Text\tLabel\tPrediction\n")
|
||||
for i in range(len(preds)):
|
||||
for p, l in zip(preds[i], labels[i]):
|
||||
if (p and l == 0) or (not p and l == 1):
|
||||
pred_n = [
|
||||
label_map[i] for i, pp in enumerate(preds[i]) if pp
|
||||
]
|
||||
f.write(",".join(pred_n) + "\t" +
|
||||
f.write(dev_ds.data[i]["text"] + "\t" +
|
||||
dev_ds.data[i]["label_n"] + "\t" +
|
||||
dev_ds.data[i]["text"] + "\n")
|
||||
",".join(pred_n) + "\n")
|
||||
break
|
||||
|
||||
f.close()
|
||||
logger.info("Bad case in dev dataset saved in {}".format(
|
||||
args.bad_case_path))
|
||||
logger.info("Bad case in dev dataset saved in {}".format(bad_case_path))
|
||||
|
||||
return
|
||||
|
||||
|
||||
@@ -0,0 +1,172 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import functools
|
||||
import random
|
||||
import os
|
||||
import argparse
|
||||
import numpy as np
|
||||
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
from paddle.io import DataLoader, BatchSampler
|
||||
from paddlenlp.data import DataCollatorWithPadding
|
||||
from paddlenlp.datasets import load_dataset
|
||||
from paddlenlp.transformers import AutoModelForSequenceClassification, AutoTokenizer, LinearDecayWithWarmup
|
||||
from paddlenlp.utils.log import logger
|
||||
from trustai.interpretation import FeatureSimilarityModel
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--device', default="gpu", help="Select which device to train model, defaults to gpu.")
|
||||
parser.add_argument("--dataset_dir", required=True, type=str, help="The dataset directory should include train.txt,dev.txt and test.txt files.")
|
||||
parser.add_argument("--params_path", default="../checkpoint/", type=str, help="The path to model parameters to be loaded.")
|
||||
parser.add_argument("--max_seq_length", default=128, type=int, help="The maximum total input sequence length after tokenization. Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--batch_size", default=16, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument("--seed", type=int, default=3, help="random seed for initialization")
|
||||
parser.add_argument("--top_k", type=int, default=3, help="Top K important training data.")
|
||||
parser.add_argument("--train_file", type=str, default="train.txt", help="Train dataset file name")
|
||||
parser.add_argument("--interpret_input_file", type=str, default="bad_case.txt", help="interpretation file name")
|
||||
parser.add_argument("--interpret_result_file", type=str, default="sent_interpret.txt", help="interpreted file name")
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
def set_seed(seed):
|
||||
"""
|
||||
Set random seed
|
||||
"""
|
||||
random.seed(seed)
|
||||
np.random.seed(seed)
|
||||
paddle.seed(seed)
|
||||
os.environ['PYTHONHASHSEED'] = str(seed)
|
||||
|
||||
|
||||
def read_local_dataset(path):
|
||||
"""
|
||||
Read dataset file
|
||||
"""
|
||||
with open(path, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
items = line.strip().split('\t')
|
||||
if items[0] == 'Text':
|
||||
continue
|
||||
if len(items) == 3:
|
||||
yield {'text': items[0], 'label': items[1], 'predict': items[2]}
|
||||
elif len(items) == 2:
|
||||
yield {'text': items[0], 'label': items[1], 'predict': ''}
|
||||
elif len(items) == 1:
|
||||
yield {'text': items[0], 'label': '', 'predict': ''}
|
||||
else:
|
||||
logger.info(line.strip())
|
||||
raise ValueError("{} should be in fixed format.".format(path))
|
||||
|
||||
|
||||
def preprocess_function(examples, tokenizer, max_seq_length):
|
||||
"""
|
||||
Preprocess dataset
|
||||
"""
|
||||
result = tokenizer(text=examples["text"], max_seq_len=max_seq_length)
|
||||
return result
|
||||
|
||||
|
||||
class LocalDataCollatorWithPadding(DataCollatorWithPadding):
|
||||
"""
|
||||
Convert the result of DataCollatorWithPadding from dict dictionary to a list
|
||||
"""
|
||||
|
||||
def __call__(self, features):
|
||||
batch = super().__call__(features)
|
||||
batch = list(batch.values())
|
||||
return batch
|
||||
|
||||
|
||||
def find_positive_influence_data():
|
||||
|
||||
set_seed(args.seed)
|
||||
paddle.set_device(args.device)
|
||||
|
||||
# Define model & tokenizer
|
||||
if os.path.exists(os.path.join(
|
||||
args.params_path, "model_state.pdparams")) and os.path.exists(
|
||||
os.path.join(args.params_path,
|
||||
"model_config.json")) and os.path.exists(
|
||||
os.path.join(args.params_path,
|
||||
"tokenizer_config.json")):
|
||||
model = AutoModelForSequenceClassification.from_pretrained(
|
||||
args.params_path)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.params_path)
|
||||
else:
|
||||
raise ValueError("The {} should exist.".format(args.params_path))
|
||||
|
||||
# Prepare & preprocess dataset
|
||||
train_path = os.path.join(args.dataset_dir, args.train_file)
|
||||
interpret_path = os.path.join(args.dataset_dir, args.interpret_input_file)
|
||||
|
||||
train_ds = load_dataset(read_local_dataset, path=train_path, lazy=False)
|
||||
interpret_ds = load_dataset(read_local_dataset,
|
||||
path=interpret_path,
|
||||
lazy=False)
|
||||
trans_func = functools.partial(preprocess_function,
|
||||
tokenizer=tokenizer,
|
||||
max_seq_length=args.max_seq_length)
|
||||
|
||||
train_ds = train_ds.map(trans_func)
|
||||
interpret_ds = interpret_ds.map(trans_func)
|
||||
|
||||
# Batchify dataset
|
||||
collate_fn = LocalDataCollatorWithPadding(tokenizer)
|
||||
train_batch_sampler = BatchSampler(train_ds,
|
||||
batch_size=args.batch_size,
|
||||
shuffle=False)
|
||||
interpret_batch_sampler = BatchSampler(interpret_ds,
|
||||
batch_size=args.batch_size,
|
||||
shuffle=False)
|
||||
train_data_loader = DataLoader(dataset=train_ds,
|
||||
batch_sampler=train_batch_sampler,
|
||||
collate_fn=collate_fn)
|
||||
interpret_data_loader = DataLoader(dataset=interpret_ds,
|
||||
batch_sampler=interpret_batch_sampler,
|
||||
collate_fn=collate_fn)
|
||||
|
||||
# Classifier_layer_name is the layer name of the last output layer
|
||||
feature_sim = FeatureSimilarityModel(model,
|
||||
train_data_loader,
|
||||
classifier_layer_name="classifier")
|
||||
# Feature similarity analysis & select sparse data
|
||||
analysis_result = []
|
||||
for batch in interpret_data_loader:
|
||||
analysis_result += feature_sim(batch, sample_num=args.top_k)
|
||||
with open(os.path.join(args.dataset_dir, args.interpret_result_file),
|
||||
'w') as f:
|
||||
for i in range(len(analysis_result)):
|
||||
f.write("text: " + interpret_ds.data[i]["text"] + '\n')
|
||||
if 'predict' in interpret_ds.data[i]:
|
||||
f.write("predict label: " + interpret_ds.data[i]["predict"] +
|
||||
'\n')
|
||||
if 'label' in interpret_ds.data[i]:
|
||||
f.write("label: " + interpret_ds.data[i]["label"] + '\n')
|
||||
f.write("examples with positive influence\n")
|
||||
for i, (idx, score) in enumerate(
|
||||
zip(analysis_result[i].pos_indexes,
|
||||
analysis_result[i].pos_scores)):
|
||||
f.write("support{} text: ".format(i + 1) +
|
||||
train_ds.data[idx]["text"] + '\t' + "label: " +
|
||||
train_ds.data[idx]["label"] + '\t' + "score: " +
|
||||
"{:.5f}".format(score) + '\n')
|
||||
f.close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
find_positive_influence_data()
|
||||
@@ -42,7 +42,8 @@ parser.add_argument("--params_path", default="../checkpoint/", type=str, help="T
|
||||
parser.add_argument("--max_seq_length", default=128, type=int, help="The maximum total input sequence length after tokenization. Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--batch_size", default=16, type=int, help="Batch size per GPU/CPU for training.")
|
||||
parser.add_argument("--seed", type=int, default=3, help="random seed for initialization")
|
||||
parser.add_argument("--rationale_num", type=int, default=3, help="Number of rationales per example.")
|
||||
parser.add_argument("--rationale_num_sparse", type=int, default=3, help="Number of rationales per example for sparse data.")
|
||||
parser.add_argument("--rationale_num_support", type=int, default=6, help="Number of rationales per example for support data.")
|
||||
parser.add_argument("--sparse_num", type=int, default=100, help="Number of sparse data.")
|
||||
parser.add_argument("--support_threshold", type=float, default="0.7", help="The threshold to select support data.")
|
||||
parser.add_argument("--support_num", type=int, default=100, help="Number of support data.")
|
||||
@@ -180,7 +181,8 @@ def find_sparse_data():
|
||||
# Feature similarity analysis & select sparse data
|
||||
analysis_result = []
|
||||
for batch in dev_data_loader:
|
||||
analysis_result += feature_sim(batch, sample_num=args.rationale_num)
|
||||
analysis_result += feature_sim(batch,
|
||||
sample_num=args.rationale_num_sparse)
|
||||
sparse_indexs, sparse_scores, preds = get_sparse_data(
|
||||
analysis_result, args.sparse_num)
|
||||
|
||||
@@ -285,7 +287,8 @@ def find_support_data():
|
||||
# Feature similarity analysis
|
||||
analysis_result = []
|
||||
for batch in sparse_data_loader:
|
||||
analysis_result += feature_sim(batch, sample_num=-1)
|
||||
analysis_result += feature_sim(batch,
|
||||
sample_num=args.rationale_num_support)
|
||||
|
||||
support_indexs, support_scores = get_support_data(analysis_result,
|
||||
args.support_num,
|
||||
|
||||
File diff suppressed because one or more lines are too long
@@ -1,6 +1,6 @@
|
||||
# 基于Paddle Serving的服务化部署
|
||||
|
||||
本文档将介绍如何使用[Paddle Serving](https://github.com/PaddlePaddle/Serving/blob/develop/README_CN.md)工具部署基于ERNIE 2.0的层次分类部署pipeline在线服务。
|
||||
本文档将介绍如何使用[Paddle Serving](https://github.com/PaddlePaddle/Serving/blob/develop/README_CN.md)工具搭建层次分类在线服务部署。
|
||||
|
||||
## 目录
|
||||
- [环境准备](#环境准备)
|
||||
@@ -8,8 +8,24 @@
|
||||
- [部署模型](#部署模型)
|
||||
|
||||
## 环境准备
|
||||
需要[准备PaddleNLP的运行环境]()和Paddle Serving的运行环境。
|
||||
需要准备PaddleNLP的运行环境和Paddle Serving的运行环境。
|
||||
|
||||
- python >= 3.6
|
||||
- paddlepaddle >= 2.3
|
||||
- paddlenlp >= 2.4
|
||||
|
||||
### 安装PaddlePaddle
|
||||
|
||||
环境中paddlepaddle-gpu或paddlepaddle版本应大于或等于2.3, 请参见[飞桨快速安装](https://www.paddlepaddle.org.cn/install/quick?docurl=/documentation/docs/zh/install/pip/linux-pip.html)根据自己需求选择合适的PaddlePaddle下载命令。
|
||||
|
||||
|
||||
### 安装PaddleNLP
|
||||
|
||||
安装PaddleNLP默认开启百度镜像源来加速下载,如果您使用 HTTP 代理可以删去` -i https://mirror.baidu.com/pypi/simple` ,更多关于PaddleNLP安装的详细教程请查见[PaddleNLP快速安装](https://github.com/PaddlePaddle/PaddleNLP/blob/develop/docs/get_started/installation.rst)。
|
||||
|
||||
```shell
|
||||
python3 -m pip install --upgrade paddlenlp -i https://mirror.baidu.com/pypi/simple
|
||||
```
|
||||
### 安装Paddle Serving
|
||||
|
||||
安装client和serving app,用于向服务发送请求:
|
||||
@@ -49,15 +65,17 @@ pip install faster_tokenizer
|
||||
|
||||
使用Paddle Serving做服务化部署时,需要将保存的inference模型转换为serving易于部署的模型。
|
||||
|
||||
用已安装的paddle_serving_client将静态图参数模型转换成serving格式。如何使用[静态图导出脚本](../../export_model.py)将训练后的模型转为静态图模型详见[模型静态图导出](../../README.md),模型地址--dirname根据实际填写即可。
|
||||
用已安装的paddle_serving_client将静态图参数模型转换成serving格式。如何使用[静态图导出脚本](../../export_model.py)将训练后的模型转为静态图模型详见[模型静态图导出](../../README.md),模型地址`dirname`,模型文件和参数名`model_filename`,`params_filename`根据实际填写即可。
|
||||
|
||||
```shell
|
||||
python -m paddle_serving_client.convert --dirname ../../export --model_filename float32.pdmodel --params_filename float32.pdiparams
|
||||
```
|
||||
|
||||
可以通过命令查参数含义:
|
||||
```shell
|
||||
python -m paddle_serving_client.convert --help
|
||||
```
|
||||
|
||||
转换成功后的目录如下:
|
||||
```
|
||||
paddle_serving/
|
||||
@@ -94,25 +112,31 @@ serving/
|
||||
# 修改模型目录为下载的模型目录或自己的模型目录:
|
||||
model_config: serving_server => model_config: erine-3.0-tiny/serving_server
|
||||
|
||||
# 修改rpc端口号为9998
|
||||
rpc_port: 9998 => rpc_port: 9998
|
||||
# 修改rpc端口号
|
||||
rpc_port: 10231 => rpc_port: 9998
|
||||
|
||||
# 修改使用GPU推理为使用CPU推理:
|
||||
device_type: 1 => device_type: 0
|
||||
|
||||
#开启MKLDNN加速
|
||||
#use_mkldnn: False => use_mkldnn: True
|
||||
|
||||
#Fetch结果列表,以serving_client/serving_client_conf.prototxt中fetch_var的alias_name为准
|
||||
fetch_list: ["linear_147.tmp_1"] => fetch_list: ["linear_75.tmp_1"]
|
||||
|
||||
#开启MKLDNN加速
|
||||
#use_mkldnn: True => use_mkldnn: True
|
||||
```
|
||||
|
||||
|
||||
### 分类任务
|
||||
#### 启动服务
|
||||
修改好配置文件后,执行下面命令启动服务:
|
||||
```shell
|
||||
python service.py
|
||||
python service.py --max_seq_length 128 --model_name "ernie-3.0-medium-zh"
|
||||
```
|
||||
|
||||
可支持配置的参数:
|
||||
* `max_seq_length`:分词器tokenizer使用的最大序列长度,ERNIE模型最大不能超过2048。请根据文本长度选择,通常推荐128、256或512,若出现显存不足,请适当调低这一参数;默认为128。
|
||||
* `model_name`:选择预训练模型,可选"ernie-1.0-large-zh-cw","ernie-3.0-xbase-zh", "ernie-3.0-base-zh", "ernie-3.0-medium-zh", "ernie-3.0-micro-zh", "ernie-3.0-mini-zh", "ernie-3.0-nano-zh", "ernie-2.0-base-en", "ernie-2.0-large-en","ernie-m-base","ernie-m-large";默认为"ernie-3.0-medium-zh",根据实际使用的预训练模型选择。
|
||||
|
||||
输出打印如下:
|
||||
```
|
||||
[DAG] Succ init
|
||||
@@ -129,20 +153,37 @@ I0727 06:50:34.993671 43126 naive_executor.cc:102] --- skip [linear_75.tmp_1],
|
||||
[OP Object] init success
|
||||
```
|
||||
|
||||
#### 启动client测试
|
||||
#### 启动rpc client测试
|
||||
注意执行客户端请求时关闭代理,并根据实际情况修改server_url地址(启动服务所在的机器)
|
||||
```shell
|
||||
python rpc_client.py
|
||||
```
|
||||
输出打印如下:
|
||||
```
|
||||
text: 请问木竭胶囊能同高血压药、氨糖同时服吗?
|
||||
label: 3,37
|
||||
text: 消失的“外企光环”,5月份在华裁员900余人,香饽饽变“臭”了
|
||||
label: 组织关系,组织关系##裁员
|
||||
--------------------
|
||||
text: 低压100*高压140*头涨,想吃点降压药。谢谢!
|
||||
label: 0
|
||||
text: 卡车超载致使跨桥侧翻,没那么简单
|
||||
label: 灾害/意外,灾害/意外##坍/垮塌
|
||||
--------------------
|
||||
text: 脑穿通畸形易发人群有哪些
|
||||
label: 0,9
|
||||
text: 金属卡扣安装不到位,上海乐扣乐扣贸易有限公司将召回捣碎器1162件
|
||||
label: 产品行为,产品行为##召回
|
||||
--------------------
|
||||
```
|
||||
#### 启动http client测试
|
||||
注意执行客户端请求时关闭代理,并根据实际情况修改server_url地址(启动服务所在的机器)
|
||||
```shell
|
||||
python http_client.py
|
||||
```
|
||||
输出打印如下:
|
||||
```
|
||||
text: 消失的“外企光环”,5月份在华裁员900余人,香饽饽变“臭”了
|
||||
label: 组织关系,组织关系##裁员
|
||||
--------------------
|
||||
text: 卡车超载致使跨桥侧翻,没那么简单
|
||||
label: 灾害/意外,灾害/意外##坍/垮塌
|
||||
--------------------
|
||||
text: 金属卡扣安装不到位,上海乐扣乐扣贸易有限公司将召回捣碎器1162件
|
||||
label: 产品行为,产品行为##召回
|
||||
--------------------
|
||||
```
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
rpc_port: 18090
|
||||
|
||||
#http端口, rpc_port和http_port不允许同时为空。当rpc_port可用且http_port为空时,不自动生成http_port
|
||||
http_port: 9999
|
||||
http_port: 9878
|
||||
|
||||
#worker_num, 最大并发数。
|
||||
#当build_dag_each_worker=True时, 框架会创建worker_num个进程,每个进程内构建grpcSever和DAG
|
||||
|
||||
@@ -0,0 +1,67 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
import numpy as np
|
||||
from numpy import array
|
||||
import requests
|
||||
import json
|
||||
import sys
|
||||
|
||||
|
||||
class Runner(object):
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
server_url: str,
|
||||
):
|
||||
self.server_url = server_url
|
||||
|
||||
def Run(self, text, label_list):
|
||||
sentence = np.array([t.encode('utf-8') for t in text], dtype=np.object_)
|
||||
sentence = sentence.__repr__()
|
||||
data = {"key": ["sentence"], "value": [sentence]}
|
||||
data = json.dumps(data)
|
||||
|
||||
ret = requests.post(url=self.server_url, data=data)
|
||||
ret = ret.json()
|
||||
for t, l in zip(text, eval(ret['value'][0])):
|
||||
print("text: ", t)
|
||||
label = ','.join([label_list[int(ll)] for ll in l.split(',')])
|
||||
print("label: ", label)
|
||||
print("--------------------")
|
||||
return
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
server_url = "http://127.0.0.1:9878/seq_cls/prediction"
|
||||
runner = Runner(server_url)
|
||||
text = [
|
||||
"消失的“外企光环”,5月份在华裁员900余人,香饽饽变“臭”了?", "卡车超载致使跨桥侧翻,没那么简单",
|
||||
"金属卡扣安装不到位,上海乐扣乐扣贸易有限公司将召回捣碎器1162件"
|
||||
]
|
||||
label_list = [
|
||||
'交往', '交往##会见', '交往##感谢', '交往##探班', '交往##点赞', '交往##道歉', '产品行为',
|
||||
'产品行为##上映', '产品行为##下架', '产品行为##发布', '产品行为##召回', '产品行为##获奖', '人生',
|
||||
'人生##产子/女', '人生##出轨', '人生##分手', '人生##失联', '人生##婚礼', '人生##庆生', '人生##怀孕',
|
||||
'人生##死亡', '人生##求婚', '人生##离婚', '人生##结婚', '人生##订婚', '司法行为', '司法行为##举报',
|
||||
'司法行为##入狱', '司法行为##开庭', '司法行为##拘捕', '司法行为##立案', '司法行为##约谈', '司法行为##罚款',
|
||||
'司法行为##起诉', '灾害/意外', '灾害/意外##地震', '灾害/意外##坍/垮塌', '灾害/意外##坠机',
|
||||
'灾害/意外##洪灾', '灾害/意外##爆炸', '灾害/意外##袭击', '灾害/意外##起火', '灾害/意外##车祸', '竞赛行为',
|
||||
'竞赛行为##夺冠', '竞赛行为##晋级', '竞赛行为##禁赛', '竞赛行为##胜负', '竞赛行为##退役', '竞赛行为##退赛',
|
||||
'组织关系', '组织关系##停职', '组织关系##加盟', '组织关系##裁员', '组织关系##解散', '组织关系##解约',
|
||||
'组织关系##解雇', '组织关系##辞/离职', '组织关系##退出', '组织行为', '组织行为##开幕', '组织行为##游行',
|
||||
'组织行为##罢工', '组织行为##闭幕', '财经/交易', '财经/交易##上市', '财经/交易##出售/收购',
|
||||
'财经/交易##加息', '财经/交易##涨价', '财经/交易##涨停', '财经/交易##融资', '财经/交易##跌停',
|
||||
'财经/交易##降价', '财经/交易##降息'
|
||||
]
|
||||
runner.Run(text, label_list)
|
||||
@@ -26,12 +26,13 @@ class Runner(object):
|
||||
self.client = PipelineClient()
|
||||
self.client.connect([server_url])
|
||||
|
||||
def Run(self, data):
|
||||
def Run(self, data, label_list):
|
||||
data = np.array([x.encode('utf-8') for x in data], dtype=np.object_)
|
||||
ret = self.client.predict(feed_dict={"sentence": data})
|
||||
for d, l, in zip(data, eval(ret.value[0])):
|
||||
print("text: ", d)
|
||||
print("label: ", l)
|
||||
label = ','.join([label_list[int(ll)] for ll in l.split(',')])
|
||||
print("label: ", label)
|
||||
print("--------------------")
|
||||
return
|
||||
|
||||
@@ -39,8 +40,23 @@ class Runner(object):
|
||||
if __name__ == "__main__":
|
||||
server_url = "127.0.0.1:18090"
|
||||
runner = Runner(server_url)
|
||||
texts = [
|
||||
text = [
|
||||
"消失的“外企光环”,5月份在华裁员900余人,香饽饽变“臭”了?", "卡车超载致使跨桥侧翻,没那么简单",
|
||||
"金属卡扣安装不到位,上海乐扣乐扣贸易有限公司将召回捣碎器1162件"
|
||||
]
|
||||
runner.Run(texts)
|
||||
label_list = [
|
||||
'交往', '交往##会见', '交往##感谢', '交往##探班', '交往##点赞', '交往##道歉', '产品行为',
|
||||
'产品行为##上映', '产品行为##下架', '产品行为##发布', '产品行为##召回', '产品行为##获奖', '人生',
|
||||
'人生##产子/女', '人生##出轨', '人生##分手', '人生##失联', '人生##婚礼', '人生##庆生', '人生##怀孕',
|
||||
'人生##死亡', '人生##求婚', '人生##离婚', '人生##结婚', '人生##订婚', '司法行为', '司法行为##举报',
|
||||
'司法行为##入狱', '司法行为##开庭', '司法行为##拘捕', '司法行为##立案', '司法行为##约谈', '司法行为##罚款',
|
||||
'司法行为##起诉', '灾害/意外', '灾害/意外##地震', '灾害/意外##坍/垮塌', '灾害/意外##坠机',
|
||||
'灾害/意外##洪灾', '灾害/意外##爆炸', '灾害/意外##袭击', '灾害/意外##起火', '灾害/意外##车祸', '竞赛行为',
|
||||
'竞赛行为##夺冠', '竞赛行为##晋级', '竞赛行为##禁赛', '竞赛行为##胜负', '竞赛行为##退役', '竞赛行为##退赛',
|
||||
'组织关系', '组织关系##停职', '组织关系##加盟', '组织关系##裁员', '组织关系##解散', '组织关系##解约',
|
||||
'组织关系##解雇', '组织关系##辞/离职', '组织关系##退出', '组织行为', '组织行为##开幕', '组织行为##游行',
|
||||
'组织行为##罢工', '组织行为##闭幕', '财经/交易', '财经/交易##上市', '财经/交易##出售/收购',
|
||||
'财经/交易##加息', '财经/交易##涨价', '财经/交易##涨停', '财经/交易##融资', '财经/交易##跌停',
|
||||
'财经/交易##降价', '财经/交易##降息'
|
||||
]
|
||||
runner.Run(text, label_list)
|
||||
|
||||
@@ -12,26 +12,48 @@
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from paddle_serving_server.web_service import WebService, Op
|
||||
|
||||
from numpy import array
|
||||
|
||||
import argparse
|
||||
import logging
|
||||
import numpy as np
|
||||
from numpy import array
|
||||
from paddle_serving_server.web_service import WebService, Op
|
||||
|
||||
from paddlenlp.transformers import AutoTokenizer
|
||||
|
||||
_LOGGER = logging.getLogger()
|
||||
|
||||
FETCH_NAME_MAP = {
|
||||
"ernie-1.0-large-zh-cw": "linear_291.tmp_1",
|
||||
"ernie-3.0-xbase-zh": "linear_243.tmp_1",
|
||||
"ernie-3.0-base-zh": "linear_147.tmp_1",
|
||||
"ernie-3.0-medium-zh": "linear_75.tmp_1",
|
||||
"ernie-3.0-mini-zh": "linear_75.tmp_1",
|
||||
"ernie-3.0-micro-zh": "linear_51.tmp_1",
|
||||
"ernie-3.0-nano-zh": "linear_51.tmp_1",
|
||||
"ernie-2.0-base-en": "linear_147.tmp_1",
|
||||
"ernie-2.0-large-en": "linear_291.tmp_1",
|
||||
"ernie-m-base": "linear_147.tmp_1",
|
||||
"ernie-m-large": "linear_291.tmp_1",
|
||||
}
|
||||
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--max_seq_length", default=128, type=int, help="The maximum total input sequence length after tokenization. Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument('--model_name', default="ernie-3.0-medium-zh", help="Select model to train, defaults to ernie-3.0-medium-zh.",
|
||||
choices=["ernie-1.0-large-zh-cw", "ernie-3.0-xbase-zh", "ernie-3.0-base-zh", "ernie-3.0-medium-zh", "ernie-3.0-micro-zh", "ernie-3.0-mini-zh", "ernie-3.0-nano-zh", "ernie-2.0-base-en", "ernie-2.0-large-en","ernie-m-base","ernie-m-large"])
|
||||
args = parser.parse_args()
|
||||
# yapf: enable
|
||||
|
||||
|
||||
class Op(Op):
|
||||
|
||||
def init_op(self):
|
||||
from paddlenlp.transformers import AutoTokenizer
|
||||
self.tokenizer = AutoTokenizer.from_pretrained("ernie-3.0-medium-zh",
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(args.model_name,
|
||||
use_faster=True)
|
||||
# Output nodes may differ from model to model
|
||||
# You can see the output node name in the conf.prototxt file of serving_server
|
||||
self.fetch_names = [
|
||||
"linear_75.tmp_1",
|
||||
FETCH_NAME_MAP[args.model_name],
|
||||
]
|
||||
|
||||
def preprocess(self, input_dicts, data_id, log_id):
|
||||
@@ -46,16 +68,16 @@ class Op(Op):
|
||||
|
||||
# tokenizer + pad
|
||||
data = self.tokenizer(data,
|
||||
max_length=512,
|
||||
max_length=args.max_seq_length,
|
||||
padding=True,
|
||||
truncation=True)
|
||||
input_ids = data["input_ids"]
|
||||
token_type_ids = data["token_type_ids"]
|
||||
|
||||
return {
|
||||
"input_ids": np.array(input_ids, dtype="int64"),
|
||||
"token_type_ids": np.array(token_type_ids, dtype="int64")
|
||||
}, False, None, ""
|
||||
truncation=True,
|
||||
return_position_ids=False,
|
||||
return_attention_mask=False)
|
||||
tokenized_data = {}
|
||||
for tokenizer_key in data:
|
||||
tokenized_data[tokenizer_key] = np.array(data[tokenizer_key],
|
||||
dtype="int64")
|
||||
return tokenized_data, False, None, ""
|
||||
|
||||
def postprocess(self, input_dicts, fetch_dict, data_id, log_id):
|
||||
|
||||
|
||||
@@ -19,6 +19,12 @@ python -m pip install onnxruntime-gpu onnx onnxconverter-common psutil
|
||||
python -m pip install onnxruntime psutil
|
||||
```
|
||||
|
||||
安装FasterTokenizer文本处理加速库(可选)
|
||||
推荐安装faster_tokenizer可以得到更极致的文本处理效率,进一步提升服务性能。
|
||||
```shell
|
||||
pip install faster_tokenizer
|
||||
```
|
||||
|
||||
## 基于GPU部署推理样例
|
||||
请使用如下命令进行部署
|
||||
```
|
||||
@@ -34,7 +40,7 @@ python infer.py \
|
||||
可支持配置的参数:
|
||||
|
||||
* `model_path_prefix`:必须,待推理模型路径前缀。
|
||||
* `model_name_or_path`:选择预训练模型;默认为"ernie-3.0-medium-zh"。
|
||||
* `model_name_or_path`:选择预训练模型,可选"ernie-1.0-large-zh-cw","ernie-3.0-xbase-zh", "ernie-3.0-base-zh", "ernie-3.0-medium-zh", "ernie-3.0-micro-zh", "ernie-3.0-mini-zh", "ernie-3.0-nano-zh", "ernie-2.0-base-en", "ernie-2.0-large-en","ernie-m-base","ernie-m-large";默认为"ernie-3.0-medium-zh",根据实际使用的预训练模型选择。
|
||||
* `max_seq_length`:ERNIE/BERT模型使用的最大序列长度,最大不能超过512, 若出现显存不足,请适当调低这一参数;默认为128。
|
||||
* `use_fp16`:选择是否开启FP16进行加速;默认为False。
|
||||
* `batch_size`:批处理大小,请结合显存情况进行调整,若出现显存不足,请适当调低这一参数;默认为32。
|
||||
@@ -159,8 +165,8 @@ python infer.py \
|
||||
|
||||
| | Micro F1(%) | Macro F1(%) | latency(ms) |
|
||||
| -------------------------- | ------------ | ------------- |------------- |
|
||||
| ERNIE 3.0 Medium+FP32+GPU | 95.26|93.22| 2.42|
|
||||
| ERNIE 3.0 Medium+FP16+GPU | 95.26|93.22| 0.79|
|
||||
| ERNIE 3.0 Medium+FP32+GPU | 95.26|93.22| 1.01|
|
||||
| ERNIE 3.0 Medium+FP16+GPU | 95.26|93.22| 0.38|
|
||||
| ERNIE 3.0 Medium+FP32+CPU | 95.26|93.22| 18.93 |
|
||||
| ERNIE 3.0 Medium+INT8+CPU | 95.03 | 92.87| 12.14 |
|
||||
|
||||
|
||||
@@ -25,7 +25,8 @@ from predictor import Predictor
|
||||
# yapf: disable
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--model_path_prefix", type=str, required=True, help="The path prefix of inference model to be used.")
|
||||
parser.add_argument("--model_name_or_path", default="ernie-3.0-medium-zh", type=str, help="The directory or name of model.")
|
||||
parser.add_argument('--model_name_or_path', default="ernie-3.0-medium-zh", help="Select model to train, defaults to ernie-3.0-medium-zh.",
|
||||
choices=["ernie-1.0-large-zh-cw","ernie-3.0-xbase-zh", "ernie-3.0-base-zh", "ernie-3.0-medium-zh", "ernie-3.0-micro-zh", "ernie-3.0-mini-zh", "ernie-3.0-nano-zh", "ernie-2.0-base-en", "ernie-2.0-large-en","ernie-m-base","ernie-m-large"])
|
||||
parser.add_argument("--max_seq_length", default=128, type=int, help="The maximum total input sequence length after tokenization. Sequences longer than this will be truncated, sequences shorter will be padded.")
|
||||
parser.add_argument("--use_fp16", action='store_true', help="Whether to use fp16 inference, only takes effect when deploying on gpu.")
|
||||
parser.add_argument("--use_quantize", action='store_true', help="Whether to use quantization for acceleration, only takes effect when deploying on cpu.")
|
||||
@@ -41,12 +42,19 @@ args = parser.parse_args()
|
||||
|
||||
|
||||
def read_local_dataset(path, label_list):
|
||||
"""Read dataset"""
|
||||
label_list_dict = {label_list[i]: i for i in range(len(label_list))}
|
||||
with open(path, 'r', encoding='utf-8') as f:
|
||||
for line in f:
|
||||
sentence, label = line.strip().split('\t')
|
||||
labels = [label_list_dict[l] for l in label.split(',')]
|
||||
items = line.strip().split('\t')
|
||||
if len(items) == 0:
|
||||
continue
|
||||
elif len(items) == 1:
|
||||
sentence = items[0]
|
||||
labels = []
|
||||
else:
|
||||
sentence = ''.join(items[:-1])
|
||||
label = items[-1]
|
||||
labels = [label_list_dict[l] for l in label.split(',')]
|
||||
yield {'sentence': sentence, 'label': labels}
|
||||
|
||||
|
||||
|
||||
@@ -101,10 +101,6 @@ class InferBackend(object):
|
||||
onnx_model,
|
||||
sess_options=sess_options,
|
||||
providers=['CPUExecutionProvider'])
|
||||
input_name1 = self.predictor.get_inputs()[1].name
|
||||
input_name2 = self.predictor.get_inputs()[0].name
|
||||
self.input_handles = [input_name1, input_name2]
|
||||
|
||||
logger.info(">>> [InferBackend] Engine Created ...")
|
||||
|
||||
def dynamic_quantize(self, input_float_model, dynamic_quantized_model):
|
||||
@@ -143,12 +139,15 @@ class Predictor(object):
|
||||
data = self.tokenizer(input_data,
|
||||
max_length=self.max_seq_length,
|
||||
padding=True,
|
||||
truncation=True)
|
||||
truncation=True,
|
||||
return_position_ids=False,
|
||||
return_attention_mask=False)
|
||||
tokenized_data = {}
|
||||
for tokenizer_key in data:
|
||||
|
||||
return {
|
||||
"input_ids": np.array(data["input_ids"], dtype="int64"),
|
||||
"token_type_ids": np.array(data["token_type_ids"], dtype="int64")
|
||||
}
|
||||
tokenized_data[tokenizer_key] = np.array(data[tokenizer_key],
|
||||
dtype="int64")
|
||||
return tokenized_data
|
||||
|
||||
def postprocess(self, infer_data):
|
||||
threshold = 0.5
|
||||
@@ -178,17 +177,13 @@ class Predictor(object):
|
||||
infer_result = None
|
||||
for i in range(0, sample_num, self.batch_size):
|
||||
batch_size = min(self.batch_size, sample_num - i)
|
||||
input_ids = [
|
||||
preprocess_result["input_ids"][i + j] for j in range(batch_size)
|
||||
]
|
||||
token_type_ids = [
|
||||
preprocess_result["token_type_ids"][i + j]
|
||||
for j in range(batch_size)
|
||||
]
|
||||
preprocess_result_batch = {
|
||||
"input_ids": input_ids,
|
||||
"token_type_ids": token_type_ids
|
||||
}
|
||||
preprocess_result_batch = {}
|
||||
for tokenizer_key in preprocess_result:
|
||||
preprocess_result_batch[tokenizer_key] = [
|
||||
preprocess_result[tokenizer_key][i + j]
|
||||
for j in range(batch_size)
|
||||
]
|
||||
|
||||
result = self.infer(preprocess_result_batch)
|
||||
if infer_result is None:
|
||||
infer_result = result
|
||||
|
||||
@@ -16,7 +16,7 @@ output [
|
||||
{
|
||||
name: "linear_75.tmp_1"
|
||||
data_type: TYPE_FP32
|
||||
dims: [ 141 ]
|
||||
dims: [ 74 ]
|
||||
}
|
||||
]
|
||||
|
||||
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import json
|
||||
import time
|
||||
|
||||
|
||||
@@ -6,7 +6,7 @@ input [
|
||||
{
|
||||
name: "POST_INPUT"
|
||||
data_type: TYPE_FP32
|
||||
dims: [ 141 ]
|
||||
dims: [ 74 ]
|
||||
}
|
||||
]
|
||||
|
||||
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import json
|
||||
import time
|
||||
|
||||
@@ -33,7 +47,7 @@ class TritonPythonModel(object):
|
||||
* model_version: Model version
|
||||
* model_name: Model name
|
||||
"""
|
||||
self.tokenizer = AutoTokenizer.from_pretrained("ernie-2.0-base-en",
|
||||
self.tokenizer = AutoTokenizer.from_pretrained("ernie-3.0-medium-zh",
|
||||
use_faster=True)
|
||||
# You must parse model_config. JSON string is not parsed here
|
||||
self.model_config = json.loads(args['model_config'])
|
||||
@@ -72,7 +86,6 @@ class TritonPythonModel(object):
|
||||
be the same as `requests`
|
||||
"""
|
||||
responses = []
|
||||
# print("num:", len(requests), flush=True)
|
||||
for request in requests:
|
||||
data = pb_utils.get_input_tensor_by_name(request,
|
||||
self.input_names[0])
|
||||
@@ -86,9 +99,6 @@ class TritonPythonModel(object):
|
||||
token_type_ids = np.array(data["token_type_ids"],
|
||||
dtype=self.output_dtype[1])
|
||||
|
||||
# print("input_ids:", input_ids)
|
||||
# print("token_type_ids:", token_type_ids)
|
||||
|
||||
out_tensor1 = pb_utils.Tensor(self.output_names[0], input_ids)
|
||||
out_tensor2 = pb_utils.Tensor(self.output_names[1], token_type_ids)
|
||||
inference_response = pb_utils.InferenceResponse(
|
||||
|
||||
@@ -1,3 +1,17 @@
|
||||
# Copyright (c) 2022 PaddlePaddle Authors. All Rights Reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import argparse
|
||||
import struct
|
||||
import logging
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user